
Animagine XL V3.1
9534°
<animagine31-xl>
Các ứng dụng hỗ trợ thẻ ModelTrends cho phép bạn chạy/cài đặt mô hình bằng cách sao chép mã này vào lệnh nhắc mà không cần thiết lập. Tìm biểu tượng của chúng tôi trong các ứng dụng hỗ trợ, như Prism (bên dưới).
Chạy mô hình này
Ưu đãi / Quảng cáo

Easy Creator (Prism) Web
Không giới hạn · phí cố định
Tốt nhất cho người mới bắt đầu. Quy trình làm việc mạnh mẽ, dễ học.

PirateDiffusion Telegram
Không giới hạn · phí cố định
Tạo video, hình ảnh, nhân vật chat tùy chỉnh và nhiều hơn nữa.

Pro studio (SpyGlass) Web
Không giới hạn · phí cố định
Duyệt mô hình, render và chỉnh sửa từ bất kỳ trình duyệt hay điện thoại nào.

Discord bot (Vector)
Không giới hạn · phí cố định
Thêm Vector vào máy chủ của bạn hoặc tham gia Discord của Vector. Tạo mọi thứ!

Unified Editor Web
Không giới hạn · phí cố định
Trình chỉnh sửa cho hình ảnh và video: render, chỉnh sửa, nâng cấp và nhiều hơn nữa trên một trang.

Civitai Web
Trả theo lượt dùng
Tạo ảnh trên trang Civitai; mỗi ảnh trả bằng Buzz credits.

Ứng dụng cục bộ
Cần thiết lập
Cài đặt các chương trình local nếu máy tính của bạn có phần cứng đủ mạnh.

ModelDuel Web
Trả theo lượt dùng
Tạo cùng một lệnh trên tối đa 50 mô hình checkpoint/cơ sở cùng lúc.

Ghi chú của tác giả
Animagine XL 3.1 is an update in the Animagine XL V3 series, enhancing the previous version, Animagine XL 3.0. This open-source, anime-themed text-to-image model has been improved for generating anime-style images with higher quality. It includes a broader range of characters from well-known anime series, an optimized dataset, and new aesthetic tags for better image creation. Built on Stable Diffusion XL, Animagine XL 3.1 aims to be a valuable resource for anime fans, artists, and content creators by producing accurate and detailed representations of anime characters.
Model Details
-
Developed by:
-
In collaboration with:
-
Model type: Diffusion-based text-to-image generative model
-
Model Description: Animagine XL 3.1 generates high-quality anime images from textual prompts. It boasts enhanced hand anatomy, improved concept understanding, and advanced prompt interpretation.
-
License:
-
Fine-tuned from:
Usage Guidelines
Tag Ordering
For optimal results, it's recommended to follow the structured prompt template because we train the model like this:
1girl/1boy, character name, from what series, everything else in any order.
Special Tags
Animagine XL 3.1 utilizes special tags to steer the result toward quality, rating, creation date and aesthetic. While the model can generate images without these tags, using them can help achieve better results.
Quality Modifiers
Quality tags now consider both scores and post ratings to ensure a balanced quality distribution. We've refined labels for greater clarity, such as changing 'high quality' to 'great quality'.
Quality Modifier Score Criterion
masterpiece > 95%
best quality > 85% & ≤ 95%
great quality > 75% & ≤ 85%
good quality > 50% & ≤ 75%
normal quality > 25% & ≤ 50%
low quality > 10% & ≤ 25%
worst quality ≤ 10%
Rating Modifiers
We've also streamlined our rating tags for simplicity and clarity, aiming to establish global rules that can be applied across different models. For example, the tag 'rating: general' is now simply 'general', and 'rating: sensitive' has been condensed to 'sensitive'.
Rating Modifier Rating Criterion
safe General
sensitive Sensitive
nsfw Questionable
explicit, nsfw Explicit
Year Modifier
We've also redefined the year range to steer results towards specific modern or vintage anime art styles more accurately. This update simplifies the range, focusing on relevance to current and past eras.
Year Tag Year Range
newest 2021 to 2024
recent 2018 to 2020
mid 2015 to 2017
early 2011 to 2014
oldest 2005 to 2010
Aesthetic Tags
We've enhanced our tagging system with aesthetic tags to refine content categorization based on visual appeal. These tags are derived from evaluations made by a specialized ViT (Vision Transformer) image classification model, specifically trained on anime data. For this purpose, we utilized the model , which assesses the aesthetic value of content before it undergoes training. This ensures that each piece of content is not only relevant and accurate but also visually appealing.
Aesthetic Tag Score Range
very aesthetic > 0.71
aesthetic > 0.45 & 0.27 & < 0.45
very displeasing ≤ 0.27
Recommended settings
To guide the model towards generating high-aesthetic images, use negative prompts like:
nsfw, lowres, (bad), text, error, fewer, extra, missing, worst quality, jpeg artifacts, low quality, watermark, unfinished, displeasing, oldest, early, chromatic aberration, signature, extra digits, artistic error, username, scan, [abstract]
For higher quality outcomes, prepend prompts with:
masterpiece, best quality, very aesthetic, absurdres
it’s recommended to use a lower classifier-free guidance (CFG Scale) of around 5-7, sampling steps below 30, and to use Euler Ancestral (Euler a) as a sampler.
Multi Aspect Resolution
This model supports generating images at the following dimensions:
Dimensions Aspect Ratio
1024 x 1024 1:1 Square
1152 x 896 9:7
896 x 1152 7:9
1216 x 832 19:13
832 x 1216 13:19
1344 x 768 7:4 Horizontal
768 x 1344 4:7 Vertical
1536 x 640 12:5 Horizontal
640 x 1536 5:12 Vertical
Acknowledgements
The development and release of Animagine XL 3.1 would not have been possible without the invaluable contributions and support from the following individuals and organizations:
-
: Our collaboration partner and sponsor.
-
: For providing the aesthetic classification model, .
-
: For their custom learning rate scheduler, adapted from .
-
: For their comprehensive training scripts.
-
Cagliostrolab Collaborators: For their dedication to model training, project management, and data curation.
-
Early Testers: For their valuable feedback and quality assurance efforts.
-
NovelAI: For their innovative approach to aesthetic tagging, which served as an inspiration for our implementation.
Thank you all for your support and expertise in pushing the boundaries of anime-style image generation.
Limitations
While Animagine XL 3.1 represents a significant advancement in anime-style image generation, it is important to acknowledge its limitations:
-
Anime-Focused: This model is specifically designed for generating anime-style images and is not suitable for creating realistic photos.
-
Prompt Complexity: This model may not be suitable for users who expect high-quality results from short or simple prompts. The training focus was on concept understanding rather than aesthetic refinement, which may require more detailed and specific prompts to achieve the desired output.
-
Prompt Format: Animagine XL 3.1 is optimized for Danbooru-style tags rather than natural language prompts. For best results, users are encouraged to format their prompts using the appropriate tags and syntax.
-
Anatomy and Hand Rendering: Despite the improvements made in anatomy and hand rendering, there may still be instances where the model produces suboptimal results in these areas.
-
Dataset Size: The dataset used for training Animagine XL 3.1 consists of approximately 870,000 images. When combined with the previous
SHA256
E3C47AEDB06418C6C331443CD89F2B3B3B34B7ED2102A3D4C4408A8D35AAD6B0
Xu hướng phổ biến của Animagine XL V3.1
Điểm nhiệt, 12 tháng gần đây
Điểm nhiệt
9,534°
Tuần này
▼
0.6%
9,537° lúc đó, 9,534° bây giờ
Tháng này
▼
2.5%
9,546° lúc đó, 9,534° bây giờ
Năm qua
▼
29.8%
9,683° lúc đó, 9,534° bây giờ
7,000°
Điểm sàn
Thang điểm chạy từ 0° đến 9.999°. Mọi thứ dưới 7,000° dành cho các mô hình chưa có nguồn nào báo cáo, chúng mang một số thay thế ở đó để danh sách luôn đầy đủ. 7,000° là nơi bắt đầu dữ liệu đo được: một mô hình có dữ liệu thật nhưng gần như không có lượt tải sẽ đứng ở điểm sàn, và các số đo sẽ cộng dồn trên đó. Điểm sàn không nói gì về mô hình; chỉ có các độ trên nó mới phân biệt được các mô hình với nhau.
+45°
Lượt tải Civitai
181,860 lượt tải phiên bản chính xác này trên Civitai. Lượt tải là yếu tố nặng nhất và được tính trên thang logarit: tăng gấp mười lượt tải cộng thêm 300°, nên mô hình có một triệu lượt tải không nóng gấp nghìn lần mô hình có một nghìn lượt tải. Sáu nguồn lượt tải chia sẻ chung một điều kiện này, phân bổ theo tỷ lệ lượt tải của họ.
+2,054°
Trang tạo ảnh
8,138,965 lượt tải và lượt chạy của bản sao mô hình trên Yodayo. Mỗi lượt chạy tính như một lượt tải, và lượt tải của chúng tính như lượt tải Civitai; tất cả đều chia sẻ thành phần lượt tải.
+651°
Lượt thích
21,928 lượt thích và bấm ngón tay cái trên các nguồn. Một lượt thích được tính bằng nửa lượt tải, trên cùng thang logarit.
+131°
Tỷ lệ áp dụng
Khoảng 55 lượt tải mỗi ngày, đo giữa hai lần đọc nguồn, không đoán dựa trên trung bình cả đời. Tốc độ chiếm một phần tư thành phần lượt tải, nên một đợt tăng mới sẽ hiện rõ mà không để một đỉnh một ngày vượt qua nhiều năm sử dụng.
+150°
Mô hình đầy đủ
+150° vì đây là mô hình đầy đủ: một checkpoint, chính là trọng số. Một LoRA hoặc embedding là phần thêm vào trọng số của người khác và không vượt trên checkpoint có cùng độ phổ biến.
−497°
Tuổi
−497° vì trọng số SDXL được phát hành vào 2023. Mỗi mô hình thừa hưởng tuổi của trọng số nó dựa trên: 150° mỗi năm, tối đa 750°, và nó tiếp tục tăng cho đến đó. Nếu không có điều này, top danh sách sẽ là các checkpoint 2022 và 2023 dựa trên lượt tải tích tụ nhiều năm.
Hiển thị phân tích chi tiết
Mọi con số trên trang này đều có thể kiểm tra được. Điểm nhiệt của mô hình này là 9,534°, và đây là cách nó được xây dựng từng thành phần một, với tổng điểm chạy sau mỗi bước: điểm sàn, số độ mà mỗi nguồn đóng góp, điểm thưởng cho loại mô hình và điểm trừ theo tuổi của trọng số. Màu sắc tương ứng với các dải trên biểu đồ phía trên. Phần chú giải ở cuối định nghĩa mọi thuật ngữ.
- 1Bắt đầu từ điểm sàn.Tại sao là 7,000° chứ không phải 0: thang điểm chạy từ 0° đến 9.999°, và phần dưới 7,000° dành cho các mô hình chưa có nguồn báo cáo, mang số thay thế để danh sách đầy đủ và không bao giờ vượt trên mô hình có dữ liệu. 7,000° là nơi bắt đầu dữ liệu đo được. Một mô hình có dữ liệu thật nhưng gần như không có lượt tải đứng ở đây; mọi thứ tiếp theo là đo lường, và phần trên điểm sàn có mười bước tăng gấp mười lần lượt tải, mỗi bước 300°. Điểm sàn giống nhau cho mọi mô hình, nên nó không quyết định gì; chỉ có các độ trên nó mới quyết định.7,000°tổng đang chạy
- 2Thêm lượt tải về.8,320,825 lượt tải tương đương tổng cộng, từ Lượt tải Civitai, Trang tạo ảnh. Mười lần lượt tải thêm cùng 300°, nên kích thước quan trọng nhưng không bao giờ chiếm hết điểm.+45° Lượt tải Civitai+2,054° Trang tạo ảnh+2,099°9,099°tổng đang chạy
- 3Thêm lượt thích.21,928 lượt thích và giơ ngón tay cái, bằng một nửa trọng số của lượt tải.+651°9,750°tổng đang chạy
- 4Thêm tỷ lệ áp dụng.Khoảng 55 lượt tải mỗi ngày hiện tại, đo giữa hai lần đọc, bằng một phần tư trọng số.+131°9,881°tổng đang chạy
- 5Thưởng cho mô hình đầy đủ.Một checkpoint mang trọng số chính; các add-on không vượt trên một mô hình có cùng độ phổ biến.+150°10,031°tổng đang chạy
- 6Bỏ tuổi ra.Trọng số SDXL ra mắt vào 2023: 150° mỗi năm, tối đa 750°, tăng dần cho đến lúc đó.−497°9,534°tổng đang chạy
- =Điểm nhiệt.Mô hình này đứng ở đâu trên mọi danh sách của trang này. Không có gì khác điều chỉnh nó.9,534°
Thuật ngữ: các từ dùng ở đây
- Điểm nhiệt
- Một số duy nhất cho biết mô hình được dùng và mong muốn thế nào hiện tại, từ 0° đến 9.999°. Mọi danh sách trên trang này nói về độ hot đều sắp xếp theo nó và không theo gì khác.
- Sàn điểm
- 7.000° là điểm bắt đầu cho mọi mô hình có dữ liệu thật. Thang điểm chạy từ 0° đến 9.999°; phần dưới sàn dành cho mô hình thay thế (mô hình không có dữ liệu), để mô hình có dữ liệu luôn xếp trên mô hình không có. Sàn điểm giống nhau cho tất cả và không quyết định gì; điểm trên sàn mới là thước đo.
- Tương đương lượt tải
- Tất cả những gì điểm số coi là lượt tải, cộng lại: lượt tải thật, mỗi người chia sẻ torrent tính 1.000, mỗi ảnh AI Horde và mỗi lượt chạy trên trang tạo ảnh tính một.
- Thang log
- Đếm theo chục, không phải theo đơn vị: từ 1.000 lên 10.000 lượt tải thêm cùng số điểm như từ 10.000 lên 100.000. Giúp tránh việc các mô hình lớn lấn át hết mọi thứ khác.
- Lượt thích
- Giơ ngón tay cái và lượt thích từ mọi nguồn, mỗi lượt bằng một nửa lượt tải trên thang log.
- Tỷ lệ áp dụng
- Bao nhiêu lượt tải mỗi ngày mà mô hình nhận được hiện tại, tính từ chênh lệch giữa hai lần đọc nguồn. Bằng một phần tư trọng số của lượt tải.
- Đã đo và ước tính
- Đã đo nghĩa là có hai lần đọc từ một nguồn và sự khác biệt là thật. Ước tính nghĩa là chỉ biết tổng số hôm nay và quá khứ được phân bổ trong suốt thời gian tồn tại của mô hình; trang web sẽ nói rõ đang hiển thị loại nào.
- Seeder
- Người giữ bản sao trọng số trực tuyến để người khác tải qua torrent, hoặc một bản sao lưu trữ làm điều tương tự. Mỗi người được tính là 1.000 lượt tải.
- AI Horde
- Một mạng lưới tình nguyện tạo ảnh miễn phí trên máy tính được hiến tặng. Số ảnh nó đã tạo với một mô hình được công khai, và mỗi ảnh được tính là một lượt tải.
- Trang tạo ảnh
- Các trang lưu trữ bản sao mô hình riêng và cho phép người dùng tạo ảnh, như PixAI, SeaArt và Yodayo. Lượt tải của họ được tính giống như Civitai và mỗi lần tạo ảnh được tính là một lượt tải.
- Token OpenRouter
- Mô hình văn bản phục vụ qua API, như Claude hoặc GPT, không có trọng số để tải xuống, nên sử dụng token để đo lường: các đoạn văn bản nó đọc và viết qua OpenRouter, một cổng kết nối nhiều ứng dụng sử dụng, trong 30 ngày qua. Mỗi 10,000,000 token tính là một lượt tải. Nguồn: OpenRouter (openrouter.ai/rankings), CC BY 4.0.
- Mô hình đầy đủ (checkpoint)
- Chính là trọng số, file tự tạo ảnh. Nó được cộng thêm điểm vì các add-on phụ thuộc vào nó.
- LoRA và embedding
- Các file add-on nhỏ giúp điều chỉnh trọng số của người khác theo phong cách, nhân vật hoặc ý tưởng. Chúng không thể chạy riêng.
- Gia đình và trọng số
- Nền tảng mà mô hình xây dựng trên đó, như SD 1.5, SDXL, Flux hoặc Wan. Mỗi mô hình kế thừa ngày phát hành của trọng số gia đình nó.
- Tuổi
- Điểm trừ dựa trên thời gian trọng số gia đình được phát hành: 150° mỗi năm, tối đa 750°. Nó giữ lại lượt tải cũ đã tích tụ nhiều năm bằng cách đóng băng đầu danh sách.
- Tăng gia đình
- Một đẩy nhỏ có giới hạn cho LoRA của một gia đình mà trang này đang ưu tiên, luôn được liệt kê trong phần phân tích.
- Điểm thay thế
- Một số ổn định dưới mức tối thiểu dành cho mô hình chưa có báo cáo nguồn, để danh sách luôn đầy đủ. Nó không bao giờ xếp trên mô hình có dữ liệu.
- Mới! (giai đoạn thử nghiệm)
- Mô hình dưới 7 ngày tuổi hiển thị Mới! thay vì điểm số và không được xếp hạng. Điểm số được tính từ ngày đầu tiên, nhưng mô hình mới một ngày tăng trưởng nhanh nhất, nên nếu không chờ đợi thì #1 tuần này sẽ luôn là mô hình mới ra hôm qua thay vì mô hình giữ vững trong tuần.
- Xu hướng
- Tốc độ tăng trưởng của mô hình trong một khoảng thời gian so với tốc độ tăng trưởng trung bình của mô hình khác trong cùng khoảng thời gian. Nhanh hơn trung bình là tăng, chậm hơn là giảm.
- Mô hình điển hình
- Giữa danh mục: một nửa mô hình có số liệu tăng nhanh hơn trong khoảng thời gian, một nửa tăng chậm hơn.
Cách mà độ phổ biến của mô hình này thay đổi so với phần còn lại của danh mục: sự tăng trưởng về lượt tải xuống, lượt thích và sử dụng qua từng giai đoạn, so với sự tăng trưởng điển hình của mô hình trong cùng giai đoạn, cùng với điểm nhiệt của nó lúc đó. Cao hơn mức tăng trưởng điển hình là tăng, thấp hơn là giảm. Quá khứ được tái tạo từ tổng số hiện tại, ngày đầu tiên của mô hình và tốc độ tải xuống đo được khi có hai lần đọc; mô hình không tồn tại vào đầu giai đoạn sẽ hiển thị n/a.
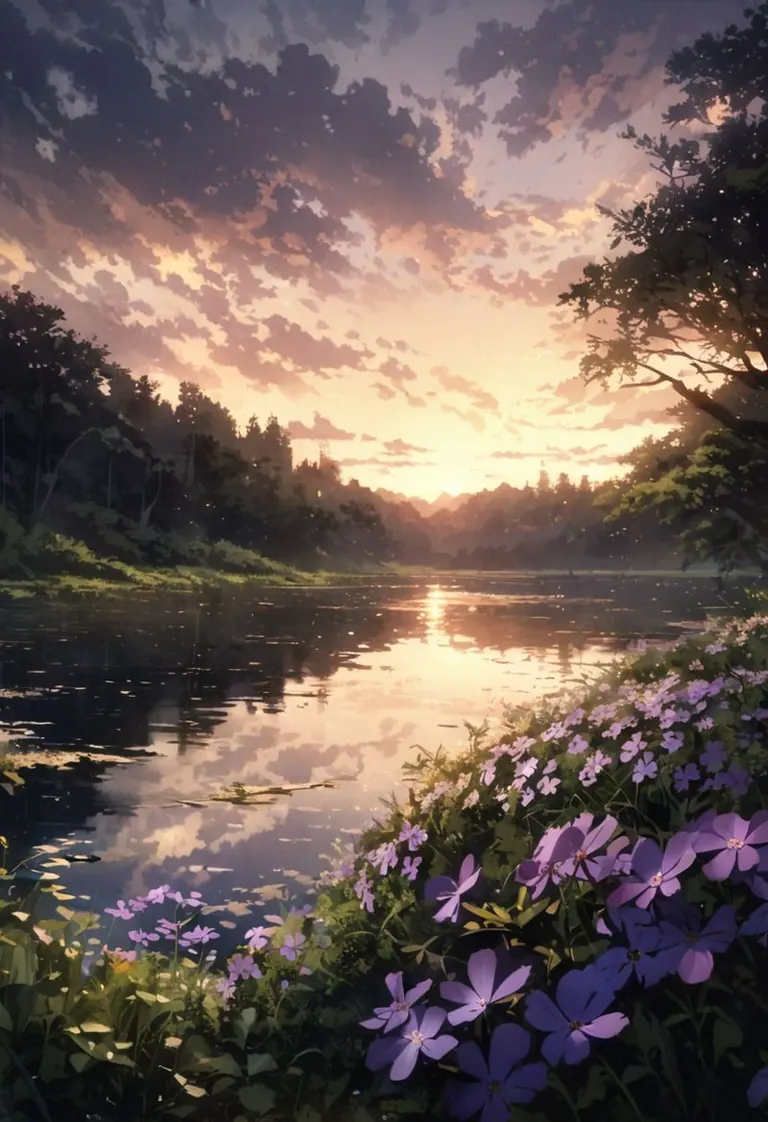
Ảnh mẫu
Prompt và thiết lập do những người tạo ra các ảnh này trên Civitai chia sẻ. Chọn một ảnh để xem nó được tạo như thế nào.
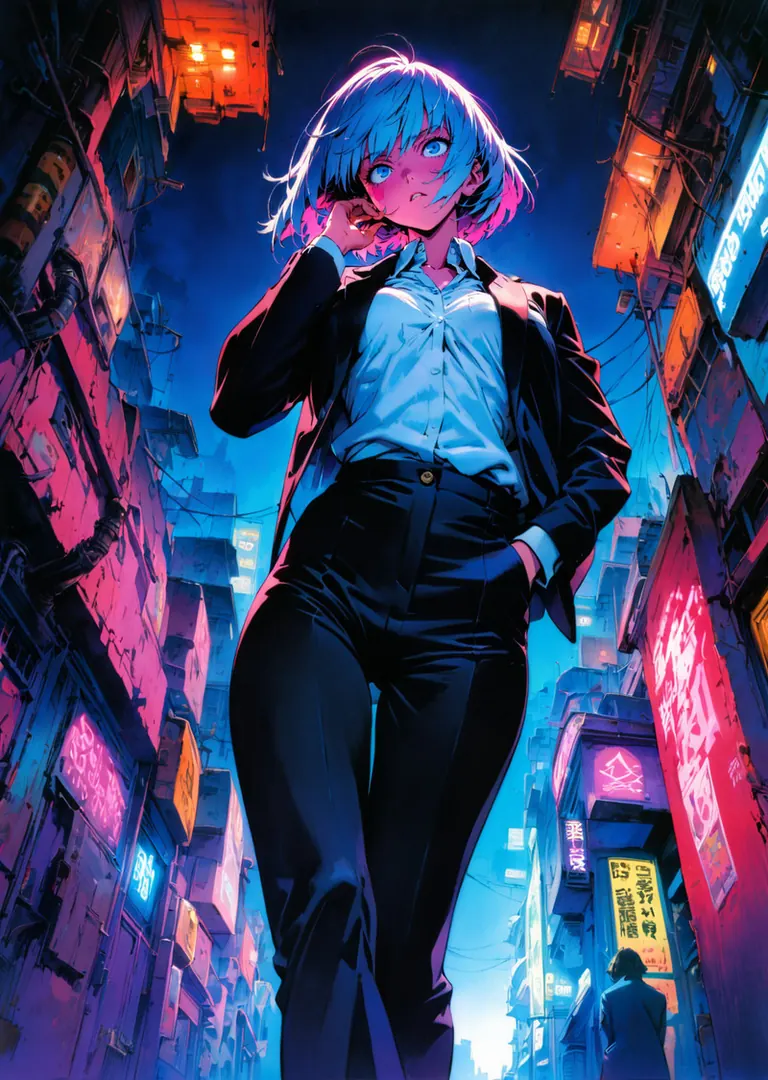
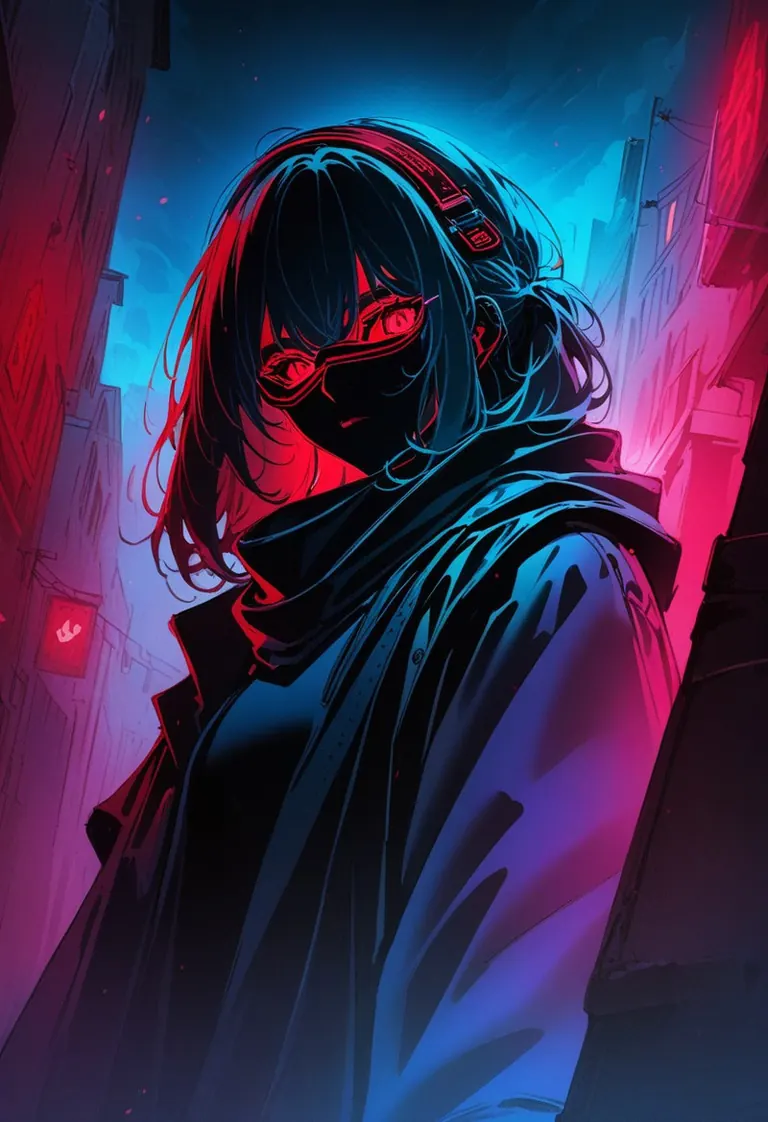
Thiết lập
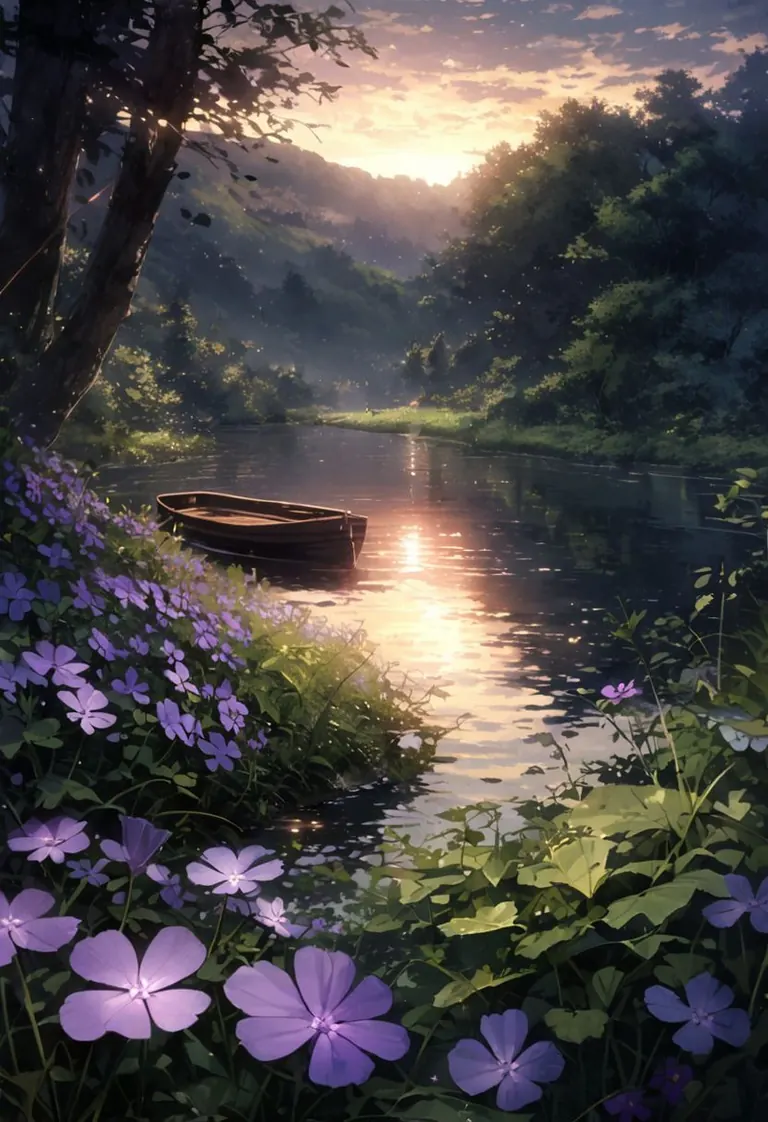
Sampler
DPM++ 2M
Số bước
42
Guidance
7
Seed
958517608
Kích thước
832x1216
Clip skip
2
Prompt
detailed background,( Calm spring night landscape), amongst lush greenery, beautiful view, creeping phlox in full bloom, creeping phlox, early morning, sunrise sky, beautiful clouds, dappled sunlight, outdoor seating, one lamp, Tranquil Lake, Boat on a Lake, depth of field, masterpiece, best quality, ultra-detailed, very aesthetic, illustration, perfect composition, intricate details, absurdres, moody lighting, wisps of light, no humans,
Prompt phủ định
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
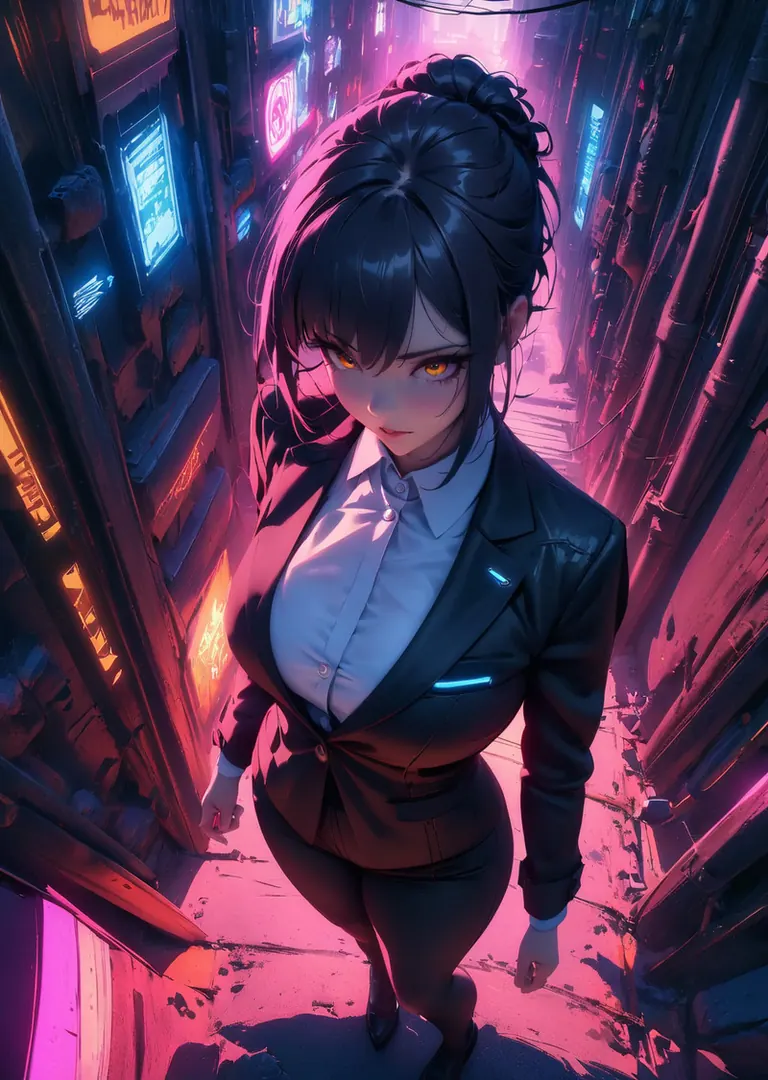
Thiết lập
Sampler
Restart
Số bước
25
Guidance
7
Seed
4257785000
Kích thước
1024x1440
Prompt
masterpiece, best quality, very aesthetic, absurdres
wlop miimalism
cinematic lighting
1girl, aged up
walking in the alley black suit white collar shirt
perspective from above
cyberpunk, neon
Prompt phủ định
lowres, worst quality, blurry, grayscale, low contrast
low quality, worst quality, normal quality
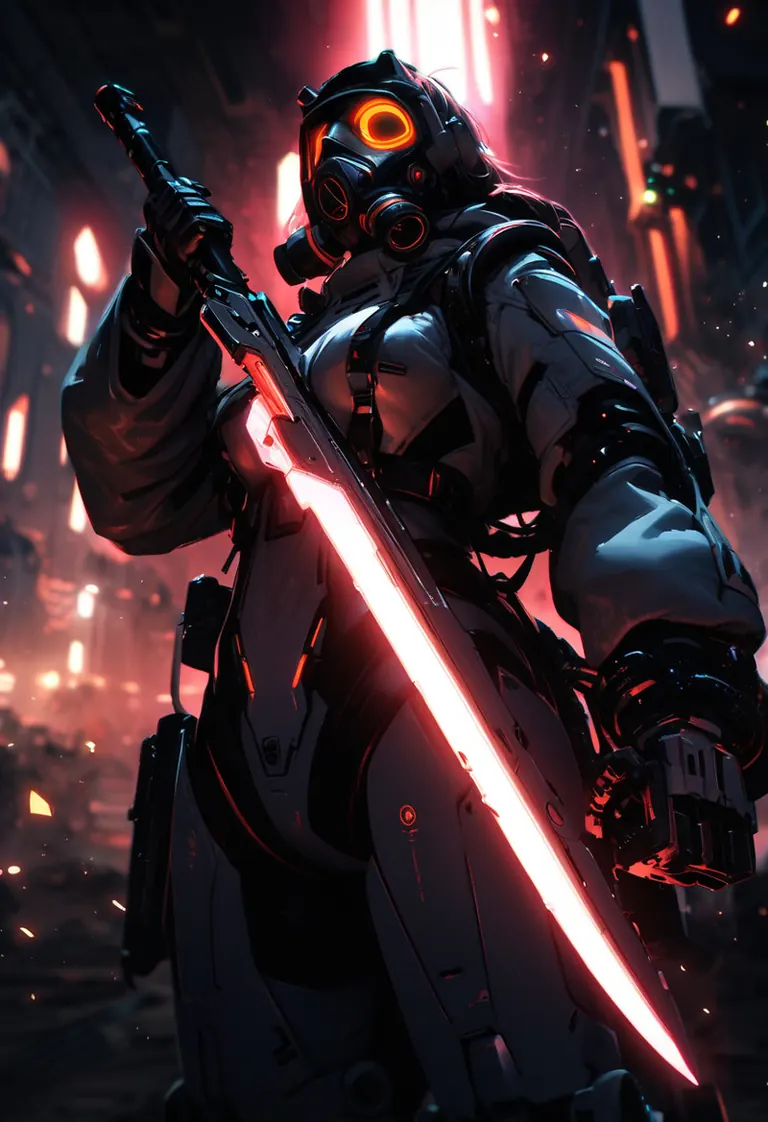
Thiết lập
Sampler
DPM++ 2M
Số bước
30
Guidance
6
Seed
585685321
Kích thước
832x1216
Clip skip
2
Prompt
(best quality), future, 1girl, solo, miko motif exoskeleton suit, led, gas mask, holding blade, machinery, digital engraving, ultra highres, absurdres, deep glow effect, hdr, light particles, cinematic lighting, depth of field
Prompt phủ định
(worst quality, low quality:1.4), (bad hands, extra fingers:1.3), missing fingers, bad feet, text, watermark, signature, sign
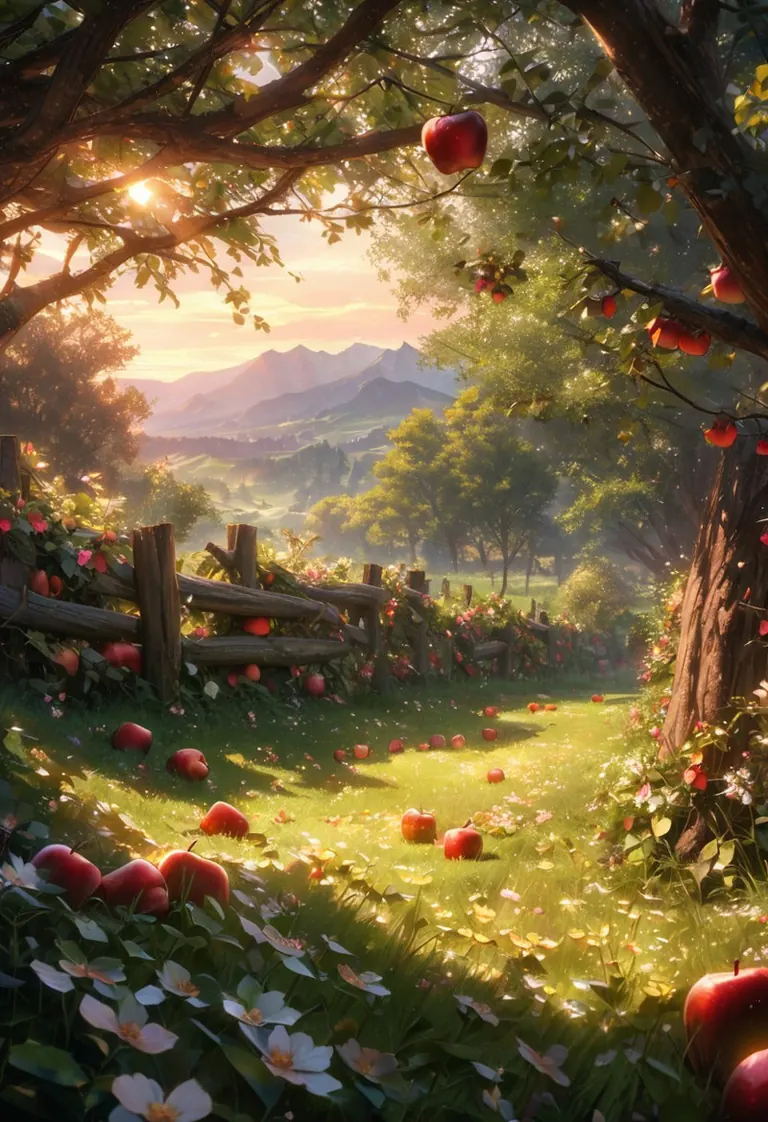
Thiết lập
Sampler
DPM++ 2M Karras
Số bước
40
Guidance
7
Seed
1535064897
Kích thước
832x1216
Clip skip
2
Prompt
(best quality, 8k, high res, masterpiece:1.2), photorealistic, ultra-detailed, vibrant photography of a picturesque apple orchard at sunset. The trees are heavy with ripe, glistening apples in shades of red, green, and gold, their leaves a vibrant, healthy green. Sunlight filters through the branches, casting a warm, golden glow over the entire scene. Delicate apple blossoms still cling to some branches, adding a touch of soft pink and white to the landscape. The ground is covered with a lush carpet of grass and wildflowers, with fallen apples scattered about. A rustic wooden fence borders the orchard, and in the background, rolling hills and distant mountains are bathed in the warm, fading light of the setting sun. A gentle breeze rustles the leaves and carries the sweet scent of apples through the air. This idyllic scene captures the serene beauty and abundance of nature in exquisite detail. (dynamic angle, cinematic lighting, ethereal atmosphere:1.1), (extremely detailed:1.2), (vivid colors:1.3), (perfect composition:1.2), (sharp focus, stunning realism:1.2)
Prompt phủ định
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
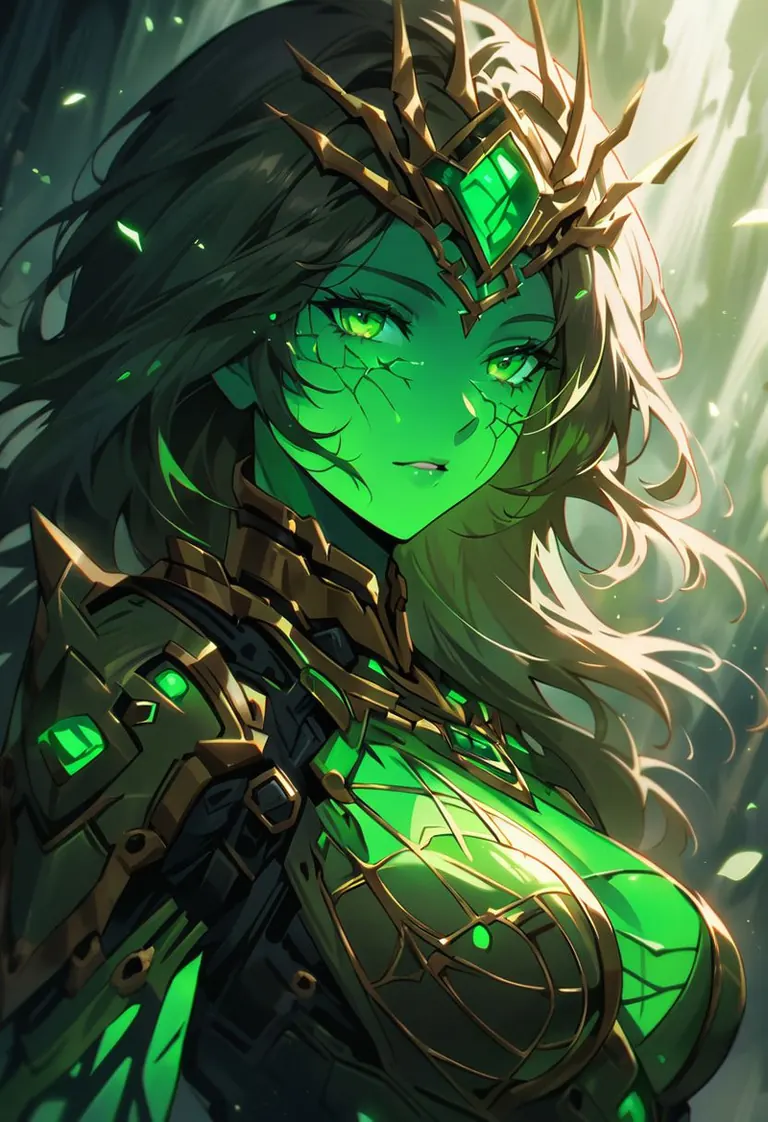
Thiết lập
Sampler
DPM++ 2M Karras
Số bước
25
Guidance
6
Seed
292950932
Kích thước
832x1216
Clip skip
2
Prompt
Sexy woman with gold and green mechanical body, glowing green face, glowing green skin, cinematic photography, golden cobweb, majestic, awesome, inspiring, closeup, smooth, atmospheric haze, cinamatic composition, soft shadows, national geographic style, green glow, extremely detailed
Prompt phủ định
easynegative, bad proportions, low resolution, bad, ugly, terrible, painting, 3d, render, comic, anime, manga, unrealistic, flat, watermark, signature, worst quality, low quality, normal quality, lowres, simple background, inaccurate limb, extra fingers, fewer fingers, missing fingers, extra arms, (extra legs:1.3), inaccurate eyes, bad composition, bad anatomy, error, extra digit, fewer digits, cropped, low res, worst quality, low quality, normal quality, jpeg artifacts, extra digit, fewer digits, trademark, watermark, artist's name, username, signature, text, words,
Thiết lập
Sampler
DPM++ 2M
Số bước
40
Guidance
7
Seed
195493639
Kích thước
832x1216
Clip skip
2
Prompt
detailed background,( Calm spring night landscape), amongst lush greenery, beautiful view, creeping phlox in full bloom, creeping phlox, early morning, sunrise sky, beautiful clouds, dappled sunlight, outdoor seating, one lamp, Tranquil Lake, Boat on a Lake, depth of field, masterpiece, best quality, ultra-detailed, very aesthetic, illustration, perfect composition, intricate details, absurdres, moody lighting, wisps of light, no humans,
Prompt phủ định
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
Thiết lập
Sampler
Restart
Số bước
25
Guidance
7
Seed
2651151167
Kích thước
1024x1440
Prompt
masterpiece, best quality, very aesthetic, absurdres
by sadamoto yoshiyuki, 1girl, aged up walking in the alley
short hair
black suit white collar shirt
wind
perspective from below
cyberpunk, neon
Prompt phủ định
lowres, worst quality, blurry, grayscale, low contrast
low quality, worst quality, normal quality
Thiết lập
Sampler
Euler a
Số bước
36
Guidance
10
Seed
2073484151
Kích thước
832x1216
Clip skip
2
Prompt
(masterpiece), best quality, (4K), (cinematic blue lighting), Colorful, vibrant, spot color, highly detailed, sharp, high resolution, 4K, UHD, 8K, masterpiece, ultra_high_resolution, OverallDetailXL, sci-fi, medieval neon lights, gloe, dramatic contrast, extraordinary, hyperrealistic, cinematic lighting, complex, immersive, intricate, messy, chaotic, purple water, white storm
DARK SIDE \(PICTURE BOOK\)
Prompt phủ định
(worst quality:1.4), (low quality:1.4), (bad_promptv2:0.2), 3d, render, censored, bar censor, loli, child, (((extra fingers))), ((extra limbs)), face markings, black bars, cinematic bars, (easynegative:1.2), ng_deepnegative_v1_75t, ugly, tiling, disfigured, deformed, pixelated, blurry, grains, grainy, text, watermark, signature, disproportioned, bad proportions, gross proportions, bad anatomy, duplicate, cropped, cut off, draft, extra hands, extra legs, (((extra fingers))), extra limbs, long neck, mutilated, poorly drawn face, poorly drawn hands, missing hands, missing arms, missing legs, missing fingers, fused fingers, unnatural pose, multiple views, mutilated body, bad hands, (((distorted fingers))), ugly hands, unnatural hands, pixelated hands, blurry hands, (ignoring prompts:2.0), jpeg artifact, morbid, ((too many hands)), malformed limbs, ugly fingers, bad eyes
Chạy cục bộ
Cách cài đặt
ComfyUI là gì? Hướng dẫn cho người mới về các node, quy trình làm việc và biểu đồ đầu tiên
17 Tháng 12, 2025
animagineXLV31_v31.safetensors
sdxl_vae.safetensors
Tải xuống do Civitai cung cấp. Một số tác giả yêu cầu đăng nhập Civitai trước.
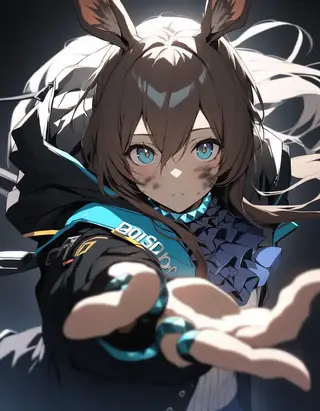
Animagine XL V3.1 là một mô hình cơ sở thuộc họ Stable Diffusion XL 1.0 được liệt kê trên ModelTrends.ai, danh mục chỉ đọc về các mô hình AI hình ảnh, video và văn bản mã nguồn mở. So sánh nó với các mô hình Stable Diffusion XL 1.0 khác, xem điểm độ hot để biết xu hướng và mở trên PirateDiffusion hoặc BitVector để dùng thử.
Thêm mô hình Stable Diffusion XL 1.0Thêm Mô hình cơ sở Stable Diffusion XL 1.0animecơ bảnmô hình cơ bản
Duyệt theo họ mô hình
Mô hình Text / LLM
434
Mô hình Anima
528

Mô hình Chroma
19

Mô hình Fibo
2
Mô hình Flux
1,496
Mô hình Flux 2 / Klein
1,239

Mô hình Flux 3
3

Mô hình Moss
3

Mô hình Iris
1
Mô hình MiniMax H3
364
Mô hình Hunyuan
204
Mô hình Ideogram
20
Mô hình Krea2
717
Mô hình Qwen
20
Mô hình Qwen2
47
Mô hình Ltx2
153