
Animagine XL V3.1
9534°
<animagine31-xl>
ModelTrends 태그를 지원하는 앱에서는 이 코드를 프롬프트에 복사해 붙여넣기만 하면 별도 설정 없이 모델을 실행하거나 설치할 수 있어요. Prism(아래) 같은 지원 앱에서 아이콘을 찾아보세요.
모델 실행
제공 / 광고

Easy Creator (Prism) 웹
무제한 · 정액제
초보자에게 최적. 강력한 워크플로우, 낮은 학습 곡선.

PirateDiffusion 텔레그램
무제한 · 정액제
영상, 이미지, 맞춤형 채팅 페르소나 등 다양하게 만들어 보세요.

Pro studio (SpyGlass) 웹
무제한 · 정액제
어떤 브라우저나 휴대폰에서도 모델을 탐색하고 렌더링하며 수정하세요.

Discord bot (Vector) 디스코드
무제한 · 정액제
Vector를 서버에 추가하거나 Vector Discord에 참여하세요. 무엇이든 만들어 보세요!

Unified Editor 웹
무제한 · 정액제
이미지와 비디오 편집기: 한 페이지에서 렌더링, 편집, 업스케일 등 모두 가능합니다.

Civitai 웹
사용량별 결제
Civitai 사이트에서 생성; 이미지마다 Buzz 크레딧 사용.

로컬 앱
설정 필요
내 컴퓨터 성능이 되면 로컬 프로그램을 설치해.

ModelDuel 웹
사용량별 결제
한 번에 최대 50개의 체크포인트/기본 모델에서 동일한 프롬프트를 생성하세요.

제작자 노트
Animagine XL 3.1 is an update in the Animagine XL V3 series, enhancing the previous version, Animagine XL 3.0. This open-source, anime-themed text-to-image model has been improved for generating anime-style images with higher quality. It includes a broader range of characters from well-known anime series, an optimized dataset, and new aesthetic tags for better image creation. Built on Stable Diffusion XL, Animagine XL 3.1 aims to be a valuable resource for anime fans, artists, and content creators by producing accurate and detailed representations of anime characters.
Model Details
-
Developed by:
-
In collaboration with:
-
Model type: Diffusion-based text-to-image generative model
-
Model Description: Animagine XL 3.1 generates high-quality anime images from textual prompts. It boasts enhanced hand anatomy, improved concept understanding, and advanced prompt interpretation.
-
License:
-
Fine-tuned from:
Usage Guidelines
Tag Ordering
For optimal results, it's recommended to follow the structured prompt template because we train the model like this:
1girl/1boy, character name, from what series, everything else in any order.
Special Tags
Animagine XL 3.1 utilizes special tags to steer the result toward quality, rating, creation date and aesthetic. While the model can generate images without these tags, using them can help achieve better results.
Quality Modifiers
Quality tags now consider both scores and post ratings to ensure a balanced quality distribution. We've refined labels for greater clarity, such as changing 'high quality' to 'great quality'.
Quality Modifier Score Criterion
masterpiece > 95%
best quality > 85% & ≤ 95%
great quality > 75% & ≤ 85%
good quality > 50% & ≤ 75%
normal quality > 25% & ≤ 50%
low quality > 10% & ≤ 25%
worst quality ≤ 10%
Rating Modifiers
We've also streamlined our rating tags for simplicity and clarity, aiming to establish global rules that can be applied across different models. For example, the tag 'rating: general' is now simply 'general', and 'rating: sensitive' has been condensed to 'sensitive'.
Rating Modifier Rating Criterion
safe General
sensitive Sensitive
nsfw Questionable
explicit, nsfw Explicit
Year Modifier
We've also redefined the year range to steer results towards specific modern or vintage anime art styles more accurately. This update simplifies the range, focusing on relevance to current and past eras.
Year Tag Year Range
newest 2021 to 2024
recent 2018 to 2020
mid 2015 to 2017
early 2011 to 2014
oldest 2005 to 2010
Aesthetic Tags
We've enhanced our tagging system with aesthetic tags to refine content categorization based on visual appeal. These tags are derived from evaluations made by a specialized ViT (Vision Transformer) image classification model, specifically trained on anime data. For this purpose, we utilized the model , which assesses the aesthetic value of content before it undergoes training. This ensures that each piece of content is not only relevant and accurate but also visually appealing.
Aesthetic Tag Score Range
very aesthetic > 0.71
aesthetic > 0.45 & 0.27 & < 0.45
very displeasing ≤ 0.27
Recommended settings
To guide the model towards generating high-aesthetic images, use negative prompts like:
nsfw, lowres, (bad), text, error, fewer, extra, missing, worst quality, jpeg artifacts, low quality, watermark, unfinished, displeasing, oldest, early, chromatic aberration, signature, extra digits, artistic error, username, scan, [abstract]
For higher quality outcomes, prepend prompts with:
masterpiece, best quality, very aesthetic, absurdres
it’s recommended to use a lower classifier-free guidance (CFG Scale) of around 5-7, sampling steps below 30, and to use Euler Ancestral (Euler a) as a sampler.
Multi Aspect Resolution
This model supports generating images at the following dimensions:
Dimensions Aspect Ratio
1024 x 1024 1:1 Square
1152 x 896 9:7
896 x 1152 7:9
1216 x 832 19:13
832 x 1216 13:19
1344 x 768 7:4 Horizontal
768 x 1344 4:7 Vertical
1536 x 640 12:5 Horizontal
640 x 1536 5:12 Vertical
Acknowledgements
The development and release of Animagine XL 3.1 would not have been possible without the invaluable contributions and support from the following individuals and organizations:
-
: Our collaboration partner and sponsor.
-
: For providing the aesthetic classification model, .
-
: For their custom learning rate scheduler, adapted from .
-
: For their comprehensive training scripts.
-
Cagliostrolab Collaborators: For their dedication to model training, project management, and data curation.
-
Early Testers: For their valuable feedback and quality assurance efforts.
-
NovelAI: For their innovative approach to aesthetic tagging, which served as an inspiration for our implementation.
Thank you all for your support and expertise in pushing the boundaries of anime-style image generation.
Limitations
While Animagine XL 3.1 represents a significant advancement in anime-style image generation, it is important to acknowledge its limitations:
-
Anime-Focused: This model is specifically designed for generating anime-style images and is not suitable for creating realistic photos.
-
Prompt Complexity: This model may not be suitable for users who expect high-quality results from short or simple prompts. The training focus was on concept understanding rather than aesthetic refinement, which may require more detailed and specific prompts to achieve the desired output.
-
Prompt Format: Animagine XL 3.1 is optimized for Danbooru-style tags rather than natural language prompts. For best results, users are encouraged to format their prompts using the appropriate tags and syntax.
-
Anatomy and Hand Rendering: Despite the improvements made in anatomy and hand rendering, there may still be instances where the model produces suboptimal results in these areas.
-
Dataset Size: The dataset used for training Animagine XL 3.1 consists of approximately 870,000 images. When combined with the previous
SHA256
E3C47AEDB06418C6C331443CD89F2B3B3B34B7ED2102A3D4C4408A8D35AAD6B0
Animagine XL V3.1 인기 추세
히트 점수, 지난 12개월
인기 점수
9,534°
이번 주
▼
0.6%
9,537° 당시, 9,534° 현재
이번 달
▼
2.5%
9,546° 당시, 9,534° 현재
지난 1년
▼
29.8%
9,683° 당시, 9,534° 현재
7,000°
기준점
점수는 0°부터 9,999°까지 있어. 7,000° 아래는 아직 어떤 출처에서도 보고되지 않은 모델들을 위해 남겨둔 영역이고, 그 모델들은 목록이 완성되도록 임시 점수를 받지. 7,000°가 실제 측정 데이터가 시작되는 지점이야: 실제 데이터는 있지만 다운로드가 거의 없는 모델은 기준점에 위치하고, 그 위로 측정된 점수가 쌓여. 기준점 자체는 모델에 대해 아무것도 말해주지 않고, 위에 쌓인 점수만이 모델 간 차이를 만들어.
+45°
Civitai 다운로드
Civitai에서 이 정확한 버전의 다운로드 수 181,860회. 다운로드가 가장 큰 비중이며 로그 스케일로 계산됩니다: 다운로드가 10배 증가하면 300°만큼 증가하므로 백만 다운로드 모델이 천 다운로드 모델보다 1000배 뜨겁지 않습니다. 여섯 다운로드 출처가 이 수치를 공유하며 각 출처 비중에 따라 분배됩니다.
+2,054°
생성 사이트
Yodayo에서 이 모델 복사본의 다운로드와 생성 실행이 8,138,965번 있었어. 각 실행은 다운로드 한 번과 같고, 다운로드는 Civitai와 똑같이 계산돼; 모두 다운로드 항목을 공유해.
+651°
좋아요
출처 전반에서 21,928개의 좋아요와 엄지 척이 있어. 좋아요 한 개는 다운로드 절반의 가치가 있고, 같은 로그 스케일로 계산돼.
+131°
채택률
출처를 두 번 측정한 사이에 하루 약 55번 다운로드돼. 평생 평균에서 추측한 게 아니야. 속도는 다운로드 항목의 4분의 1 가치를 가지니, 최근 급증이 나타나도 하루짜리 급등이 수년간 사용량을 앞서지 못해.
+150°
전체 모델
+150°는 이게 전체 모델이기 때문이야: 체크포인트, 즉 가중치 자체야. LoRA나 임베딩은 다른 사람 가중치에 덧붙이는 거라, 같은 인기도라면 체크포인트보다 순위가 높지 않아.
−497°
연령
−497°는 SDXL 가중치가 2023에 나왔기 때문이야. 모든 모델은 기반 가중치의 연령을 물려받아: 연간 150°, 최대 750°까지 점수가 깎이고, 그때까지 계속 커져. 이게 없으면 목록 상위가 2022년과 2023년 체크포인트로만 채워졌을 거야, 다운로드가 쌓일 시간이 있었으니까.
상세 내역 보기
이 사이트의 모든 숫자는 확인할 수 있어. 이 모델의 히트 점수는 9,534°이고, 여기서는 각 요소가 하나씩 더해지면서 누적 합계가 표시돼: 기준점, 각 출처가 더하는 점수, 모델 종류에 따른 보너스, 그리고 가중치의 연령이 빼는 점수. 색깔은 위 차트의 구간을 나타내. 마지막에 용어집에서 모든 용어를 정의해.
- 1기준점부터 시작해.왜 7,000°이고 0이 아닌지: 점수는 0°부터 9,999°까지 있고, 7,000° 아래는 아직 출처가 보고하지 않은 모델을 위해 남겨둔 영역이야. 그 모델들은 목록 완성을 위해 임시 점수를 받고, 데이터가 있는 모델보다 순위가 높지 않아. 7,000°가 실제 측정 데이터가 시작되는 지점이야. 실제 데이터가 있지만 다운로드가 거의 없는 모델은 여기 있고, 그 뒤로는 모두 측정된 점수야. 기준점 위에는 다운로드가 10배씩 늘어날 때마다 300°씩 10단계가 있어. 기준점은 모든 모델에 같아서 아무것도 결정하지 않고, 위 점수가 모델을 구분해.7,000°누적 합계
- 2다운로드 수를 더해.총 8,320,825개의 다운로드 동등치, Civitai 다운로드, 생성 사이트에서 나왔어. 다운로드가 10배 늘어나면 같은 300°가 더해지니까, 크기가 중요하지만 점수를 독차지하지는 않아.+45° Civitai 다운로드+2,054° 생성 사이트+2,099°9,099°누적 합계
- 3좋아요 수를 더해.21,928개의 좋아요와 엄지척, 다운로드의 절반 무게로 계산해.+651°9,750°누적 합계
- 4채택률을 추가하세요.지금 하루 약 55개의 다운로드가 있어, 두 번 측정한 차이로 계산하고 무게는 4분의 1이야.+131°9,881°누적 합계
- 5전체 모델에 보너스.체크포인트는 가중치 자체를 담고 있어; 애드온은 같은 인기도면 체크포인트보다 점수가 높지 않아.+150°10,031°누적 합계
- 6연령을 제외하세요.SDXL 가중치는 2023에 나왔어: 연간 150°, 최대 750°까지, 그때까지 점점 커져.−497°9,534°누적 합계
- =히트 점수.이 모델이 이 사이트 모든 목록에서 어디에 있는지 보여줘. 다른 건 조정하지 않아.9,534°
용어집: 여기서 쓰는 말들
- 히트 점수
- 모델이 지금 얼마나 쓰이고 원하는지 한 숫자로 나타낸 거야, 0°부터 9,999°까지. 이 사이트에서 가장 인기 있는 목록은 모두 이 점수로 정렬돼.
- 기본 점수
- 실제 데이터가 있는 모든 모델이 시작하는 7,000°야. 점수는 0°부터 9,999°까지인데, 기본 점수 아래는 데이터 없는 모델(대체 모델)용으로 남겨둬서 데이터 있는 모델이 항상 위에 오도록 해. 기본 점수는 모두 같고 아무것도 결정하지 않아; 그 위 점수가 실제 측정치야.
- 다운로드 동등치
- 점수가 다운로드로 취급하는 모든 걸 합친 거야: 실제 다운로드, 토렌트 시더 1,000개씩, AI Horde 이미지와 생성 사이트 실행 1개씩.
- 로그 스케일
- 1씩이 아니라 10씩 세는 거야: 1,000에서 10,000 다운로드가 늘면 10,000에서 100,000 늘어난 것과 같은 점수가 더해져. 큰 모델이 다 차지하는 걸 막아줘.
- 좋아요
- 모든 출처의 좋아요와 엄지척, 로그 스케일에서 다운로드 절반 가치야.
- 채택률
- 두 번 측정한 차이로 계산한 지금 하루 다운로드 수야. 다운로드 항목 무게의 4분의 1이야.
- 측정 및 추정
- 측정은 두 번의 소스 읽기가 존재하고 그 차이가 실제라는 뜻이야. 추정은 오늘의 총합만 알고 과거는 모델의 전체 기간에 나눠서 보여주는 거야; 사이트에서 어떤 걸 보여주는지 알려줘.
- 시더
- 토렌트를 통해 다른 사람이 다운로드할 수 있도록 가중치 파일을 온라인에 보관하는 사람이나 호스팅 미러를 말해. 각각 1,000번 다운로드로 계산돼.
- AI 호드
- 기부받은 컴퓨터에서 무료로 이미지를 생성하는 자원봉사 네트워크야. 모델로 만든 이미지 수가 공개되고, 각각이 한 번의 다운로드로 계산돼.
- 생성 사이트
- PixAI, SeaArt, Yodayo 같은 모델 복사본을 직접 호스팅하고 사람들이 생성할 수 있게 하는 사이트들이야. 이들의 다운로드는 Civitai와 같고, 생성 한 번이 한 번의 다운로드로 계산돼.
- OpenRouter 토큰
- Claude나 GPT 같은 API를 통해 제공되는 텍스트 모델은 다운로드할 가중치가 없으므로, 지난 30일간 OpenRouter를 통해 읽고 쓴 텍스트 조각인 토큰 수로 사용량을 측정합니다. 10,000,000 토큰마다 다운로드 1회로 계산합니다. 출처: OpenRouter (openrouter.ai/rankings), CC BY 4.0.
- 전체 모델 (체크포인트)
- 가중치 자체, 혼자서 생성하는 파일이야. 애드온이 이걸 기반으로 하기 때문에 보너스 점수를 받아.
- LoRA와 임베딩
- 다른 사람의 가중치를 특정 스타일, 캐릭터, 개념 쪽으로 조정하는 작은 추가 파일이야. 혼자 실행할 수 없어.
- 패밀리와 가중치
- 모델이 기반으로 하는 것, 예를 들어 SD 1.5, SDXL, Flux, Wan 같은 거야. 모든 모델은 패밀리 가중치의 출시일을 물려받아.
- 연령
- 패밀리 가중치가 나온 지 얼마나 됐는지에 따라 점수를 깎아: 1년에 150°, 최대 750°까지. 오래된 다운로드는 리스트 상단 고정을 풀어 쌓이도록 해.
- 패밀리 부스트
- 이 사이트가 지금 밀고 있는 패밀리의 LoRA에 주는 작고 제한된 점수 조정으로, 항상 세부 내역에 표시돼.
- 대체 점수
- 아직 소스 보고가 없는 모델에 안정적으로 주는 최저 점수로, 리스트가 완전하게 유지되도록 해. 데이터가 있는 모델보다 절대 높게 평가되지 않아.
- 신규! (유예 기간)
- 7일 미만의 신규 모델은 점수 대신 '신규!' 표시가 나오며 순위에 포함되지 않습니다. 점수는 첫날부터 계산되지만, 하루 된 모델은 매우 빠르게 성장하므로 유예 기간 없이는 항상 어제 나온 모델이 이번 주 #1이 되어버립니다.
- 추세
- 한 기간 동안 모델의 성장 속도가 같은 기간의 일반 모델 성장 속도와 비교해서 어떤지 보여줘. 일반보다 빠르면 상승, 느리면 하락으로 봐.
- 일반 모델
- 카탈로그의 중간값: 수치가 있는 모델 중 절반은 기간 동안 더 빨리 성장했고, 절반은 더 느리게 성장했어.
이 모델의 인기가 카탈로그 다른 모델들과 비교해 어떻게 움직였는지 보여줘: 각 기간마다 다운로드, 좋아요, 사용량이 얼마나 늘었는지, 같은 기간 보통 모델의 성장과 비교해서, 그때의 히트 점수와 함께. 보통 성장보다 위면 상승, 아래면 하락으로 봐. 과거는 오늘까지의 총합, 모델 첫 날, 두 번 측정된 다운로드 속도로 재구성돼; 기간 시작에 없던 모델은 n/a로 표시돼.
예시 작품
Civitai에서 이 작품들을 만든 사람들이 공유한 프롬프트와 설정입니다. 작품을 선택하면 어떻게 만들어졌는지 볼 수 있습니다.
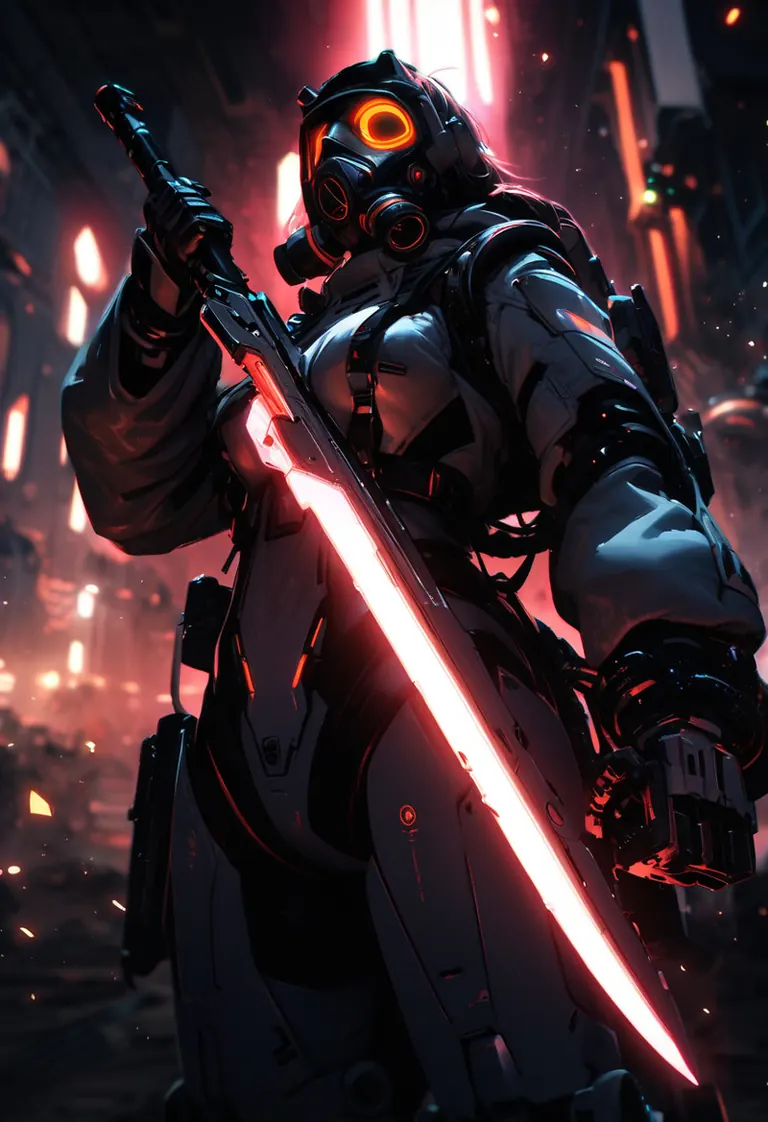
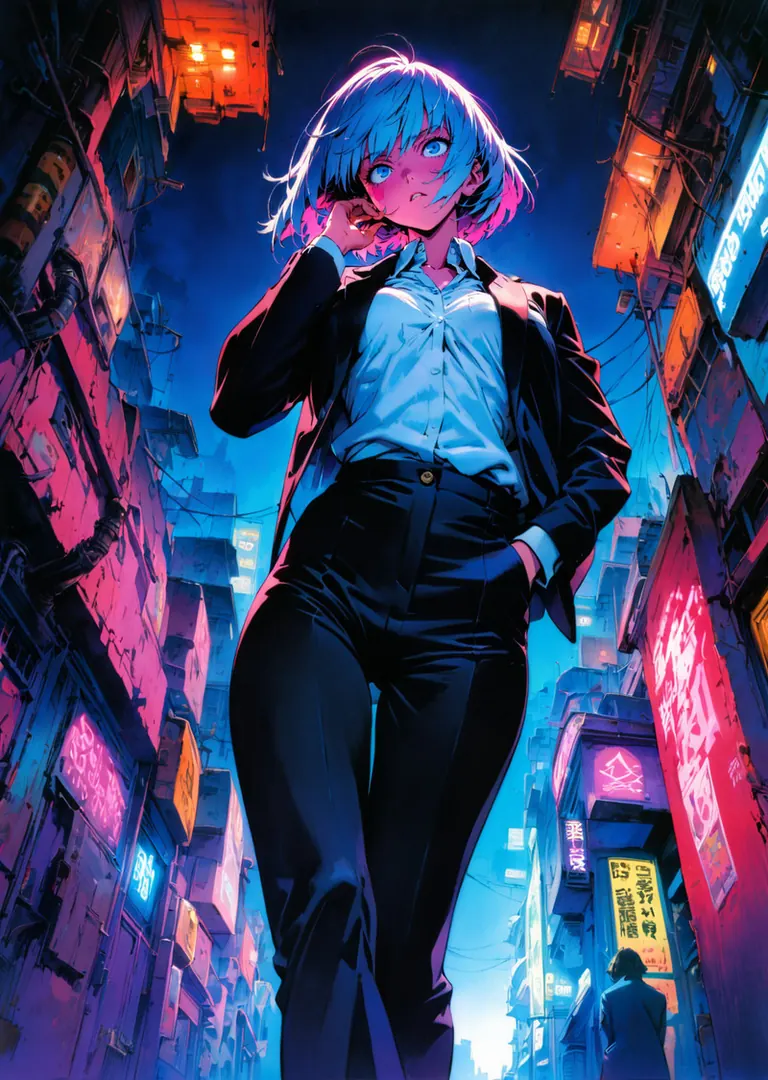
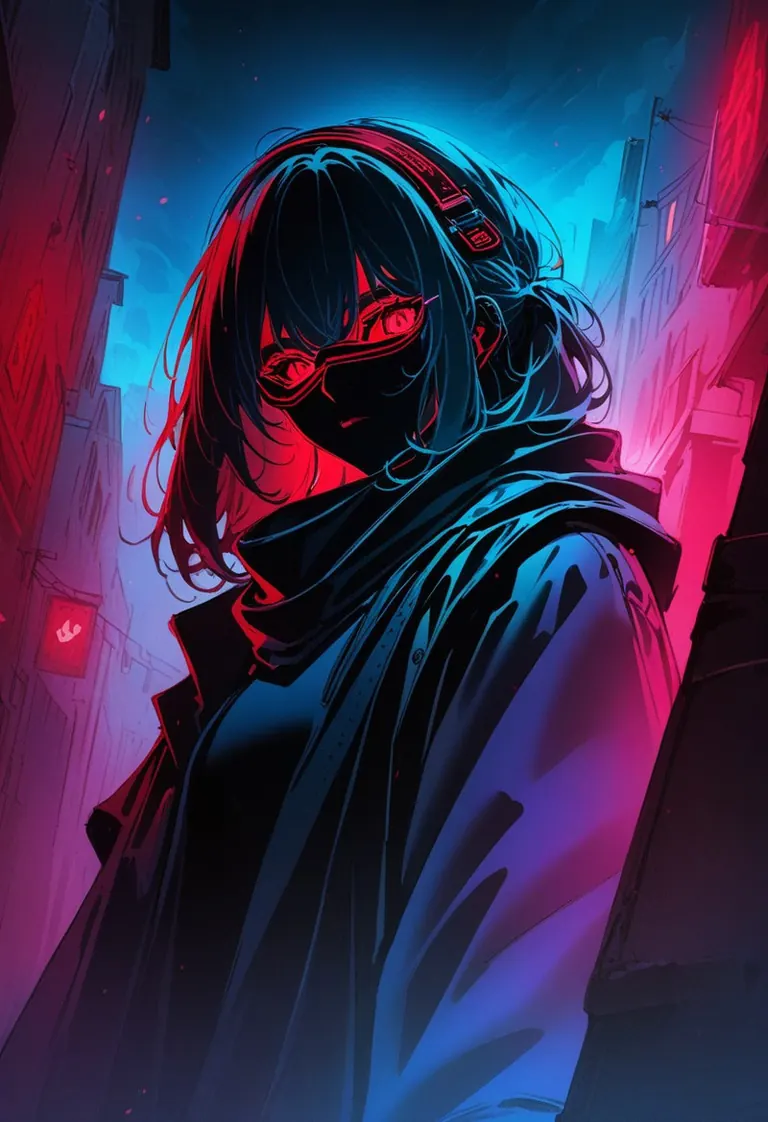
설정
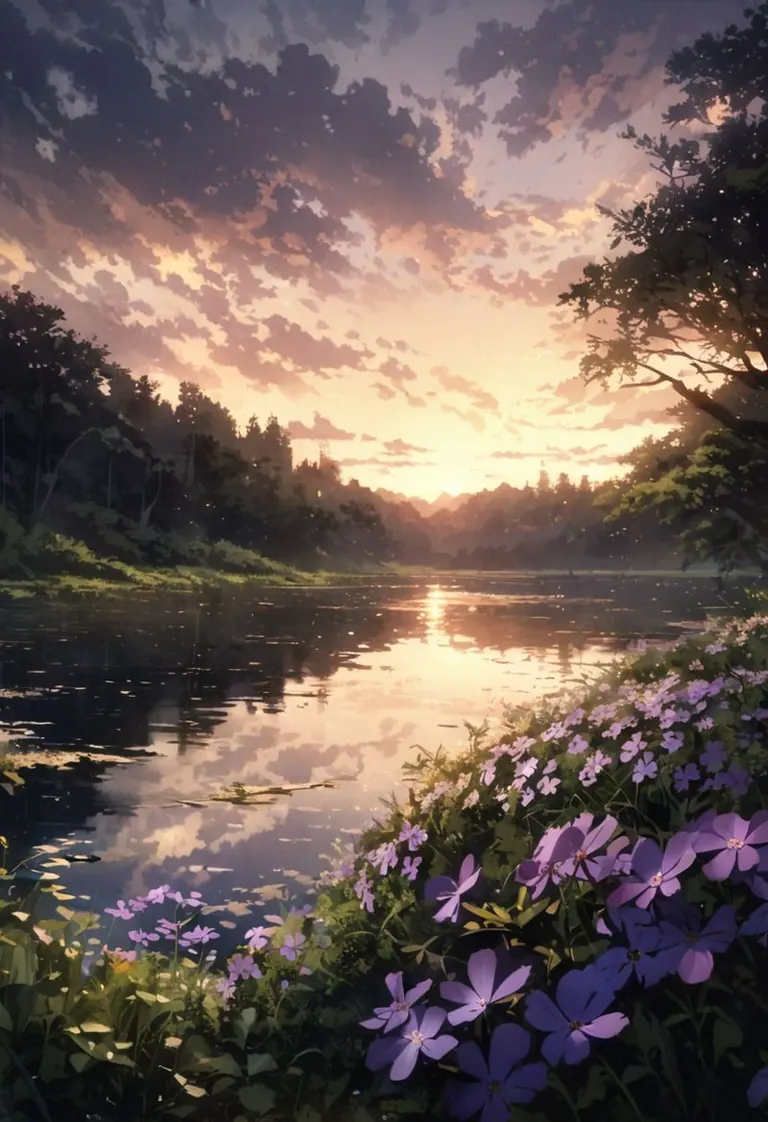
샘플러
DPM++ 2M
스텝
42
가이던스
7
시드
958517608
크기
832x1216
Clip skip
2
프롬프트
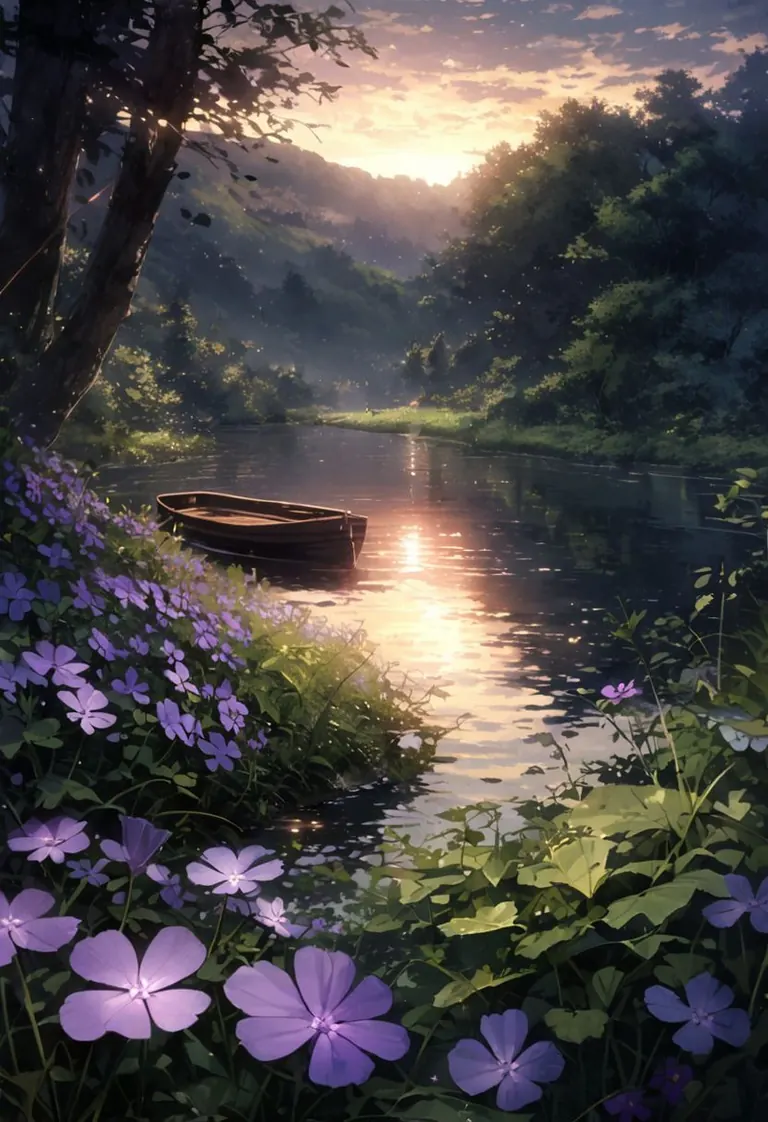
detailed background,( Calm spring night landscape), amongst lush greenery, beautiful view, creeping phlox in full bloom, creeping phlox, early morning, sunrise sky, beautiful clouds, dappled sunlight, outdoor seating, one lamp, Tranquil Lake, Boat on a Lake, depth of field, masterpiece, best quality, ultra-detailed, very aesthetic, illustration, perfect composition, intricate details, absurdres, moody lighting, wisps of light, no humans,
네거티브 프롬프트
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
설정
샘플러
Restart
스텝
25
가이던스
7
시드
4257785000
크기
1024x1440
프롬프트
masterpiece, best quality, very aesthetic, absurdres
wlop miimalism
cinematic lighting
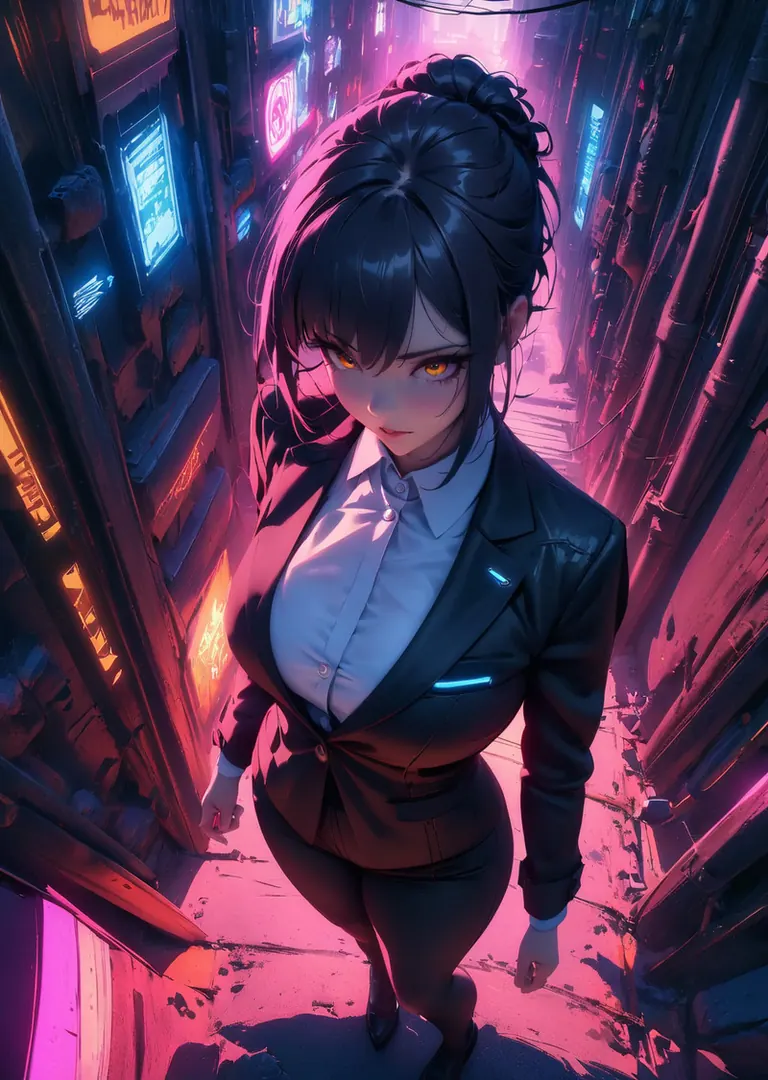
1girl, aged up
walking in the alley black suit white collar shirt
perspective from above
cyberpunk, neon
네거티브 프롬프트
lowres, worst quality, blurry, grayscale, low contrast
low quality, worst quality, normal quality
설정
샘플러
DPM++ 2M
스텝
30
가이던스
6
시드
585685321
크기
832x1216
Clip skip
2
프롬프트
(best quality), future, 1girl, solo, miko motif exoskeleton suit, led, gas mask, holding blade, machinery, digital engraving, ultra highres, absurdres, deep glow effect, hdr, light particles, cinematic lighting, depth of field
네거티브 프롬프트
(worst quality, low quality:1.4), (bad hands, extra fingers:1.3), missing fingers, bad feet, text, watermark, signature, sign
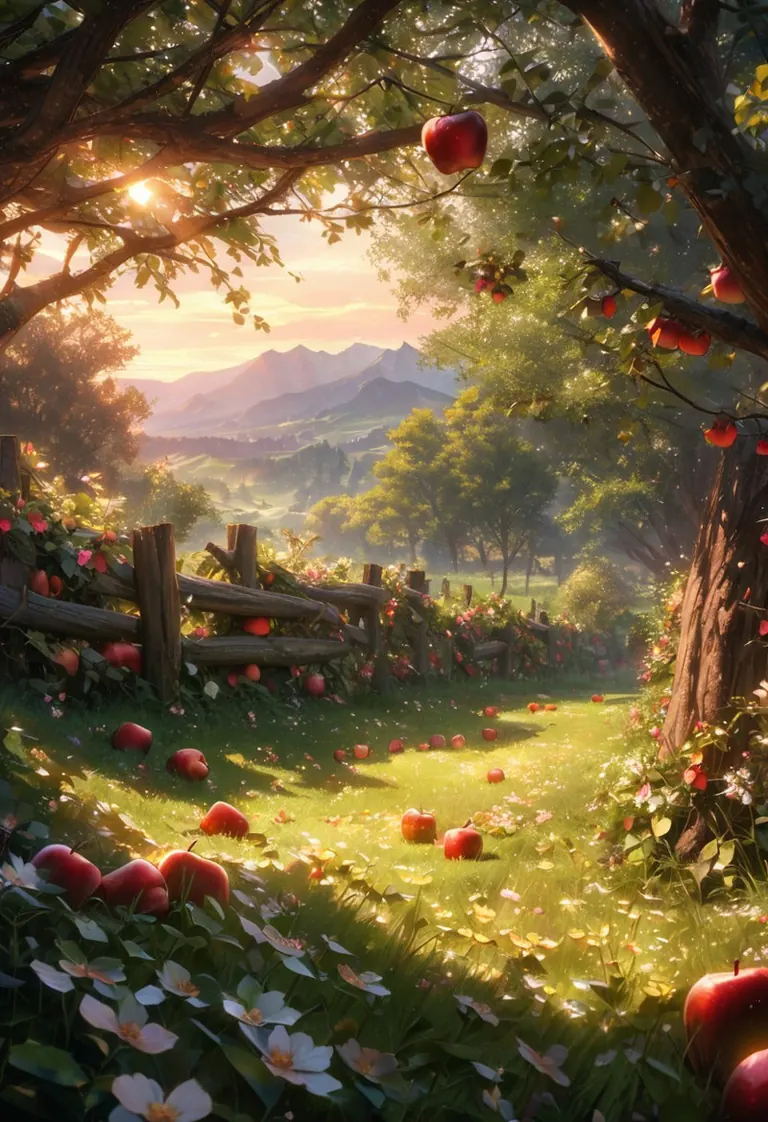
설정
샘플러
DPM++ 2M Karras
스텝
40
가이던스
7
시드
1535064897
크기
832x1216
Clip skip
2
프롬프트
(best quality, 8k, high res, masterpiece:1.2), photorealistic, ultra-detailed, vibrant photography of a picturesque apple orchard at sunset. The trees are heavy with ripe, glistening apples in shades of red, green, and gold, their leaves a vibrant, healthy green. Sunlight filters through the branches, casting a warm, golden glow over the entire scene. Delicate apple blossoms still cling to some branches, adding a touch of soft pink and white to the landscape. The ground is covered with a lush carpet of grass and wildflowers, with fallen apples scattered about. A rustic wooden fence borders the orchard, and in the background, rolling hills and distant mountains are bathed in the warm, fading light of the setting sun. A gentle breeze rustles the leaves and carries the sweet scent of apples through the air. This idyllic scene captures the serene beauty and abundance of nature in exquisite detail. (dynamic angle, cinematic lighting, ethereal atmosphere:1.1), (extremely detailed:1.2), (vivid colors:1.3), (perfect composition:1.2), (sharp focus, stunning realism:1.2)
네거티브 프롬프트
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
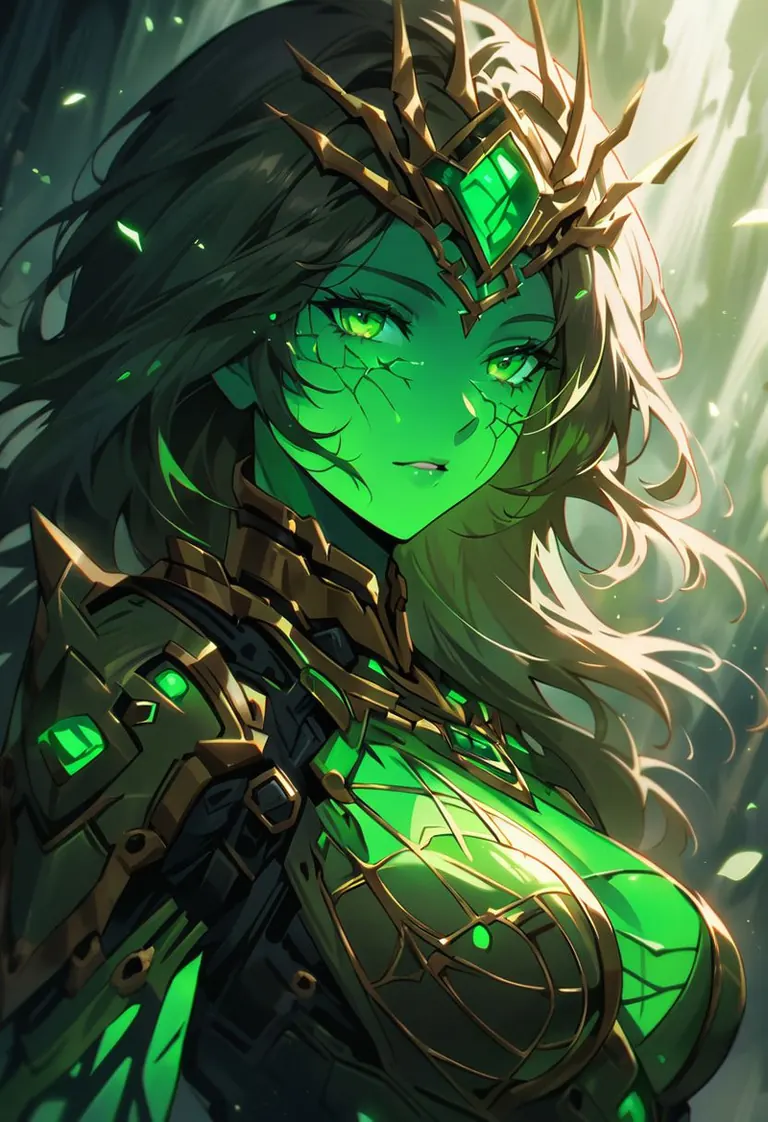
설정
샘플러
DPM++ 2M Karras
스텝
25
가이던스
6
시드
292950932
크기
832x1216
Clip skip
2
프롬프트
Sexy woman with gold and green mechanical body, glowing green face, glowing green skin, cinematic photography, golden cobweb, majestic, awesome, inspiring, closeup, smooth, atmospheric haze, cinamatic composition, soft shadows, national geographic style, green glow, extremely detailed
네거티브 프롬프트
easynegative, bad proportions, low resolution, bad, ugly, terrible, painting, 3d, render, comic, anime, manga, unrealistic, flat, watermark, signature, worst quality, low quality, normal quality, lowres, simple background, inaccurate limb, extra fingers, fewer fingers, missing fingers, extra arms, (extra legs:1.3), inaccurate eyes, bad composition, bad anatomy, error, extra digit, fewer digits, cropped, low res, worst quality, low quality, normal quality, jpeg artifacts, extra digit, fewer digits, trademark, watermark, artist's name, username, signature, text, words,
설정
샘플러
DPM++ 2M
스텝
40
가이던스
7
시드
195493639
크기
832x1216
Clip skip
2
프롬프트
detailed background,( Calm spring night landscape), amongst lush greenery, beautiful view, creeping phlox in full bloom, creeping phlox, early morning, sunrise sky, beautiful clouds, dappled sunlight, outdoor seating, one lamp, Tranquil Lake, Boat on a Lake, depth of field, masterpiece, best quality, ultra-detailed, very aesthetic, illustration, perfect composition, intricate details, absurdres, moody lighting, wisps of light, no humans,
네거티브 프롬프트
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
설정
샘플러
Restart
스텝
25
가이던스
7
시드
2651151167
크기
1024x1440
프롬프트
masterpiece, best quality, very aesthetic, absurdres
by sadamoto yoshiyuki, 1girl, aged up walking in the alley
short hair
black suit white collar shirt
wind
perspective from below
cyberpunk, neon
네거티브 프롬프트
lowres, worst quality, blurry, grayscale, low contrast
low quality, worst quality, normal quality
설정
샘플러
Euler a
스텝
36
가이던스
10
시드
2073484151
크기
832x1216
Clip skip
2
프롬프트
(masterpiece), best quality, (4K), (cinematic blue lighting), Colorful, vibrant, spot color, highly detailed, sharp, high resolution, 4K, UHD, 8K, masterpiece, ultra_high_resolution, OverallDetailXL, sci-fi, medieval neon lights, gloe, dramatic contrast, extraordinary, hyperrealistic, cinematic lighting, complex, immersive, intricate, messy, chaotic, purple water, white storm
DARK SIDE \(PICTURE BOOK\)
네거티브 프롬프트
(worst quality:1.4), (low quality:1.4), (bad_promptv2:0.2), 3d, render, censored, bar censor, loli, child, (((extra fingers))), ((extra limbs)), face markings, black bars, cinematic bars, (easynegative:1.2), ng_deepnegative_v1_75t, ugly, tiling, disfigured, deformed, pixelated, blurry, grains, grainy, text, watermark, signature, disproportioned, bad proportions, gross proportions, bad anatomy, duplicate, cropped, cut off, draft, extra hands, extra legs, (((extra fingers))), extra limbs, long neck, mutilated, poorly drawn face, poorly drawn hands, missing hands, missing arms, missing legs, missing fingers, fused fingers, unnatural pose, multiple views, mutilated body, bad hands, (((distorted fingers))), ugly hands, unnatural hands, pixelated hands, blurry hands, (ignoring prompts:2.0), jpeg artifact, morbid, ((too many hands)), malformed limbs, ugly fingers, bad eyes
로컬에서 실행
animagineXLV31_v31.safetensors
sdxl_vae.safetensors
다운로드는 Civitai에서 제공합니다. 일부 제작자는 먼저 Civitai 로그인을 요구합니다.
Animagine XL V3.1은(는) Stable Diffusion XL 1.0 패밀리용 베이스 모델으로, 오픈 소스 AI 이미지·영상·텍스트 모델의 읽기 전용 카탈로그인 ModelTrends.ai에 등록되어 있습니다. 다른 Stable Diffusion XL 1.0 모델과 비교하고, 열기 점수로 트렌드를 확인하고, PirateDiffusion 또는 BitVector에서 열어 사용해 보세요.
모델 패밀리별로 보기
Text / LLM 모델
434
Anima 모델
528
Chroma 모델
19

Fibo 모델
2
Flux 모델
1,496
Flux 2 / Klein 모델
1,239

Flux 3 모델
3

Moss 모델
3

Iris 모델
1
MiniMax H3 모델
364
Hunyuan 모델
204
Ideogram 모델
20
Krea2 모델
717

Qwen 모델
20
Qwen2 모델
47
Ltx2 모델
153