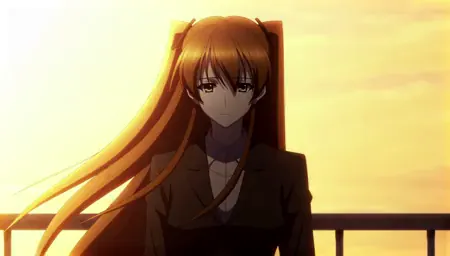
Autoplay
Patakbuhin nang lokal
SetsunaLtx2.safetensors
816 MB · SafeTensor
Ang mga download ay mula sa Civitai. May mga gumawa na humihingi muna ng Civitai login.
AD


I-install / Patakbuhin sa Graydient
Nangangailangan ng membership
<setsuna-ltx2>
Tungkol sa model na ito
LTX2 · Mga LoRA
by MengY_Madrigal - Setsuna_LTX2-Beta1
Mga tala ng gumawa
This is a test LoRA model based on LTX-2, trained on 44 videos (most with audio) using LTX Trainer. The Lora still has some problems, but here I'd like to share some experiences from the training process.
LTX-2 has significant limitations with Japanese language support, which appears to be a base model capability issue—most Japanese kanji characters cannot be pronounced correctly. However, there are some impressive aspects: lip-sync and audio cloning show great promise. The model fits quickly and shows results rapidly, but I believe more diverse training data (video dynamics, audio variations, etc.) is needed for better outcomes.
Dataset Caption
I highly recommend using Gemini for dataset captioning. Gemini can directly process both video and audio, delivering excellent results. While ComfyUI workflows with other caption nodes + Whisper audio recognition + refine are possible, they're not particularly recommended.
Agent Prompt
I used the following prompt for video analysis:
You are a professional video analysis assistant responsible for generating descriptive text for video training datasets. Please analyze this video and output the description in the following format:
【Output Format】
Visual content: [Detailed description of visual content]
Speech transcription: [Transcribe dialogue content, omit this line if none]
Sounds: [Describe sounds and music, omit this line if none]
On-screen text: [List on-screen text, omit this line if none]
【Rules】
1. Use plain text format, no Markdown bold or other formatting
2. "Visual content:" is required; omit entire lines (not "None") if other sections are empty
3. Descriptions should be natural and fluid, suitable for video generation model training
4. Focus on: actions, scenes, camera movement, lighting, atmosphere, emotions
5. Use present continuous tense for actions (e.g., is walking, is standing)
【Visual Content Description Points】
- Subject's actions and behaviors
- Scene environment and background details
- Camera movements (push, pull, pan, tilt, close-up, wide-angle, etc.)
- Lighting and color tone (warm light, cool light, backlight, soft light, etc.)
- Overall atmosphere and mood (serene, tense, warm, etc.)
- Composition and visual elements
Refine Prompt
After generation, use this prompt to convert structured descriptions into natural paragraphs:
You are a video description expert. Now you need to rewrite structured video descriptions into completely natural paragraph form.
【Task】
Rewrite the segmented video description into a smooth, natural paragraph, as if someone is describing what they see in the video.
【Rewriting Requirements】
1. Completely remove all labels (don't write "Visual content:", "Speech:", "Sounds:", etc.)
2. Naturally merge all information (visuals + dialogue + sounds into one fluid paragraph)
3. Like storytelling (use third-person perspective, present tense, vivid and specific with visual appeal)
4. Maintain technical details (camera movement, lighting, atmosphere descriptions should be preserved but naturally integrated)
Preprocessing Configuration
To prevent VRAM overflow, I used multiple bucket settings:
-
Maximum resolution: 768×?, 25 frames
-
Minimum resolution: 256×?, 121 frames
-
Unified frame rate: 24fps
-
Frame count requirement: Must satisfy frame_count % 8 == 1 (e.g., 1, 9, 17, 25...)
Training Configuration
Using RTX 4090 (48GB VRAM), no fp8/quanto quantization needed, training config was barely modified.
Training Progress:
-
Sampling every 400 steps
-
First sample (400 steps) already captured basic character features
-
At 800 steps, ComfyUI testing showed incomplete character feature retention
-
Total training: 3400 steps (approximately 8 hours)
-
Final weight used: 2200 steps (1400 steps might also work well)
Testing Findings
Prompt Impact
Prompts significantly affect results:
-
Without background description, likely generates simple solid color backgrounds
-
Need detailed descriptions of character movements (hair flowing, etc.)
-
Overall motion tends to be minimal
Workflow Configuration
Using official T2V workflow, found second-pass sampling has significant impact:
-
First pass (720p): More aligned with LoRA characteristics but slightly blurry
-
Second pass (spatial upscale): Clearer, but audio quality slightly degraded
-
Without LoRA in second pass, noticeable differences appear—more 2.5D style, most obvious in lip-sync details (presence/absence of teeth)
Interesting Discovery
Using cinematic-style descriptions produces interesting effects.
Future Plans
Planning to test training with larger-scale datasets.
Reference Documentation:
Mga trigger word
Setsuna
SHA256
4810A51C5F1AFC0A5563FEF6FB49F97139080EF0A768D62A54B74A27EB27BF98
ModelTrends.ai Model ID
#21095
I-flag ang nilalaman
Mga katulad na model
Badges for creators
Made this model? Put its standing on your Civitai page, your Hugging Face card, your README or your site. Each badge is a small picture that shows the standing on the day you copy it and never changes afterwards, however the rankings move later. The date is part of the badge.


Mga AI model para sa paggawa ng larawan, video at teksto
Ang setsuna ltx2 ay isang LoRA para sa pamilyang Ltx2 na nakalista sa ModelTrends.ai, isang read-only na catalog ng mga open source AI model para sa larawan, video at teksto. Ikumpara ito sa ibang Ltx2 model, tingnan ang heat score nito para makita kung gaano ito kasikat, at buksan ito sa PirateDiffusion o BitVector para subukan.
Mag-browse ayon sa pamilya ng model
Mga Text / LLM model
411
Mga Anima model
509
Mga Chroma model
14
Mga Flux model
1,071
Mga Flux 2 / Klein model
1,237
Mga MiniMax H3 model
332
Mga Hunyuan model
198
Mga Ideogram model
20
Mga Krea2 model
675
Mga Qwen model
17
Mga Qwen2 model
37
Mga Ltx2 model
151
Mga Stable Diffusion 1.5 model
6,465
Mga Stable Diffusion XL 1.0 model
15,432
Mga Zimage model
804
Mga Wan model
920

Model
Trends
.ai
© ModelTrends.ai
|
© 2026
|
Nakalaan ang lahat ng karapatan