Better Human Motion for MiniMax H3: natural, consistent body movement
Topic: Models

By Captain
Published 2026-10-01
Example renders
Prompts and settings shared by the people who made these renders on Civitai. Pick a render to see how it was made.
Settings
Steps
12
Guidance
1
Size
1440x832
Prompt
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced.
integrated_multimodal_description: [Shot 1] The scene opens from <Picture 1>, preserving the three young women standing close together outdoors on a city street in winter, with European-style buildings and bare trees in the background under soft daylight. The camera has a natural handheld smartphone selfie shakiness, as if held by one of the girls at arm's length. The girl on the left with long straight black hair, a thick gray scarf, and a dark coat (S1) shivers slightly, pulling her scarf tighter around her neck with one hand. She looks directly into the camera lens with a bright, slightly complaining expression and says: <d>[Chinese] 今天有点冷啊,快看镜头啊!我们三个谁最好看啊?</d> The girl in the middle with chestnut-brown hair, a gray coat with bow buttons, and a white phone with a bear charm (S2) turns her gaze toward the camera, a playful smile forming on her lips. The girl on the right with a single braid, a gray sweater, and a gold necklace (S3) continues looking down at her dark phone, smiling faintly.
[Shot 2] At 00:05.000, the handheld camera wobbles slightly as the girls adjust their positions. The middle girl (S2) raises her hand in a cute peace-sign gesture beside her face, tilts her head playfully, and laughs with a cheeky, confident expression, saying: <d>[Chinese] 当然是我啦!</d> She winks one eye playfully after the line. The left girl (S1) reacts with a mock-offended expression, opening her mouth in playful protest and lightly nudging the middle girl's shoulder with her elbow. The right girl (S3) finally looks up from her phone toward the camera, an amused smile spreading across her face as she shakes her head at the other two.
[Shot 3] At 00:10.000, the right girl (S3) laughs warmly, her eyes crinkling with genuine amusement, and says in a light, scolding-but-affectionate tone: <d>[Chinese] 两个臭屁精!别拍了,赶快吃火锅去啦!</d> She puts her dark phone away into her coat pocket and starts to turn her body toward the street, gesturing with her hand for the others to follow. The middle girl (S2) giggles and lowers her peace-sign hand, while the left girl (S1) laughs and nods in agreement. The handheld camera begins to lower and tilt as if the person filming is putting the phone down, the three girls starting to move together toward the street, their shoulders brushing as they walk off, still laughing. The frame ends with a slight downward tilt as the selfie video concludes.
overall_soundscape:
Soft outdoor city street ambience continues throughout — distant traffic hum, occasional car passing, faint wind rustling through the bare tree branches, and the low murmur of pedestrians in the background. The girls' voices are clear and close, captured by the phone's microphone with a slight natural reverb from the open street. Subtle fabric rustling is audible as they adjust their coats and scarves, and the soft click of a phone lock button is heard near the end as the right girl puts her phone away. Light, cheerful laughter from all three girls overlaps naturally throughout the conversation.
non_diegetic_music:
N/A
Settings
Size
416x736
Prompt
the girl from example.png finally meets ryu from streetfighter in a dark ally. the girl proves far more superior in hand to hand combat since she is fighting in her own comfyui environment using a modified workflow.
Settings
Sampler
Euler
Steps
8
Seed
1765670026011586
Size
512x800
Prompt
[source image: https://civitai.red/images/141930523]
How the reference pictures align with the target video — <Picture 1> (from [Shot 1]) aligns with the end mark of the target video.
integrated_multimodal_description: [Shot 1] mvmt. Live-action, cinematic, a wide shot captures a bustling European city square under bright daylight, featuring richly textured historic buildings surrounding the open plaza, with the camera remaining static, perfectly framing the architectural grandeur. Overall, the scene maintains a pleasant, cheerful atmosphere underscored by upbeat, lively instrumental music. After a period of stillness, at 00:05.000, a distant, drawn-out female shriek of fright drifts faintly through the music. As the sound of the scream grows noticeably louder, overpowering the music's volume, the broom with a woman flying headfirst downwards streaks at high speed across the frame in half of a second from left to right straightly. As the broom carries her out of the frame to the right, her shriek diminishes in volume, gradually being swallowed again by the music. For several seconds, the frame returns to a static depiction of the city square with no significant action.
[Shot 2] At 00:07.500, Medium low-angle shot of the same woman who is now seated upright the broom, seemingly having regained control, the camera placed just in front of her broom handle. With a happy expression on her face, with her hair and scarf blowing in the air and her eyes and mouth widely opened in cry of mixed joy and fear, mingled with laughter, she rapidly flies over the city plaza while the camera tracking her non-stop flight.
overall_soundscape: The primary ambient sound is the distant murmur of the city crowd. The distinct, loud, and then fading shrieks punctuate the general urban noise. The laugh and cries of joy of the woman when she filmed in [Shot 2].
non_diegetic_music: Upbeat, lively instrumental music plays throughout, maintaining a consistent, cheerful tempo, though it is periodically overwhelmed by the screams.
Settings
Steps
10
Size
768x1216
Prompt
subject_definitions:
<Subject 1> is the veteran archmage, with his facial identity and clothing perfectly matching <Picture 1>, his voice weathered, gravelly, low, ancient and commanding.
<Picture 1> is the opening-frame anchor for [Shot 1], the archmage atop the cliff's edge analyzing the battlefield below.
<Audio 1> is the original background music track for this video, gradually building in intensity over its full duration.
summary:
[keyframe completion + audio reuse] The target video opens from <Picture 1>, the archmage atop the cliff. Over the full 15 seconds, he delivers a lengthy incantation while a storm gathers behind him and the camera arcs from his front to his back, all set to <Audio 1>, which builds gradually in intensity throughout without needing to align to any specific action.
retention_analysis:
<Picture 1> ([Shot 1] first frame): fully_preserved - the archmage, his staff, his aura, and the cliffside setting anchor the opening composition.
<Subject 1> (appears throughout [Shot 1]): fully_preserved - the archmage's identity, staff, and aura from <Picture 1> are retained throughout.
<Audio 1>: fully_copy - the track is reused in full, unmodified, as the complete non-diegetic score for the entire video, its gradual build not tied to any single visual cue.
detailed_description: Live-action, cinematic. [Shot 1] <Subject 1>, the veteran archmage matching <Picture 1>, remains atop the cliff's edge exactly as established, analyzing the battlefield below, his staff still crackling with stored power visualized as a swirling aura of light, the sky overcast but bright behind him. The camera begins directly in front of the mage, matching the vantage of <Picture 1>, and over the full 15 seconds of this shot, arcs slowly and continuously around him with small amplitude at slow speed, tracing a wide arc until it arrives directly behind him by the shot's end, the mage's position remaining fixed in place throughout while the camera alone circles around him. Below on the battlefield, distant armies clash in a chaotic, evenly matched struggle, neither side gaining ground, soldiers and war machines colliding in a constant, disorganized churn visible far below the cliff. From 00:00.000 to 00:05.000, a strong wind begins gusting from behind the mage, his robes snapping and billowing loudly with each fresh surge, the aura around his staff pulsing brighter in time with the wind's intensity. He (S1) begins his incantation, <d>[Japanese] 天をつらぬく黄金のことわり、我が身に降りよ。</d> A white subtitle reading "Golden law that pierces the heavens, descend upon me." appears at the bottom of the frame, slowly raising his staff overhead with both hands as he speaks, lifting it toward the sky in a deliberate, unhurried motion. From 00:05.000 to 00:09.000, the camera continues its slow arc as the overcast sky behind him churns and thickens, towering cumulonimbus clouds building rapidly upward from the wind's disturbance, darkening progressively as they grow, casting a spreading shadow across the chaotic, struggling battlefield below. He continues, his tone sharpening with authority, <d>[Japanese] 閃光のさばき、時よ止まれ。</d> A white subtitle reading "Judgment of the flash, let time stand still." appears at the bottom of the frame, his staff now held fully raised above his head, steady and unmoving. From 00:09.000 to 00:12.500, still arcing steadily around him, the towering clouds above have grown massive enough to plunge the battlefield into a deep, shifting shadow, static electricity visibly building within the cloud mass, faint flickers of inner light sparking intermittently through the dark clouds. He presses on, his voice rising with intensity, <d>[Japanese] いにしえの盟約、今ここに解き放たん。</d> A white subtitle reading "Ancient covenant, I release you here and now." appears at the bottom of the frame, the staff remaining held high overhead, unmoving, in anticipation of the final strike. From 00:12.500 to 00:15.000, the camera completes its arc, arriving directly behind the mage by the shot's end. As he reaches the incantation's final line, his staff's aura flares to its brightest yet, his robes whipping violently in the now-fierce wind, his expression fierce with concentration as he suddenly swings the staff downward in one sharp, decisive motion, bringing it down in front of himself as he delivers the final words, <d>[Japanese] ——きたれ、らいていの顕現!</d> A white subtitle reading "—Come forth, manifestation of thunder!" appears at the bottom of the frame, the shot ending the instant the incantation concludes and the staff completes its downward swing.
overall_soundscape: A low wind begins as a faint murmur and builds steadily into a powerful, sustained gust, the mage's heavy robes snapping and flapping loudly throughout. The distant, chaotic clatter of clashing armies and war machines rumbles faintly from the battlefield far below throughout the entire shot. Beginning around the midpoint, a deep, rolling rumble of distant thunder builds within the gathering clouds, growing steadily louder and closer, punctuated by faint crackling pops of static discharge as the storm intensifies toward the final line, culminating in a sharp whoosh as the staff swings down.
non_diegetic_music: <Audio 1> plays in full for the entire 15-second duration of the video, exactly as the source file, unmodified, its gradual build in intensity underscoring the mage's incantation and the gathering storm without being tied to any specific moment or action.
Settings
Steps
30
Size
640x1152
Prompt
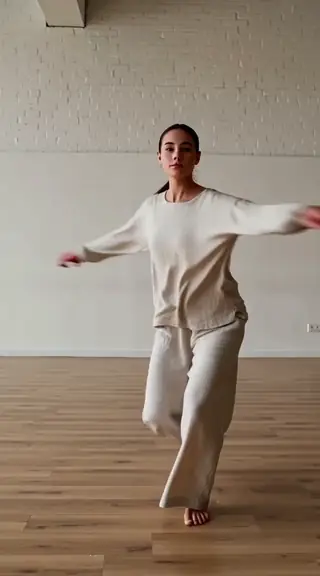
Eye-level continuous shot of a contemporary dancer in loose linen clothing executing a fluid, spinning turn on one foot, transitioning smoothly into a low spiral crouch onto the wooden floor, and rising back up into an extended reach. 360-degree torso rotation, continuous arm trailing, clean limb tracking, no morphing or phantom limbs.
Settings
Steps
8
Size
768x1216
Prompt
subject_definitions:
<Subject 2> is the spiker, the woman in <Picture 1>, with her facial features, clothing, and back number 3 perfectly referenced. She has a quiet, reserved voice.
<Subject 7> is the male coach in <Picture 2>, with his facial features, clothing, and penis proportions perfectly. He has the voice of an overweight man.
<Subject 8> is the Japanese gymnasium <Picture 3>, with its space, equipment, and lighting perfectly referenced.
Summary:
[Reference generation] This scene shows <Subject 2> entering the room where <Subject 8> is located and conversing with <Subject 7>, who is off-screen.
retention_analysis:
<Subject 2> (appears in [Shot 1]): fully_preserved - the woman's facial features, clothing, and back number 3 are retained.
<Subject 7> (appears in [Shot 1]): fully_preserved - the male coach's facial features and clothing and penis size are retained.
<Subject 8> (appears in [Shot 1]): fully_preserved - the gymnasium's space, equipment, and lighting are retained.
detailed_description:
The target video is set in a dimly lit, dusty Japanese gymnasium storage room from <Subject 8>, evoking a sense of unease and isolation.
[Shot 1] a medium wide shot establishes <Subject 8>, the gymnasium storage room, with a dimly lit interior and a dusty atmosphere. Accompanied by a sound like that of a heavy cart being moved, the metal sliding door slowly side opens. The camera begins a slow, ascending low-angle shot of <Subject 2>, the female volleyball team member, in her volleyball uniform. She appears tense and apprehensive. A quiet, unsettling piano melody begins to play softly in the background. Upon entering the room, she closes the sliding door behind her without turning around; the sound produced is like that of moving a heavy cart. <Subject 2> turns toward the camera and <Subject 2> (S1) says in a quiet, reserved voice, <d>[Japanese] コーチ、何かありましたか?</d> A white subtitle reading "Coach, is there something?" appears at the bottom of the frame. <Subject 7> (S2) voice (off-screen, low and calm) says: <d>[Japanese] 3番ちゃん、頑張ってるし、少し体をほぐしてあげようと思ってね</d> A white subtitle reading "3-chan, you’ve been working hard, so I thought I’d loosen up your body a little." appears at the bottom of the frame. <Subject 2> stands frozen, her back rounded with anxiety. Ventilation fan steady, rhythmic hum fills the silence.
overall_soundscape:
Soft indoor gymnasium room tone and a low ventilation hum.
non_diegetic_music:
Ambient noise and low-pitched drone sounds play faintly, accentuating a claustrophobic and oppressive atmosphere. Low-frequency vibrations create an unpleasant auditory sensation.
AdaptiveVision's Better Motion LoRA makes MiniMax H3 (and LTX) characters move naturally and consistently. Learn weight, resolution, step count and how to write short motion prompts.
Overview
Better Human Motion (v1.0-MH3) is a
LoRA
for
MiniMax H3
and
LTX
video models that improves body movement: smoother walking, gesturing and turning, with fewer limb glitches and more consistent anatomy across frames. It was trained on text-to-video but works for image-to-video too.
Author recommendations: 720x1280, 15-30 steps, weight 0.4-0.8, and short sentences to avoid prompt bleeding.
Reference
Name | Type | What it is |
|---|---|---|
LoRA weight | 0.4-0.8 | 0.6 default. |
Resolution | 720x1280 | Portrait video; landscape works at the same pixel count. |
Steps | 15-30 | |
Prompt style | short sentences | One action per sentence. |
Mode | T2V / I2V | Both. |
AD

No install required - run AI models on the cloud
BitVector Prism is the easiest way to start: pick a model, type a prompt and generate in a clean web app, with nothing to configure. BitVector is also available on Discord and on the web (SpyGlass).
Step by step
- Write the H3 prompt with one or two clear actions in short sentences.
- 720x1280, 20 steps.
- Keep the soundscape simple so motion gets the attention.
- Raise to 0.8 for dance or sports; lower to 0.4 for subtle gestures.
Examples
Walk
integrated_multimodal_description: [Shot 1] A woman in a trench coat walks along a rainy pier toward the camera. She adjusts her collar. She stops and looks at the sea.
overall_soundscape: Rain, waves, footsteps on wood.
non_diegetic_music: N/A
Better Motion 0.6
Dance
integrated_multimodal_description: [Shot 1] A dancer in a studio spins once and lands in a low pose. Mirrors behind. Camera static.
overall_soundscape: Soft shoes on wood floor.
Better Motion 0.8
Creative idea: anime meets live action
integrated_multimodal_description: [Shot 1] A young woman in a hoodie faces a martial artist in a dark alley. She steps forward and blocks a slow punch. Camera handheld.
Better Motion 0.7
Tips
- Describe the motion path (walks from left to right) rather than adjectives.
- Pairs with the Combat LoRA at reduced weights for action scenes.
- For I2V, make sure the start frame already shows the pose that begins the motion.
- Shorter clips (5 s) stay more consistent.
Troubleshooting
Prompt bleeding (actions merge)
Why it happens
Long compound sentences.
How to fix it
Split into short sentences, one action each.
Stiff motion
Why it happens
Weight too low.
How to fix it
0.7-0.8.
AD

No install required - run AI models on the cloud
PirateDiffusion is Telegram only and built for pros: thousands of models, LoRAs and workflows driven by chat commands, with unlimited generation on a fixed price plan.

Questions
LTX too?
Yes, there is an LTX variant.
Trigger?
None.
Links and sources
Models in this guide
Written by
Captain
Related guides
Models
MiniMax H3 Combat BASE V2: fight motion, impact and drama
FourBunny's Combat BASE LoRA for MiniMax H3 improves fight choreography, hit reactions, continuity and physical cause and effect, and it helps dialogue scenes too. Learn the prfight1, prfin1 and prslow1 triggers and how to stage a scene.
By Captain
2026-10-01
Models
GalaxyAce LoRA for MiniMax H3: early-2010s low-end phone footage
aiguild's GalaxyAce LoRA recreates the look of a Samsung Galaxy Ace phone camera: muted colors, sensor noise, rolling shutter and everyday framing. Learn strengths per model, prompts and found-footage ideas.
By Captain
2026-10-02
Models
MiniMax H3 Turbo LoRAs: 4-8 step video with the larryvrh pack
The MiniMax H3 Turbo LoRA pack (larryvrh 4-step and friends) cuts video generation steps from dozens to a handful. Learn the per-variant step counts, samplers and strengths, plus how to prompt H3 for fast, clean clips.
By Captain
2026-10-01
Models
Passionate Kissing LoRA for MiniMax H3: convincing romantic scenes between adults
kermitfrog1202's LoRA improves kissing scenes in MiniMax H3 video. Learn the trigger sentence, the strength values the author found for different couples and how to stage a tasteful romantic shot.
By Captain
2026-10-01
Prompting
Prompting MiniMax H3: text to video, image to video, reference video and audio
How to direct MiniMax H3 from a chat command: the WHO + WHERE + ACTION + CAMERA + SOUND recipe for text to video, animating a still with image to video, giving every reference picture a job in reference mode, and getting clean dialogue instead of mumbling. With copy-and-try prompts and the author's PDF.
By Mark White
2026-09-20
More guides

Models
FLUX.1 Dev: how to prompt it, best settings and creative ideas
A practical guide to FLUX.1 Dev by Black Forest Labs: natural-language prompting, guidance and step settings, LoRA stacking, text rendering and prompt ideas that play to its strengths.
By Captain
2026-09-30

Models
Stable Diffusion XL 1.0: prompts, settings and what it still does best
How to get the most out of the official SDXL 1.0 base model: native resolutions, CFG and sampler settings, the refiner, negative prompts and ideas for styles where SDXL still shines.
By Captain
2026-10-01

Models
Stable Diffusion 1.5: the classic model, prompted properly
Stable Diffusion 1.5 is still worth knowing: the right resolution, CFG and sampler, how to use its huge library of LoRAs and embeddings, and creative prompt ideas suited to a 512-pixel model.
By Captain
2026-10-02

Models
FLUX.2 Dev: prompting the newest Black Forest Labs model
FLUX.2 Dev brings larger prompts, better text, stronger realism and multi-reference editing. This guide covers the turbo workflow, guidance and resolution settings, prompt structure and ideas that use its new strengths.
By Captain
2026-10-03

Models
Qwen-Image: long prompts, perfect text and bilingual posters
Qwen-Image is the model to reach for when the words in the picture matter. Learn how to write its long descriptive prompts, render English and Chinese text accurately, set CFG and steps, and explore layout-heavy creative ideas.
By Captain
2026-09-29

Models
SDXL-Lightning: four-step generation on any SDXL checkpoint
ByteDance's SDXL-Lightning LoRA turns a 30-step SDXL render into a 4-step one. Learn the step counts, the CFG you must use, the sampler, and how to combine it with your favorite checkpoints and style LoRAs.
By Captain
2026-09-30

Model
Trends
.ai
© ModelTrends.ai
|
Made in Japan
|
© 2026