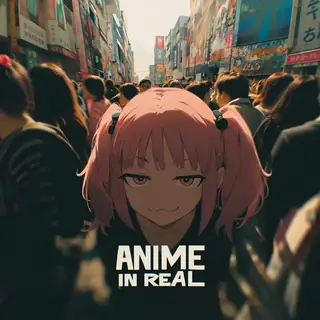
Anime in Real for Anima: anime characters in realistic backgrounds
Topic: Models

By Captain
Published 2026-09-30
Zoropaton's Anime in Real LoRA places Anima's anime characters in photorealistic environments. Learn the @Ani3rel trigger, the solo, depth-of-field and blurry-background tags it loves, and creative ideas.
Overview
Anime in Real
(v1.5 for
Anima
) by Zoropaton focuses on anime characters standing in realistic backgrounds. It works best with solo subjects, depth of field and blurry background tags. The trigger is essential: @Ani3rel (the author's text also writes it Ani2rel).
Anima is a Danbooru-tag anime model with natural-language support, so you can mix tags with a sentence about the real-world setting.
Reference
Name | Type | What it is |
|---|---|---|
Trigger | @Ani3rel | Required. |
Helper tags | solo, depth of field, blurry background | |
LoRA weight | 0.7-1.0 | |
Base | Anima | |
Negative | optional | no lineart for a painterly blend. |
AD

No install required - run AI models on the cloud
BitVector Prism is the easiest way to start: pick a model, type a prompt and generate in a clean web app, with nothing to configure. BitVector is also available on Discord and on the web (SpyGlass).
Step by step
- Quality tags, @Ani3rel, solo, depth of field, blurry background.
- Character tags.
- A sentence describing a real place (a Tokyo crosswalk at dusk).
- Weight 0.9.
- Hires fix for the background.
Examples
Street
score_7, score_8, score_9, masterpiece, very aesthetic, @Ani3rel, 1girl, adult, solo, depth of field, blurry background, hoodie, headphones. She stands at a rainy Tokyo crosswalk at dusk, real photo background.
Painterly
masterpiece, very aesthetic, dynamic angle, (mixed media:1.5), sensitive, @Ani3rel, 1girl, adult, solo, foreshortening, limited palette, no lineart. Highly textured brush-like strokes blend her into a real forest path.
Creative idea: travel series
@Ani3rel character in six real cities: Lisbon tram, Venice bridge, Reykjavik harbor..., same tags and seed.
Tips
- Mixed media and limited palette tags give a collage feel.
- Textured painting style prompts blend character and background.
- Keep to one character.
- Foreshortening and dynamic angle add energy.
Troubleshooting
Background turns anime
Why it happens
Trigger missing.
How to fix it
@Ani3rel first.
Two characters merge
Why it happens
Not solo.
How to fix it
solo.
AD

No install required - run AI models on the cloud
PirateDiffusion is Telegram only and built for pros: thousands of models, LoRAs and workflows driven by chat commands, with unlimited generation on a fixed price plan.

Questions
Trigger?
@Ani3rel.
Other bases?
Earlier versions exist for other models; this is the Anima build.
Links and sources
Models in this guide
Written by
Captain
Related guides
Models
Style > gpt-image-2 for Anima: detail, lighting and texture enhancer
AgileNumbers' LoRA steers Anima toward the gpt-image-2 look: more detail, lighting and texture. Learn the @gpt-image-2 trigger, v1 versus v1.1, strength advice and ideas.
By Captain
2026-10-01
Models
Aesthetic Quality Modifiers - Masterpiece for Anima: making quality tags mean something
motimalu's Masterpiece LoRA for Anima was trained only on hand-rated masterpiece images, so the quality tags at the start of your prompt actually bite. Learn the prompt structure, weight and how to combine it with artist tags.
By Captain
2026-10-01
More guides

Models
FLUX.1 Dev: how to prompt it, best settings and creative ideas
A practical guide to FLUX.1 Dev by Black Forest Labs: natural-language prompting, guidance and step settings, LoRA stacking, text rendering and prompt ideas that play to its strengths.
By Captain
2026-09-30

Models
Stable Diffusion XL 1.0: prompts, settings and what it still does best
How to get the most out of the official SDXL 1.0 base model: native resolutions, CFG and sampler settings, the refiner, negative prompts and ideas for styles where SDXL still shines.
By Captain
2026-10-01

Models
Stable Diffusion 1.5: the classic model, prompted properly
Stable Diffusion 1.5 is still worth knowing: the right resolution, CFG and sampler, how to use its huge library of LoRAs and embeddings, and creative prompt ideas suited to a 512-pixel model.
By Captain
2026-10-02

Models
FLUX.2 Dev: prompting the newest Black Forest Labs model
FLUX.2 Dev brings larger prompts, better text, stronger realism and multi-reference editing. This guide covers the turbo workflow, guidance and resolution settings, prompt structure and ideas that use its new strengths.
By Captain
2026-10-03

Models
Qwen-Image: long prompts, perfect text and bilingual posters
Qwen-Image is the model to reach for when the words in the picture matter. Learn how to write its long descriptive prompts, render English and Chinese text accurately, set CFG and steps, and explore layout-heavy creative ideas.
By Captain
2026-09-29

Models
SDXL-Lightning: four-step generation on any SDXL checkpoint
ByteDance's SDXL-Lightning LoRA turns a 30-step SDXL render into a 4-step one. Learn the step counts, the CFG you must use, the sampler, and how to combine it with your favorite checkpoints and style LoRAs.
By Captain
2026-09-30

Model
Trends
.ai
© ModelTrends.ai
|
Made in Japan
|
© 2026