
Furry Enhancer Video
8516°
<furry-enhancer-h3>
支持 ModelTrends 标签的应用允许你通过在提示中复制这段代码来运行/安装模型,无需任何设置。请在支持该功能的应用中寻找我们的图标,比如下面的 Prism。
运行此模型
优惠 / 广告

Easy Creator (Prism) 网页
不限量 · 固定费用
最适合初学者。强大的工作流程,学习曲线低。

PirateDiffusion Telegram
不限量 · 固定费用
创建视频、图像、自定义聊天角色等。

Pro studio (SpyGlass) 网页
不限量 · 固定费用
从任何浏览器或手机浏览模型、渲染和优化。

Discord bot (Vector)
不限量 · 固定费用
将 Vector 添加到你的服务器或加入 Vector Discord。创造任何东西!

Unified Editor 网页
不限量 · 固定费用
图像和视频编辑器:在同一页面渲染、编辑、放大等。

Civitai 网页
按次付费
在Civitai官网生成;每张图片用Buzz积分支付。

本地应用
需设置
如果你的电脑硬件够好,可以安装本地程序。

ModelDuel 网页
按次付费
一次在多达50个检查点/基础模型上生成相同的提示。

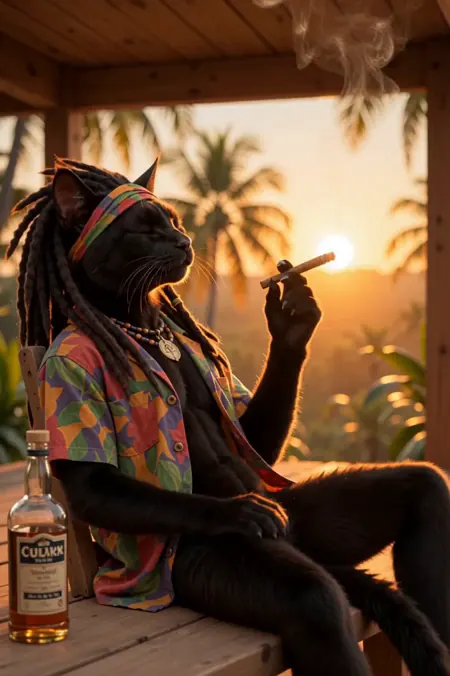
by freek22 - Furry Enhancer Video
创作者说明
This Lora is made to enhance the ability / quality to create anthro and furry
but it works also for all kind of other fantasy creatures and animals too
the range that it can handle for example the Wan 2.2 V2 Lora is from comic and drawing towards real photos .
i made the lora for Hunyuan Video , WAN 2.1 and 2.2 (SFW and NSFW)
Furry Enhancer Hunyuan V1
The Hunyuan Video version is trained for Text to Video (T2V) but i also tested it on Image to Video its also working with it very good but not made for that.
All example images for the Hunyuan Video are made T2V
Its also compatible with
Wan 2.1 I2v and T2V V1
The Wan 2.1 has 2 different models
I2V and T2V
the image to video is in most cases the model of choice for Wan
for the Text to Video Variant please read the description.
Its also compatible and will for sure increase the quality especially in the NSFW Area.
I also tested the I2V Lora with Wan 2.2 it seems to enhance the result too but very experimental
Wan 2.2 I2V and T2V V1
This enhancer version is for its splitted in basically 2 Loras: low and high noise
both loras for I2V are trained on the same dataset. I its my own dataset before i trained with the wan 2.1 Lora but add more pictures and videos
it's completely synthetic so no real persons or art is used for the dataset.
whats the pros of this lora compared to the wan 2.1?
-
more consistent
-
more specimen
better in sfw and nsfw
i recommend using both loras and use the workflow in the training folder Note: your resolution needed to set between 0.4 (480P) and 0.92 (720p) overwise the lora generate backscreens or other failures.
for strength i prefer the full 1.0 strength its tested
its tested with the original wan 2.2 model
also in a short test with my model (use only the high noise version with that model)
for technical data about Wan 2.2 visit there official site
V2 Furry Enhancer High Noise
Changes compared to V1
-
more consistent
-
more specimen
-
better overall movements
-
more stable overall
-
way better with comic and anime than V1
better in sfw and nsfw
i recommend using the V1 Version of the
Note: I used for example the old workflow for this model to compare V1 with V1 if you like the newest workflow download the training folder.
Important for this workflow is to keep the resolution between 0.4 and 0.92 (480p - 720p)
V3 High Noise and Low Noise
This enhancer version is for Wan 2.2
its trained my own dataset
it's completely synthetic so no real persons or art is used for the dataset.
the biggest change in this dataset is its now completely trained on videos
Changes compared to V2
-
trained now on over 650 Videos
-
better overall movements
-
more emotions
-
way better with comic and anime than V1 and V2
better in sfw and nsfw
for this Version there is also an newtrained Low Noise Model
LTX2.3 Version (WIP Preview V0.1)
this is an preview version of the first attempt to train the ltx 2.3 model with a very limited dataset
so it's more like an technical demonstration / trial than a fully trained lora.
So don't expect best results yet it's highly experimental.
for workflow i have also added an experimental workflow.
LTX2.3 Version V1 Lora Pack
This is the First full Release Version of the LTX Version of Furry Enhancer Video.
Better to say it's an model pack because
V1.1 is made based on ltx 2.0 training setup so best for the LTX 2.0 model
V1.215 its the main model trained specifically for the ltx 2.3 Version so start usually with that lora
V1.22 More advanced in training but has sound issues.
V1.3 experimental (wip) model trained in different training modes (heavy sound issues)
you find the used workflows and the different model versions in the "training folder"
the loras are tested on the dev version and the distilled variant.
what has changed to preview?
-
Trained on the full video database (V1.2 and up) at around 700 videos instead of only 40 videos
-
Also trained on my photo database of ratatoskr overall over 10k pictures
-
Trained for i2v and t2v
-
better overall knowledge and movement .
Note: this is still in development because most of the trained videos are based on my wan2.2 database so its planned to train an v2 this year with video output of that model.
also i don't have my own workflow done yet so it depends on other workflow don by afroman4peace and
LTX2.3 Version V2.4
I have decided to retrain the dataset on a far advanced system now its trained on a server with an rtx6000 pro blackwell for more than a week 24/7 (and yes this was expensive)
so what has changed from V1 to V2.4?
-
the trained video resolution is now at 720P constant
-
image training did improved from 1024p to 1536p
-
added 120 new sound videos for training especially for speech and jaw movements.
-
seperated videos with sound and not sound and trained in different databases
-
trained for T2V and I2V in stages so its nearly equally trained for both now
-
added new pictures to database too but more important overworked the captions fitting better for video training
For settings and workflow i have added my example videos in the training folder the images and some videos has the metadata just put them into comfy
on my workflows was the loral at best between 0.8 and 1.0
the lora is trained on the dev model but also tested for the distilled version
for now still don't have my own workflow done yet so it depends on other workflow don by afroman4peace and
please support my work with an like and look on my other loras and models too
the newest workflow download the training folder.
in all videos the metadata is also included just download the video and put it into Comfy
Important for this workflow is to keep the resolution between 0.4 and 0.92 (480p - 720p)
if you like to support me please give a like and Check out my other models.
Making such loras take a huge amount of cost and time please support my work with a like.
and please check out my other models and loras too
SHA256
FC1E06352B7CC8689DAA539CA3064AF57D3265A4ADA995C055F4FE66CDBA3AB0
Furry Enhancer Video 热度趋势
自16 Aug 2026以来的热度分数
热度评分
8,516°
本周
▲
2.7%
8,510° 当时,8,516° 现在
本月
▲
16.1%
8,483° 当时,8,516° 现在
过去一年
n/a
尚未发布/跟踪
7,000°
起点
评分范围是 0° 到 9,999°。低于 7,000° 的部分保留给还没有任何来源报告的模型,这些模型用替代数值填充,保证列表完整。7,000° 是有实际数据的起点:一个有真实数据但几乎没人下载的模型就在这里,后续的度数都是基于它的测量。起点本身不反映模型质量,只有起点以上的度数才区分不同模型。
+1,016°
Civitai 下载量
该版本在Civitai上有2,099次下载。下载是最重要的因素,按对数刻度计数:下载量增加十倍,热度增加300°,所以百万下载的模型不会比千次下载的热度高一千倍。六个下载来源共享该指标,按各自下载量比例分配。
+325°
点赞数
各来源累计点赞数为 145。点赞权重是下载量的一半,按同样的对数比例计算。
+75°
采用率
每天大约 9 次下载,基于两次来源读取间的测量,不是用历史平均估算。下载速度权重是下载项的四分之一,这样能反映新热度,但不会让一天的峰值超过多年累计。
+100°
家族加成
+100°,因为这是本站当前重点推广的家族 LoRA。这是评分内有限的加成,公开列出;不会掩盖模型,也不会超过下载量千倍差异。
显示详细分解
本站上的每个数字都可以查证。这个模型的热度评分是 8,516°,这里一步步展示了它是如何组成的,每一步都有累计总分:起点、每个来源增加的度数、模型类型的加成以及权重年龄的扣减。颜色对应上方图表的区间。最后的词汇表解释了所有术语。
- 1从起点开始。为什么是 7,000° 而不是零:评分范围是 0° 到 9,999°,低于 7,000° 的部分保留给还没有任何来源报告的模型,这些模型用替代数值填充,保证列表完整且不会超过有数据的模型。7,000° 是有实际数据的起点。一个有真实数据但几乎没人下载的模型就在这里;后续的度数都是测量值,起点以上有十个十倍下载阶梯,每阶梯增加 300°。起点对所有模型一样,不影响排名;区分模型的是起点以上的度数。7,000°累计总数
- 2加上下载量。总共2,099个下载等价量,来自Civitai 下载量。下载量增加十倍,热度增加相同的300°,所以大小很重要,但不会让分数失控。+1,016°8,016°累计总数
- 3加上点赞数。145个点赞和竖起大拇指,权重是下载量的一半。+325°8,341°累计总数
- 4增加采用率。现在大约每天9次下载,基于两次读数的差值,权重是四分之一。+75°8,416°累计总数
- 5家族加成。对本站当前重点推广的LoRA家族的开放且有限的推动。+100°8,516°累计总数
- =热度得分。这个模型在本站所有榜单上的排名。没有其他因素会调整它。8,516°
术语表:这里用到的术语
- 热度得分
- 一个数字,表示模型当前的使用和需求程度,范围从0°到9,999°。本站所有标注为最热门的榜单都按这个分数排序,别无他物。
- 基准线
- 所有有真实数据的模型起始于7,000°。分数范围是0°到9,999°;基准线以下的部分保留给无数据的替代模型,这样有数据的模型总是排在无数据模型之上。基准线对所有人相同,不影响排名;超过基准线的度数才是实际测量值。
- 下载等价量
- 得分中当作下载计算的所有项目总和:下载本身,每个种子上传者算1,000,每个AI Horde图片和每次生成网站的运行算一个。
- 对数刻度
- 以十为单位计数,而不是以一为单位:从1,000到10,000下载增加的热度和从10,000到100,000增加的热度相同。这样可以防止巨头压倒一切。
- 点赞
- 来自所有来源的点赞和竖起大拇指,每个点赞在对数刻度上价值半个下载。
- 采用率
- 模型当前每天的下载次数,基于两次读数的差值。权重是下载项的四分之一。
- 测量与估算
- 测量表示有两个来源的读数,且差异是真实的。估算表示只知道今天的总数,过去的数据是根据模型的生命周期分配的;网站会说明显示的是哪种。
- 做种者
- 指那些在线保存权重副本供他人通过种子下载的人,或者提供同样服务的托管镜像。每个做种者相当于1000次下载。
- AI Horde
- 一个志愿者网络,在捐赠的电脑上免费生成图片。它用某个模型生成的图片数量是公开的,每张图片算作一次下载。
- 生成网站
- 托管自己模型副本并允许用户生成的站点,比如PixAI、SeaArt和Yodayo。它们的下载计数和Civitai一样,每次生成算一次下载。
- OpenRouter 令牌
- 通过API提供的文本模型,如Claude或GPT,没有权重需要下载,因此其使用量以令牌计量:过去30天内通过OpenRouter(一种许多应用使用的网关)读取和生成的文本片段。每10,000,000个令牌计为一次下载。来源:OpenRouter (openrouter.ai/rankings),CC BY 4.0。
- 完整模型(检查点)
- 权重文件本身,是能独立生成的文件。它会获得额外加分,因为附加组件依赖它。
- LoRA和嵌入
- 小型附加文件,用来引导别人的权重朝向某种风格、角色或概念。它们不能单独运行。
- 家族与权重
- 模型构建所基于的基础,比如SD 1.5、SDXL、Flux或Wan。每个模型继承其家族权重的发布日期。
- 年龄
- 根据家族权重发布多久,扣除的度数:每年150°,最多750°。它保留了那些积累了多年下载量的老模型,防止它们被挤出榜单顶部。
- 家族加成
- 对当前网站重点推广的某个家族的LoRA给予的小幅度限制性加分,总是在分数细目中列出。
- 替代分数
- 给还没有任何来源报告的模型一个稳定的最低分数,这样榜单才完整。它永远不会高于有数据的模型。
- 新模型!(宽限期)
- 不到7天的新模型显示“新模型!”而非分数,且不参与排名。其分数从第一天开始计算,但一天大的模型增长最快,若不等待,周榜#1总是昨天刚发布的模型,而非持续一周的。
- 趋势
- 模型在某段时间内的增长与同一时间段内典型模型增长的对比。比典型快表示上升,比典型慢表示下降。
- 典型模型
- 目录的中间值:一半有数据的模型增长比它快,一半比它慢。
这个模型的受欢迎程度相对于整个目录的变化:它在每个时间段内下载量、点赞和使用量的增长,和同一时间段内典型模型的增长相比,以及当时的热度分数。高于典型增长表示上升,低于则表示下降。过去的数据是从今天的总数、模型的第一天和测量的下载速度(如果有两次测量)推算出来的;如果模型在某个时间段开始时不存在,则显示为 n/a。
示例作品
以下提示词和参数由在 Civitai 上创作这些作品的人分享。选择一张作品查看它是如何生成的。
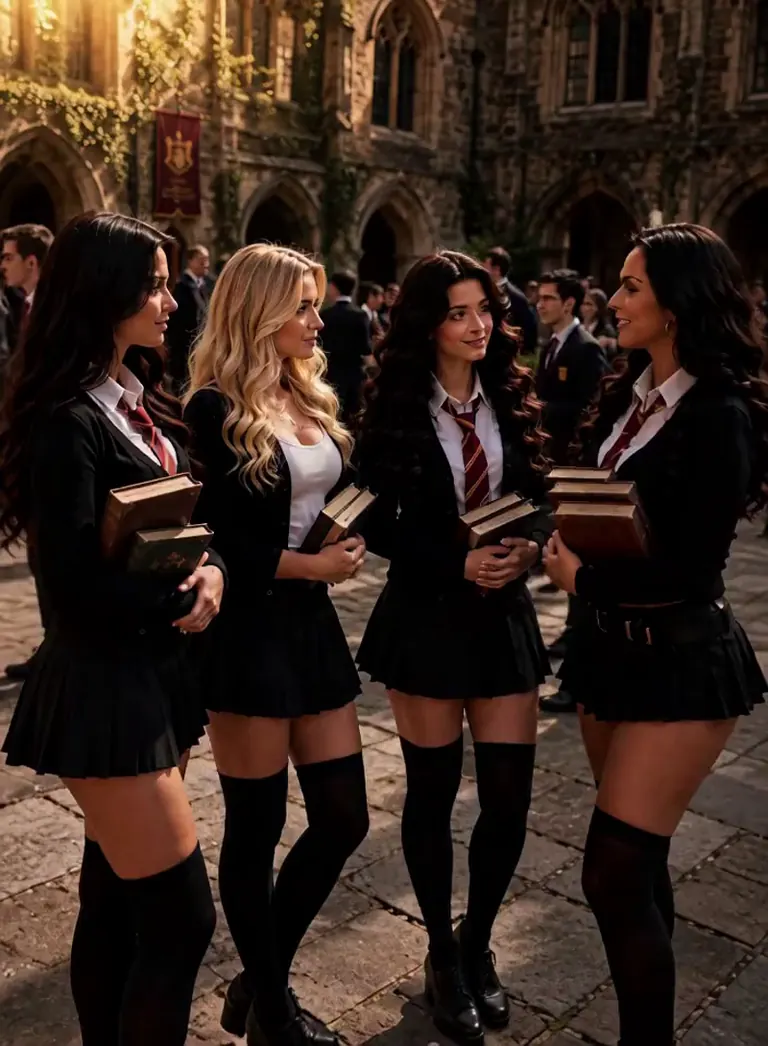
参数
尺寸
1152x640
提示词
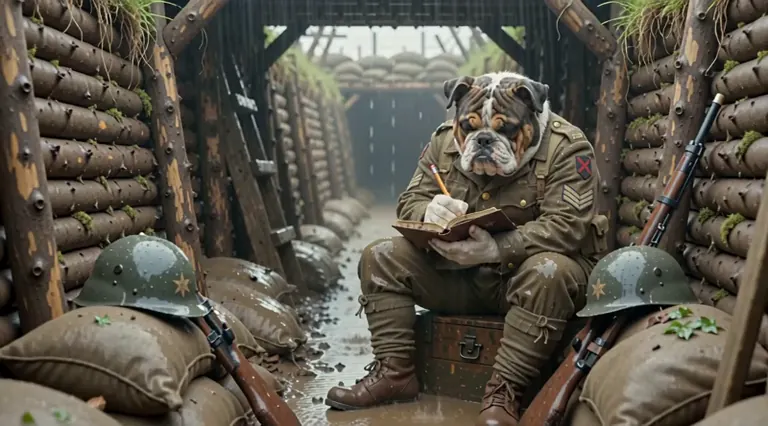
Anthropomorphic English bulldog soldier in a World War 1 trench, late 1910s. He has short stocky build, wrinkled grey-brown and white fur, heavy jowls, and a deeply sad, weary expression. He wears a muddy British khaki uniform, puttees, and a dented Brodie helmet resting beside him.
He sits on a wooden crate inside a dim, damp dugout, writing slowly in a small leather-bound diary with a pencil. Soft rain falls outside the trench entrance. The camera slowly pushes in on his face and the open diary pages.
An epic, low, somber male narrator voice says: "War never changes."
Cinematic lighting, muted desaturated colors, detailed wet fur and fabric textures, coherent slow motion over 15–20 seconds, heavy emotional atmosphere, no glory or action — only quiet exhaustion.
参数
步数
30
种子
1535164946
尺寸
1280x704
使用权重
0.7
提示词
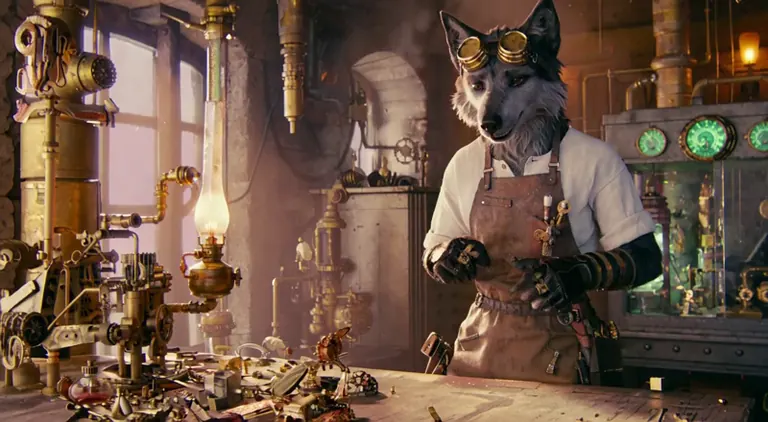
A 15-second photorealistic cinematic video. An anthropomorphic grey wolf scientist in a cluttered steampunk laboratory filled with brass pipes, glowing gauges, gears, and warm gaslight. He wears a worn leather apron over a white shirt with rolled sleeves and brass goggles pushed up on his forehead. He carefully assembles a detailed mechanical bird made of polished brass, copper, and small clockwork parts on a wooden workbench. While adjusting the wings and gears, he speaks in a thoughtful, serious voice:
“At what point does it stop being just a machine? When the gears move on their own… when it reacts… or only when it wants to keep moving? Where exactly does life begin?”
He turns a small brass component, watches the mechanical bird’s wing twitch slightly, and stares at it with quiet intensity. Soft steam rises in the background. Realistic fur, metal reflections, and warm steampunk lighting. 15 seconds exact
参数
尺寸
1056x704
提示词
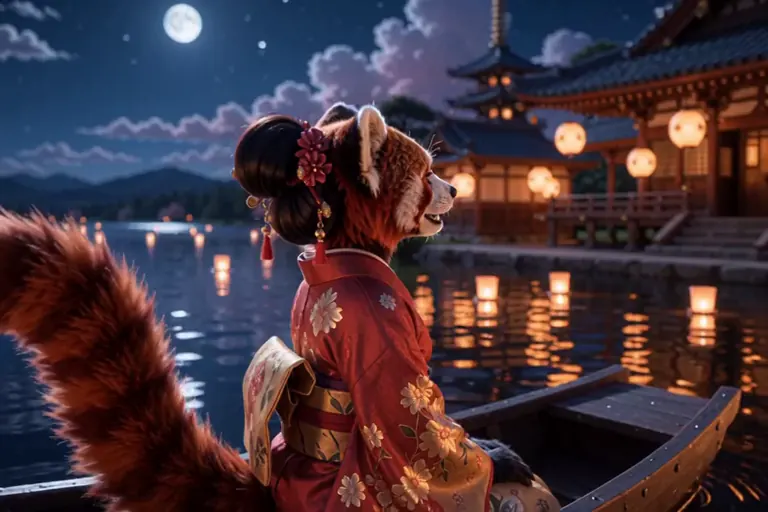
AA beautiful and highly detailed 30-second anime-style video of an anthropomorphic female red panda sitting in a small wooden boat on a calm lake at night. She has soft reddish-brown fur, cream-colored facial markings, large round ears, and a long fluffy ringed tail. She wears an elegant traditional geisha kimono in deep crimson and gold with delicate floral patterns, her hair styled in an elaborate updo decorated with ornate hairpins and silk flowers. Soft white makeup accents her face while keeping her red panda features clear.
The boat drifts gently near an ancient Japanese temple with glowing paper lanterns and a tall pagoda reflected on the water. Dozens of floating candles and small paper lanterns drift across the dark lake surface, their warm light shimmering on the gentle ripples. Above, an epic night sky stretches wide — a massive full moon, dense fields of stars, and soft purple-blue clouds edged with silver light.
She sings a gentle Japanese-style song in a clear, soft voice, lips moving naturally with the melody:
“Yoru no mizu ni, hikari ga mau
Tsuki ga michite, kokoro yasuragu
Kaze ga sasayaku, furusato no uta
Watashi no koe de, yume o tsunagu…”The camera slowly circles the boat in a smooth, cinematic motion, keeping her fully in frame while revealing the temple, floating lights, and vast sky. Soft moonlight and warm candle glow, highly detailed fur and fabric, serene and atmospheric.
参数
步数
20
种子
393546382
尺寸
704x960
使用权重
0.7
提示词
A single continuous cinematic shot in a sunlit courtyard with stone arches and banners. Four women in short black cardigans, white shirts, striped ties, short pleated skirts, and thigh-high black stockings stand in a close group holding thick books. The girl on the far right (long dark wavy hair, hoop earrings) leans in and whispers to the other three with a mischievous smile: “I heard the anatomy professor is EIGHT inches. Some of the other girls saw it."
The blonde woman says "No, he's more like nine. That's why I'm walking so funny today. Man am I sore." The blonde girl stretches and groans.
The other girls all turn and look at her in shock. They are scandalized.
Smooth continuous camera movement, no cuts, natural golden-hour lighting, highly detailed, realistic skin and fabric textures, dynamic expressions and motion.
参数
尺寸
736x1088
提示词
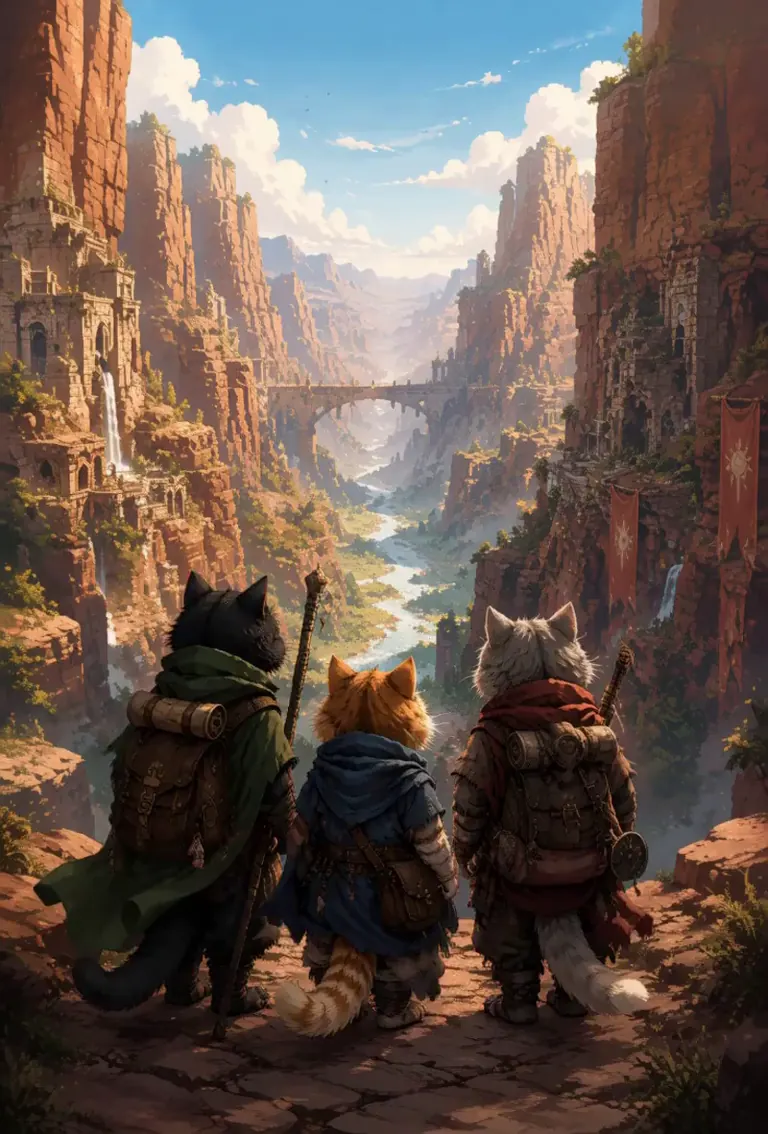
hree anthropomorphic cat adventurers standing on a stone path at the edge of a massive red-rock canyon, viewed from behind. Left: black-furred cat in a green cloak and leather backpack, holding a wooden staff. Middle: orange tabby cat in a blue hooded cloak with a small satchel. Right: white/grey cat in a red cloak and heavy backpack, sword on his back. They overlook a breathtaking canyon filled with ancient stone ruins carved into the cliffs, a long arched bridge spanning the chasm, a winding river far below, cascading waterfalls, and red banners with golden sun symbols hanging from the walls. Bright blue sky with soft white clouds. Camera starts behind them at eye level. Soft wind moves their cloaks and fur. The black cat slowly raises his staff and points toward the distant bridge. The orange cat turns his head slightly toward the others. The white cat shifts his weight and takes the first step forward. They begin walking down the path together, cloaks billowing. Camera slowly pushes forward and slightly rises, revealing more of the vast canyon and ruins. Distant birds glide between the cliffs. Sunlight glints off the river and stone. Ends as they continue toward the bridge, the full scale of the world opening in front of them. Epic atmosphere, rich colors, cinematic lighting, high detail, smooth motion, no text, no watermark.
参数
步数
28
种子
1357918036
尺寸
1280x704
使用权重
0.65
提示词
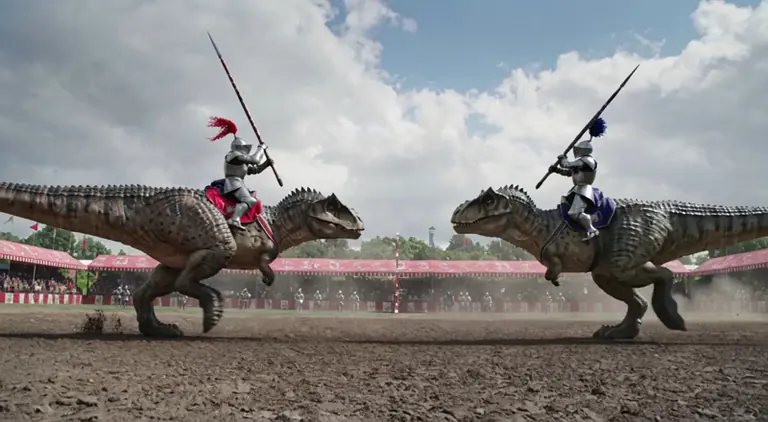
A static, locked wide shot of a muddy medieval tournament field, focused on two knights in polished steel plate armor riding massive, scaled T-Rexes instead of horses. The first knight, wearing red plumes, rides his T-Rex forward while the second knight, wearing blue plumes, charges from the right to meet him. They clash lances mid-stride, the wooden shafts snapping on impact, then both T-Rexes lunge backward in recoil before settling into a neutral stance. The camera never moves—no push in, no handheld, no zoom, no dolly. Overcast natural light, muddy ground, distant crowd blurred in the background. Audio: the heavy thud of T-Rex footsteps on mud, the sharp crack of lances breaking, the low guttural growls of the dinosaurs, ambient crowd murmur. No music, no other text.
参数
步数
23
种子
17874010
尺寸
704x960
使用权重
0.7
提示词
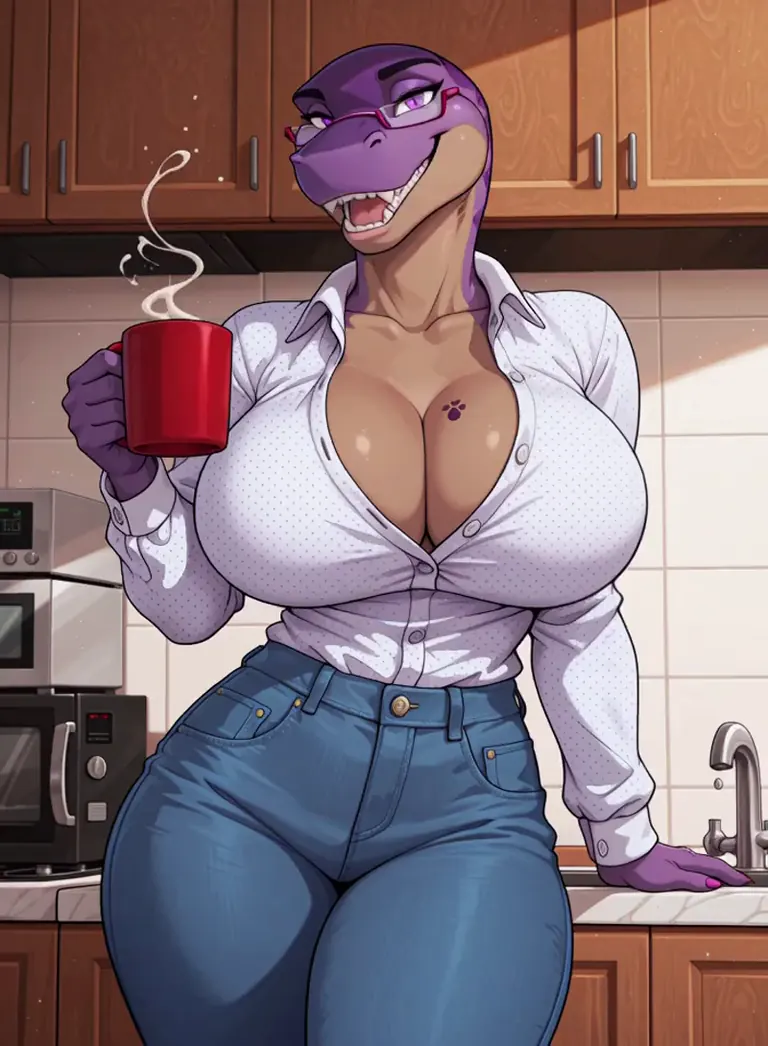
a anthro woman is standing in her kitchen holding a red mug.
(0-10s) she waves at the viewer and said in deep mature accent 'hello there! you got here just in time. David just left for work... and now....' she place her red mug down on the countertop behind her and began to grab her button shirt. she said in a seductive tone 'since it's just us you and me... we can get started" she then rips open her own button shirt very hard and fast exposing her breasts and nipples. breast slightly bounces by this.
(10-15s) night club rap music instantly plays here. instant transition cuts to a male pov in bedroom where the anthro woman is completely nude and she is riding the man, her breasts bounce rhythmically as she moves up and down rapidly on his penis. The motion is fast and continuous, with fluid body mechanics and natural weight transfer. Smooth, loopable animation with consistent energy. Static camera framing the couple closely, focusing on the vertical movement. Soft, warm lighting highlights the detailed animation style. High quality, 4k, detailed artwork, smooth motion. anthro tyrannosaurus), (purple scales), (purple skin:1.3), (tan chest:1.3), (tan skin:1.3), mature female, (huge breasts:1.2), (bottom heavy:1.2), (small waist)
romantic music playing in background
参数
尺寸
704x1056
提示词
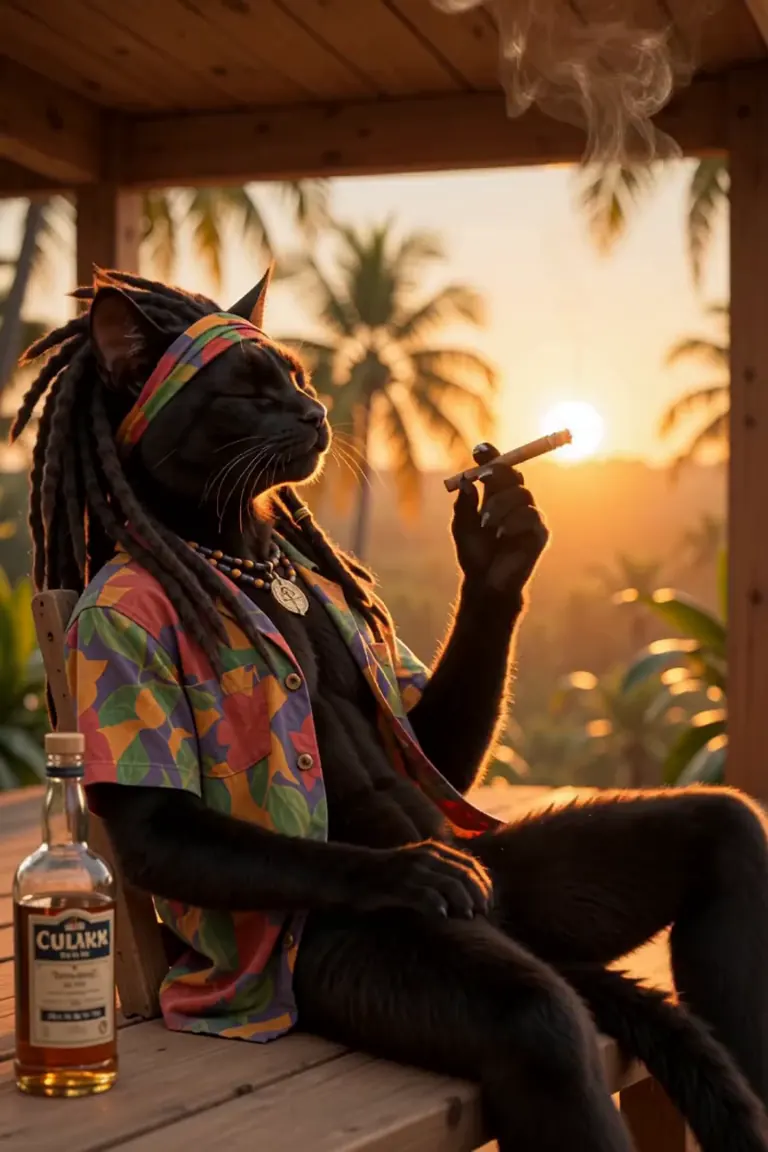
ultra-realistic cinematic reggae music video, chill positive island style: Exact anthropomorphic black cat Rasta with long dreadlocks, colorful headband and shirt, sitting on a wooden porch at golden sunset. He sings the full lyrics with relaxed soulful patois flow, eyes half-closed, paw gestures,holding an smoking joint with swirling smoke, and an rum bottle beside him. detailed jaw movements with detailed fangs.., slow zooms, Warm sunset lighting, palm fronds swaying, fragrant smoke ultra-detailed fur and textures, pure no-stress good-vibes atmosphere, 4K." the cat sings that following song: [0-6s] — Intro (beat kicks in light, selector energy) Camera opens slow on the porch, cat leaning back cool, joint smoke rising. He nods to the rhythm and points forward like calling the crowd. Cat (deep, smooth patois voice): “Yo! Selector! Turn up the bass bin… Watch the horizon… Fire inna the sky… Yeah!” [6-18s] — Chorus 1 (full band drops, everyone feels it) Cat raises the rum bottle high, takes a slow pull from the joint, eyes glowing with peace. Gentle head nods, dreads swaying. Cat (singing with heart, big smile): “Pour out the rum (Pour it!) Light up the herb (Blaze it!) Sun a go down (Way down!) No stress inna the world… Bottle inna hand… Smoke inna the chest… Me and my team… Yeah we truly blessed (Truly blessed!)
本地运行
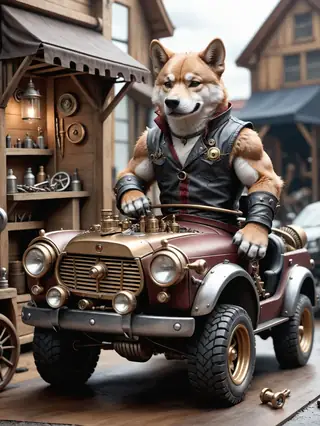
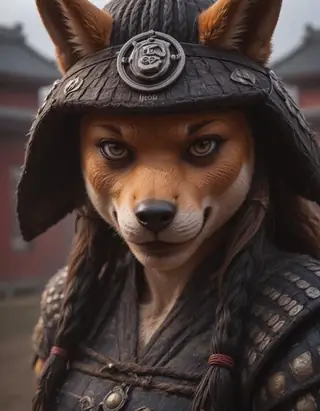
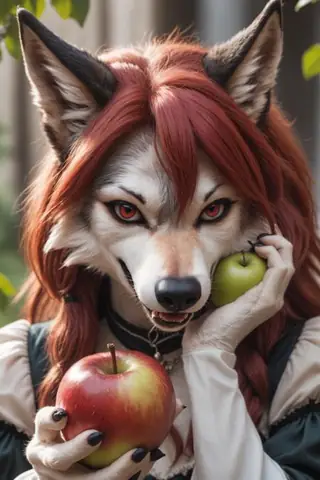
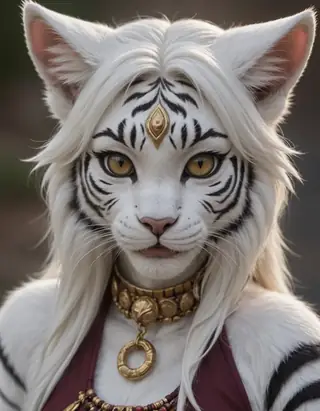
Furry Enhancer Video 是 MiniMax H3 系列的一个LoRA,收录于 ModelTrends.ai——一个只读的开源 AI 图像、视频和文本模型目录。你可以将它与其他 MiniMax H3 模型比较,查看热度分数了解趋势,并在 PirateDiffusion 或 BitVector 上打开试用。
按模型系列浏览
Text / LLM 模型
434
Anima 模型
528
Chroma 模型
19

Fibo 模型
2
Flux 模型
1,496
Flux 2 / Klein 模型
1,239

Flux 3 模型
3

Moss 模型
3

Iris 模型
1
MiniMax H3 模型
364
Hunyuan 模型
204

Ideogram 模型
20
Krea2 模型
717
Qwen 模型
20
Qwen2 模型
47
Ltx2 模型
153