Anything2RealCharacters Qwen2.1
NSFW
NSFW model. Its pictures are hidden while NSFW is off; turn NSFW on to see them.
Run Locally
Qwen2.1_Anything2RealCharacters.safetensors
304 MB · SafeTensor · bf16
Downloads are served by Civitai. Some creators ask for a Civitai login first.


About This Model
Compare
QWEN2 · LoRAs
by AIGC_Singularity - Anything2RealCharacters
Creator notes
Krea2_Anything2RealCharacters (V3 Release)
Krea2_Anything2RealCharacters-V3 is a high-resolution Image-to-Image / stylization LoRA model fine-tuned on top of Krea2_Turbo. It is specifically optimized to translate any 2D, anime, or artistic input into a high-fidelity, photorealistic style with fine skin micro-textures and precise facial details.
💡 What's New in V3
-
Complete Realism Conversion: Fixed the incomplete realism translation in V2.5, delivering significantly more authentic and natural photorealistic results.
-
Enhanced Character Consistency: Achieves vastly superior character feature retention and identity consistency compared to the original V1 release.
-
Released as LoRA for Maximum Flexibility: Unlike V2 and V2.5, V3 is released as a LoRA. This provides much stronger compatibility when stacking external Krea2 style or character LoRAs, opening up endless possibilities for custom aesthetics.
Special thanks to our community group members for their valuable test feedback! Unless critical issues arise, V3 will serve as the final release for the foreseeable future. For commercial inquiries, feel free to reach out. 🙏
🚀 Workflows & Online Demo
-
Try Online Demo:
-
Download ComfyUI Workflows:
✨ Key Features
-
Native 2048px Resolution Training: Trained on a full dataset at 2048×2048 resolution, allowing high-resolution direct outputs without additional upscalers.
-
Micro-Texture Detail: High-precision rendering of skin pores, hair strands, and realistic lighting.
-
LoRA Stacking & Compatibility: Fully compatible with external Krea2 Text-to-Image (T2I) LoRAs and face/character LoRAs for adjusting photography styles, lighting, and facial genetics.
-
Embedded Style & Feature Triggers: Fine-tuned support for custom film filters, lighting setups, and specific feature keywords.
-
Dual-Image Identity Transfer (Experimental): Supports transferring real-world identities from a reference image onto anime/stylized poses.
⚙️ Recommended Inference Settings
ParameterRecommended ValueDescriptionBase ModelKrea2 TurboCore architectureLoRA Weight0.8 – 1.0Adjust based on style intensitySampler Steps8 – 10Matches the Krea2 Turbo architectureCFG Scale1.0Prevents over-saturation and artifactsTarget Resolution2048 × 2048Native 2K outputCLIP / VAEStandard ComfyUI ModelsDownload official weights from ComfyUI Repository
🔑 Prompting & Trigger Words
Primary Trigger
Include the main trigger phrase at the start of your positive prompt:
transform the image to realistic photograph
Auxiliary Triggers & Filters
Mix and match these trained keywords to modify style, lighting, or body features:
-
Demographics: caucasian, woman, man, muscular
-
Gaze & Angles: looking at camera, look down, unfocused face
-
Lighting & Aesthetics: backlight, Film filter, hazy, photorealistic, highly detailed
-
Attire & Features: black stockings, white stockings
-
Anatomical Details: pubic hair, labia
🧪 Dual-Image Persona Conditioning (Experimental)
For transferring a real-world face onto a 2D/anime pose:
-
Figure 1: Base anime image (determines pose and structure).
-
Figure 2: Reference person image (determines real-world identity).
-
Dual-Image Trigger Phrase: with the character looking exactly like the one in Figure 2
⚠️ Note: Dual-image feature transfer is experimental and results may vary depending on the seed and input alignment.
Trigger words
photorealistic,transform the image to realistic photograph
SHA256
5DB4DD2376E6017812BF1189B2FC46E52AAA2C0B7E688FAAC75E83E1C4DCE849
ModelTrends.ai Model ID
#27521
Flag content
Example renders
Prompts and settings shared by the people who made these renders on Civitai. Pick a render to see how it was made.
NSFW
NSFW render, blurred. Turn NSFW on to see it.
NSFW render, blurred. Turn NSFW on to see it.
NSFW render, blurred. Turn NSFW on to see it.
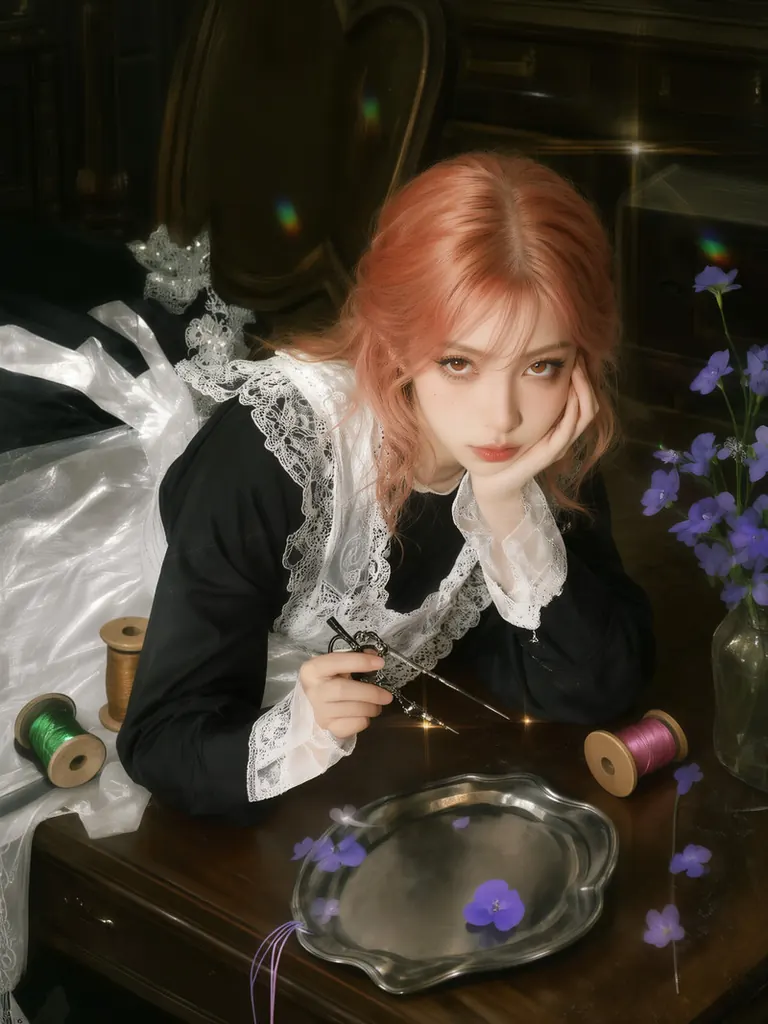
NSFW render, blurred. Turn NSFW on to see it.
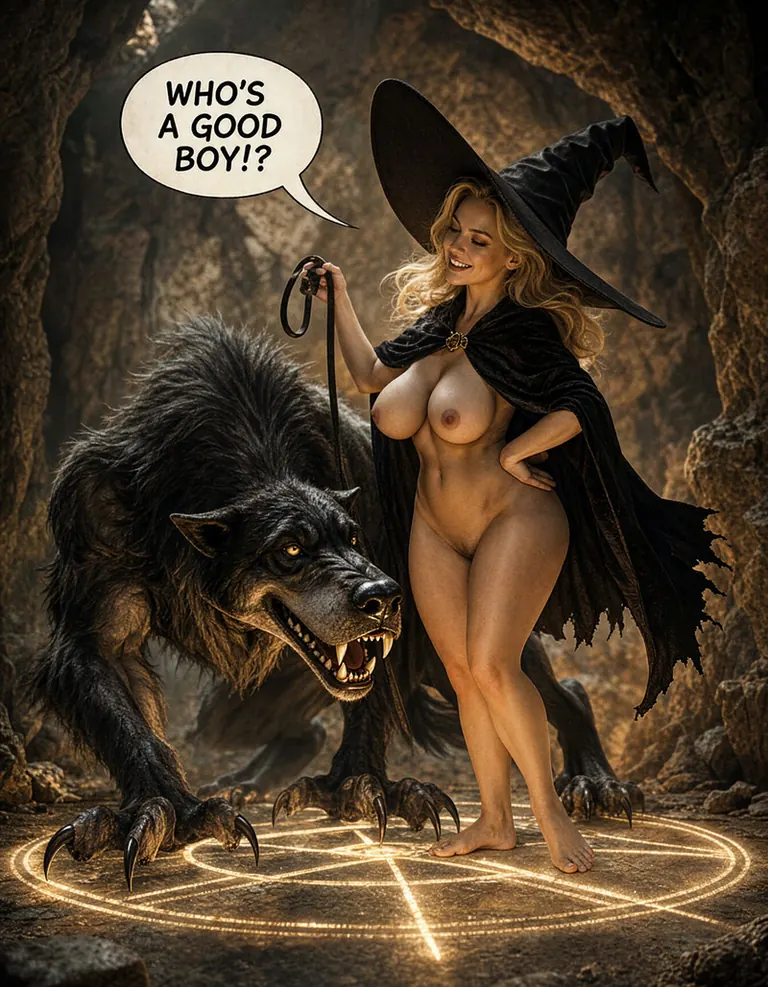
NSFW render, blurred. Turn NSFW on to see it.
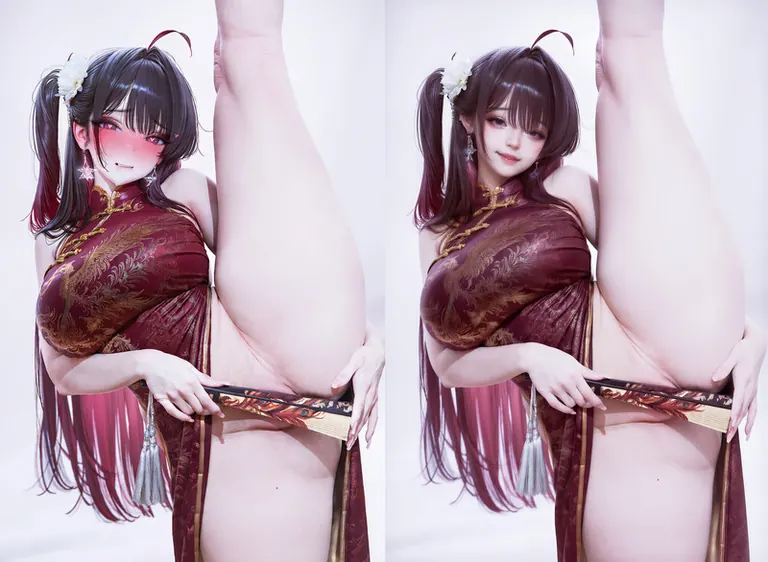
NSFW render, blurred. Turn NSFW on to see it.
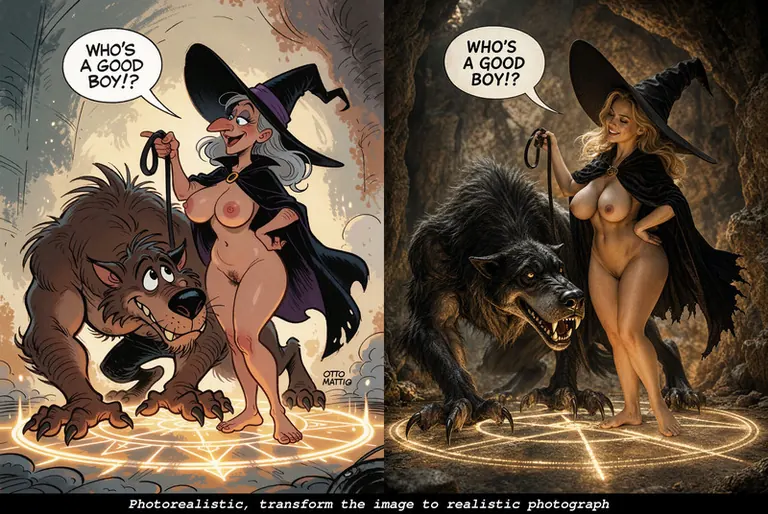
NSFW render, blurred. Turn NSFW on to see it.
Get this prompt
No prompt was shared with this render.
No prompt was shared with this render.
No prompt was shared with this render.
No prompt was shared with this render.
Settings
Sampler
res_2s
Steps
5
Guidance
1
Seed
489372181305894
Size
1344x1728
Prompt
Photorealistic photograph. A photorealistic, cinematic depiction of a nude blonde witch with wavy hair, fair skin texture, wearing only a signature witche's hat and tattered black velvet cape fastened at the neck with a gold clasp, standing barefoot on a glowing golden pentagram inscribed on stone, holding a black leather leash in her right hand while her left hand rests on her hip, smiling playfully as she looks down at a large, menacing black werewolf with sharp claws and fangs, which stands beside her on the ritual circle, its head tilted upward toward her; a speech bubble above her head reads "WHO'S A GOOD BOY!?" in bold black text; the scene is set in a dimly lit, cavernous underground chamber with rough-hewn stone walls and scattered rocks, illuminated by warm, directional lighting casting soft shadows and highlighting the textures of the witch’s skin, the werewolf’s fur, and the glowing magical symbols; shallow depth of field blurs the background while keeping the witch and werewolf sharply focused; rich color palette dominated by dark browns, blacks, and warm golden hues with high contrast and cinematic saturation; ultra-detailed, hyperrealistic rendering with sharp focus, no visible noise, and lifelike textures. Intricate details, masterful shading, cinematic composition, The aesthetic features deep chiaroscuro contrasts, dramatic volumetric lighting, and a rich, moody color palette and deep shadows, reminiscent of a masterpiece from a dark fantasy era; subtle volumetric light. Lighting: soft diffused light; realistic shadow falloff; physically based rendering; natural color grading. Camera: full-frame camera, 50mm lens, f-1.8, shallow depth of field, eye-level perspective. night, low bright, Use soft lighting to cast soft shadows on the subject, adding a touch of dimension to your images without compromising detail, cinematic lighting with warm-toned glow. Lighting and Composition: The lighting is focused on the subjects, highlighting their features and creating shadows that add depth to the image. The composition suggesting an intimate or intense interaction. Quality: 8k, HDR look, natural film grain (subtle), realistic reflections; no CGI look, no illustration; no drawing, no painting, no anime, no concept art, no stylized linework, no plastic skin, no unreal proportions, no over-smoothed textures, no AI artifacts, no cartoon lighting.
Settings
Sampler
Euler
Steps
25
Guidance
1
Seed
42
Size
1659x1216
Prompt
transform the image to realistic photograph
Settings
Sampler
res_2s
Steps
5
Guidance
1
Seed
489372181305894
Size
1792x1200
Prompt
Photorealistic, transform the image to realistic photograph. Photorealistic photograph. A photorealistic, cinematic depiction of a nude blonde witch with wavy hair, fair skin texture, wearing only a signature witche's hat and tattered black velvet cape fastened at the neck with a gold clasp, standing barefoot on a glowing golden pentagram inscribed on stone, holding a black leather leash in her right hand while her left hand rests on her hip, smiling playfully as she looks down at a large, menacing black werewolf with sharp claws and fangs, which stands beside her on the ritual circle, its head tilted upward toward her; a speech bubble above her head reads "WHO'S A GOOD BOY!?" in bold black text; the scene is set in a dimly lit, cavernous underground chamber with rough-hewn stone walls and scattered rocks, illuminated by warm, directional lighting casting soft shadows and highlighting the textures of the witch’s skin, the werewolf’s fur, and the glowing magical symbols; shallow depth of field blurs the background while keeping the witch and werewolf sharply focused; rich color palette dominated by dark browns, blacks, and warm golden hues with high contrast and cinematic saturation; ultra-detailed, hyperrealistic rendering with sharp focus, no visible noise, and lifelike textures. Intricate details, masterful shading, cinematic composition, The aesthetic features deep chiaroscuro contrasts, dramatic volumetric lighting, and a rich, moody color palette and deep shadows, reminiscent of a masterpiece from a dark fantasy era; subtle volumetric light. Lighting: soft diffused light; realistic shadow falloff; physically based rendering; natural color grading. Camera: full-frame camera, 50mm lens, f-1.8, shallow depth of field, eye-level perspective. night, low bright, Use soft lighting to cast soft shadows on the subject, adding a touch of dimension to your images without compromising detail, cinematic lighting with warm-toned glow. Lighting and Composition: The lighting is focused on the subjects, highlighting their features and creating shadows that add depth to the image. The composition suggesting an intimate or intense interaction. Quality: 8k, HDR look, natural film grain (subtle), realistic reflections; no CGI look, no illustration; no drawing, no painting, no anime, no concept art, no stylized linework, no plastic skin, no unreal proportions, no over-smoothed textures, no AI artifacts, no cartoon lighting.
Similar Models
Popularity trend
How this model's popularity has moved against the rest of the catalog: its growth in downloads, likes and usage over each period, measured against the typical model's growth over the same period, with its heat score at the time. Above the typical growth reads as a rise, below it as a fall. The past is reconstructed from today's totals, the model's first day and its measured download speed where two readings exist; a model that did not exist at the start of a period shows n/a.
This week
▲
1.9%
8,321° then, 8,327° now
This month
n/a
Not out yet at the start of this period
Past year
n/a
Not out yet at the start of this period
Measured download speed: about 3 a day, from two readings of the sources.
First seen 27 Sep 2026.
AI Models for Image, Video & Text Generation
Anything2RealCharacters Qwen2.1 is a LoRA for the Qwen2 family listed on ModelTrends.ai, a read-only catalog of open source AI image, video and text models. Compare it with other Qwen2 models, check its heat score to see how it is trending, and open it on PirateDiffusion or BitVector to try it.
Browse by Model Family
Text / LLM Models
415
Anima Models
519
Chroma Models
17
Flux Models
1,498
Flux 2 / Klein Models
1,239
MiniMax H3 Models
330
Hunyuan Models
204
Ideogram Models
20
Krea2 Models
676
Qwen Models
20
Qwen2 Models
36
Ltx2 Models
152
Stable Diffusion 1.5 Models
7,042
Stable Diffusion XL 1.0 Models
17,420
Zimage Models
815
Wan Models
1,067

Model
Trends
.ai
© ModelTrends.ai
|
© 2026
|
All Rights Reserved