Autoplay
Run Locally
Sharpness H3.json
0 MB · Other
minimax_h3_lms_v1.0_r64.safetensors
1.15 GB · SafeTensor · fp16
Downloads are served by Civitai. Some creators ask for a Civitai login first.


About This Model
MINIMAX H3 · LoRAs
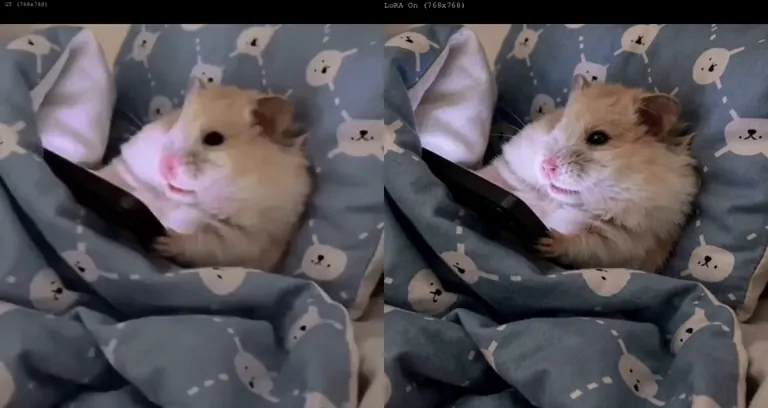
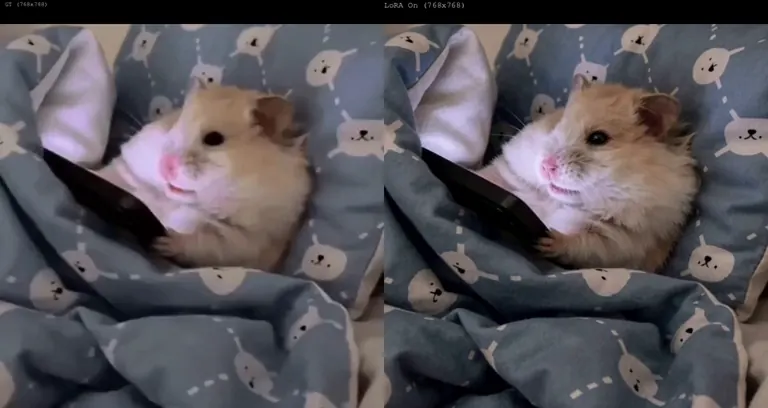
by NRDX - LMS - A Little More Sharpness. This is not an upscaler. It does not change your video's resolution or size. It works on the detail already in the frame — enriching it, or reshaping it, depending on how hard you push it.
Creator notes
A Little More Sharpness
This is not an upscaler. It does not change your video's resolution or size. It works on the detail already in the frame — enriching it, or reshaping it, depending on how hard you push it.
What it does
Trained mostly on real photography and video, with a strong focus on human subjects.
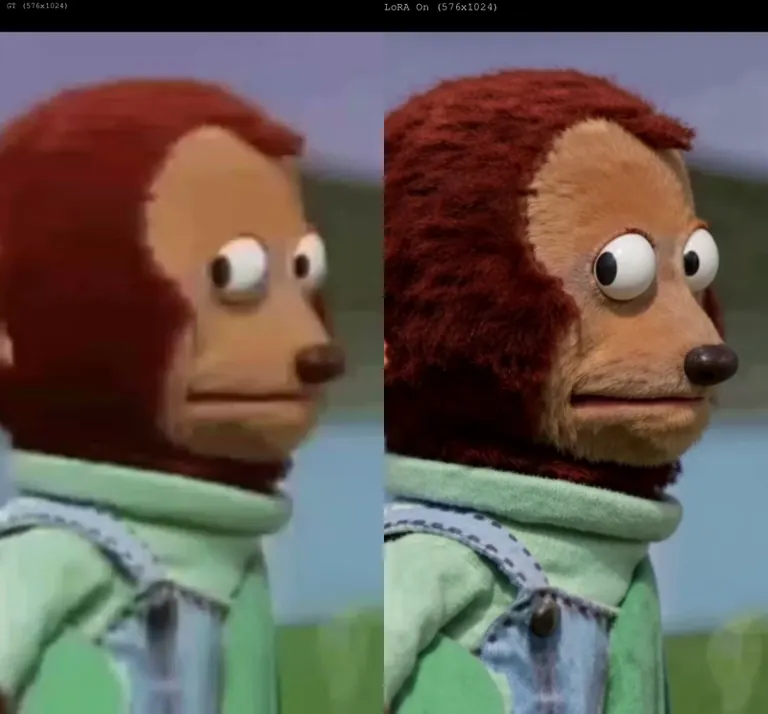
- On real footage — sharpens and enriches detail: skin, hair, fabric, edges.
- On anime, cartoon or stylized footage — pushes the subject toward a more humanized rendering (LTX 2.5 version).
Both behaviours come from the same mechanism. This LoRA is an extension of anime2real, which was built to turn stylized footage into realistic footage, so that pull toward realism is inherited. Feed it non-real input and expect some of it.
The name is modest on purpose, but be aware the effect is not always subtle — at higher strength it can do more than sharpen.
One of the main goals of this LoRA is to serve as a second pass for videos generated by any model, but especially Minimax H3 (LTX 2.5 version).
Strength is the control
This is the single knob that matters. Low strength leans toward enhancement, high strength leans toward transformation. There is no "correct" value — it depends on your source and the look you want. Start low and raise it until it lands.
Notes
Runs as a v2v pass over existing footage. Trained on human-centric content — results on non-human subjects are untested.
Trigger words
Enhance this video with sharp, crisp details while preserving a natural photorealistic appearance.
SHA256
071454F9B5A954EB0FB99C8B4470993A1A0100B7093A4DFFF79DF5225D4DC575
ModelTrends.ai Model ID
#27010
Flag content
Example renders
Prompts and settings shared by the people who made these renders on Civitai. Pick a render to see how it was made.
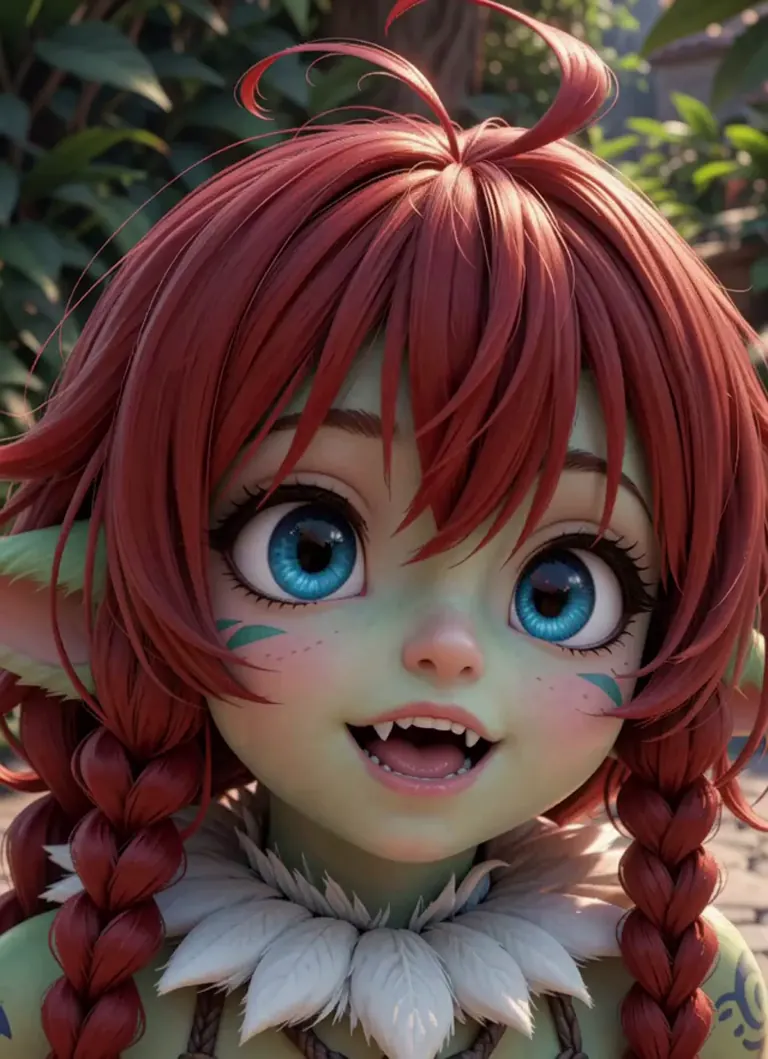
Settings
Size
672x928
Prompt
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced.
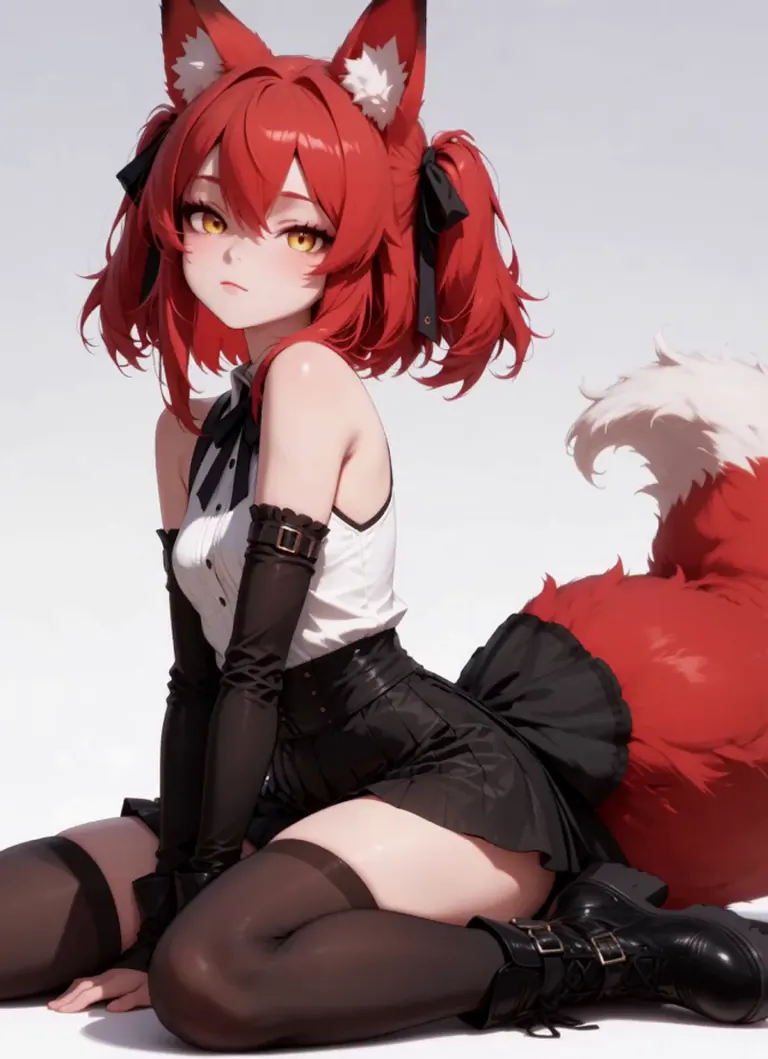
integrated_multimodal_description: [Shot 1] 2D-animated, cinematic, a medium-wide shot frames the red-haired fox girl with large golden eyes and pointed ears, kneeling on a plain white floor in a stylized black-and-white schoolgirl outfit with thigh-high stockings and black boots. She sits with her head slightly tilted, one hand resting on her knee, the other near her hip, looking directly forward with a calm, neutral expression. The camera holds a static shot as she begins to focus — her eyes narrow slightly, pupils dilate, and her ears twitch downward before suddenly pricking up with sharp, alert motion. Her head tilts just a fraction upward, and her gaze sharpens as if tracking something off-screen. Her tail curls slightly behind her as she shifts her weight subtly, preparing for movement. At 00:03.500, the camera cuts to a close-up of her face as she blinks once, then her ears snap upright in unison with a quick, synchronized motion — the fur along their edges flickers slightly. Her expression remains neutral but intensely focused, her lips parting just barely as if about to speak or react. She remains still for a moment, then slowly lifts her right hand toward her ear, fingers curling gently as if adjusting something or listening more closely. The shot ends with her ears fully erect, the tail curled tighter around her body, and her gaze locked forward, ready to respond.
overall_soundscape: A soft, ambient hum of studio lighting fades in as a faint, distant wind rustles through the background. The girl’s breath is barely audible, but her movements are crisp and silent — no footsteps, no ambient noise — only the subtle shift of fur and fabric as she adjusts her posture.
non_diegetic_music: Gentle, minimal piano notes at a slow tempo, with a single sustained string note that rises slightly as her ears prickle up, then fades out as she settles into focus.
Settings
Size
1152x1072
Prompt
Enhance this video with sharp, crisp details while preserving a natural photorealistic appearance.
Settings
Size
1536x816
Prompt
Enhance this video with sharp, crisp details while preserving a natural photorealistic appearance.
Settings
Size
672x928
Prompt
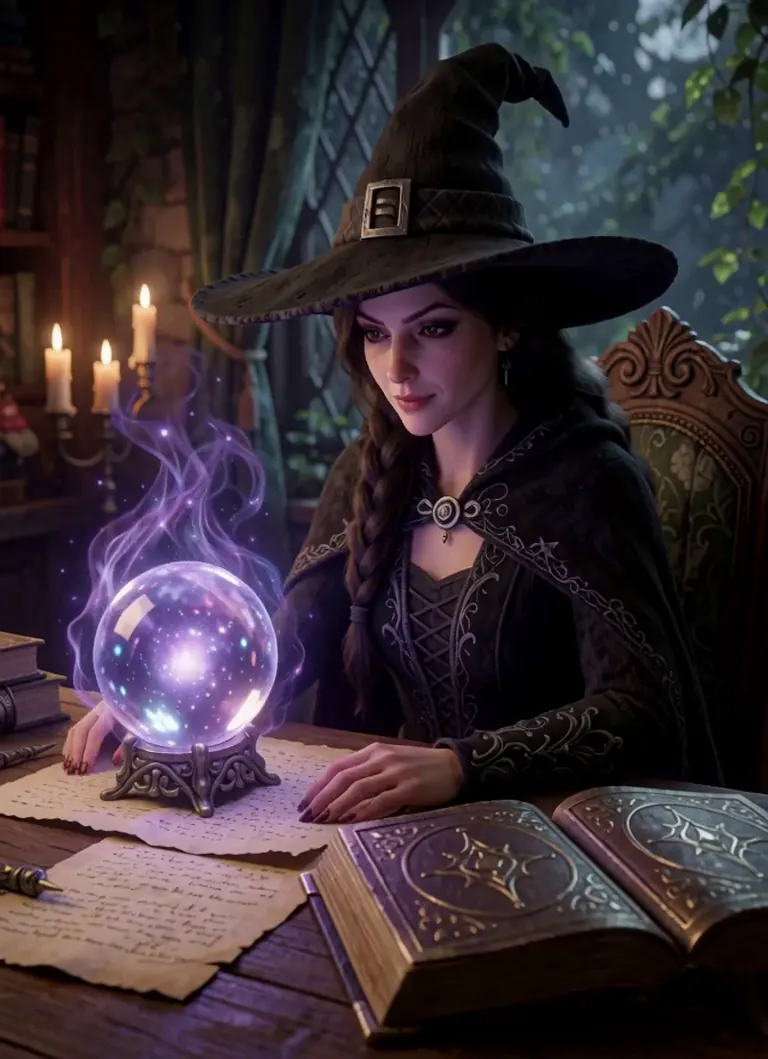
subject_definitions:
<Subject 1> is the witch in <Picture 1>, with long dark braided hair, wearing a tall pointed hat and a dark ornate robe, seated at a wooden table.
<Picture 1> is the reference image for the witch’s appearance and environment in [Shot 1] and [Shot 3].
<Picture 2> is the visual reference for the content that materializes inside the crystal ball in [Shot 2].
summary:
[video continuation + keyframe completion] The video begins with a close-up of a witch manipulating a glowing crystal ball, then transitions to a POV shot revealing a “Generation failed” error message emerging from the ball, before cutting back to the initial frame where she sighs in annoyance.
retention_analysis:
<Subject 1> (appears in [Shot 1], [Shot 3]): fully_preserved - her appearance, clothing, and seated posture are retained.
<Picture 1> ([Shot 1] first frame): fully_preserved - composition, lighting, and environment are preserved as the starting point.
<Picture 2> ([Shot 2]): fully_preserved - the “Generation failed” text and warning icon are directly rendered inside the crystal ball.
No video or audio references are defined.
detailed_description:
The scene opens with a realistic 3D CGI depiction of <Subject 1>, the witch, seated at a wooden table in a dimly lit, book-filled study. She wears a tall, textured black witch’s hat and an ornate dark robe with intricate embroidery. Her long dark hair is braided over one shoulder. In front of her rests a glowing crystal ball on an ornate stand, emitting swirling purple energy. An open spellbook lies beside it, and parchment scrolls are scattered across the table. Candles flicker in the background, casting warm light against stone walls and green curtains. The camera slowly pushes in on her hands as they hover around the ball, then smoothly zooms into a medium shot focusing on her face — calm, focused, and slightly amused. The camera then pans 90° clockwise to center on the crystal ball, transitioning seamlessly into a first-person view (POV) looking directly through the ball’s surface.
At 06.00, the crystal ball’s interior suddenly shifts: a blurry, ominous dark cloud swirls violently at its center. From this vortex, the image of <Picture 2> — a red warning triangle and the text “Generation failed... try again later” — begins to grow outward, materializing as if being summoned from within the ball. The POV perspective reveals her hands gripping the edges of the crystal ball on either side, as if anchoring the projection.
At 08.00, the scene cuts abruptly back to the exact frame of [Shot 1]. <Subject 1> leans back in her chair, takes a deep breath, lifts her chin, and looks upward with a weary, exasperated expression. Her voice, delivered off-screen by (S1), carries a tone of annoyance: <d>Not - again</d>.
overall_soundscape:
N/A
non_diegetic_music:
N/A
Settings
Size
1536x816
Prompt
Enhance this video with sharp, crisp details while preserving a natural photorealistic appearance.
Settings
Size
1792x720
Prompt
Enhance this video with sharp, crisp details while preserving a natural photorealistic appearance.
Settings
Size
1280x1920
Prompt
subject_definitions:
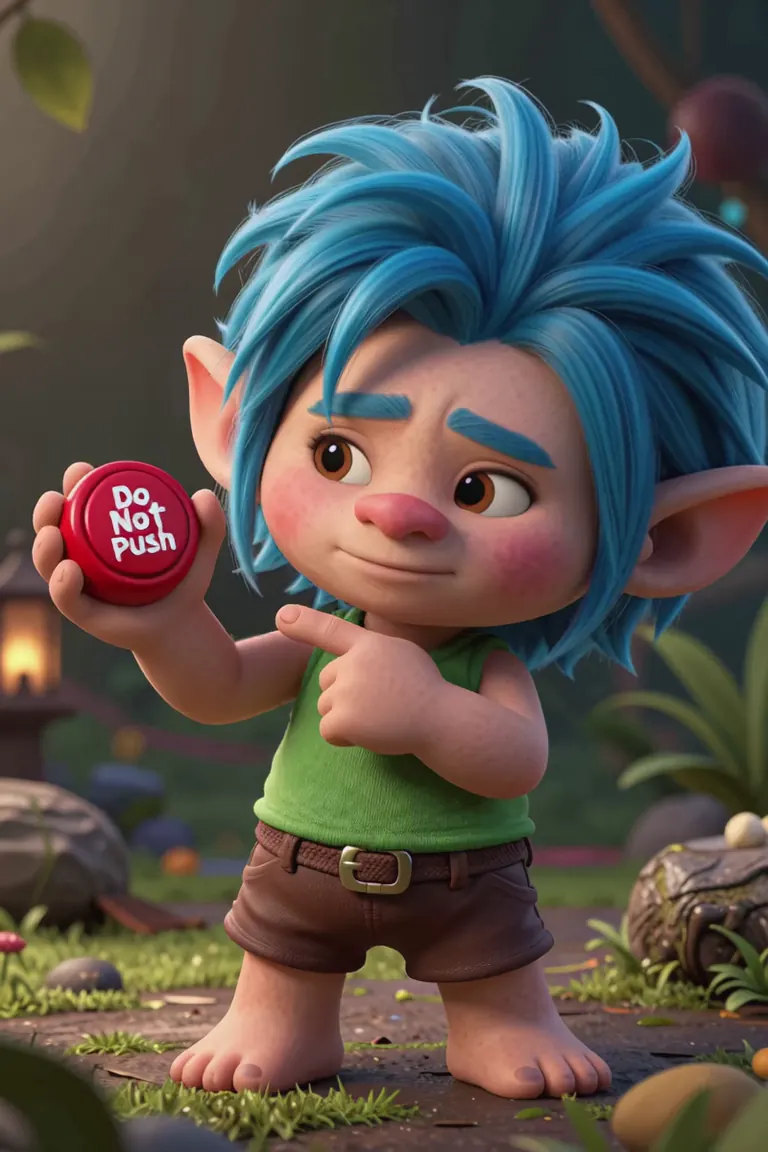
<Subject 1> is the young troll character in <Picture 1>, with spiky blue hair, pointed ears, a green tank top, brown shorts, and bare feet.
<Subject 2> is the transformed female troll character in <Picture 2>, with long flowing blue hair, pointed ears, a green crop top, brown shorts, and bare feet.
<Picture 1> is the starting frame of [Shot 1], showing the male troll holding a red button labeled "Do Not Push".
<Picture 2> is the ending frame of [Shot 1], showing the female troll after transformation.
overall_soundscape: Soft forest ambience with birds chirping and leaves rustling continues throughout the scene.
summary:
[reference generation] The target video shows a seamless 10-second continuous scene where <Subject 1> shakes a red "Do Not Push" button, pushes it, and transforms into <Subject 2>. The background features a natural forest environment with ambient sounds. No cuts occur during the sequence.
detailed_description:
The target video uses a cinematic, slightly whimsical animation style with soft natural lighting filtering through a forest canopy.
[Shot 1] The scene opens with <Subject 1>, the young troll with spiky blue hair, pointed ears, a green tank top, brown shorts, and bare feet, standing barefoot on mossy ground. He holds a red circular button labeled "Do Not Push" in his right hand while pointing at it with his left index finger. At 0-3s, he playfully shakes the button back and forth near his ears, then stops and looks down at it with a mischievous grin. He shrugs his shoulders with a playful expression before decisively pushing the button with his other hand. At 3-7s, the button falls to the ground with a soft thud. <Subject 1> looks down at the fallen button with wide-eyed surprise. His body begins to transform seamlessly: his hair grows longer and flows down his back, his torso elongates by two times its original height, his arms and legs stretch outwards, and his facial structure subtly shifts to match <Subject 2>'s features. By 7s, he has fully transformed into <Subject 2>, the female troll with long flowing blue hair, pointed ears, a green crop top, brown shorts, and bare feet. At 7-10s, she looks down at her new form with a puzzled expression, tilting her head slightly as if examining herself. She then slowly looks around the forest environment, appearing confused yet curious about her new appearance. The entire transformation occurs without any cuts or camera movement, maintaining a continuous shot throughout the 10 seconds.
retention_analysis:
<Subject 1> (appears in [Shot 1]): fully_preserved - the spiky blue hair, pointed ears, green tank top, brown shorts, and bare feet are retained throughout the initial state.
<Subject 2> (appears in [Shot 1]): fully_preserved - the long flowing blue hair, pointed ears, green crop top, brown shorts, and bare feet are retained in the final transformed state.
<Picture 1> ([Shot 1] first frame): fully_preserved - the male troll holding the red "Do Not Push" button is retained as the starting visual anchor.
<Picture 2> ([Shot 1] last frame): fully_preserved - the female troll's final appearance after transformation is retained as the ending visual anchor.
non_diegetic_music: N/A
Settings
Size
672x928
Prompt
integrated_multimodal_description:
For the target video, at 0.00 seconds into the target video, <Picture 1> is fully referenced as the first frame.
[Shot 1]
A single continuous 10-second close-up of the same character, preserving her exact appearance, hair, eyes, skin, outfit, lighting, and forest background. Nearly static camera with a subtle push-in. No cuts, No dialogue.
at 00.00, Bright open smile. She blinks, then looks slightly left and back to camera, tilting her head gently.
at 02.00, Her smile softens into curiosity. Eyes widen, eyebrows rise, and her gaze shifts right before returning to camera; head follows with a small tilt.
at 04.00, Curiosity becomes playful surprise. Eyes open wide, mouth parts, then she tilts her head and gives a mischievous sideways glance.
at 06.00, Surprise melts into joyful amusement. Eyes squint slightly with happiness, cheeks lift, head bobs subtly, and she blinks while smiling.
at 08.00, She glances down, then quickly looks back up at the viewer, tilts her head slightly, and settles into confusion ans surprise.
Smooth continuous transitions, expressive eye tracking, natural blinks, eyebrow movement, subtle breathing and lively head motion. No dialogue.
overall_soundscape:
Soft forest ambience throughout: faint birds, gentle leaves moving in a light breeze, and very subtle natural outdoor atmosphere. No dialogue. No exaggerated sound effects.
non_diegetic_music:
N/A
Similar Models
AI Models for Image, Video & Text Generation
lms h3 is a LoRA for the MiniMax H3 family listed on ModelTrends.ai, a read-only catalog of open source AI image, video and text models. Compare it with other MiniMax H3 models, check its heat score to see how it is trending, and open it on PirateDiffusion or BitVector to try it.
More MiniMax H3 modelsMore MiniMax H3 LoRAsvideoeditseffectsrealisticsharpnessltx25detailsbetter skin
Browse by Model Family
Text / LLM Models
411
Anima Models
509
Chroma Models
14
Flux Models
1,071
Flux 2 / Klein Models
1,237
MiniMax H3 Models
331
Hunyuan Models
197
Ideogram Models
20
Krea2 Models
674
Qwen Models
17
Qwen2 Models
36
Ltx2 Models
150
Stable Diffusion 1.5 Models
6,465
Stable Diffusion XL 1.0 Models
15,432
Zimage Models
804
Wan Models
919

Model
Trends
.ai
© ModelTrends.ai
|
Made in Japan
|
© 2026