Appar som stöder ModelTrends-taggar låter dig köra/installera modeller genom att kopiera denna kod i din prompt utan någon installation. Leta efter vår ikon i appar som stöder det, som Prism (nedan).
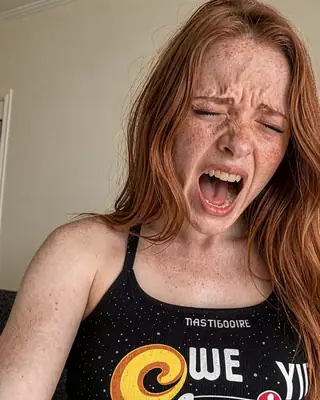
MOSS-Image: A 5B-parameter open diffusion model with layout control and text rendering in English and Chinese. Powered by Qwen3.5-9B and the FLUX.2 latent space. UPDATE - Supports LoRAs. Telegram Commands: /run:moss-image [prompt] - Generate an image from description or spatial layout /steps:50 - Sampling steps (default: 50, range: 15-100) /guidance:3.0 - Prompt guidance / CFG (default: 3.0, range: 1.5-6.0) /seed:42 - Reproducible random seed /size:1024x1024 - Output canvas size (multiples of 16, e.g. 1024x1024, 1280x768, 768x1280) /slot1:5.0 - Flow sampling shift (default: 5.0) Tips: - Text…MOSS-Image: A 5B-parameter open diffusion model with layout control and text rendering in English and Chinese. Powered by Qwen3.5-9B and the FLUX.2 latent space. UPDATE - Supports LoRAs. Telegram Commands: /run:moss-image [prompt] - Generate an image from description or spatial layout /steps:50 - Sampling steps (default: 50, range: 15-100) /guidance:3.0 - Prompt guidance / CFG (default: 3.0, range: 1.5-6.0) /seed:42 - Reproducible random seed /size:1024x1024 - Output canvas size (multiples of 16, e.g. 1024x1024, 1280x768, 768x1280) /slot1:5.0 - Flow sampling shift (default: 5.0) Tips: - Text Rendering: Put text in quotes within the prompt or use newlines (\n) for line breaks. - Negative Prompt: Default filter cleans up artifacts (worst quality, bad anatomy, blurry, watermark). - Layout Control: Supports 4K token prompts and structured JSON bounding boxes.
Skaparens anteckningar
MOSS Image is a 5B parameter text-to-image DiT from the OpenMOSS team, built for accurate in-image text, layout control and long prompts. It pairs a Qwen3.5 9B text encoder with the FLUX.2 VAE, accepts prompts of up to 4K tokens in natural language, booru-style tags or a JSON layout, and renders from 512px up to 2K at any aspect ratio.
Originally released by on Hugging Face. All credit for the model goes to the OpenMOSS team. Civitai hosts a mirror so creators can generate with it on-site and train against it. Head to the for the reference pipeline, the user guide and updates.
Two versions
-
SFT is the supervised fine-tune of Base on curated data. OpenMOSS recommends it for generation: cleaner text grouping and more organised layouts.
-
Base is the undistilled base model with no post-training. OpenMOSS recommends it for fine-tuning and LoRA training. LoRAs trained on Base can also be used on SFT, with partial compatibility.
Both run at 50 steps with CFG 3 (raise it for short prompts), flow-matching Euler, shift 5. OpenMOSS recommends English prompts; Chinese and other languages are supported. Use line breaks and quotes around text you want rendered.
Files
Each version carries the diffusion model in bf16 and int8, from the . The Qwen3.5 text encoder and FLUX.2 VAE ship in the same repo. The original Diffusers weights are at and .
Generating on Civitai
Both versions are in the Civitai generator for text-to-image, with steps, CFG and a negative prompt exposed. JSON layout prompts work as plain prompt text. Image editing and reference images are not part of this release.
License
MOSS Image weights and inference code are released under the . Commercial use, derivatives and LoRAs are allowed; keep the licence notice with any redistribution.
Links
-
-
-
-
-
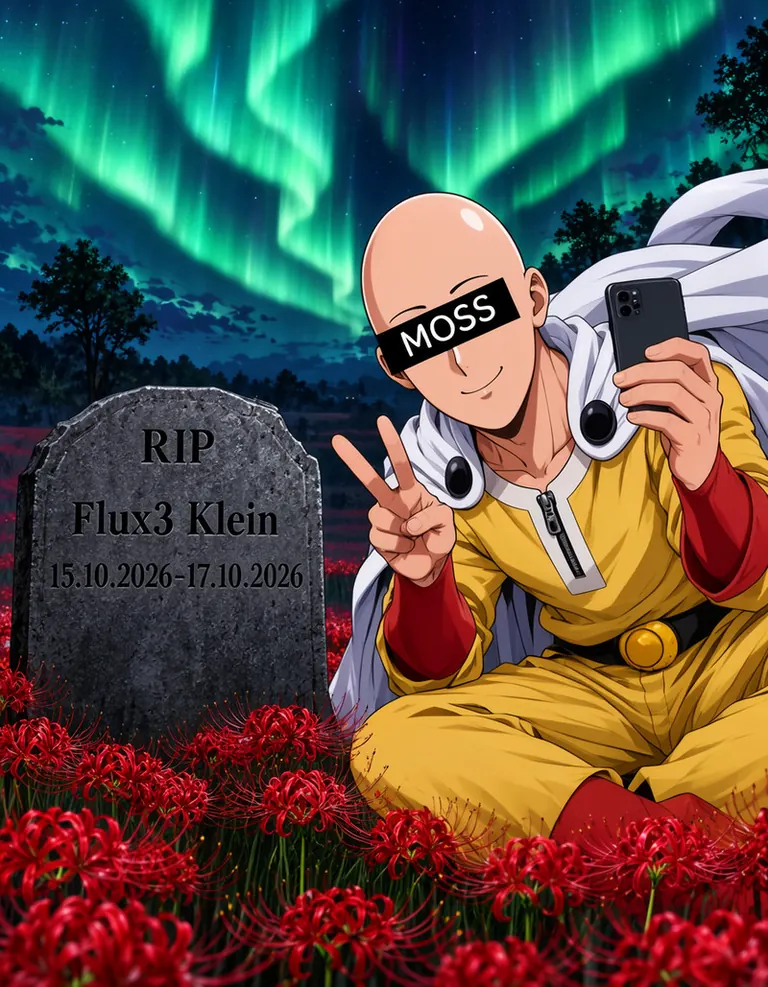
A digital anime art depicts a man, saitama \(one-punch man\), at right of the image, poses with a peace sign and taking selfie next to a tombstone at left of the image. He sits in a field of red spider lilies under a glowing aurora borealis. His eyes are covered by black censor bar with white text "MOSS".
The tombstone engraved with words "RIP", "Flux3 Klein", "15.10.2026-17.10.2026". This medium shot features a vibrant anime style with dramatic lighting, contrasting the somber grave with his smug, cheerful expression.
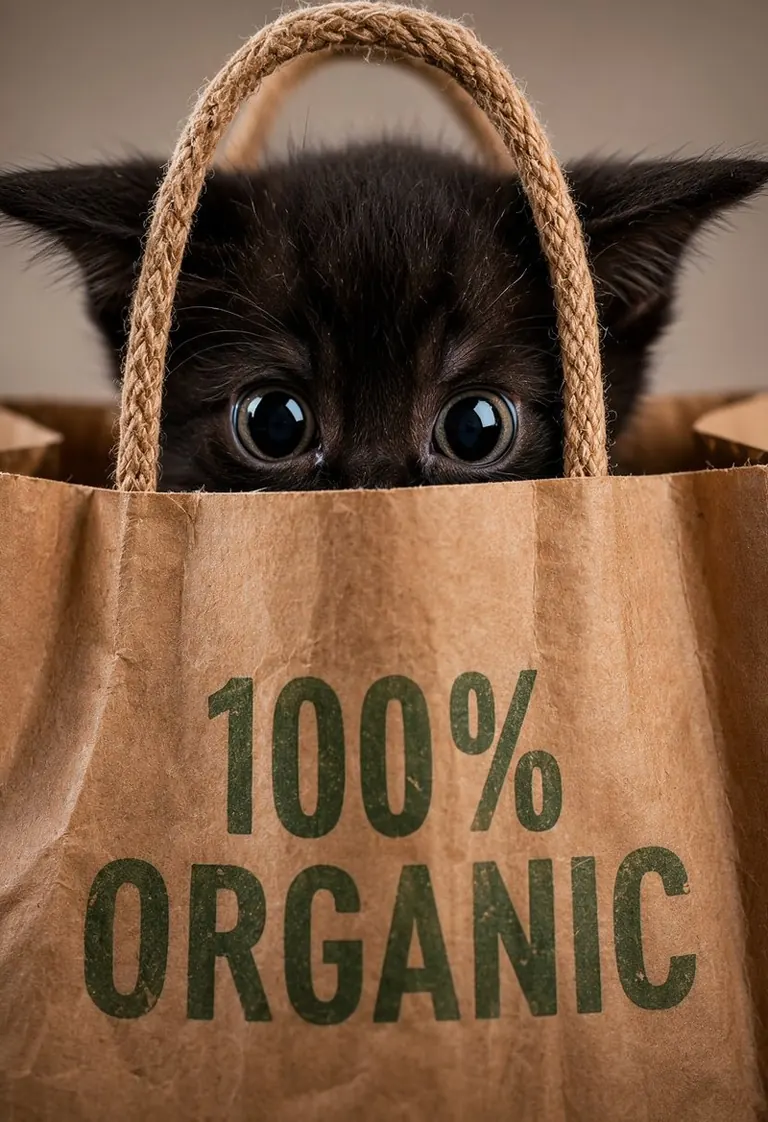
Editorial studio animal photography. Shot with 85mm f/2.8 lens, narrow depth of field, bokeh. Perfect exposure, natural diffuse light casting soft shadows. Peek-a-boo by a little black kitten hiding inside a standing up brown paper grocery bag. Highly detailed textures, creases and wrinkles on the paper and cloth handle of the bag;
The mischievous kitten is in full high energy play-and-hunt mode, an extremely intense gaze with enormous fully dilated pupils, ears flattened forward in full focus forward;
Sharp focus on the eyes;
Extreme tight crop, extreme close-up; the face of the kitten is framed inside the rope handles of the paper bag;
Stamped directly onto the rough paper texture is the text "100% ORGANIC". The lettering is rendered in a minimalist, faded dark green sans-serif grocery store font, featuring slight texture imperfections and subtle ink bleeding into the paper grain to match the lighting and curvature of the bag perfectly.
Primary visual focus and impact of the image is the comedic effect of the kitten keeping a low profile, with striking eyes just above the edge of the bag and ears comically flattened; flattened "airplane" ears!
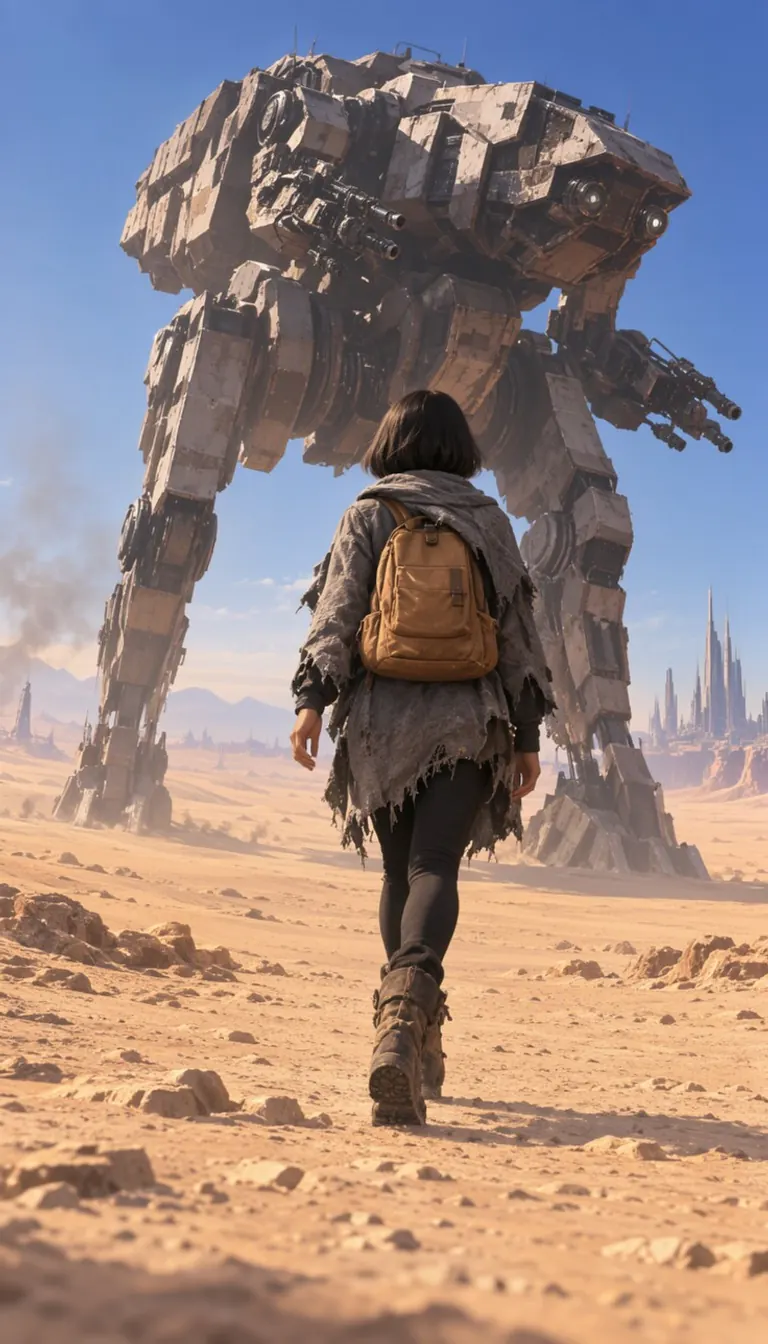
A lone figure, likely female, walks away from the viewer across a vast, sandy desert landscape, facing a colossal, dilapidated war machine. The subject is of indeterminable ethnicity, her hair a dark, blunt bob. She wears a tattered gray wrap, a tan leather backpack, black leggings, and worn brown boots. The war machine, a massive bipedal walker, towers behind her, constructed from weathered metal panels, suggesting advanced age and battle damage. Its design features a large cockpit and weaponry. The sky is a clear, bright blue, contrasting sharply with the warm tones of the desert and the cooler grays and browns of the machine and the figure's attire. The background features a distant, futuristic city with tall, spired structures. The composition uses a low-angle perspective, emphasizing the scale of the walker and the vulnerability of the lone figure. The overall mood is one of post-apocalyptic exploration, a sense of solitude, and facing overwhelming odds. The lighting is strong, casting shadows and highlighting the textures. Style reminiscent of Science Fiction concept art, and digital painting.
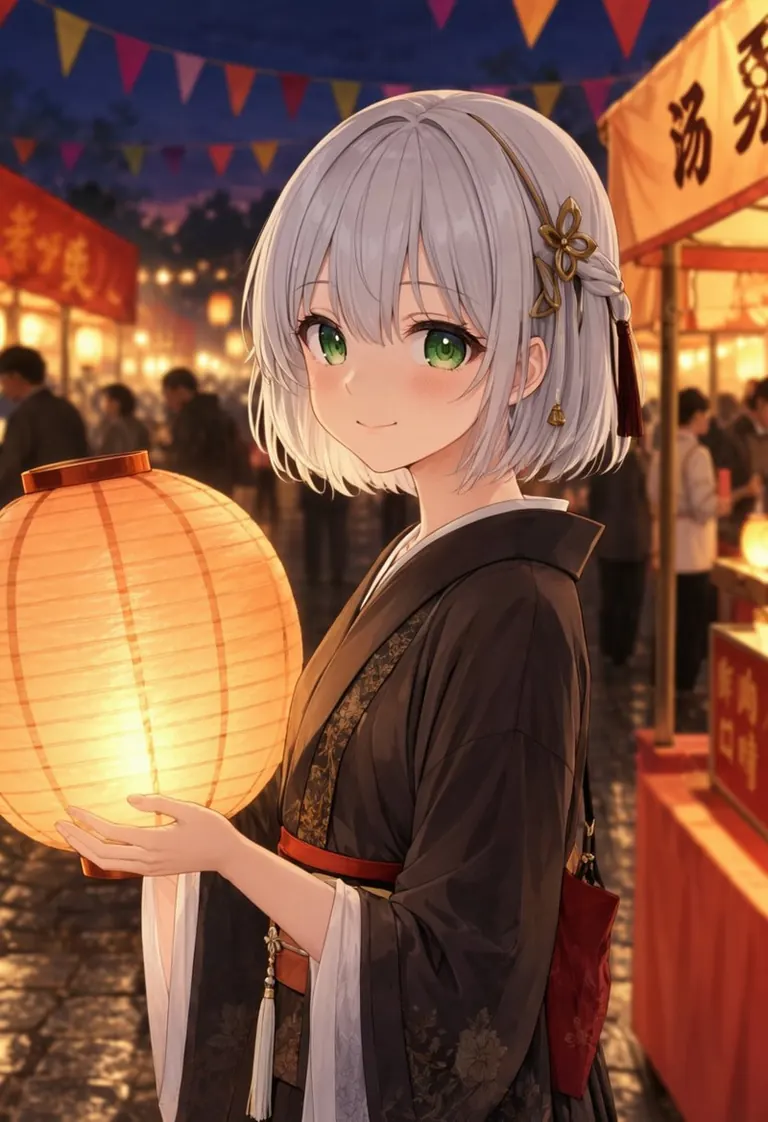
best quality, highres, 1girl, silver hair, green eyes, holding a glowing paper lantern, night festival, paper streamers, food stalls in the background, soft bokeh, detailed background, gentle smile, anime illustration
Negativ prompt
nsfw, worst quality, bad anatomy, watermark, jpeg artifact
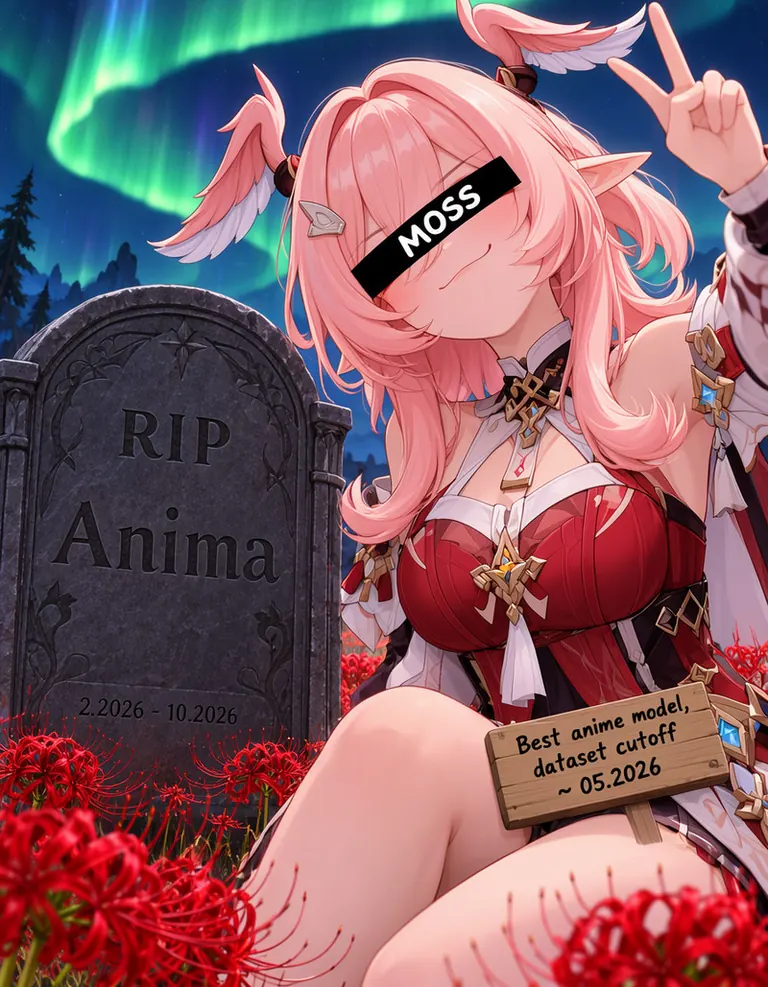
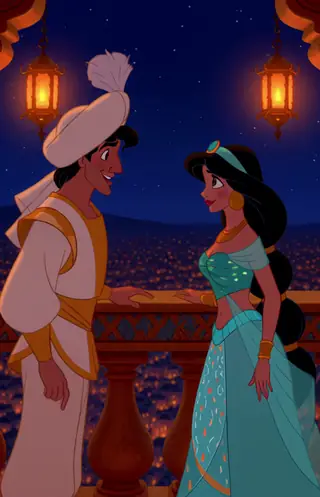
A digital anime art depicts a girl, linnea \(genshin impact\), at right of the image, poses with a peace sign and taking selfie next to a tombstone at left of the image. She sits in a field of red spider lilies under a glowing aurora borealis. Her eyes are covered by black censor bar with white text "MOSS". A wooden sign placed on her leg with the words "Best anime model, dataset cutoff ~ 05.2026".
The tombstone engraved with words "RIP", "Anima", small text "2.2026 - 10.2026" at bottom.
This medium shot features a vibrant anime style with dramatic lighting, contrasting the somber grave with her smug, cheerful expression.
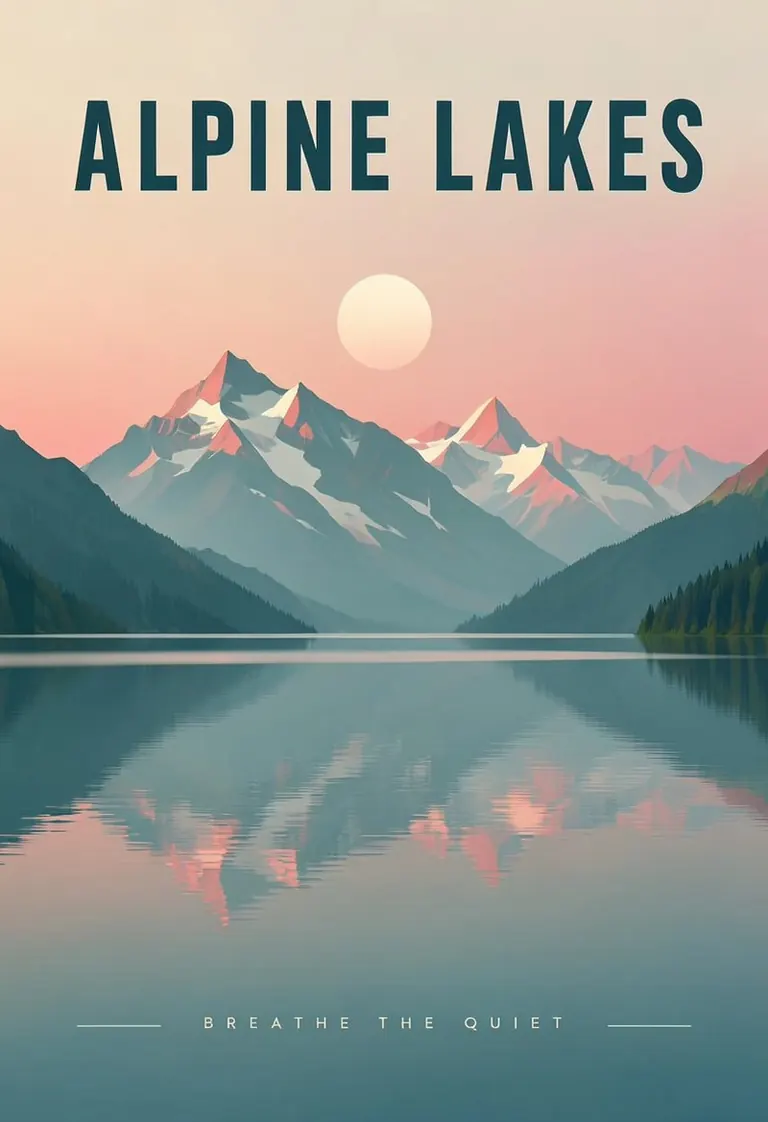
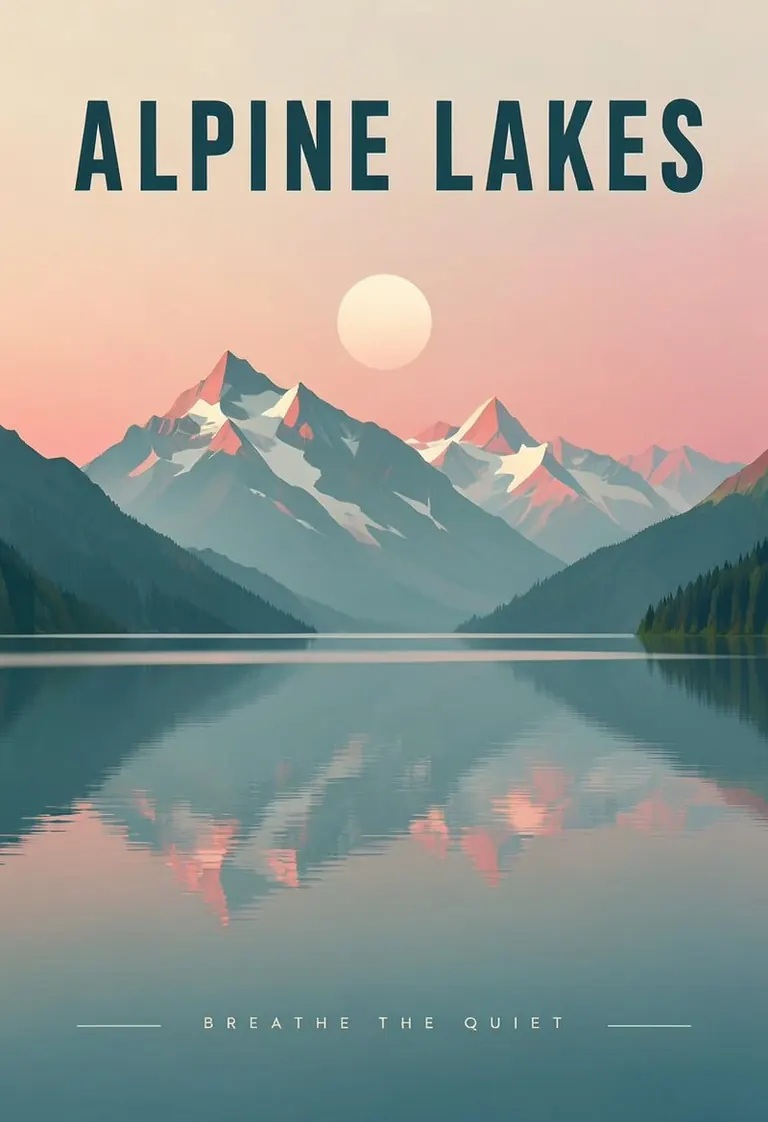
A minimalist travel poster of a still mountain lake at dawn, flat vector style with soft gradients. A bold title "ALPINE LAKES" across the top and the tagline "breathe the quiet" in small capitals along the bottom. Teal, cream and dusty pink palette, clean typography, centered composition.
Negativ prompt
nsfw, worst quality, bad anatomy, watermark, jpeg artifact
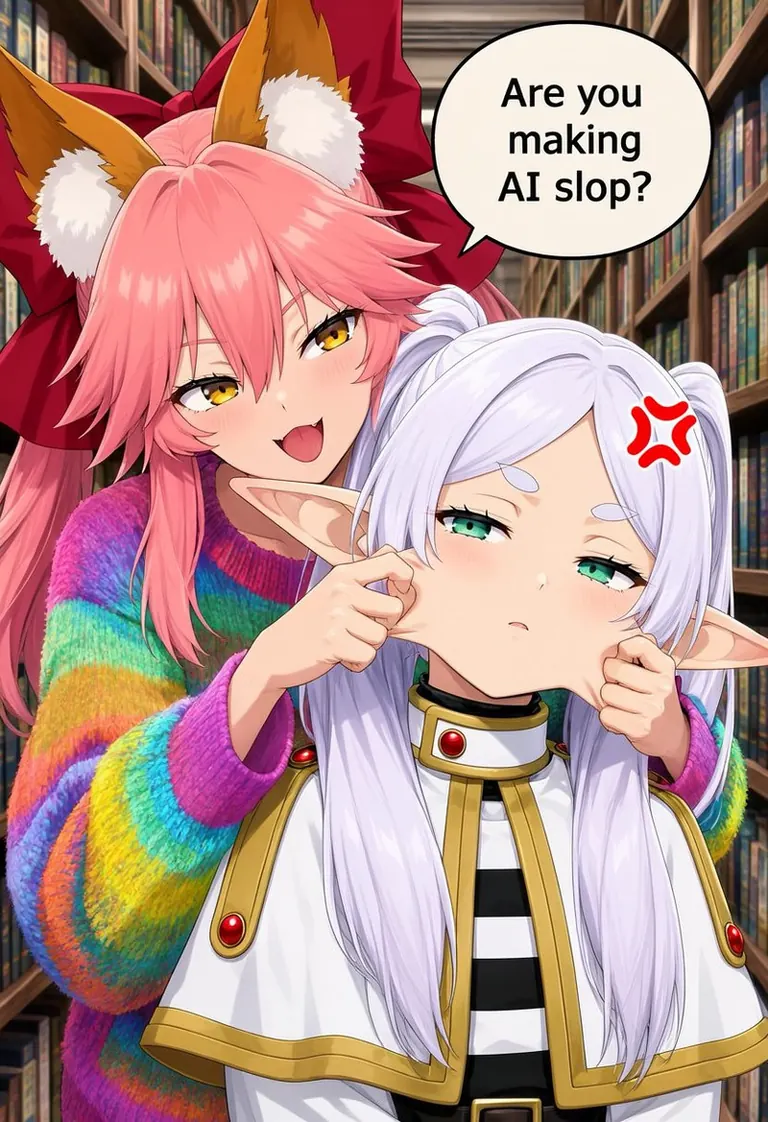
Close-up shot of two anime girls, tamamo \(fate\) and frieren, inside a library aisle, between tall bookshelves.
tamamo \(fate\), on the left, has pink hair, large fox ears. She wears a vibrant, multi-colored sweater and a playful expression as she stands behind Frieren, using both hands to pinch and stretch frieren’s cheeks. Speech bubble at top right "Are you making AI slop?"
frieren, an elf with long pointed ears and green eyes, wears her mage outfit. She has a neutral, slightly dazed expression, half-closed eyes, while her face is being pulled. Red "anger" symbol on her head.
@abe tsukasa,
MiMo-V2.6-Pro är Xiaomis flaggskeppsmodell: ett sparsamt Mixture-of-Experts-system med totalt 1,02 biljoner parametrar (42 miljarder aktiverade) som hanterar text, bild, video och ljud i en enda modell. Dess kännetecken är en förstärkningsinlärningspipeline designad för att ständigt förbättra sig själv genom utforskning snarare än separat finjustering per domän. Den passar team som kör komplexa agentbaserade arbetsflöden, kod med lång kontext eller forskningsuppgifter, och alla som vill ha en kapabel öppen-vikts gränsmodell till under en dollar per miljon tokens.
Känd för
Verklig omnimodal: text, bild, video och ljud hanteras inbyggt i en modell
1 miljon tokens kontextfönster – tillräckligt långt för hela kodförråd eller agentkörningar över flera sessioner
En enda blandad RL-körning över kodning, visuella, generella och cybersäkerhetsuppgifter
En seriös öppen-vikts gränsmodell för agentbaserat och långkontextarbete – priset är rätt, men hårdvarukraven är inte vardagliga.Kaptens omdöme