
H3 LTX 2.3 I2V T2V Video Reasoning lora VBVR H3 VBVR Pro
8938°
<vbvr-h3>
Aplikacje obsługujące tagi ModelTrends pozwalają uruchamiać/instalować modele, kopiując ten kod do swojego promptu bez żadnej konfiguracji. Szukaj naszej ikony w aplikacjach, które to wspierają, jak Prism (poniżej).
Uruchom model
Oferty / Reklamy

Easy Creator (Prism) Web
Nielimitowane · stała opłata
Najlepsze dla początkujących. Potężne procesy, niska krzywa nauki.

PirateDiffusion Telegram
Nielimitowane · stała opłata
Twórz filmy, obrazy, niestandardowe postacie do czatu i więcej.

Pro studio (SpyGlass) Web
Nielimitowane · stała opłata
Przeglądaj modele, renderuj i poprawiaj z dowolnej przeglądarki lub telefonu.

Discord bot (Vector)
Nielimitowane · stała opłata
Dodaj Vector do swojego serwera lub dołącz do Vector Discord. Twórz wszystko!

Unified Editor Web
Nielimitowane · stała opłata
Edytor obrazów i wideo: renderuj, edytuj, powiększaj i więcej na jednej stronie.

Civitai Web
Płać za użycie
Generuj na stronie Civitai; każda grafika płatna kredytami Buzz.

Aplikacje lokalne Lokalnie
Wymaga konfiguracji
Zainstaluj programy lokalnie, jeśli masz wystarczająco mocny komputer.

ModelDuel Web
Płać za użycie
Generuj ten sam prompt na maksymalnie 50 modelach checkpoint/podstawowych jednocześnie.

By - MisticRain69 Motion improver for H3
Notatki twórcy
This was the first VBVR lora trained for LTX 2.3 and H3
You can make money with my models. Sell what you generate, use it in paid work, run it on paid services, merge it, sell the merge all of it, no permission needed. Credit is appreciated but never required. New releases might have a short early access window behind Buzz, then go free and free is permanent. Once a model is free, I will never re-paywall it or pull it for a paid platform, and you're welcome to mirror, archive, and rehost it so it stays free no matter what happens to any one site.
Feel free to mirror any of my loras to HuggingFace
The H3 VBVR Pro version was trained on 1k videos from the VBVR Pro SFT dataset and with a rank of 16 instead of 8. You should see a noticeable improvement vs the previous version. Experiment with the strength of the lora since everyone's workflow and lora stack differs. I used a strength of 1.0 for the example video. If you use it with 10eros max beta 5 drop the strength to 0.5 to begin with or else the effect is too strong.
The H3 version was trained on around ~400 videos and It seems H3 does not need a high rank for this type of lora so it was trained with a rank of 8. You should notice a nice bump in prompt following. The generated video also used my unreleased MisticNSFW lora which I am still testing. For better NSFW in general with H3 probably use one of the AIO NSFW loras in the meantime while I am testing MisticNSFW H3. Don't want to post it until its ready so you don't get subpar gens. It is looking good so far though. The VBVR lora works on non NSFW as well the same as it does on NSFW. I use the lora at a strength of 1.0 but experiment like usual for the best results. The lora was trained for I2V, T2V I have not tested.
V4 has been trained on Sulphur 2 Base and was trained on 7000 videos with rank increased to 128 to give it more capacity to be able to improve prompt following. Using the distilled 1.1 lora at a strength of 0.5 in wan2gp you can crank steps all the way to 50 which can improve quality of gens. Not required though like it was not required in V3 or below but a nice option to maximize quality if you want. I usually do 10-12 steps. Videos are generated using 10eros since its the version of Sulphur optimized for i2v.
Wall of text with a bunch of info below
V3 has been optimized for motion. Expect noticeably livelier, more dynamic movement compared to previous versions. I generated the example videos using the int8/fp8 distilled model using 8 steps in wan2gp. For on site generation the dev model has been reported to be broken, if using on site gen try the distilled one instead! I can highly recommend LTX 2.3 Sulphur 2 base if you are using comfyui and if your using wan2gp use the Sulphur 2 base rank 768 lora
What changed in V3: Attention-only layers. The feedforward layers have been stripped, leaving only the attention weights. It seems like the prompt following and reasoning behavior most likely live in the attention layers, while the feedforward layers were potentially interfering with natural motion, likely by over-learning features like textures and style from the training data.
Better motion, smaller file size.
A LoRA that improves prompt following, temporal consistency, and motion "precision" for LTX 2.3. Reduces the floaty, drifty motion that LTX tends to add to scenes. Things that should move, move with purpose. Things that shouldn't move, move less. Also works on non-NSFW, non-Furry, realistic, animated etc. It responds well to detailed prompts.
In comfyui or wan2gp lowering image strength to 0.85 can improve motion in general if you want more motion
Feedback and A-B comparisons welcome. V2 and V1 was trained on 4800 videos.
Recommended to run at strength 1.0-0.7 but experiment to find what works best for your setup. If you want stronger prompt adherence try strength 1.5-2.0. I have noticed the only side effect I have gotten from a high strength is the video looking like its 16fps. I have not seen the choppiness issues on i2v unless the lora is cranked to 1.5-2.0 so it may be a t2v thing.
Prompting tips in non-nsfw terms so its less confusing just adapt it to nsfw:
Be specific and literal. Describe what happens, in what order, step by step.
Instead of "a ball bouncing around" → "A red ball moves to the right, bounces off the wall, and returns to the center"
Instead of "fluid pouring" → "Water flows from the left container through the connecting tube into the right container until both levels are equal"
Describe the starting state, the action, and the end state
The LoRA follows prompts more literally than base LTX — precise prompts will give much better results
How was it made?
v0.1 and v0.2 were trained on 360 videos from the VBVR (Very Big Video Reasoning) dataset synthetic task videos where every motion is precise and intentional. No concept bleed, no style change, just tighter control.
Based on the paper which demonstrated this approach on Wan 2.2. I noticed that lora helped prompt following and temporal consistency a ton with wan so I trained this for LTX, and now H3.
What does it actually do?
Prompt following is more faithful — the model does more of what you asked instead of improvising
Motion is more deliberate and less erratic
Reduces random drift and wobble in scenes
Temporal consistency improved — actions follow logical sequences
What it doesn't do:
Doesn't change visual style
Doesn't add or remove capabilities LTX OR H3 doesn't already have
Not a motion LoRA — stacks with motion LoRA's
Training details for v0.1 and v0.2 (if you give a shit)
Rank 32
360 VBVR synthetic videos at 512x512, 81 frames <------Alot less than 1 million but still a shitload to train on this is very slow to train locally.
LR 1e-4, adamw8bit
Training details for V1
Training videos were increased to 4800
Resolution is the same but frames were increased to 121
Every other setting the same as v0.1 and v0.2
More training data from the VBVR dataset was
SHA256
9C20EFA6D207F1A843443B741A2F6BC0D1993F938CEF743E7E8A250D62BAA1E0
Trend popularności: H3 LTX 2.3 I2V T2V Video Reasoning lora VBVR H3 VBVR Pro
Wynik heat od 7 Sep 2026
Wskaźnik popularności
8,938°
Ten tydzień
▲
7.7%
8,923° wtedy, 8,938° teraz
Ten miesiąc
▲
64.5%
8,838° wtedy, 8,938° teraz
Ostatni rok
n/a
Jeszcze nie wydano/śledzono
7,000°
Podstawa
Skala idzie od 0° do 9 999°. Wszystko poniżej 7,000° jest zarezerwowane dla modeli, o których żadne źródło jeszcze nie raportuje, które mają tam zastępczą wartość, by listy były kompletne. 7,000° to punkt startowy dla danych pomiarowych: model z prawdziwymi danymi, ale prawie bez pobrań, stoi na tej podstawie, a pomiary wypełniają stopnie powyżej niej. Podstawa nic nie mówi o modelu; to stopnie powyżej niej robią różnicę i to one rozróżniają modele.
+1,261°
Pobrania z Civitai
13,624 pobrań tej dokładnej wersji na Civitai. Pobrania to najważniejszy składnik i liczone są na skali logarytmicznej: dziesięciokrotny wzrost pobrań dodaje te same 300°, więc model z milionem pobrań nie jest tysiąc razy gorętszy niż ten z tysiącem. Sześć źródeł pobrań dzieli ten jeden termin proporcjonalnie do ich liczby.
+415°
Polubienia
585 polubień i kciuków w górę ze wszystkich źródeł. Polubienie waży połowę pobrania, na tej samej skali logarytmicznej.
+162°
Tempo adopcji
Około 142 pobrań dziennie, mierzone między dwoma odczytami źródeł, nigdy nie szacowane na podstawie średniej z całego czasu. Prędkość waży ćwierć składnika pobrań, więc świeży wzrost jest widoczny, ale jednodniowy skok nie przebije lat użycia.
+100°
Bonus rodzinny
+100° bo to LoRA z rodziny, którą ta strona teraz promuje. To ograniczony bonus w wyniku i jest tu jawnie pokazany; nigdy nie ukryje modelu ani nie zrównoważy różnicy w pobraniach rzędu tysiąca razy.
Pokaż szczegóły
Każdą liczbę na tej stronie można sprawdzić. Wynik popularności tego modelu to 8,938°, a tutaj jest zbudowany krok po kroku, z bieżącym sumowaniem po każdym składniku: podstawa, stopnie dodawane przez każde źródło, bonus za rodzaj modelu oraz odejmowanie za wiek wag. Kolory odpowiadają zakresom na wykresie powyżej. Na końcu znajduje się słownik, który wyjaśnia każde pojęcie.
- 1Zacznij od podstawy.Dlaczego 7,000°, a nie zero: skala idzie od 0° do 9 999°, a część poniżej 7,000° jest zarezerwowana dla modeli, o których żadne źródło jeszcze nie raportuje, które mają tam zastępczą wartość, by listy były kompletne i nigdy nie wyprzedzały modeli z danymi. 7,000° to punkt startowy dla danych pomiarowych. Model z prawdziwymi danymi, ale prawie bez pobrań, stoi tutaj; wszystko co dalej to pomiary, a przestrzeń powyżej podstawy mieści dziesięć dziesięciokrotnych kroków w pobraniach po 300° każdy. Podstawa jest taka sama dla każdego modelu, więc nic nie decyduje; decydują stopnie powyżej niej.7,000°bieżąca suma
- 2Dodaj pobrania.13,624 równoważników pobrań łącznie, z Pobrania z Civitai. Dziesięć razy więcej pobrań dodaje ten sam 300°, więc rozmiar ma znaczenie, ale nigdy nie dominuje wyniku.+1,261°8,261°bieżąca suma
- 3Dodaj polubienia.585 polubień i kciuków w górę, o połowę mniej wartości niż pobranie.+415°8,676°bieżąca suma
- 4Dodaj tempo adopcji.Około 142 pobrań dziennie teraz, mierzone między dwoma odczytami, z wagą ćwierć pobrania.+162°8,838°bieżąca suma
- 5Wzmocnienie rodziny.Otwarte, ograniczone wsparcie dla LoRA z rodziny, którą ta strona teraz promuje.+100°8,938°bieżąca suma
- =Wynik heat.Pozycja tego modelu na każdej liście na tej stronie. Nic innego tego nie zmienia.8,938°
Słowniczek: używane tu terminy
- Wynik heat
- Jedna liczba pokazująca, jak bardzo model jest używany i pożądany teraz, od 0° do 9,999°. Każda lista na tej stronie z napisem hottest jest sortowana według tego i niczego innego.
- Podstawa
- 7,000° to punkt startowy dla każdego modelu z prawdziwymi danymi. Skala idzie od 0° do 9,999°; część poniżej podstawy jest zarezerwowana dla zastępczych modeli (bez danych), żeby model z danymi zawsze był wyżej. Podstawa jest taka sama dla wszystkich i nic nie decyduje; stopnie powyżej niej to właściwy pomiar.
- Równoważniki pobrań
- Wszystko, co wynik traktuje jak pobranie, zsumowane: same pobrania, każdy seeder torrenta jako 1,000, każde AI Horde zdjęcie i każde uruchomienie na stronie generującej jako jedno.
- Skala logarytmiczna
- Liczenie co dziesięć, nie co jeden: przejście z 1,000 do 10,000 pobrań dodaje tyle samo stopni, co z 10,000 do 100,000. Zapobiega to dominacji gigantów nad resztą.
- Polubienia
- Kciuki w górę i polubienia ze wszystkich źródeł, warte połowę pobrania na skali logarytmicznej.
- Tempo adopcji
- Ile pobrań dziennie model ma teraz, na podstawie różnicy między dwoma odczytami źródła. Ćwierć wagi terminu pobrania.
- Zmierzony i szacowany
- Zmierzony oznacza, że istnieją dwa odczyty źródła i różnica jest rzeczywista. Szacowany oznacza, że znana jest tylko dzisiejsza suma, a przeszłość jest rozłożona na czas życia modelu; strona mówi, który z nich pokazuje.
- Seeder
- Ktoś, kto trzyma kopię wag online, aby inni mogli je pobrać przez torrent, albo hostowany mirror robiący to samo. Każdy taki liczy się jako 1 000 pobrań.
- AI Horde
- Sieć wolontariuszy, która generuje obrazy za darmo na komputerach darczyńców. Liczba obrazów wygenerowanych z modelem jest publiczna i każde liczy się jako jedno pobranie.
- Strony generujące
- Strony, które mają własne kopie modelu i pozwalają ludziom generować z nim obrazy, takie jak PixAI, SeaArt i Yodayo. Ich pobrania liczą się jak na Civitai, a każde uruchomienie generowania to jedno pobranie.
- Tokeny OpenRouter
- Model tekstowy obsługiwany przez API, taki jak Claude czy GPT, nie ma wag do pobrania, więc jego użycie mierzy się tokenami: fragmentami tekstu, które przeczytał i napisał przez OpenRouter, bramkę używaną przez wiele aplikacji, w ciągu ostatnich 30 dni. Każde 10,000,000 tokenów liczy się jako jedno pobranie. Źródło: OpenRouter (openrouter.ai/rankings), CC BY 4.0.
- Pełny model (checkpoint)
- Same wagi, plik, który generuje samodzielnie. Dostaje bonus, bo dodatki od niego zależą.
- LoRA i embedding
- Małe pliki dodatków, które kierują czyjeś wagi w stronę stylu, postaci lub koncepcji. Nie mogą działać samodzielnie.
- Rodzina i wagi
- Podstawa, na której zbudowano model, np. SD 1.5, SDXL, Flux lub Wan. Każdy model dziedziczy datę wydania wag swojej rodziny.
- Wiek
- Stopnie odejmowane za to, jak dawno wyszły wagi rodziny: 150° za rok, do 750°. Zachowuje stare pobrania, które miały lata na narastanie, zamrażając szczyt listy.
- Wzmocnienie rodziny
- Małe, ograniczone wsparcie dla LoRA z rodziny, którą ta strona teraz promuje, zawsze podane w rozbiciu.
- Wynik zastępczy
- Stabilna liczba poniżej minimum, przyznawana modelowi, o którym jeszcze nie ma danych źródłowych, żeby listy były kompletne. Nigdy nie jest wyżej niż model z danymi.
- Nowy! (okres karencji)
- Model młodszy niż 7 dni pokazuje Nowy! zamiast wyniku i nie zajmuje miejsca w rankingu. Jego wynik jest liczony od pierwszego dnia, ale model jednodniowy rośnie najszybciej, więc bez oczekiwania #1 tygodnia byłby zawsze tym, który pojawił się wczoraj, a nie tym, który utrzymał się przez tydzień.
- Trend
- Jak wzrost modelu w danym okresie wypada na tle typowego wzrostu modelu w tym samym czasie. Szybszy niż zwykle to wzrost, wolniejszy to spadek.
- Typowy model
- Środek katalogu: połowa modeli z danymi rosła szybciej w tym okresie, połowa wolniej.
Jak popularność tego modelu zmieniała się w porównaniu do reszty katalogu: jego wzrost w pobraniach, polubieniach i użyciu w każdym okresie, mierzony względem typowego wzrostu modelu w tym samym czasie, wraz z jego wynikiem heat score. Powyżej typowego wzrostu oznacza wzrost, poniżej spadek. Przeszłość jest odtwarzana na podstawie dzisiejszych sum, pierwszego dnia modelu i zmierzonej prędkości pobrań, jeśli są dwa odczyty; model, który nie istniał na początku okresu, pokazuje n/d.
Przykładowe rendery
Prompty i ustawienia udostępnione przez osoby, które wykonały te rendery na Civitai. Wybierz render, aby zobaczyć, jak powstał.
Ustawienia
Kroki
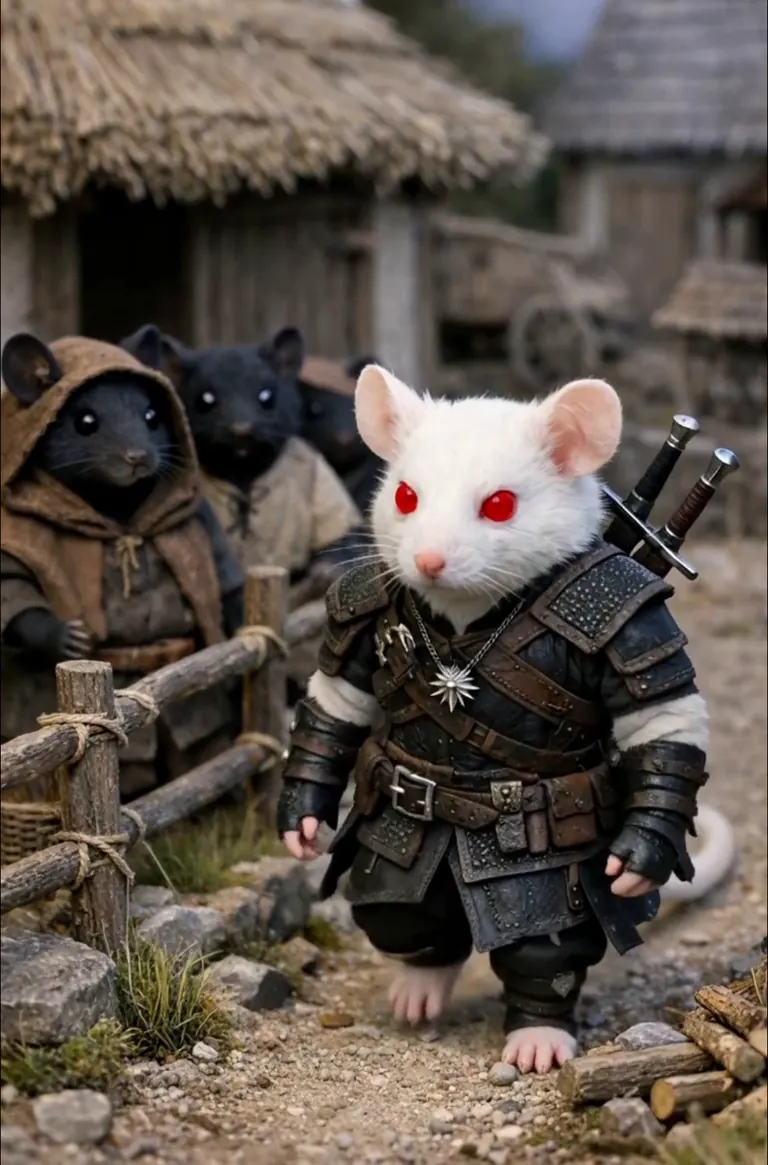
8
Rozmiar
1080x1640
Prompt
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced.
integrated_multimodal_description: [Shot 1] Stop-motion, photographed as practical puppets with a slight frame-by-frame jerk. The camera is static. The white mouse in dark armor is already walking and takes slow steps along the path until he leaves the frame on the right. The two swords, the medallion and the armor stay the same. Behind the fence the hooded mice are already looking at him. The hooded mouse in front (S1), a small raspy male voice, says: <d>[English] That's the Witcher! Look at his eyes!</d> His mouth moves with the words. The speech bubble printed on the reference picture is not in the shot. No letters and no caption appear anywhere in the frame.
overall_soundscape: Grit crunches under slow puppet steps. A fence post ticks. Village air, no music under the line.
non_diegetic_music: N/A
Ustawienia
Rozmiar
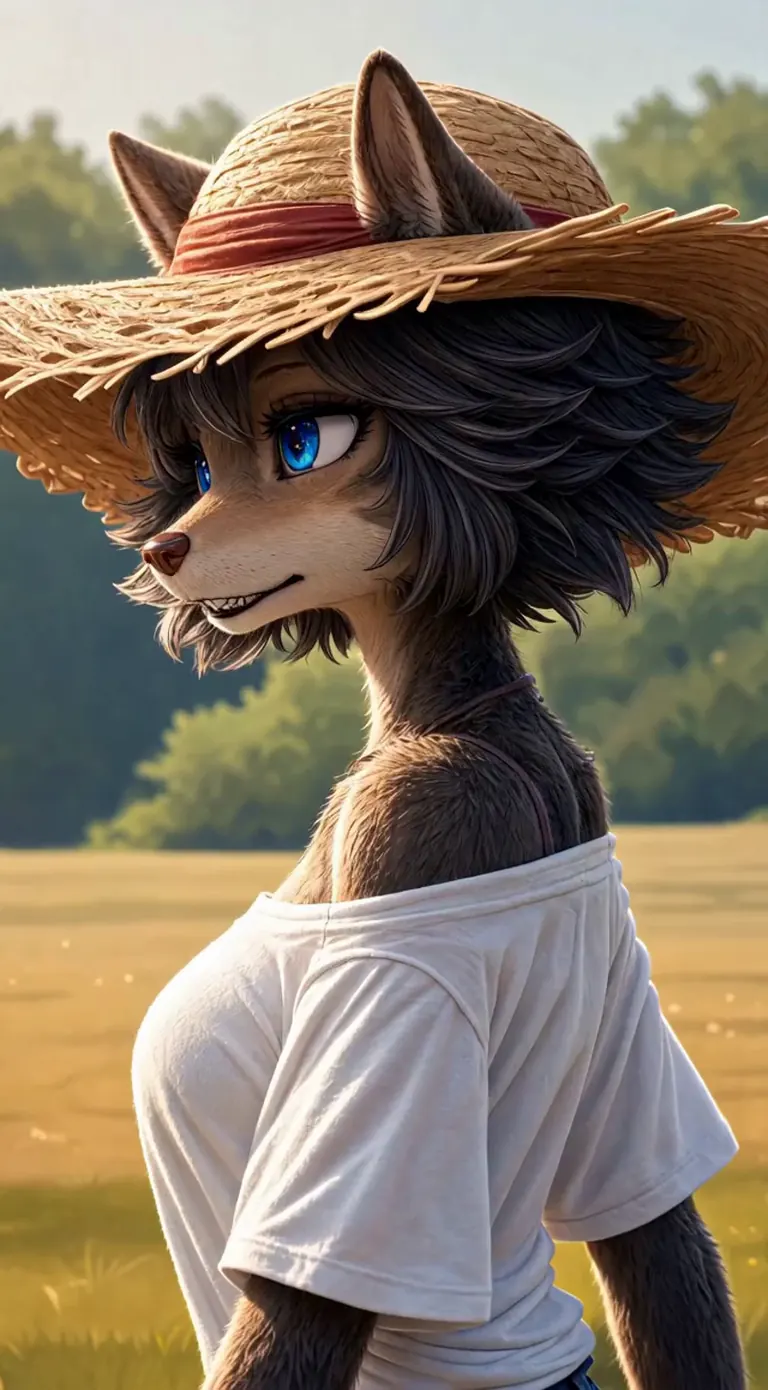
672x1216
Prompt
subject_definitions:
<Subject 1> is the anthropomorphic wolf woman defined by <Picture 1> — grey‑brown fur, short dark hair, blue eyes, pointed ears, white off‑shoulder t‑shirt. In [Shot 2] she also wears blue jeans and the straw hat with the red band, securely placed on her head.
summary:
[reference generation] <Subject 1> breathes in the opening medium shot, then walks away through an already knee‑high golden field in a dreamlike handheld back view, the hat remaining firmly on her head throughout.
detailed_description:
[Shot 1] Cinematic handheld film photography, camera shakes slightly. Medium shot of <Subject 1> in three‑quarter profile as in <Picture 1>, body facing left. The field, grass length, trees and sky stay exactly as already visible in <Picture 1>. The grass does not grow. Her eyes are closed. She draws one long slow breath in, chest rising, then exhales. Light wind moves fur on her neck.
[Shot 2] At 00:05.200, the camera cuts to a dreamlike back view of <Subject 1> already standing in an existing knee‑high golden field. Handheld, shakes slightly, lens low so out‑of‑focus grass stalks occupy the bottom of the frame. Warm late‑sun backlight, long lens haze, gentle flare, air looking like a half‑remembered dream. She wears the same white off‑shoulder t‑shirt and blue jeans. The straw hat with the red band sits steadily on her head, unaffected by the light breeze. A long grey‑brown wolf tail hangs behind her over the jeans and sways with each slow step; the tail is already there when the shot opens. The already knee‑high grass hides her lower legs and paws for the entire shot; the grass does not grow. She walks slowly away from the camera, one unhurried step at a time, turning her head left then right as if taking the field in. Foreground stalks drift across the lens. No bare legs. No extra people. No readable text.
overall_soundscape:
Soft open‑field wind. One slow inhale, then a longer exhale. Gentle rustling of the straw hat as she moves, but no sound of it coming off. After the cut, denim and already knee‑high grass brushing her legs, a low breeze, distant insects. No voices.
non_diegetic_music:
N/A
Ustawienia
Sampler
Euler
Kroki
6
Guidance
1
Rozmiar
1600x2176
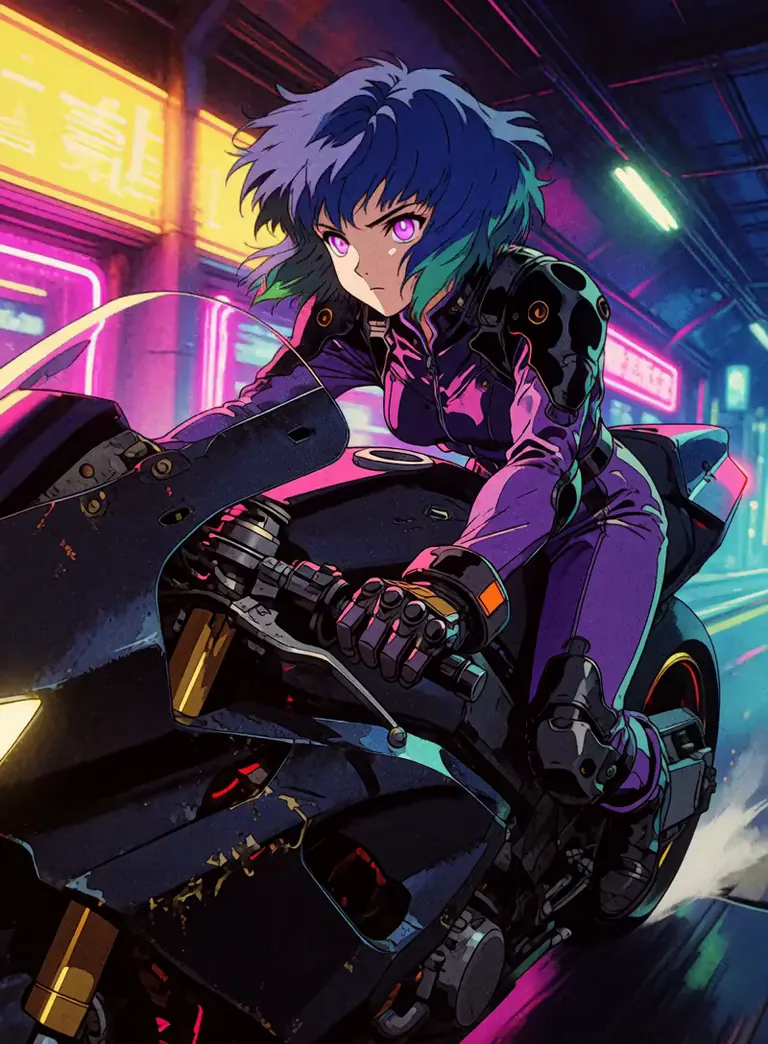
Prompt
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced.
integrated_multimodal_description:
[Shot 1] Cinematic, high-quality two-dimensional animated movie, in a Japanese animation style, 1990s style cyberpunk anime similar to Ghost in the Shell. The target video is rendered at 15 frames per second for a choppy traditional animation effect. Tracking shot. At 00:00.000, an anime woman is riding a motorcycle through a tunnel lit by bright neon lights. The lights flash by, illuminating the woman and the motorcycle as she speeds through the the tunnel with her hair whipping. At 00:05.000, she looks behind her as a retro-futuristic military hovercraft with a large central gun and box-like rocket pods with multiple rows strapped to the sides of the turret starts to gain on her. The motorcycle and hovercraft are the only two vehicles in the tunnel. She begins to maneuver the bike, weaving left and right, as the hovercraft fires a rocket at her from one of the pods. The rocket hits the ground and explodes behind her, kicking up debris, fire, smoke, and dust. She drives through the cloud of smoke as the camera pushes in on her face.
overall_soundscape:
The roar and revving of the motorcycle engine as she speeds through traffic. The sound of an explosion.
non_diegetic_music:
High-adrenaline 1990s cyberpunk anime chase scene score, non-diegetic. Frantic 160-BPM breakbeats combined with driving, aggressive industrial synth bass. Sharp Yamaha DX7 digital synth leads and tense, sweeping atmospheric pads. Retro-futuristic electronic, gritty, cinematic, intense, fast-paced, high stakes
Ustawienia
Sampler
Euler
Kroki
6
Guidance
1
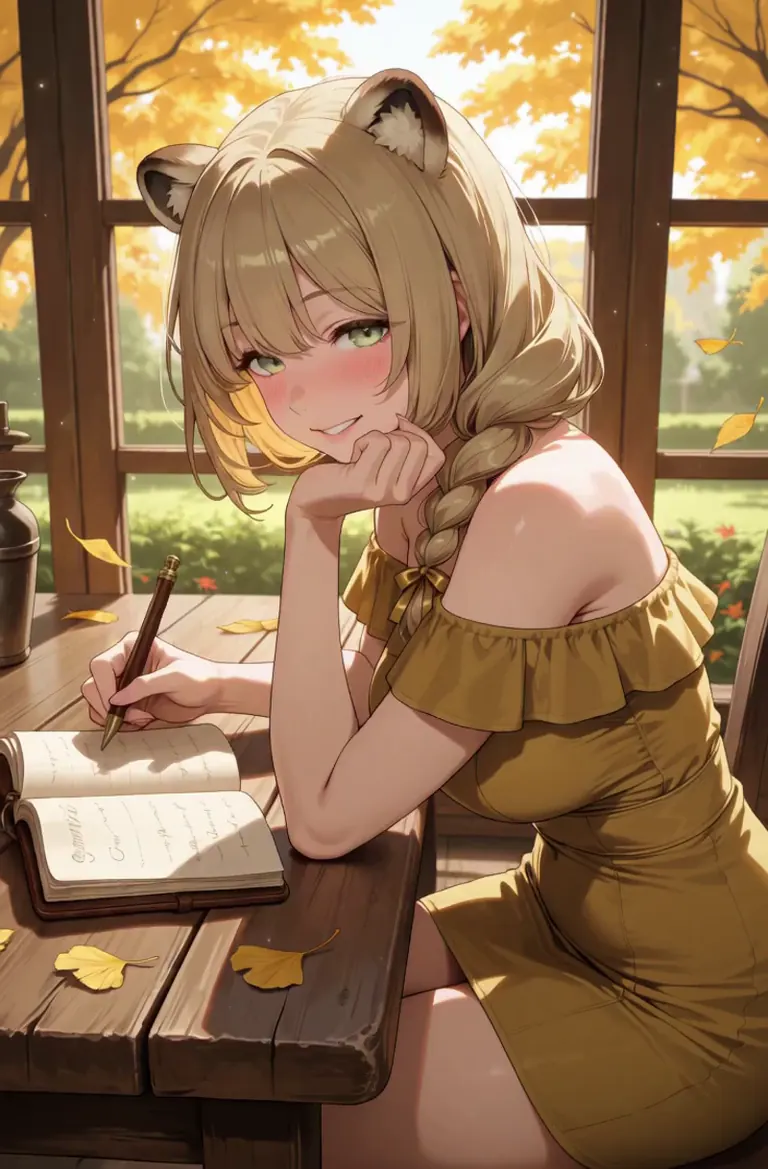
Rozmiar
736x1120
Prompt
subject_definitions:
<Subject 1> is the female character from <Picture 1>. A young woman sitting at a desk, writing in a book.
summary:
[reference generation] A cinematic two-dimensional western-style animation video.
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced.
detailed_description:
The target video is cinematic two-dimensional western-style animation video. Cel-shaded style at 15 fps for choppy, traditional animation pacing.
[Shot 1] First-person, POV. At 00:00.000, <Subject 1> is sitting at a desk, holding a pen and writing in a book. She has her head in her hand and is smiling gently at the viewer. The viewer walks up to her; she looks at the viewer and with a cute, feminine voice, she says: <d>[English]Man, I've got some awful writers block today.</d>. The viewer reaches out and puts a single hand on her head between her ears. He gently strokes the top of her head. <Subject 1> closes her eyes and her mouth, tilting her head up towards the viewer. With a gentle masculine voice, the off-screen viewer says: <d>[English] It's okay hun. How about you take a break for a bit?</d>
overall_soundscape:
The soft footsteps of the viewer as he approaches.
non_diegetic_music:
Instrumental, lo-fi chillhop, relaxed tempo, warm vintage vinyl crackle, soft Rhodes electric piano chords, smooth deep bassline, laid-back syncopated hip-hop drum beat, ambient coffee shop atmosphere, mellow saxophone accents, non-diegetic background music, trendy, cozy, high fidelity, continuous groove.
Ustawienia
Sampler
Euler
Kroki
6
Guidance
1
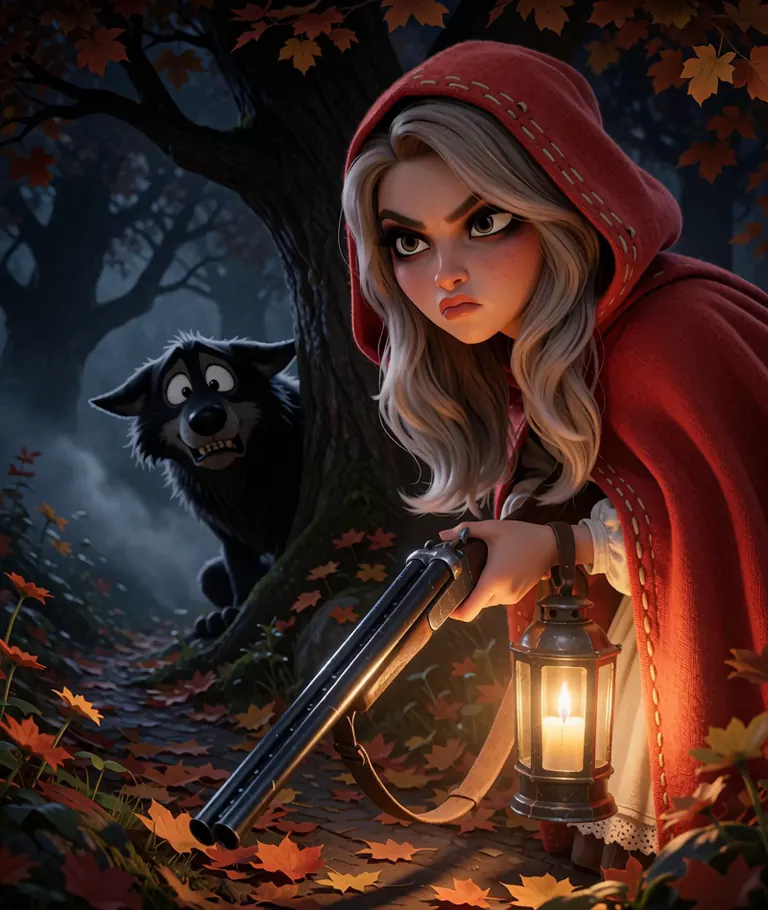
Rozmiar
1728x2048
Prompt
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced.
integrated_multimodal_description:
[Shot 1] Cinematic, high-quality three-dimensional computer generated movie. Static shot. At 00:00.000, the blonde woman wearing a red hood is holding a shotgun in her hands, scanning the area ahead of her with narrowed eyes. With a quiet voice with a sing-song tone, she says:<d>[English]Come here, little wolfie.</d> A cartoonish wolf is peeking around a tree in the background. At 04:00.000, the woman hears a twig snap. The wolf's eyes widen in panic and he quickly hides behind the tree. The woman's head snaps around to look at the tree, but the wolf is already hiding. She slowly turns back around and continues looking around ahead of her. The wolf slowly peeks around the tree again.
overall_soundscape:
N/A
non_diegetic_music:
Light-hearted comedic jazz, sneaking upright bass, tiptoeing piano, muted trumpet, playful, mischievous cartoon background music, upbeat.
Ustawienia
Rozmiar
1080x1920
Prompt
boom
Do tego renderu nie udostępniono promptu.
Do tego renderu nie udostępniono promptu.
Uruchom lokalnie
Jak zainstalować
Jak zainstalować LoRA: foldery, sprawdzanie plików i pierwsze użycie w ComfyUI, Forge, Automatic1111 i Draw Things
24 Wrz 2025
H3_VBVR_Pro_attn_only.safetensors
Pobieranie obsługuje Civitai. Niektórzy twórcy wymagają najpierw zalogowania się na Civitai.
H3 LTX 2.3 I2V T2V Video Reasoning lora VBVR H3 VBVR Pro to LoRA z rodziny MiniMax H3 wymieniony na ModelTrends.ai, katalogu tylko do odczytu otwartych modeli AI do obrazów, wideo i tekstu. Porównaj go z innymi modelami MiniMax H3, sprawdź wynik popularności, aby zobaczyć trend, i otwórz na PirateDiffusion lub BitVector, aby wypróbować.
Przeglądaj według rodziny modeli
Modele Text / LLM
434
Modele Anima
528
Modele Chroma
19

Modele Fibo
2
Modele Flux
1,496
Modele Flux 2 / Klein
1,239

Modele Flux 3
3

Modele Moss
3

Modele Iris
1
Modele MiniMax H3
364
Modele Hunyuan
204
Modele Ideogram
20
Modele Krea2
717

Modele Qwen
20
Modele Qwen2
47
Modele Ltx2
153