animagine31 xl
Bandingkan
8849°
Jalankan secara tempatan
animagineXLV31_v31.safetensors
6.46 GB · SafeTensor · fp16 · full
sdxl_vae.safetensors
319 MB · SafeTensor
Muat turun disediakan oleh Civitai. Sesetengah pencipta memerlukan log masuk Civitai dahulu.


Tentang model ini
STABLE DIFFUSION XL 1.0 · Model asas
Nota pencipta
Animagine XL 3.1 is an update in the Animagine XL V3 series, enhancing the previous version, Animagine XL 3.0. This open-source, anime-themed text-to-image model has been improved for generating anime-style images with higher quality. It includes a broader range of characters from well-known anime series, an optimized dataset, and new aesthetic tags for better image creation. Built on Stable Diffusion XL, Animagine XL 3.1 aims to be a valuable resource for anime fans, artists, and content creators by producing accurate and detailed representations of anime characters.
Model Details
-
Developed by:
-
In collaboration with:
-
Model type: Diffusion-based text-to-image generative model
-
Model Description: Animagine XL 3.1 generates high-quality anime images from textual prompts. It boasts enhanced hand anatomy, improved concept understanding, and advanced prompt interpretation.
-
License:
-
Fine-tuned from:
Usage Guidelines
Tag Ordering
For optimal results, it's recommended to follow the structured prompt template because we train the model like this:
1girl/1boy, character name, from what series, everything else in any order.
Special Tags
Animagine XL 3.1 utilizes special tags to steer the result toward quality, rating, creation date and aesthetic. While the model can generate images without these tags, using them can help achieve better results.
Quality Modifiers
Quality tags now consider both scores and post ratings to ensure a balanced quality distribution. We've refined labels for greater clarity, such as changing 'high quality' to 'great quality'.
Quality Modifier Score Criterion
masterpiece > 95%
best quality > 85% & ≤ 95%
great quality > 75% & ≤ 85%
good quality > 50% & ≤ 75%
normal quality > 25% & ≤ 50%
low quality > 10% & ≤ 25%
worst quality ≤ 10%
Rating Modifiers
We've also streamlined our rating tags for simplicity and clarity, aiming to establish global rules that can be applied across different models. For example, the tag 'rating: general' is now simply 'general', and 'rating: sensitive' has been condensed to 'sensitive'.
Rating Modifier Rating Criterion
safe General
sensitive Sensitive
nsfw Questionable
explicit, nsfw Explicit
Year Modifier
We've also redefined the year range to steer results towards specific modern or vintage anime art styles more accurately. This update simplifies the range, focusing on relevance to current and past eras.
Year Tag Year Range
newest 2021 to 2024
recent 2018 to 2020
mid 2015 to 2017
early 2011 to 2014
oldest 2005 to 2010
Aesthetic Tags
We've enhanced our tagging system with aesthetic tags to refine content categorization based on visual appeal. These tags are derived from evaluations made by a specialized ViT (Vision Transformer) image classification model, specifically trained on anime data. For this purpose, we utilized the model , which assesses the aesthetic value of content before it undergoes training. This ensures that each piece of content is not only relevant and accurate but also visually appealing.
Aesthetic Tag Score Range
very aesthetic > 0.71
aesthetic > 0.45 & 0.27 & < 0.45
very displeasing ≤ 0.27
Recommended settings
To guide the model towards generating high-aesthetic images, use negative prompts like:
nsfw, lowres, (bad), text, error, fewer, extra, missing, worst quality, jpeg artifacts, low quality, watermark, unfinished, displeasing, oldest, early, chromatic aberration, signature, extra digits, artistic error, username, scan, [abstract]
For higher quality outcomes, prepend prompts with:
masterpiece, best quality, very aesthetic, absurdres
it’s recommended to use a lower classifier-free guidance (CFG Scale) of around 5-7, sampling steps below 30, and to use Euler Ancestral (Euler a) as a sampler.
Multi Aspect Resolution
This model supports generating images at the following dimensions:
Dimensions Aspect Ratio
1024 x 1024 1:1 Square
1152 x 896 9:7
896 x 1152 7:9
1216 x 832 19:13
832 x 1216 13:19
1344 x 768 7:4 Horizontal
768 x 1344 4:7 Vertical
1536 x 640 12:5 Horizontal
640 x 1536 5:12 Vertical
Acknowledgements
The development and release of Animagine XL 3.1 would not have been possible without the invaluable contributions and support from the following individuals and organizations:
-
: Our collaboration partner and sponsor.
-
: For providing the aesthetic classification model, .
-
: For their custom learning rate scheduler, adapted from .
-
: For their comprehensive training scripts.
-
Cagliostrolab Collaborators: For their dedication to model training, project management, and data curation.
-
Early Testers: For their valuable feedback and quality assurance efforts.
-
NovelAI: For their innovative approach to aesthetic tagging, which served as an inspiration for our implementation.
Thank you all for your support and expertise in pushing the boundaries of anime-style image generation.
Limitations
While Animagine XL 3.1 represents a significant advancement in anime-style image generation, it is important to acknowledge its limitations:
-
Anime-Focused: This model is specifically designed for generating anime-style images and is not suitable for creating realistic photos.
-
Prompt Complexity: This model may not be suitable for users who expect high-quality results from short or simple prompts. The training focus was on concept understanding rather than aesthetic refinement, which may require more detailed and specific prompts to achieve the desired output.
-
Prompt Format: Animagine XL 3.1 is optimized for Danbooru-style tags rather than natural language prompts. For best results, users are encouraged to format their prompts using the appropriate tags and syntax.
-
Anatomy and Hand Rendering: Despite the improvements made in anatomy and hand rendering, there may still be instances where the model produces suboptimal results in these areas.
-
Dataset Size: The dataset used for training Animagine XL 3.1 consists of approximately 870,000 images. When combined with the previous
SHA256
E3C47AEDB06418C6C331443CD89F2B3B3B34B7ED2102A3D4C4408A8D35AAD6B0
ID Model ModelTrends.ai
#9309
Laporkan kandungan
Contoh render
Prompt dan tetapan yang dikongsi oleh orang yang membuat render ini di Civitai. Pilih render untuk melihat cara ia dibuat.
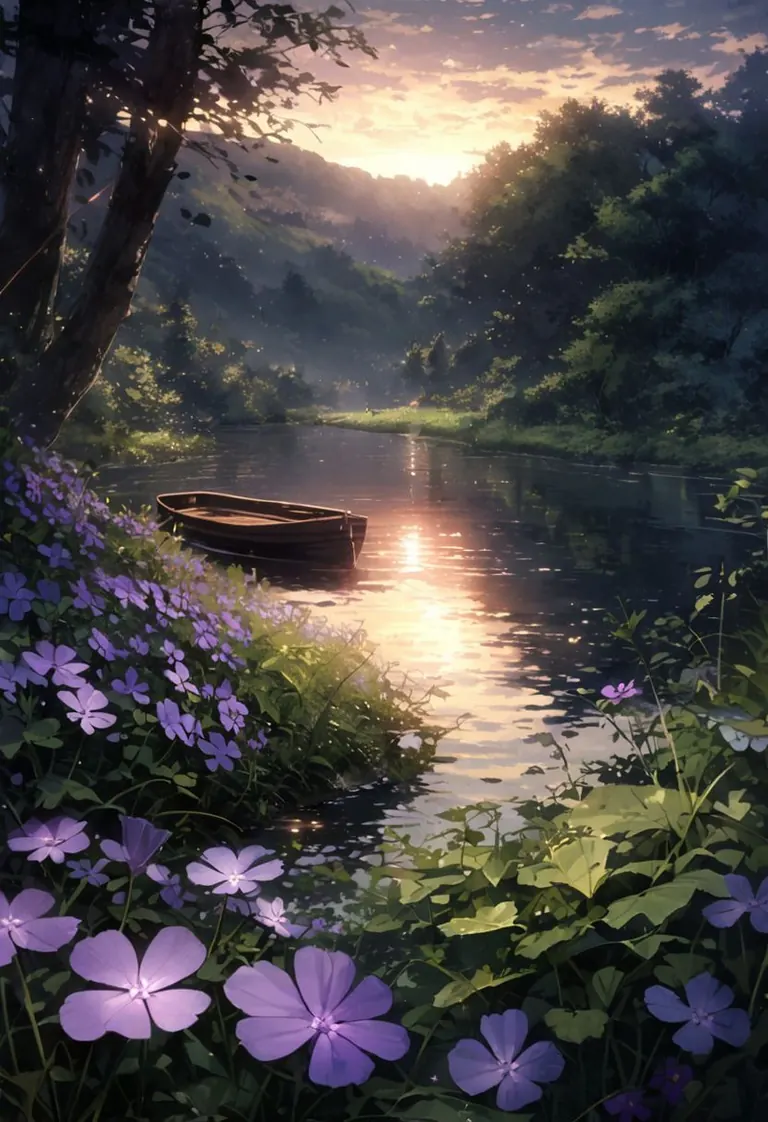
Tetapan
Sampler
DPM++ 2M
Langkah
42
Guidance
7
Seed
958517608
Saiz
832x1216
Clip skip
2
Prompt
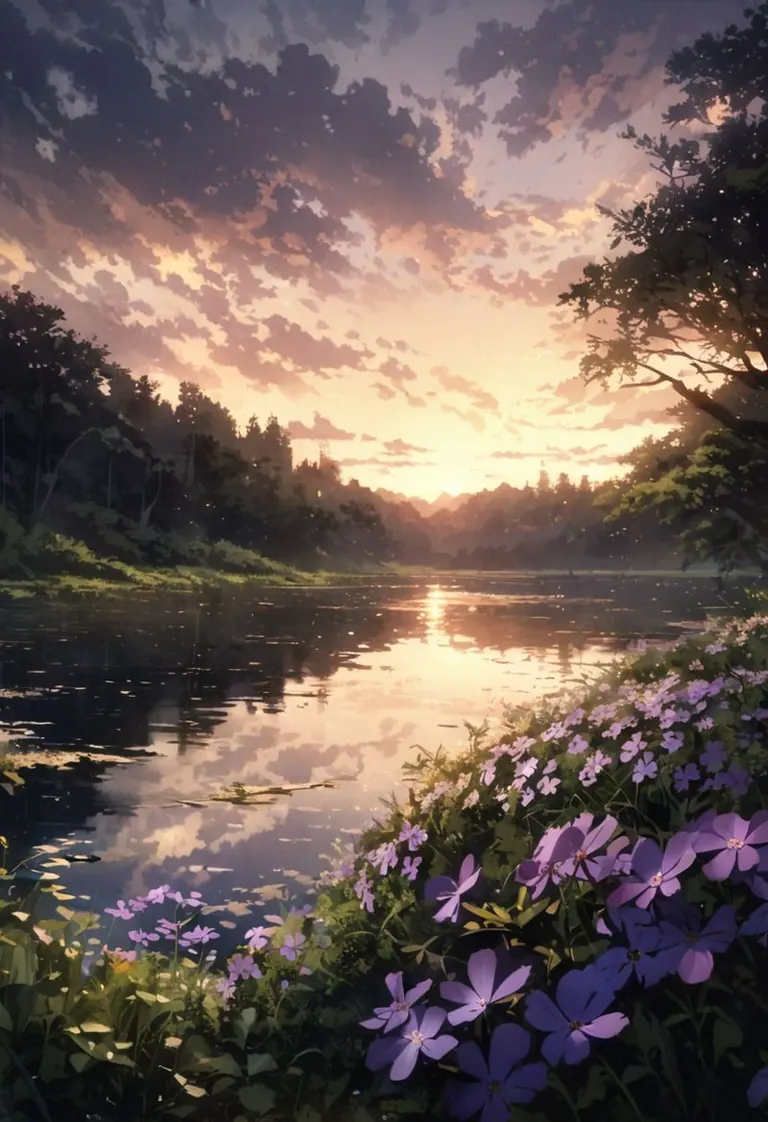
detailed background,( Calm spring night landscape), amongst lush greenery, beautiful view, creeping phlox in full bloom, creeping phlox, early morning, sunrise sky, beautiful clouds, dappled sunlight, outdoor seating, one lamp, Tranquil Lake, Boat on a Lake, depth of field, masterpiece, best quality, ultra-detailed, very aesthetic, illustration, perfect composition, intricate details, absurdres, moody lighting, wisps of light, no humans,
Prompt negatif
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
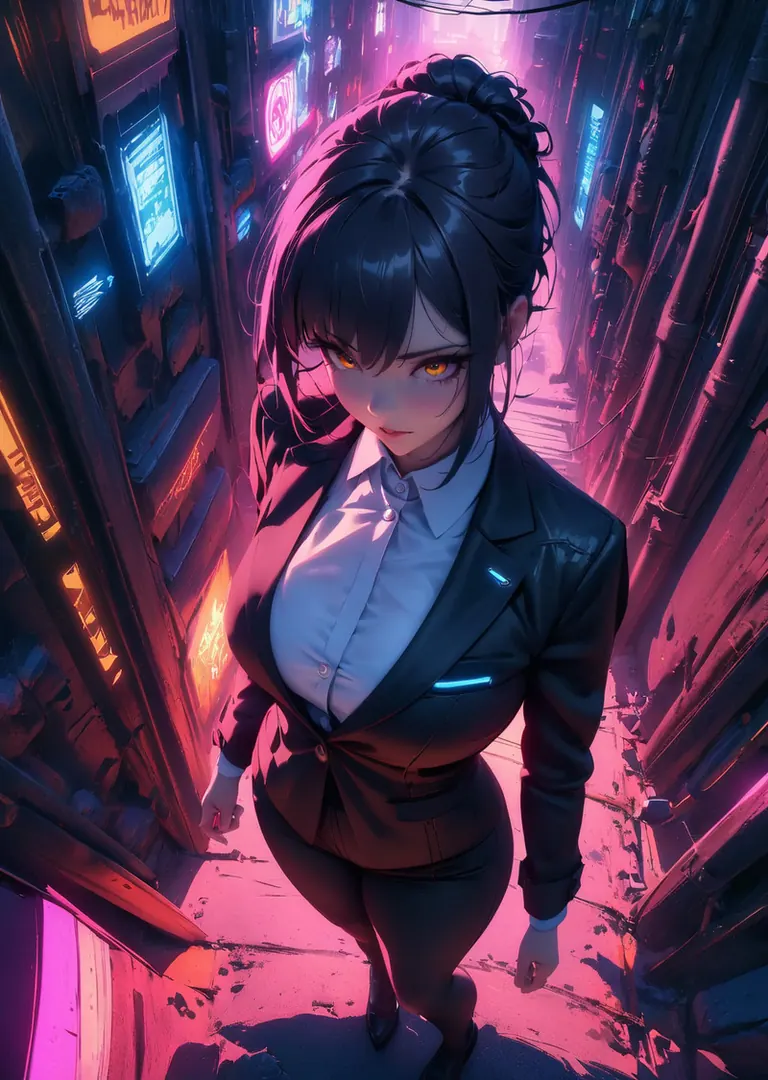
Tetapan
Sampler
Restart
Langkah
25
Guidance
7
Seed
4257785000
Saiz
1024x1440
Prompt
masterpiece, best quality, very aesthetic, absurdres
wlop miimalism
cinematic lighting
1girl, aged up
walking in the alley black suit white collar shirt
perspective from above
cyberpunk, neon
Prompt negatif
lowres, worst quality, blurry, grayscale, low contrast
low quality, worst quality, normal quality
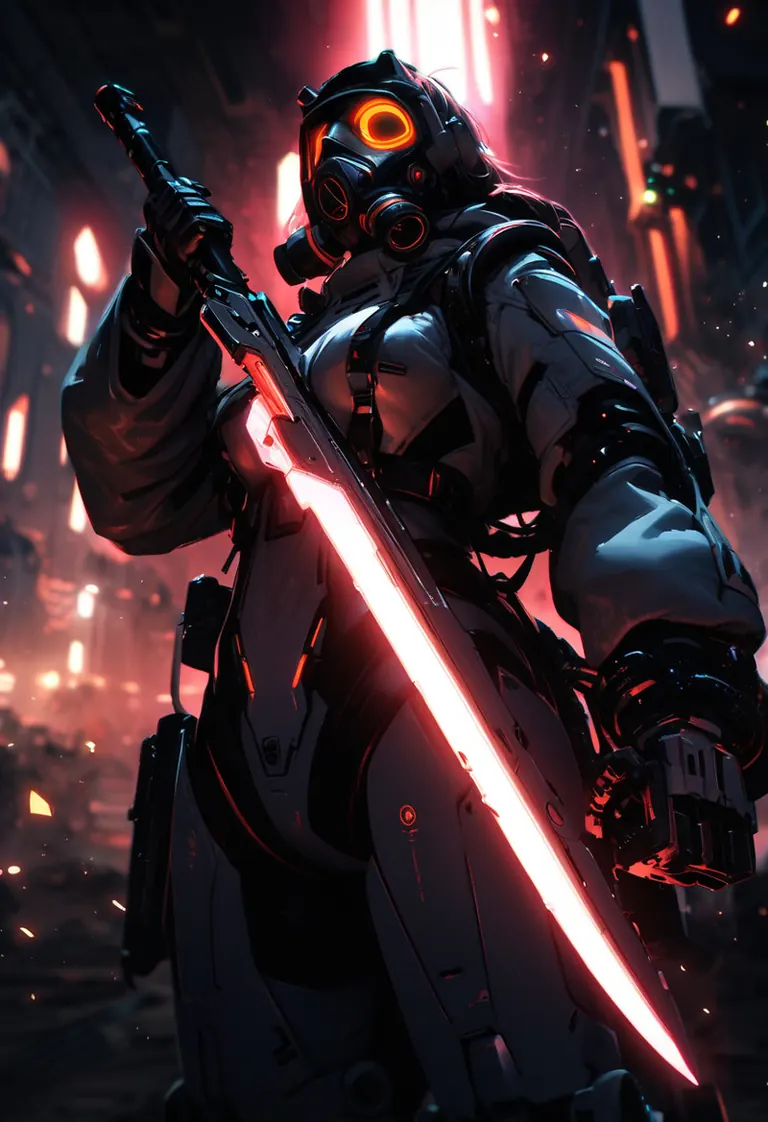
Tetapan
Sampler
DPM++ 2M
Langkah
30
Guidance
6
Seed
585685321
Saiz
832x1216
Clip skip
2
Prompt
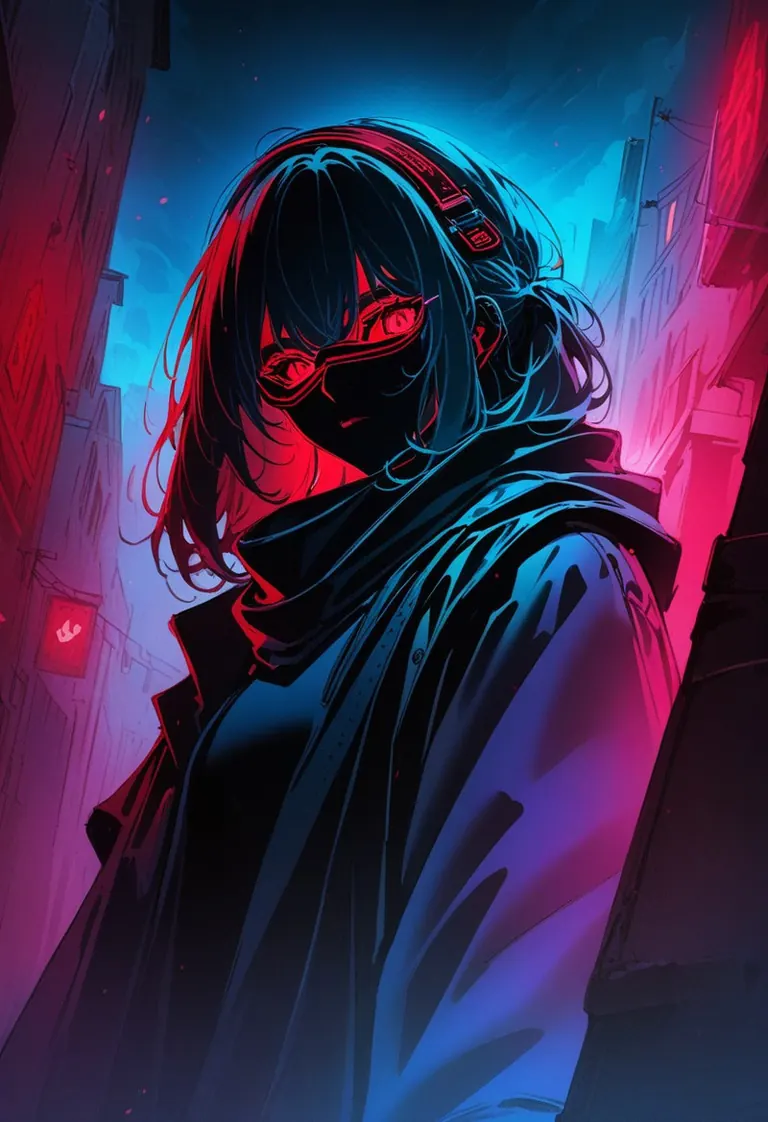
(best quality), future, 1girl, solo, miko motif exoskeleton suit, led, gas mask, holding blade, machinery, digital engraving, ultra highres, absurdres, deep glow effect, hdr, light particles, cinematic lighting, depth of field
Prompt negatif
(worst quality, low quality:1.4), (bad hands, extra fingers:1.3), missing fingers, bad feet, text, watermark, signature, sign
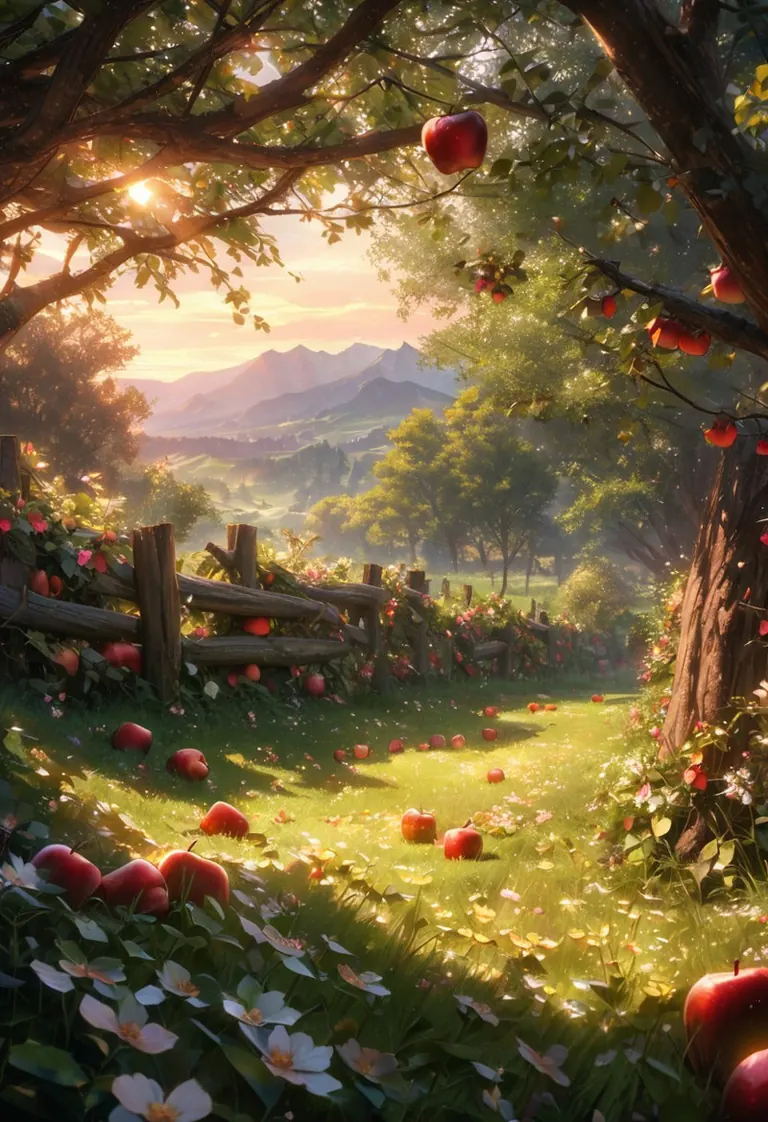
Tetapan
Sampler
DPM++ 2M Karras
Langkah
40
Guidance
7
Seed
1535064897
Saiz
832x1216
Clip skip
2
Prompt
(best quality, 8k, high res, masterpiece:1.2), photorealistic, ultra-detailed, vibrant photography of a picturesque apple orchard at sunset. The trees are heavy with ripe, glistening apples in shades of red, green, and gold, their leaves a vibrant, healthy green. Sunlight filters through the branches, casting a warm, golden glow over the entire scene. Delicate apple blossoms still cling to some branches, adding a touch of soft pink and white to the landscape. The ground is covered with a lush carpet of grass and wildflowers, with fallen apples scattered about. A rustic wooden fence borders the orchard, and in the background, rolling hills and distant mountains are bathed in the warm, fading light of the setting sun. A gentle breeze rustles the leaves and carries the sweet scent of apples through the air. This idyllic scene captures the serene beauty and abundance of nature in exquisite detail. (dynamic angle, cinematic lighting, ethereal atmosphere:1.1), (extremely detailed:1.2), (vivid colors:1.3), (perfect composition:1.2), (sharp focus, stunning realism:1.2)
Prompt negatif
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
Tetapan
Sampler
DPM++ 2M Karras
Langkah
25
Guidance
6
Seed
292950932
Saiz
832x1216
Clip skip
2
Prompt
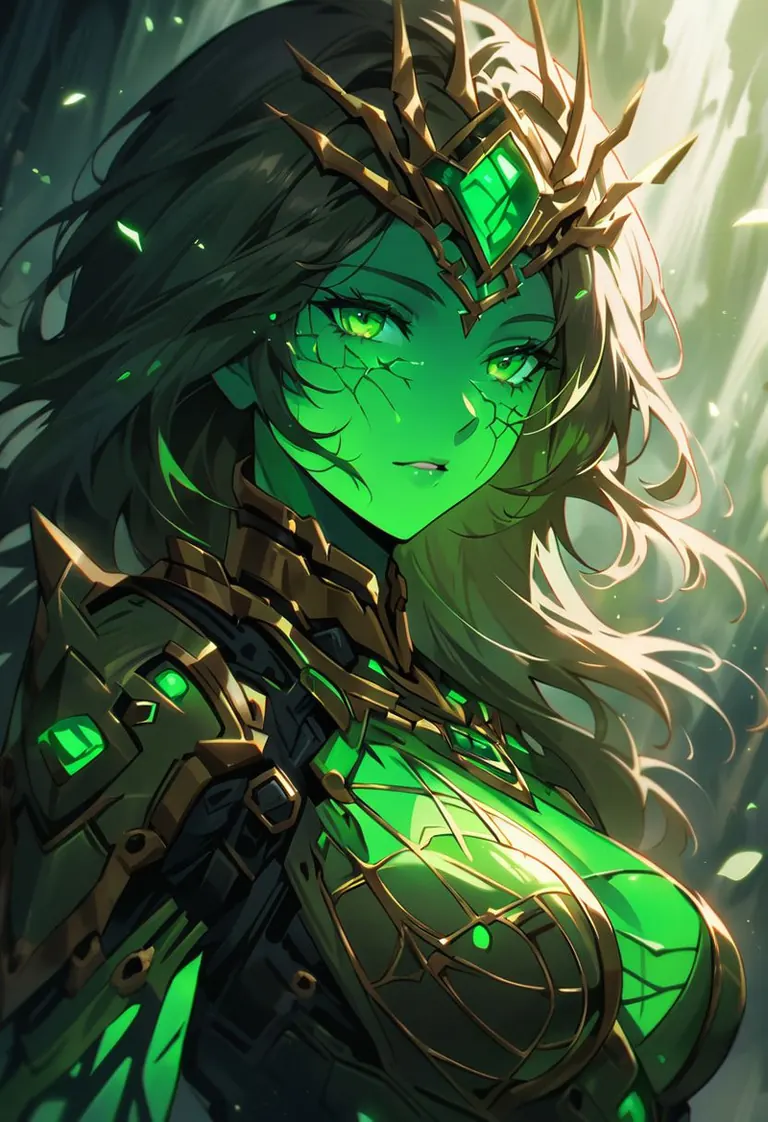
Sexy woman with gold and green mechanical body, glowing green face, glowing green skin, cinematic photography, golden cobweb, majestic, awesome, inspiring, closeup, smooth, atmospheric haze, cinamatic composition, soft shadows, national geographic style, green glow, extremely detailed
Prompt negatif
easynegative, bad proportions, low resolution, bad, ugly, terrible, painting, 3d, render, comic, anime, manga, unrealistic, flat, watermark, signature, worst quality, low quality, normal quality, lowres, simple background, inaccurate limb, extra fingers, fewer fingers, missing fingers, extra arms, (extra legs:1.3), inaccurate eyes, bad composition, bad anatomy, error, extra digit, fewer digits, cropped, low res, worst quality, low quality, normal quality, jpeg artifacts, extra digit, fewer digits, trademark, watermark, artist's name, username, signature, text, words,
Tetapan
Sampler
DPM++ 2M
Langkah
40
Guidance
7
Seed
195493639
Saiz
832x1216
Clip skip
2
Prompt
detailed background,( Calm spring night landscape), amongst lush greenery, beautiful view, creeping phlox in full bloom, creeping phlox, early morning, sunrise sky, beautiful clouds, dappled sunlight, outdoor seating, one lamp, Tranquil Lake, Boat on a Lake, depth of field, masterpiece, best quality, ultra-detailed, very aesthetic, illustration, perfect composition, intricate details, absurdres, moody lighting, wisps of light, no humans,
Prompt negatif
extra digit, fewer digits, cropped, worst quality, low quality, normal quality, very displeasing, blurry, artist name,
Tetapan
Sampler
Restart
Langkah
25
Guidance
7
Seed
2651151167
Saiz
1024x1440
Prompt
masterpiece, best quality, very aesthetic, absurdres
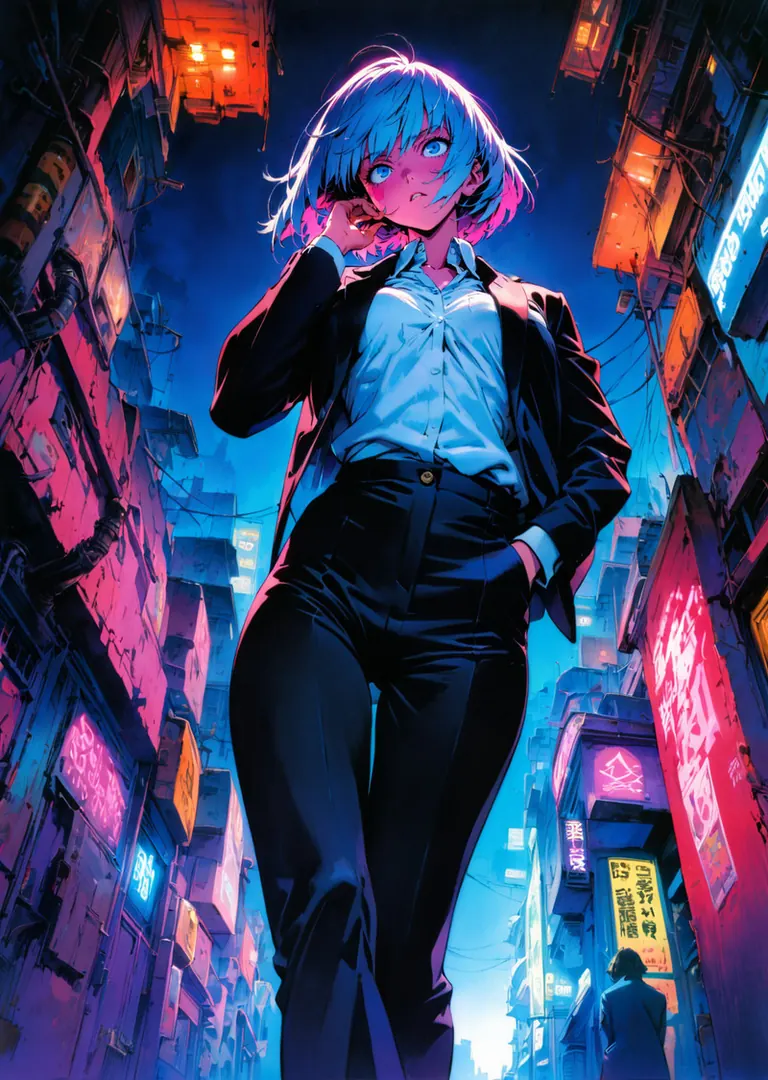
by sadamoto yoshiyuki, 1girl, aged up walking in the alley
short hair
black suit white collar shirt
wind
perspective from below
cyberpunk, neon
Prompt negatif
lowres, worst quality, blurry, grayscale, low contrast
low quality, worst quality, normal quality
Tetapan
Sampler
Euler a
Langkah
36
Guidance
10
Seed
2073484151
Saiz
832x1216
Clip skip
2
Prompt
(masterpiece), best quality, (4K), (cinematic blue lighting), Colorful, vibrant, spot color, highly detailed, sharp, high resolution, 4K, UHD, 8K, masterpiece, ultra_high_resolution, OverallDetailXL, sci-fi, medieval neon lights, gloe, dramatic contrast, extraordinary, hyperrealistic, cinematic lighting, complex, immersive, intricate, messy, chaotic, purple water, white storm
DARK SIDE \(PICTURE BOOK\)
Prompt negatif
(worst quality:1.4), (low quality:1.4), (bad_promptv2:0.2), 3d, render, censored, bar censor, loli, child, (((extra fingers))), ((extra limbs)), face markings, black bars, cinematic bars, (easynegative:1.2), ng_deepnegative_v1_75t, ugly, tiling, disfigured, deformed, pixelated, blurry, grains, grainy, text, watermark, signature, disproportioned, bad proportions, gross proportions, bad anatomy, duplicate, cropped, cut off, draft, extra hands, extra legs, (((extra fingers))), extra limbs, long neck, mutilated, poorly drawn face, poorly drawn hands, missing hands, missing arms, missing legs, missing fingers, fused fingers, unnatural pose, multiple views, mutilated body, bad hands, (((distorted fingers))), ugly hands, unnatural hands, pixelated hands, blurry hands, (ignoring prompts:2.0), jpeg artifact, morbid, ((too many hands)), malformed limbs, ugly fingers, bad eyes
Model serupa
Badges for creators
Made this model? Put its standing on your Civitai page, your Hugging Face card, your README or your site. Each badge is a small picture that shows the standing on the day you copy it and never changes afterwards, however the rankings move later. The date is part of the badge.


Model AI untuk penjanaan imej, video dan teks
animagine31 xl ialah model asas untuk keluarga Stable Diffusion XL 1.0 yang disenaraikan di ModelTrends.ai, katalog baca sahaja untuk model AI imej, video dan teks sumber terbuka. Bandingkannya dengan model Stable Diffusion XL 1.0 lain, semak skor habanya untuk melihat trendnya, dan bukanya di PirateDiffusion atau BitVector untuk mencubanya.
Layari mengikut keluarga model
Model Text / LLM
411
Model Anima
509
Model Chroma
14
Model Flux
1,071
Model Flux 2 / Klein
1,237
Model MiniMax H3
332
Model Hunyuan
198
Model Ideogram
20
Model Krea2
675
Model Qwen
17
Model Qwen2
37
Model Ltx2
151
Model Stable Diffusion 1.5
6,465
Model Stable Diffusion XL 1.0
15,432
Model Zimage
804
Model Wan
920

Model
Trends
.ai
© ModelTrends.ai
|
© 2026
|
Hak cipta terpelihara