rouwei080 xl
Vergleichen
8078°
Lokal ausführen
rouwei_v080Epsilon.safetensors
6.46 GB · SafeTensor · fp16 · pruned
rouwei_v080Epsilon_trainingData.zip
1 MB · Other
Downloads werden von Civitai bereitgestellt. Manche Ersteller verlangen zuerst eine Anmeldung bei Civitai.
AD


Auf Graydient installieren / ausführen
Mitgliedschaft erforderlich
<rouwei080-xl>
Über dieses Modell
STABLE DIFFUSION XL 1.0 · Basismodelle
by Minthybasis - RouWei
Notizen des Erstellers
In depth retraining of Illustrious to achieve best prompt adherence, knowledge and state of the art performance.
Big dreams come true
The version number is just an index of current final release, not a fraction of the planned training.
Large scale finetune using gpu cluster with a dataset of ~13M pictures (~4M with natural text captions)
-
Fresh and wast knowledge about characters, concepts, styles, cultural and related things
-
The best prompt adherence among SDXL anime models at the moment of release
-
Solved main problems with tags bleeding and biases, common for Illustrious, NoobAi and other checkpoints
-
Excellent aesthetics and knowledge across a wide range of styles ( (), including hundreds of unique cherry-picked datasets from private galleries, including those received from the artists themselves)
-
High flexibility and variety without stability tradeoff
-
No more annoying watermarks for popular styles thanks to clean dataset
-
Vibrant colors and smooth gradients without trace of burning, full range even with epsilon
-
Pure training from Illustrious v0.1 without involving third-party checkpoints, Loras, tweakers, etc.
There are also some issues and changes compared to the previous version, please RTFM.
Dataset cut-off - end of April 2025.
Features and prompting:
Important change:
When you are prompting artist styles, especially mixing several, their tags MUST BE in a separate CLIP chunk. Just add BREAK after it (for A1111 and derivatives), use conditioning concat node (for Comfy) or at least put them in the very end. Otherwise, significant degradation of results is likely.
Basic:
The checkpoint works both with short-simple and long-complex prompts. However, if there are contradictory or weird things - unlike with others they won't be ignored affecting the output. No guide-rails, no safeguards, no lobotomy.
Just prompt what you want to see and don't prompt what shouldn't be on the picture. If you want to have a view from above - don't put ceiling into positive, if you want to have crop view with head out of frame - don't make detailed description of character facial features, and so on. Pretty simple but sometimes people are missing it.
Version 0.8 comes with advanced understanding of natural text prompts. It doesn't mean that you are obligated to use it, tags only - completely fine, especially because understanding of tags combinations is also improved.
Do not expect it to perform like Flux or other models based on T5 or LLM text encoders. The whole size ot SDXL checkpoint is less then only that text encoder, in addition illustrious-v0.1 which is used as the base completely forgot a lot of general things from vanilla sdxl-base.
However, even in current state it works much better, allows to do new things usually impossible without external guidance, as well making manual editing, inpainting, etc more convenient.
To achieve best performance you should keep track of CLIP chunks. In SDXL the prompt is separated into a chunks of 75 (77 including BOS and EOS) tokens, that are processing by CLIP separately, and only then are concatinating and comes as conditions to unet.
If you want to specify some features for character/object and separate them from other prompt parts - make sure they are in the same chunk and optionally separate it with BREAK. It will not solve problem of traits mixing completely, but can reduce it improving overall understanding, since text encoders on RouWei are able to process the whole sequence, not individual concepts better then others.
Dataset contains only booru-style tags and natural text expressions. Despite having a share of furries, real life photos, western media, etc. all captions have been converted to classic booru style to avoid a number of problems from mixing of different systems. So e621 tags won't be understanded properly.
Sampling parameters:
-
~1 megapixel for txt2img, any AR with resolution multiple of 32 (1024x1024, 1056x, 1152x, 1216x832,...). Euler_a, 20..28steps.
-
CFG: for epsilon version 4..9 (7 is best), for vpred version, 3..5
-
Sigmas multiply may improve results a bit, CFG++ samplers work fine. LCM/PCM/DMD/... and exotic samplers untested.
-
Some schedulers doesn't work well.
-
Highresfix - x1.5 latent + denoise 0.6 or any gan + denoise 0.3..0.55.
-
For vpred version lower CFG 3..5 is needed!
For vpred version lower CFG 3..5 is needed!
Quality classification:
Only 4 quality tags:
masterpiece, best quality
for positive and
low quality, worst quality
for negative.
Nothing else. Actually you can even omit positive and reduce negative to low quality only, since they can affect basic style and composition.
Meta tags like lowres have been removed and don't work, better not to use them. Low resolution images have been either removed or upscaled and cleaned with DAT depending on their importance.
Negative prompt:
worst quality, low quality, watermark
That's all, no need of "rusty trombone", "farting on prey" and others. Do not put tags like greyscale, monochrome in negative unless you understand what are you doing. Extra tags for brightness/colors/contrast section below can be used
Artist styles:
, (also can be found in "training data").
Used with "by " it's mandatory. It will not work properly without it.
"by " is a meta-token for styles to avoid mixing/misinterpret with tags/characters of similar or close name. This allows to have a better results for styles and at the same time avoid random style fluctuation that you may observe in other checkpoints.
Multiple give very interesting results, can be controlled with prompt weights and spells.
YOU MUST ADD BREAK after artists/style tags (for A1111) or concat conditioning (for Comfy) or put them in the very end of your prompt.
For example:
by kantoku, by wlop, best quality, masterpiece BREAK 1girl, ...
General styles:
2.5d, anime screencap, bold line, sketch, cgi, digital painting, flat colors, smooth shading, minimalistic, ink style, oil st
SHA256
1ABA15DECD15DA1810054ED4C58984610DFAFC728BEF2FB3F3EBE846B2E287A4
ModelTrends.ai-Modell-ID
#20560
Inhalt melden
Beispielbilder
Prompts und Einstellungen, geteilt von den Leuten, die diese Bilder auf Civitai erstellt haben. Wähle ein Bild, um zu sehen, wie es entstanden ist.
Einstellungen
Sampler
Euler a
Schritte
30
Guidance
8
Seed
2039167766
Größe
1504x1024
Prompt
glitch, horror \(theme\), h4rdcry1ng_illu, chiaroscuro, (perspective:2.0), blurry foreground, linear hatching, chromatic aberration, blurry background, iridescent,
BREAK
1man, mature male, aged up, (tall:2.0), (((solo))), serious, expressionless, very short hair, single sidelock, inverted man, albino, gray trench coat, floor-length coat, extremely long coat, oversized clothes, walking, black glow, static, fedora, no feet, long shadow, reaching out, turning head, looking at another,
BREAK
skull chinese dragon monster spirals from the ceiling, eastern dragon, dragon has no legs, ghost dragon, fractal,
BREAK
close-up, eye focus, wide shot, atmospheric perspective,
BREAK
masterpiece, best quality, newest,
<lora:Depth_Map_Simulator:0.4> <lora:hardcry1ng:0.6>
Negativer Prompt
sitting, drinking, talking, feet, standing, worst quality, lowres, [bad anatomy:artist name, signature, jpeg artifacts:0.3]
Einstellungen
Sampler
DDIM
Schritte
28
Guidance
6
Größe
768x1152
Prompt
(by big squid man),(by murayama\ ryota:0.6), (by itomugi-kun:0.8), BREAK, masterpiece, best quality, animal focus, variatons, [moth|owl], whiskers, still life, looking at viewer, white eyes, line art, ink style, illustration.media, AND very as2
Einstellungen
Sampler
Euler a
Schritte
27
Guidance
5.5
Seed
213411725881997
Größe
832x1216
Prompt
masterpiece, best quality, very aesthetic, 1girl, solo, adult, blue eyes, blonde, wavy hair, blush, blush, smile, parted lips, half-closed eyes, holding cup, coffee, cup, looking away, dress shirt, blue shirt, upper body, sidelighting, night, night city, dark
Negativer Prompt
low quality, displeasing,
Einstellungen
Sampler
Euler a
Schritte
29
Guidance
5
Seed
1338700339
Größe
832x1216
Clip skip
2
Prompt
1girl,tamamo \(fate\),fox ears,upper body,from behind,arm up,v,dark,night,cityscape,fireworks,stars in sky,shadow,masterpiece,
Einstellungen
Sampler
DPM++ 3M SDE
Schritte
24
Guidance
5.5
Seed
1328120956
Größe
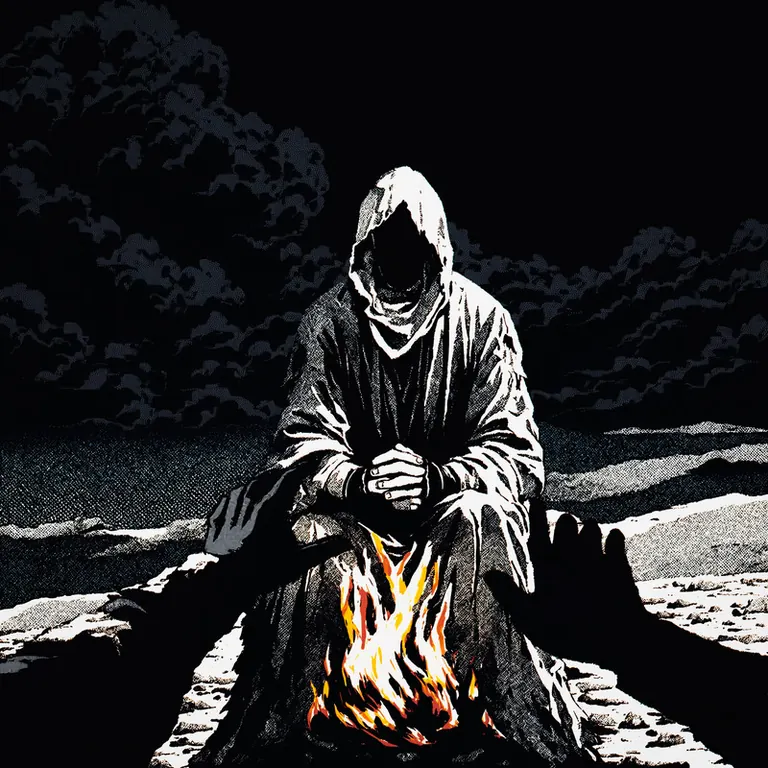
2880x2880
Prompt
dithering, aliasing, limited palette, greyscale, retro art style, good quality, low gamma, hdr,
BREAK
((POV)), night, black theme, black sky, desert, reaching towards another, own hands together, bonfire, large fire, red glow from fire, 1boy, tattered clothes, covered face, rags, looking at viewer, sitting on rock, ((pov across fire)),
fingerless gloves, post-apocalypse
BREAK
POV of you warming your hands by the fire. a man wrapped in cloth and tattered clothes sits across from you. dark desert scene with black sky.
Negativer Prompt
bad quality, explicit, questionable, light particles,
Einstellungen
Sampler
Euler a
Schritte
28
Guidance
7
Seed
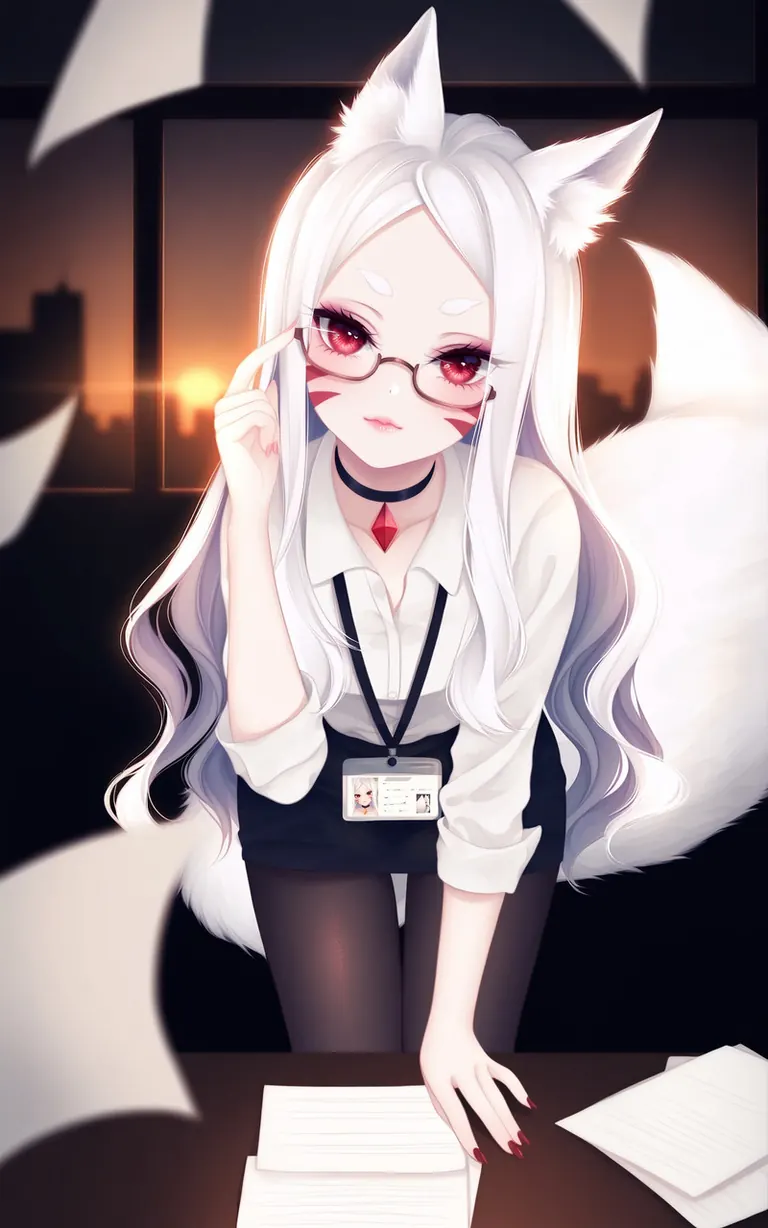
3075936962
Größe
1024x1024
Prompt
by ushiyama ame, by foxykuro, masterpiece, best quality BREAK
1girl, shiro \(sewayaki kitsune no senko-san\), office lady, white shirt, pencil skirt, black pantyhose, bent over, semi-rimless eyewear, head tilt, choker, thigh gap, fox tail, thick eyebrows, floating papers, large tail BREAK
Cute fox girl shiro \(sewayaki kitsune no senko-san\) with long white hair, red eyes and whisker markings, bending over and looking with mixed expression, id card on neck, she fixing glasses with one hand and leaning over a table with other where lays few papers. On the background a cozy office with a cityscape seen through windows slightly blurry, dusk
Negativer Prompt
worst quality, low quality, watermark, dutch angle,
Einstellungen
Sampler
Euler a
Schritte
28
Guidance
7
Seed
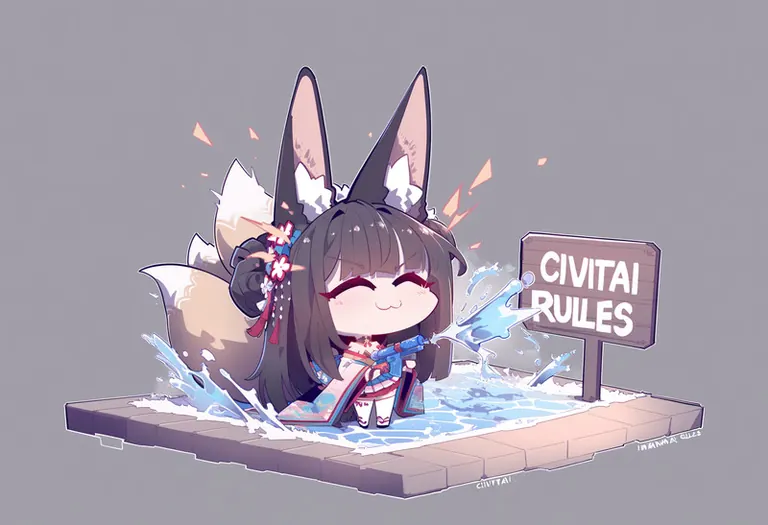
1976316963
Größe
1216x832
Prompt
by imazawa, masterpiece, best quality BREAK
1girl, nagato \(azur lane\), chibi, nagato \(guardian fox's shining furisode\) \(azur lane\), kimono, fox girl, animal ear fluff, tail, smug, :3, standing, simple background, sign with text "civitai rules" covered in water,
holding water gun, firing water at the sign, splashes of water
Negativer Prompt
worst quality, low quality
Einstellungen
Sampler
DDPM
Schritte
30
Guidance
8
Seed
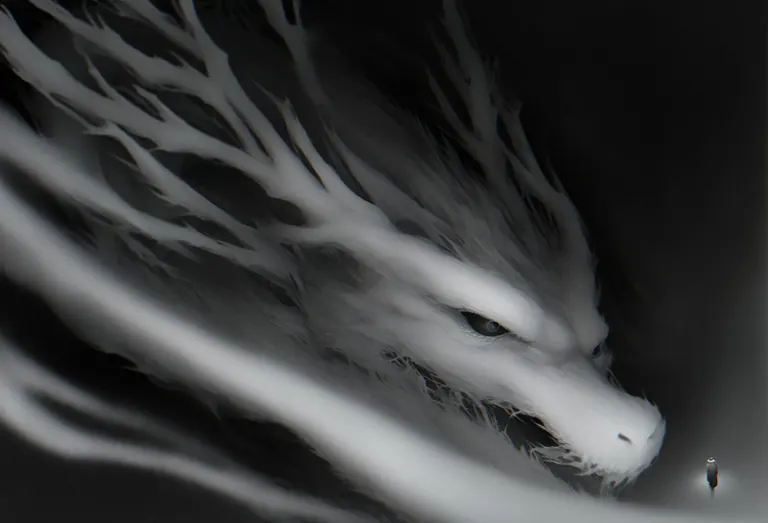
919857956
Größe
1504x1024
Prompt
glitch, horror \(theme\), h4rdcry1ng_illu, chiaroscuro, (perspective:2.0), blurry foreground, ((linear hatching)), chromatic aberration, blurry background, iridescent,
BREAK
1man, mature male, aged up, (tall:2.0), (((solo))), serious, expressionless, very short hair, single sidelock, inverted man, albino, gray trench coat, floor-length coat, extremely long coat, oversized clothes, walking, black glow, static, fedora, no feet, long shadow, reaching out, turning head, looking at another,
BREAK
(skull) chinese dragon monster spirals from the ceiling, ((eastern dragon)), dragon has no legs, ghost dragon, fractal,
BREAK
close-up, eye focus, wide shot, atmospheric perspective,
BREAK
masterpiece, best quality, newest,
<lora:Depth_Map_Simulator:0.4> <lora:hardcry1ng:0.6>
Negativer Prompt
sitting, drinking, talking, feet, standing, worst quality, lowres, [bad anatomy:artist name, signature, jpeg artifacts:0.3]
Ähnliche Modelle
KI-Modelle für Bild-, Video- und Texterzeugung
rouwei080 xl ist ein Basismodell für die Familie Stable Diffusion XL 1.0 und wird auf ModelTrends.ai gelistet, einem reinen Lesekatalog für Open-Source-KI-Modelle für Bild, Video und Text. Vergleiche es mit anderen Stable Diffusion XL 1.0-Modellen, prüfe den Hitzewert, um den Trend zu sehen, und öffne es auf PirateDiffusion oder BitVector, um es auszuprobieren.
Weitere Stable Diffusion XL 1.0-ModelleWeitere Stable Diffusion XL 1.0 Basismodelleillustriousanimebasebase model
Nach Modellfamilie stöbern
Text / LLM-Modelle
415
Anima-Modelle
519
Chroma-Modelle
15
Flux-Modelle
1,497
Flux 2 / Klein-Modelle
1,239
MiniMax H3-Modelle
332
Hunyuan-Modelle
204
Ideogram-Modelle
20
Krea2-Modelle
677
Qwen-Modelle
20
Qwen2-Modelle
37
Ltx2-Modelle
152
Stable Diffusion 1.5-Modelle
7,032
Stable Diffusion XL 1.0-Modelle
17,383
Zimage-Modelle
815
Wan-Modelle
1,244

Model
Trends
.ai
© ModelTrends.ai
|
© 2026
|
Alle Rechte vorbehalten