Lecture automatique
Exécuter en local
wan_i2v_720_l1v3w4llp4p3r_e50_with_trigger.safetensors
685 MB · SafeTensor
Les téléchargements sont servis par Civitai. Certains créateurs demandent d'abord une connexion à Civitai.


À propos de ce modèle
WAN · LoRA
by alissonerdx - Live Wallpaper Style
Notes du créateur
The goal of this lora is to reproduce the video style similar to live wallpaper, for those who play league of legends remember the launcher opening videos, that's the goal, but you can also use it to create your lofi videos :D enjoy.
[Wan2.2 TI2V 5B - Motion Optimized Edition] Trained on 51 curated videos (24fps, 96 frames) for 5,000 steps across 100 epochs with rank 48. Optimized specifically for Wan2.2's unified TI2V 5B dense model and high-compression VAE.
My Workflow (It's not organized, the important thing is that it works hahaha):
Loop Workflow:
Trigger word: l1v3w4llp4p3r
[Wan2.2 I2V A14B - Full Timestep Edition]
Trained on 301 curated videos (256px, 16fps, 49 frames) for 24 hours using Diffusion Pipe with Automagic optimizer, rank 64. Uses extended timestep range (0-1) instead of standard (0-0.875), enabling compatibility with both Low and High models despite training only on Low model.
Trigger word: l1v3w4llp4p3r
Works excellently with LightX2V v2 (256 rank) for faster inference
[Wan I2V 720P Fast Fusion - 4 (or more) steps]
Wan I2V 720P Fast Fusion combines 2 Live Wallpaper LoRA (1 Exclusive) with Lightx2v, AccVid, MoviiGen and Pusa LoRAs for ultra-fast 4+ steps generation while maintaining cinematic quality.
🚀 – accelerates generation by 20x through 4-step distillation, enabling sub 2-minute videos on RTX 4090 with only 8GB VRAM requirements.
🎬 – improves motion accuracy and dynamics for expressive sequences.
🌌 – adds cinematic depth and flow to animation, enhancing visual storytelling.
🧠 – provides fine-grained temporal control with zero-shot multi-task capabilities (start-end frames, video extension) while achieving 87.32% VBench score.
🧠 base model – providing strong temporal consistency and high-resolution outputs for expressive video scenes.
[Wan I2V 720P]
The dataset used consists of 149 videos (each one hand-selected) in 1280x720x96 resolution but was trained in 244p and 480p and 64 frames with 64 dim (L40s).
Trigger word was used so it needs to be included in the prompt: l1v3w4llp4p3r
[Hunyuan T2V]
The dataset used consists of 529 videos (each one hand-selected) in 1280x720x96 resolution but was trained in 244p and 72 frames with 64 dim (multiple RTX 4090).
No captions or activation words were used, the only control you will need to adjust is the lora strength.
Another important note is that it was trained in full blocks, I don't know how it will behave when mixing 2 or more loras, if you want to mix and are not getting a good result, try disabling single blocks.
I recommend using lora strength between 0.2 and 1.2 maximum, resolution 1280x720 or generate at 512 and upscale later, minimum 3 seconds (72 frames + 1).
[LTXV I2V 13b 0.9.7 – Experimental v1]
The model was trained on 140 curated videos (512px, 24fps, 49 frames), using 250 epochs, 32 dim, and AdamW8bit.
It was trained using Diffusion Pipe with support for LTXV I2V v0.9.7 (13B).
Captions were used and generated with Qwen2.5-VL-7B via a structured prompt format.
This is an experimental first version, so expect some variability depending on seed and prompt detail.
Recommended:
Scheduler: sgm_uniform
Sampler: euler
Steps: 30
⚠️ Long prompts are highly recommended to avoid motion artifacts.
You can generate captions using the or optionally use the official LTXV Prompt Enhancer.
For more details, see the About this version tab.
------------------------------------------------------------------------------------------------------
For more details see the version description
Share your results.
Mots déclencheurs
l1v3w4llp4p3r
SHA256
5709C41FE18C6968A1F18DE480D9E7F4C590A8C5D40F9C4222797CA43667E1F3
ID de modèle ModelTrends.ai
#11594
Signaler le contenu
Rendus d'exemple
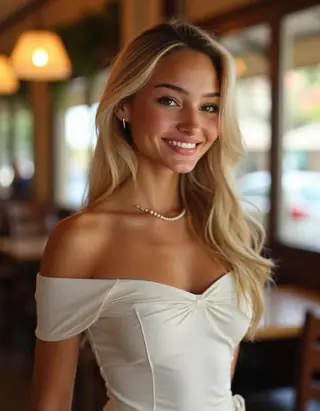
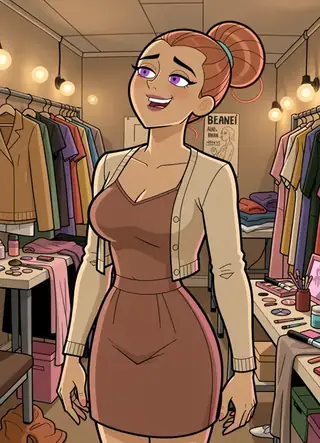
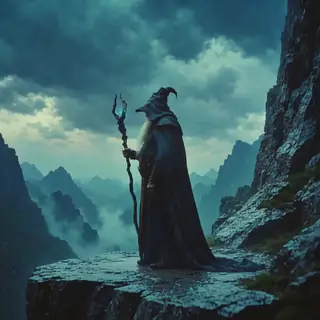
Prompts et réglages partagés par les personnes qui ont réalisé ces rendus sur Civitai. Choisissez un rendu pour voir comment il a été fait.
Réglages
Taille
696x1024
Prompt
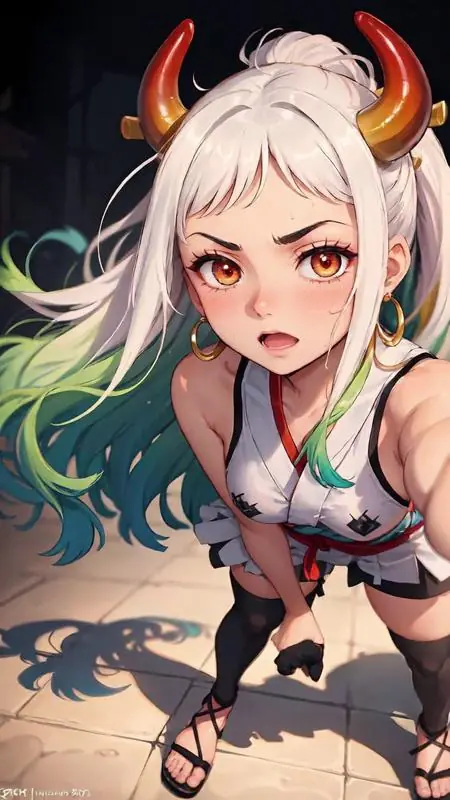
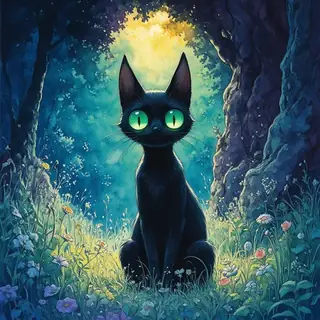
anime style scene,a cat.l1v3w4llp4p3r
Réglages
Taille
480x720
Prompt
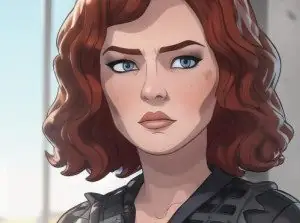
l1v3w4llp4p3r, Palading elf female knight from warcraft. Wind slightly ruffles grass, sun rays shift dynamically, slight breathing motion, live wallpaper effects.
Prompt négatif
Overexposure, static, blurred details, subtitles, paintings, pictures, still, overall gray, worst quality, low quality, JPEG compression residue, ugly, mutilated, redundant fingers, poorly painted hands, poorly painted faces, deformed, disfigured, deformed limbs, fused fingers, cluttered background, three legs, a lot of people in the background, upside down, white flashlights, glow light effect, post edit, ugly distorted hands, scrambled fingers, wild arm movement, text, icons, logo, post production, istorted face, exaggerated anatomy, unrealistic proportions
Réglages
Taille
696x1024
Prompt
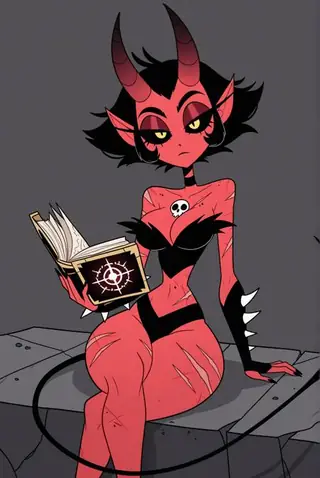
Anime style scene,.l1v3w4llp4p3r,
Prompt négatif
色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走
Réglages
Étapes
20
Guidance
3.4
Seed
2146930585
Taille
480x688
Poids utilisé
1
Prompt
masterpiece, best quality, amazing quality, standing at the ready, dripping water, ring of paint floating behind the knight
Réglages
Taille
712x1024
Prompt
Anime style scene,.l1v3w4llp4p3r,
Prompt négatif
色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走
Réglages
Étapes
20
Guidance
4
Seed
1226181787
Taille
480x688
Poids utilisé
1
Prompt
The dark fantasy vampire kisses a woman, blood flows from her lips, her eyes slowly close. In the background, clouds drift across the moon.
Réglages
Étapes
20
Guidance
4
Seed
1842396528
Taille
480x688
Poids utilisé
1
Prompt
The alien winks and smiles as the camera slowly zoom in. His malachite-colored skin moves as if it were liquid.
Modèles similaires
Badges for creators
Made this model? Put its standing on your Civitai page, your Hugging Face card, your README or your site. Each badge is a small picture that shows the standing on the day you copy it and never changes afterwards, however the rankings move later. The date is part of the badge.


Modèles d'IA pour générer image, vidéo et texte
live wallpaper wan est un LoRA pour la famille Wan, référencé sur ModelTrends.ai, un catalogue en lecture seule de modèles d'IA open source pour l'image, la vidéo et le texte. Comparez-le aux autres modèles Wan, consultez son score de chaleur pour suivre sa tendance et ouvrez-le sur PirateDiffusion ou BitVector pour l'essayer.
Parcourir par famille de modèles
Modèles Text / LLM
411
Modèles Anima
509
Modèles Chroma
14
Modèles Flux
1,071
Modèles Flux 2 / Klein
1,237
Modèles MiniMax H3
332
Modèles Hunyuan
198
Modèles Ideogram
20
Modèles Krea2
675
Modèles Qwen
17
Modèles Qwen2
37
Modèles Ltx2
151
Modèles Stable Diffusion 1.5
6,465
Modèles Stable Diffusion XL 1.0
15,432
Modèles Zimage
804
Modèles Wan
920

Model
Trends
.ai
© ModelTrends.ai
|
© 2026
|
Tous droits réservés