Exécuter en local
dixar_iiiTripleTheD.safetensors
6.46 GB · SafeTensor · fp16 · full
Les téléchargements sont servis par Civitai. Certains créateurs demandent d'abord une connexion à Civitai.


À propos de ce modèle
STABLE DIFFUSION XL 1.0 · Modèles de base
by Typhoon2285 - This version definetely has some issues, but it is good enough to post. It aims to be closer to a screenshot from a Pixar movie, it's obviously not there yet but it is getting there. You don't have to specify 3d, Pixar, or anything but I feel it looks better when you do, just like anything with image generation you are telling the model what you want it to make for you. Euler A Beta or SGM 50 Steps 3 CFG It does not know specific characters, although I only tried one. It is also fragile and easily breakable. It will work with some loras but others just break it.
Notes du créateur
Click on the pictures to see them in better quality.
__________________________________________________________________________________________________
Dixar v5 is coming soon! I finished finalizing my Dataset, which has grown to 20,110 images.
90% of The Dataset for Dixar consists of images created by me. About 6k images now.
V4 Below
A new version already? I know right!
Dixar Version 4 is a merge of trained Dixar models, similar to v3. It is less cinematic than v3 but I feel that it is more stable and more faithful to the original Dixar.
I was lazy with the example images and for many of them, I just stole prompts from images I liked that you morons made with slight alterations because you all are sick mother fuckers. The Prompts were taken from pictures I liked in both Dixar v2 and v3. I really used minimal effort on the example images and they are only lightly detailed.
The Clip is also lightly trained as well, although I just used whatever tags Kohya gave me. I don't really know how to make high quality captions/tags and i'm not tagging 6k images by hand lol
For once the example images actually contain the prompts and shit. For most of the images it was:
Euler A
Beta
40 Steps
CFG of 5
I used the SeedVR2 node in Comfy to upscale.
Idk if it is better, worse, or just different than v3, but the quality looked good enough to publish.
If you merge it with something just credit me.
Likely no more updates to Dixar until Z-image base comes out. I will train on that next.
Post your images and maybe i'll use your prompt for Dixar five's showcase images.
That's kinda it, by now you should all know how to use an image generation model.
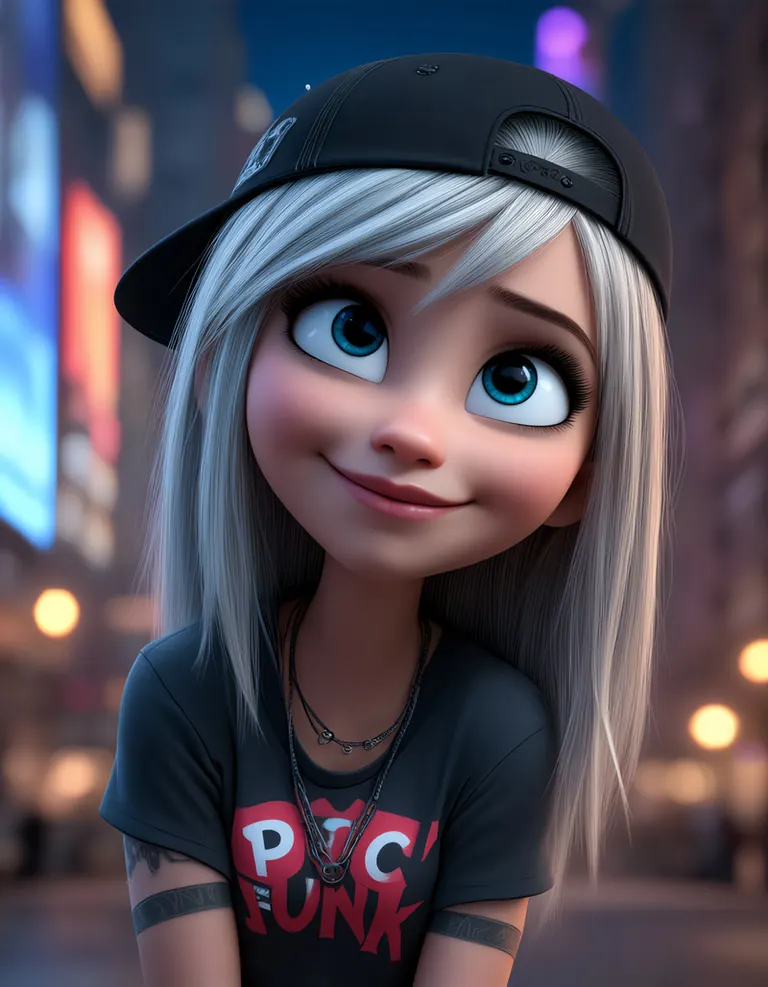
PS- The main picture that is always in front (punk silver haired girl with backwards hat) got flagged for review for some reason so after it got approved by the mods the day after I posted this, i moved it to image 5.
Have a wonderful day and go fuck yourself.
__________________________________________________________________________________________
V3 Below
-
Dixar version 3 is a trained model...mostly. It is a merge of five separate trained versions of Dixar.
Each version was trained on Kohya. I am still learning how to train checkpoints and honestly, I kinda suck at it. I have trained it about 20 separate times and I have six versions that I like but none are perfect as standalone models. This is probably among the best I have so far. The dataset at the time consisted of 2600 images, 90% of the dataset was created by me, which is where I think the model is unique, very high quality images in a dataset, almost all of which were created by me. They were created using everything you can imagine, some in Comfy with various versions of Dixar that I have, some using Chat GPT, Some using Nano Banana Pro, Hunyuan image 3, Wan2.5 image, Seed Dream 4, Qwen, and Midjourney.
Just building the dataset probably cost a few thousand $$$ worth of gpu time or credits on various sites, as well as a ton of time. Currently I have brought the dataset up to 6910 images but I have not trained, or even organized those images yet.
This version defiantly has some issues, but it is good enough to post.
It aims to be closer to a screenshot from a Pixar movie, it's obviously not there yet but it is getting there.
You don't have to specify 3d, Pixar, or anything but I feel it looks better when you do, just like anything with image generation you are telling the model what you want it to make for you.
Euler A
Beta or SGM
50 Steps
3 CFG
It does not know specific characters, although I only tried one.
It is also fragile and easily breakable. It will work with some loras but others just break it.
Some of the example images are hidden if you have X and XXX enabled.
The very last image is a raw batch of 50 images.
Just credit me if you merge it.
I Like to see the images you create, plus if I like them a lot, I'll add them to my master dataset for v4.
Next, I will train my anime model, Hemorrhoids, but I must build my own dataset first though.
As always, have a wonderful day and go fuck yourself.
__________________________________________________________________________________________________
------------------------------------V2 Below-----------------------------------------------------
Dixar 2: Double the Dix
Low CFG suggested 3 to 3.5
Sample pics were all made with Deis and SGM
I merged Dixar with CyberIllustrious40 + MMMix + A cool 3d checkpoint I found on a Chinese website + an unreleased blender style model I made (not releasing that one yet, it is still not up to my standards).
It was also merged with a Lora I made that took 100 of the most 3d pictures I used with 3dish lora for flux. There was no trigger word in there, the images weren't even tagged or captioned. All the pictures in that Dataset were made by me. That lora took 2 months for thousands of images with flux and thousands of individual fixes.... all that for 150 downloads :(
Because The above source images in that Lora were made with Flux, it is pretty blush heavy. I do recommend using (Blush:1.2) in the negative prompt.
The clip is a 50/50 mix of Dixar and Cyber.
There were more sample images but they got flagged for review and I am too lazy to make more.
Always remember, I do not care about your opinion.
Keep in mind that I have no idea what I am doing. I make models the same way I passed algebra in high school, the guess and check method. Fuck you Mx+B=Dick
The very first image was made with the same prompt as image 2 from v1. That prompt is at the bottom. If you know how to read it will be helpful to look at it.
For it's first eligible week 6/5/25 to 6/12/25, I'll put the rest of my buzz on it to enable it for sitewide generation. I have 10k left which might be enough to crack the top 200
I appreciate everyone who donates BUZZ to me but honestly, I don't need the money. Save the buzz, give it to somebody else, or just bid on this for onsite generation so everybody can
SHA256
9BA9AA0034AD6690220E70238AE58DD8A6667DD6654BB6F39E1F9DCF9AC603CA
ID de modèle ModelTrends.ai
#20875
Signaler le contenu
Rendus d'exemple
Prompts et réglages partagés par les personnes qui ont réalisé ces rendus sur Civitai. Choisissez un rendu pour voir comment il a été fait.
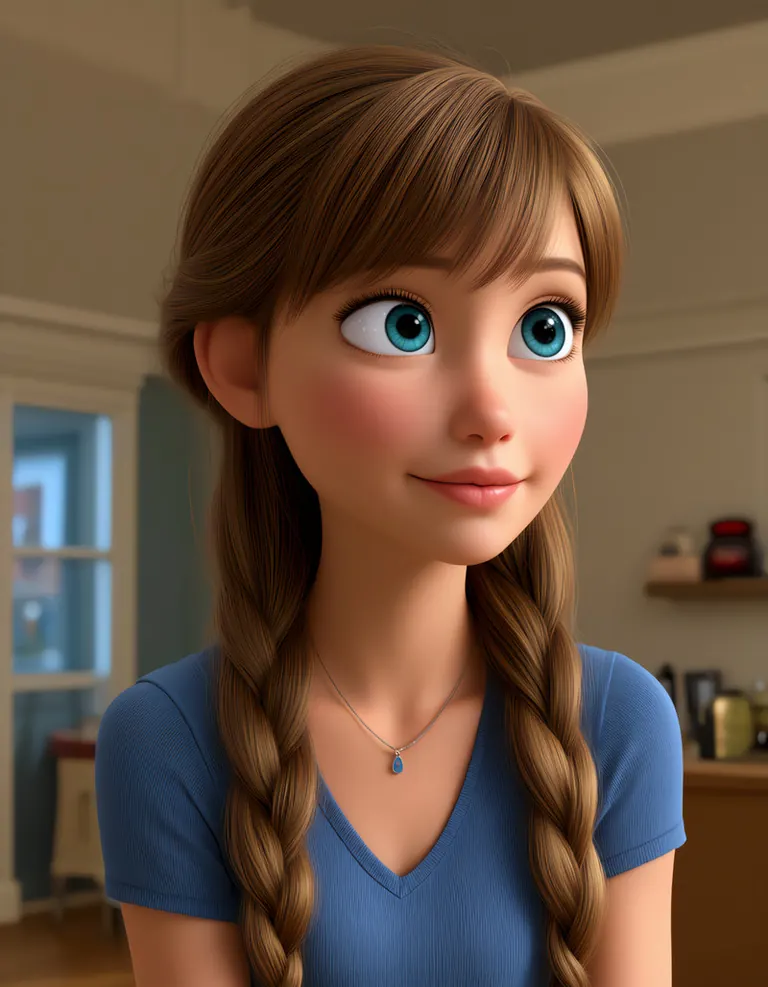
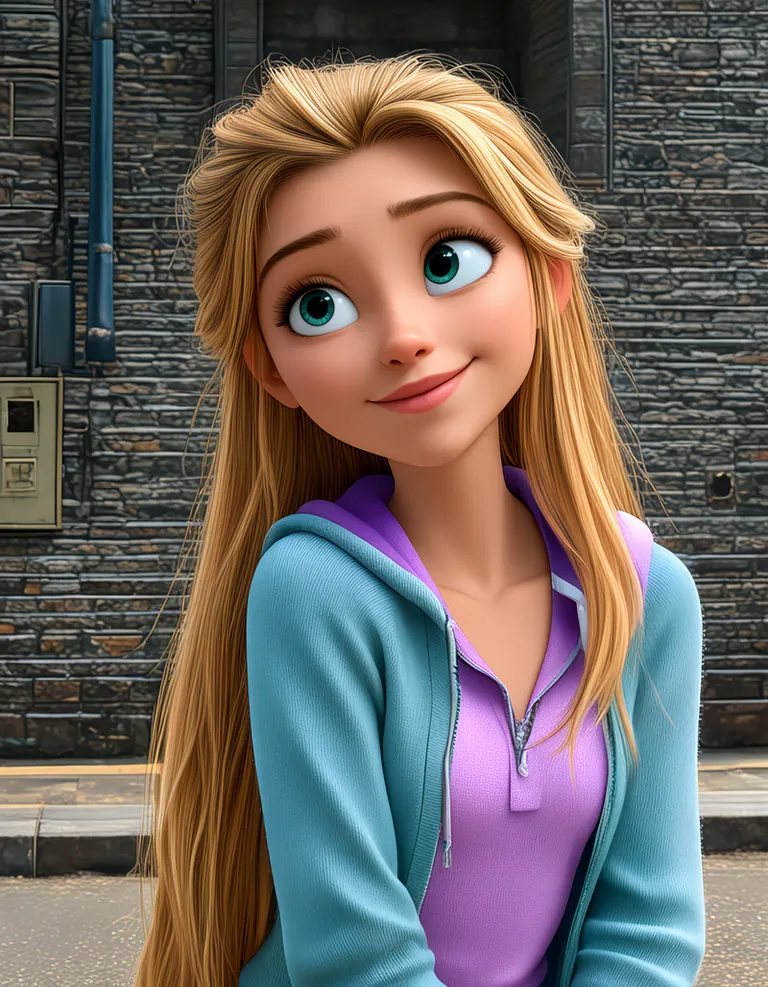

Réglages
Taille
1792x2304
Prompt
The same prompt as the first two versions with the similar image
Réglages
Taille
1792x2304
Prompt
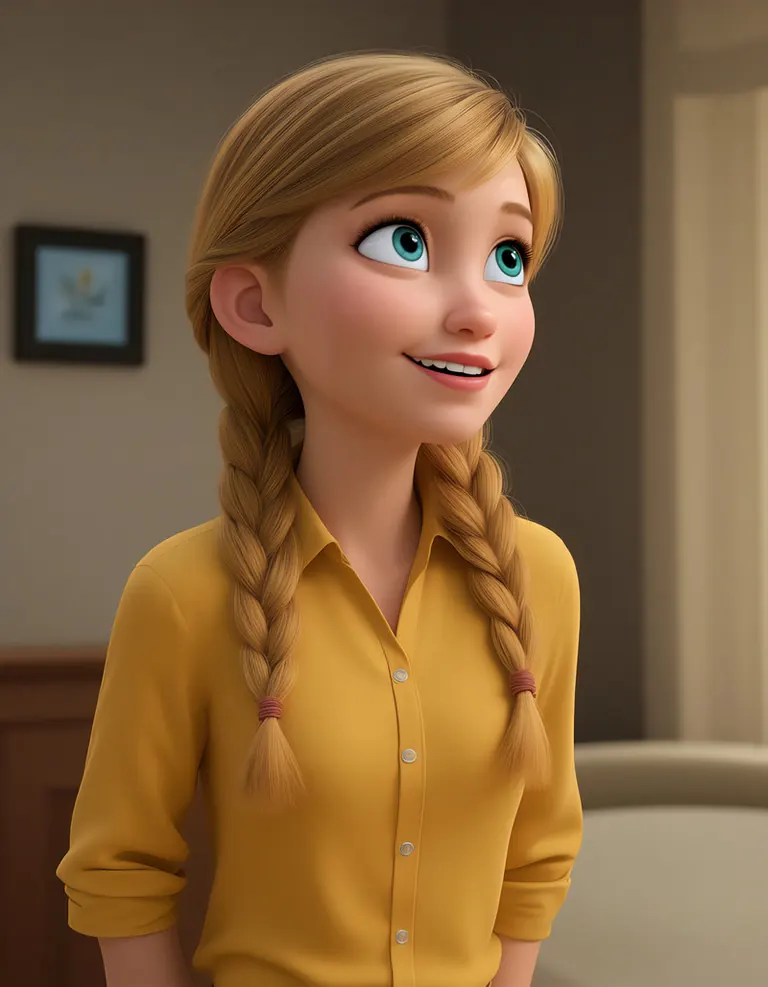
Ho with braids
Réglages
Taille
1792x2304
Prompt
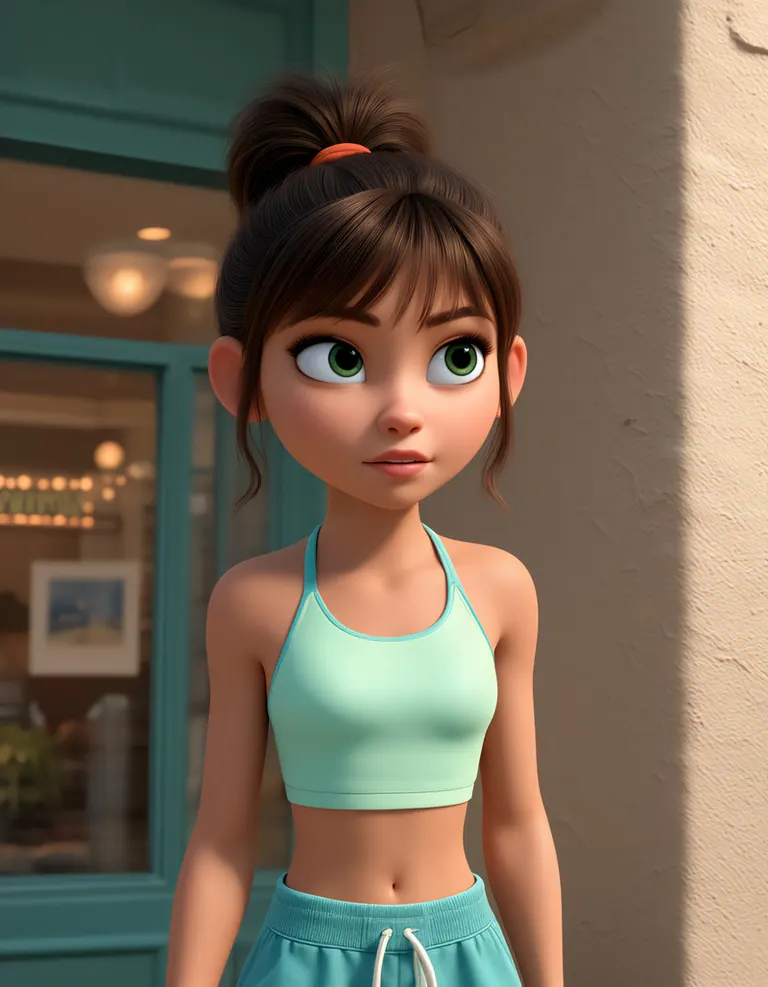
She defiantly a ho
Réglages
Taille
1792x2304
Prompt
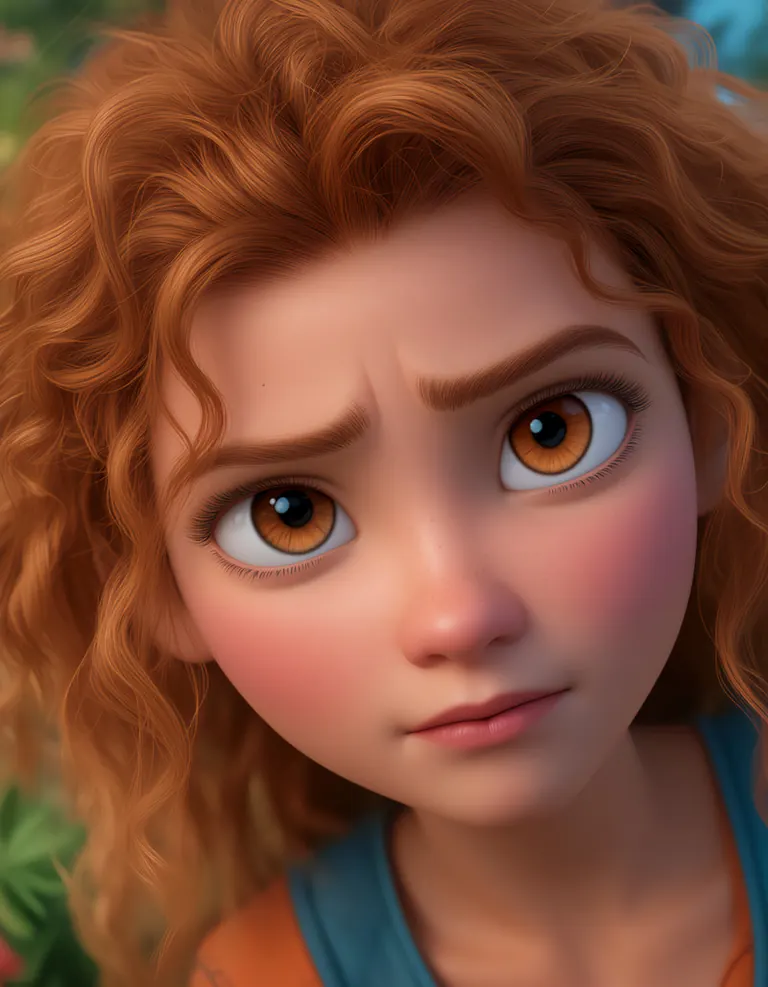
Ginger Ho
Réglages
Taille
1792x2304
Prompt
Ho with uncomfortably large eyes
Réglages
Taille
1792x2304
Prompt
no
Réglages
Sampler
Euler_simple
Étapes
18
Guidance
6.8
Seed
602496007352635
Taille
1024x1024
Clip skip
2
Prompt
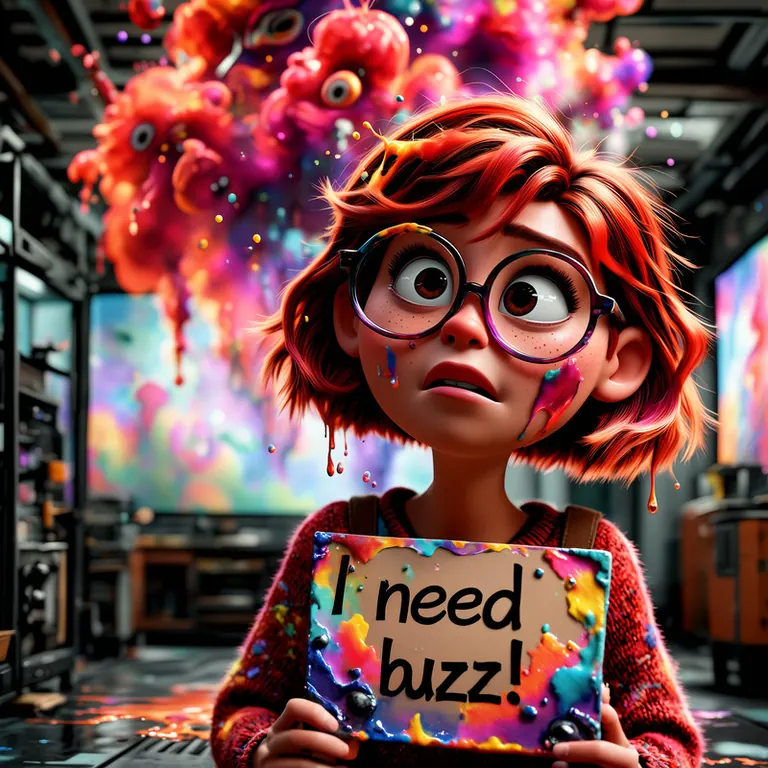
(need_buzz, holding sign:1.5),masterpiece, best quality, detailed eyes, detailed face, close up. (surreal:1.5), cinematic still, Me1l1n, 3d_animation, solo, 1girl, short hair, brown eyes, red hair, glasses, round eyewear, freckles, red sweater, streaked hair merging with smoke, (large_breasts:0.9), abstract colorful explosions, ink drips, watercolor splashes, radiant particles, impossible geometry background, dreamlike surreal vibe, colorful, glitching server room, corrupted data, wild abstract background, liquid light, oil paint swirls, black and neon purple palette, running, <lora:illustriousXLv01_stabilizer_v1.198:0.6> <lora:Add_Details_v1.2:0.8> <lora:RealSkin_xxXL_v1:2> <lora:NeedBuzz_sign_Illustrious:1> <lora:Meilin_Lee_IllustriousXL11:1>
Prompt négatif
(bad quality:1.1), (worst quality:1.1), bad details, (bad hands:1.2), child, loli, pubic hair, letters, shiny skin,
Réglages
Taille
928x1376
Prompt
Cute and innocent girl gets bashful and shy around viewer, action sequence, sexy
Modèles similaires
Modèles d'IA pour générer image, vidéo et texte
dixar3 xl est un modèle de base pour la famille Stable Diffusion XL 1.0, référencé sur ModelTrends.ai, un catalogue en lecture seule de modèles d'IA open source pour l'image, la vidéo et le texte. Comparez-le aux autres modèles Stable Diffusion XL 1.0, consultez son score de chaleur pour suivre sa tendance et ouvrez-le sur PirateDiffusion ou BitVector pour l'essayer.
Plus de modèles Stable Diffusion XL 1.0Plus de Modèles de base Stable Diffusion XL 1.03dcartoonsbaseanime25dbase modelpixarthe
Parcourir par famille de modèles
Modèles Text / LLM
411
Modèles Anima
509
Modèles Chroma
14
Modèles Flux
1,071
Modèles Flux 2 / Klein
1,237
Modèles MiniMax H3
332
Modèles Hunyuan
198
Modèles Ideogram
20
Modèles Krea2
675
Modèles Qwen
17
Modèles Qwen2
37
Modèles Ltx2
151
Modèles Stable Diffusion 1.5
6,465
Modèles Stable Diffusion XL 1.0
15,432
Modèles Zimage
804
Modèles Wan
920

Model
Trends
.ai
© ModelTrends.ai
|
© 2026
|
Tous droits réservés