Run Locally
thinkdiffusionxl_v10.safetensors
6.46 GB · SafeTensor · fp16 · full
Downloads are served by Civitai. Some creators ask for a Civitai login first.


About This Model
STABLE DIFFUSION XL 1.0 · Base Models
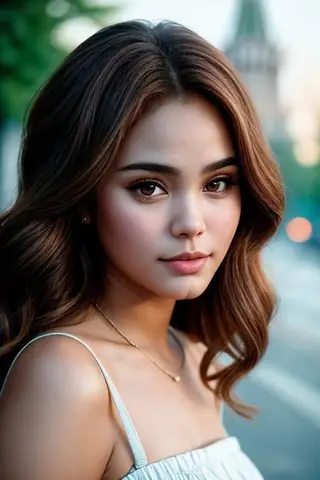
ThinkDiffusionXL by ThinkDiffusion. ThinkDiffusionXL is the result of our goal to build a go-to model capable of amazing photorealism that's also versatile enough to generate high-quality images across a variety of styles and subjects without needing to be a prompting genius.
Creator notes
ThinkDiffusionXL (TDXL)
ThinkDiffusionXL is the result of our goal to build a go-to model capable of amazing photorealism that's also versatile enough to generate high-quality images across a variety of styles and subjects without needing to be a prompting genius.
You can find it preloaded on
Please leave a review if you're happy with it, this will encourage us to create more and improve on it.
The work
-
Data source: TDXL is trained on over 10,000 diverse images that span photorealism, digital art, anime, and more. The smallest resolution in our dataset is 1365x2048, but many images go up to resolutions as high as 4622x6753. In total, our dataset takes up 42GB.
-
Training: With 1.8 million steps, we’ve put in the work. For comparison, Juggernaut is at 600k steps and RealVisXL is at 348k steps
-
Hand-captioned images: Each image is carefully captioned by hand, enhancing the model's ability to generate accurate and high-quality results from minimal prompts.
-
NSFW capabilities: The model includes over 1,000 tastefully curated NSFW images.
Our thoughts
-
Detail and quality: Most XL models in the Realistic category suffer from poor detail, especially in the background and even in basic features like eyes, teeth, and skin. We believe TDXL outperforms in these areas due to its large, high-quality dataset. For comparison, Juggernaut has about half the image material, and RealVisXL has only 1,700 images. Ultimately, TDXL simply possesses much more "knowledge".
-
Less-Bias: We made sure to use an equal number of images for each style, gender, etc. Other models we tested over the past few months had some kind of bias, sometimes it was bias toward portrait shots, gender bias, certain ethnicities, etc. For instance, Juggernaut has a bias in the Close-Up area, and the Cinematic Light is quite dominant in that model. RealVisXL also has a bias towards Portrait shots. On the other hand, TDXL gives you what you want: Landscape, Midshot, Full Body, Close-Up, Portrait, Sideview, Backview, Action Shots, Cinematic...whatever you want without always being pushed in a certain direction due to a bias.
-
Versatile base: Because of its large balanced quality dataset, TDXL is versatile to serve as a base model for future trainings. You can create new finetunes in entirely different directions, add LoRAs to fill in missing concepts, or do additional trainings with more balanced quality data.
SHA256
A21C9949EFCB8A0218F575AAFF3FD5E8FEDC508CA6757DDB44C5958CB0859F77
ModelTrends.ai Model ID
#7681
Flag content
Example renders
Prompts and settings shared by the people who made these renders on Civitai. Pick a render to see how it was made.
Settings
Sampler
DPM++ 2M Karras
Steps
30
Guidance
7
Seed
2063937052
Size
768x1160
Clip skip
2
Prompt
(((masterpiece))),(((best quality))),highly detailed, cinematic film still 1girl wet tshirt water drops,splash detailed,surreal dramatic lighting shadow (lofi, analog),kodak film by Brandon Woelfel Ryan McGinley,vignette,high budget,bokeh,cinemascope,moody,epic,gorgeous,film grain,grainy, <lora:xl_more_art-full_v1:0.75>,
Settings
Sampler
DPM++ 2M Karras
Steps
40
Guidance
7
Seed
357142759
Size
512x768
Clip skip
2
Prompt
A gritty engraving etching in the style of Gustave Dore, Moses holds a huge stone tablet with the very large and bold number "404" on it , on mount Sinai amidst a storm, uhd, ((the number "404" written on the tablet)), 8k, intense lighting, award winning masterpiece, high contrast, extremely detailed, detailed background, cinematic, complex and multidimensional lighting, <lora:xl_more_art-full_v1:0.6>, <lora:add-detail-xl:0.6>
Negative prompt
worst quality, low quality, ugly, blurry, unaesthetic, dull colors, (watermark, signature), bad hands,
Settings
Sampler
DPM++ 2M Karras
Steps
30
Guidance
7
Seed
1636543672
Size
768x1168
Prompt
android afghan girl photography by Steve McCurry in cyberpunk style,cyberpunk urban scenery,150mm,dlrs,robotic parts,beautiful neon soft light,bioluminescent tattoos,vibrant details,explicit soft mist,beautiful masterwork by head of prompt engineering
Negative prompt
(worst quality, low quality, normal quality, lowres, low details, oversaturated, undersaturated, overexposed, underexposed, grayscale, bw, bad photo, bad photography, bad art:1.4), (watermark, signature, text font, username, error, logo, words, letters, digits, autograph, trademark, name:1.2), (blur, blurry, grainy), morbid, ugly, asymmetrical, mutated malformed, mutilated, poorly lit, bad shadow, draft, cropped, out of frame, cut off, censored, jpeg artifacts, out of focus, glitch, duplicate, (airbrushed, cartoon, anime, semi-realistic, cgi, render, blender, digital art, manga, amateur:1.3), (3D ,3D Game, 3D Game Scene, 3D Character:1.1), (bad hands, bad anatomy, bad body, bad face, bad teeth, bad arms, bad legs, deformities:1.3)
Settings
Sampler
DPM++ 2M SDE Karras
Steps
28
Guidance
7
Seed
2374393851
Size
768x1024
Prompt
a LED chihuahua with a coat made out of ral-jeans <lora:ral-jeans-sdxl:1> sitting on a ral-jeans throne
Settings
Sampler
Euler a
Steps
28
Guidance
7
Seed
135075191
Size
832x1216
Clip skip
1
Prompt
by Aaron Jasinski, by Ken Sugimori, (by Brian Mashburn, (by Dan Mumford, magical)), magical, cute baby hamster <lora:ral-jeans-sdxl:1> ral-jeans
Negative prompt
bad quality, bad anatomy, worst quality, low quality, low resolution, extra fingers, blur, blurry, ugly, wrong proportions, watermark, image artifacts, lowres, ugly, jpeg artifacts, deformed, noisy image
Settings
Sampler
DPM++ 2M Karras
Steps
30
Guidance
4
Size
1792x2304
Prompt
cinematic film still dramatic side lighting, dramatic intense stare closeup portrait, dark black background, hdr, dramatic beautiful warrior woman with warrior face paintings and blood, viking braids, blue eyes, pelt, skull necklace, shallow depth of field, vignette, highly detailed, high budget Hollywood film, cinemascope, moody, epic, gorgeous
Negative prompt
anime, cartoon, graphic, text, painting, crayon, graphite, abstract, glitch, blur, bokeh
Settings
Sampler
DPM++ 2M Karras
Steps
30
Guidance
8
Seed
3290503291
Size
1152x896
Prompt
Drawing inspiration from 20th century surrealists like Zdislaw Beksinski,M.C. Escher,H.R. Giger, Horrors of the Great War, (Rats,Sentry posts,Hand-to-hand combat,Grenades,Messengers), , Terror, Asymmetry, [dark|light], [life|death], Mangled, abstract geometric shapes, oil on canvas, drybrush
Negative prompt
modern, sci-fi, futuristic, centered, portrait, symmetry, monochrome, black and white, kitschy,superficial,overly literal,trite,naive,mundane reality
Settings
Sampler
DPM++ 2M Karras
Steps
30
Guidance
7
Seed
382626721
Size
1152x896
Prompt
Inspired by Ian Miller's detailed, nature-meets-machine artistry,Wayne England's bold, angular designs, Horrors of the Great War, (Stretcher bearers,Minenwerfer,Shellfire,Shrapnel,Bayonets), g1g3r, <lora:g1g3r:0.4>, Sorrow, Diagonals, [dark|light], [life|death], Ghoulish, limited color palette,mechanical grotesques,high contrast,detailed backgrounds,wild untamed elements,bold silhouettes,grungy textures.
Negative prompt
modern, sci-fi, futuristic, centered, portrait, symmetry, monochrome, black and white, bright and cheerful,airy and light,simplistic,pastel-colored
Similar Models
AI Models for Image, Video & Text Generation
think xl is a base model for the Stable Diffusion XL 1.0 family listed on ModelTrends.ai, a read-only catalog of open source AI image, video and text models. Compare it with other Stable Diffusion XL 1.0 models, check its heat score to see how it is trending, and open it on PirateDiffusion or BitVector to try it.
More Stable Diffusion XL 1.0 modelsMore Stable Diffusion XL 1.0 Base Modelsrealisticeffectsbasebase model
Browse by Model Family
Text / LLM Models
411
Anima Models
509
Chroma Models
14
Flux Models
1,071
Flux 2 / Klein Models
1,237
MiniMax H3 Models
331
Hunyuan Models
197
Ideogram Models
20
Krea2 Models
674
Qwen Models
17
Qwen2 Models
36
Ltx2 Models
150
Stable Diffusion 1.5 Models
6,465
Stable Diffusion XL 1.0 Models
15,432
Zimage Models
804
Wan Models
919

Model
Trends
.ai
© ModelTrends.ai
|
Made in Japan
|
© 2026