Run Locally
animagineXL40_v4Zero.safetensors
6.46 GB · SafeTensor · fp16 · full
Downloads are served by Civitai. Some creators ask for a Civitai login first.


About This Model
STABLE DIFFUSION XL 1.0 · Base Models
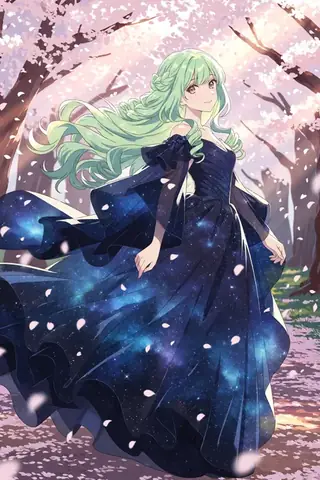
by CagliastroLab - a stylized anime followup to the series - Quality Enhancement Tags Add these tags at the start or end of your prompt: masterpiece, high score, great score, absurdres Recommended Negative Prompt lowres, bad anatomy, bad hands, text, error, missing finger, extra digits, fewer digits, cropped, worst quality, low quality, low score, bad score, average score, signature, watermark, username, blurry Optimal Settings Guidance: 5-7 Sampling Steps: 25-28 Preferred Sampler: Euler A
Creator notes
Please read our in-depth Guideline for prompting at
Overview
Animagine XL 4.0, also stylized as Anim4gine, is the ultimate anime-themed finetuned SDXL model and the latest installment of . Despite being a continuation, the model was retrained from with a massive dataset of 8.4M diverse anime-style images from various sources with the knowledge cut-off of January 7th 2025 and finetuned for approximately 2650 GPU hours. Similar to the previous version, this model was trained using tag ordering method for the identity and style training.
With the release of Animagine XL 4.0 Opt (Optimized), the model has been further refined with an additional dataset, improving stability, anatomy accuracy, noise reduction, color saturation, and overall color accuracy. These enhancements make Animagine XL 4.0 Opt more consistent and visually appealing while maintaining the signature quality of the series.
Changelog
- 2025-02-13 – Added Animagine XL 4.0 Opt and Animagine XL 4.0 Zero
-
Better stability for more consistent outputs
-
Enhanced anatomy with more accurate proportions
-
Reduced noise and artifacts in generations
-
Fixed low saturation issues, resulting in richer colors
-
Improved color accuracy for more visually appealing results
- 2025-01-24 – Initial release
Model Details
-
Developed by:
-
Model type: Diffusion-based text-to-image generative model
-
License:
-
Model Description: This is a model that can be used to generate and modify specifically anime-themed images based on text prompt
-
Fine-tuned from:
Usage Guidelines
The summary can be seen in the image for the prompt guideline.
1. Prompt Structure
The model was trained with tag-based captions and the tag-ordering method. Use this structured template:
1girl/1boy/1other, character name, from which series, rating, everything else in any order and end with quality enhancement
2. Quality Enhancement Tags
Add these tags at the end of your prompt:
masterpiece, high score, great score, absurdres
3. Recommended Negative Prompt
lowres, bad anatomy, bad hands, text, error, missing finger, extra digits, fewer digits, cropped, worst quality, low quality, low score, bad score, average score, signature, watermark, username, blurry
4. Optimal Settings
-
CFG Scale: 4-7 (5 Recommended)
-
Sampling Steps: 25-28 (28 Recommended)
-
Preferred Sampler: Euler Ancestral (Euler a)
5. Recommended Resolutions
6. Final Prompt Structure Example
1girl, firefly \(honkai: star rail\), honkai \(series\), honkai: star rail, safe, casual, solo, looking at viewer, outdoors, smile, reaching towards viewer, night, masterpiece, high score, great score, absurdres
Special Tags
The model supports various special tags that can be used to control different aspects of the image generation process. These tags are carefully weighted and tested to provide consistent results across different prompts.
Quality Tags
Quality tags are fundamental controls that directly influence the overall image quality and detail level. Available quality tags:
-
masterpiece
-
best quality
-
low quality
-
worst quality
Score Tags
Score tags provide a more nuanced control over image quality compared to basic quality tags. They have a stronger impact on steering output quality in this model. Available score tags:
-
high score
-
great score
-
good score
-
average score
-
bad score
-
low score
Temporal Tags
Temporal tags allow you to influence the artistic style based on specific time periods or years. This can be useful for generating images with era-specific artistic characteristics. Supported year tags:
-
year 2005
-
year {n}
-
year 2025
Rating Tags
Rating tags help control the content safety level of generated images. These tags should be used responsibly and in accordance with applicable laws and platform policies. Supported ratings:
-
safe
-
sensitive
-
nsfw
-
explicit
Training Information
The model was trained using state-of-the-art hardware and optimized hyperparameters to ensure the highest quality output. Below are the detailed technical specifications and parameters used during the training process:
Acknowledgement
This long-term project would not have been possible without the groundbreaking work, innovative contributions, and comprehensive documentation provided by Stability AI, Novel AI, and Waifu Diffusion Team. We are especially grateful for the kickstarter grant from Main that enabled us to progress beyond V2. For this iteration, we would like to express our sincere gratitude to everyone in the community for their continuous support, particularly:
-
: Our invaluable collaboration partner in model distribution and testing
-
Lesser Rabbit: For providing essential computing and research grants
-
: For developing the comprehensive open-source training framework
-
: For creating the industry-leading open-source Aesthetic Predictor 2.5
-
Early testers: For their dedication in providing critical feedback and thorough quality assurance
Contributors
We extend our heartfelt appreciation to our dedicated team members who have contributed significantly to this project, including but not limited to:
Model
-
-
-
Gradio
-
Relations, finance, and quality assurance
-
-
-
-
Data
-
-
-
-
Fundraising Are Now Open Again!
We're excited to introduce new fundraising methods through GitHub Sponsors to support training, research, and model development. Your support helps us push the boundaries of what's possible with AI.
You can help us with:
-
Donate: Contribute via ETH or USDT to the address below.
-
Share: Spread the word about our models and share your creations!
-
Feedback: Let us know how we can improve.
Donation Address:
ETH/USDT/USDC(e): 0xd8A1dA94BA7E6feCe8CfEacc1327f498fCcBFC0C
Github Sponsor:
Why do we use Cryptocurrency?:
When we initially opened fundraising through Ko-fi and using PayPal as withdrawal methods, our PayPal account was flagged and eventually banned, despite our efforts to explain the purpose of our pr
SHA256
F15812E65C2EA7F4E19CE37FB2A8445EB65C64DA450A508DD9C8F237C73F6BB8
ModelTrends.ai Model ID
#17097
Flag content
Example renders
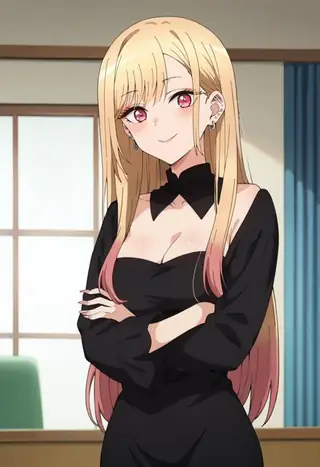
Prompts and settings shared by the people who made these renders on Civitai. Pick a render to see how it was made.
Settings
Sampler
Euler a
Steps
27
Guidance
3.5
Seed
79501396744697
Size
832x1216
Prompt
masterpiece, best quality, stylized, no humans, dog, animal focus, shiba inu, on stomach, wooden floor, fireplace, indoors, backlighting
Negative prompt
worst quality, displeasing, early, low quality, lowres, bad hands, mutated hands,
Settings
Sampler
Euler a
Steps
27
Guidance
3.5
Seed
958443423566352
Size
832x1216
Prompt
masterpiece, best quality, stylized, 1girl, solo, blonde hair, wavy hair, half updo, sidelocks, choppy bangs, blue eyes, smile, open mouth, looking at viewer, hand up, holding bottle, aqua thermos, visor cap, pink cap, transparent cap, t-shirt, white shirt, cropped jacket, denim jacket, black backpack, upper body, from below, dutch angle, blue sky, day, cloud, bird
Negative prompt
worst quality, displeasing, early, low quality, lowres, bad hands, mutated hands,
Settings
Sampler
Euler a
Steps
27
Guidance
3.5
Seed
189142163668301
Size
832x1216
Prompt
masterpiece, best quality, 1girl, solo, portrait, parted lips, patterned background, stylized
Negative prompt
worst quality, displeasing, early, low quality, lowres, bad hands, mutated hands,
Settings
Sampler
Euler a
Steps
27
Guidance
3.5
Seed
98189457879623
Size
832x1216
Prompt
masterpiece, best quality, 1girl, solo, mature female, low side ponytail, one hand on own chest, maid, maid outfit, white elbow gloves, upper body, from side, looking at viewer, smile, balcony, night, starry sky, dark, city, cityscape, stylized
Negative prompt
worst quality, displeasing, early, low quality, lowres, bad hands, mutated hands,
Settings
Sampler
Euler a
Steps
30
Guidance
7
Seed
2956350141
Size
832x1216
Prompt
hatsune miku, 1girl, artist:[lack|fuzichoco|lam \(ramdayo\)|kinta \(distortion\)|wlop|quasarcake|nixeu|happoubi jin|miyajima reiji|demizu posuka], solo, looking at viewer, colored eyelashes, long eyelashes, makeup, aqua eyes, red eyes, multicolored eyes, multicolored hair, circle formation, single vertical stripe, black theme, aqua theme, ocean, lying, on side, bioluminescence, black theme, night sky, dark, deep glow, partially submerged, legs, masterpiece, best quality, very aesthetic, absurdres, newest
<lora:animagineXL40_v4Zero_aqm_complete_v1:1>
Negative prompt
(worst quality, low quality, sketch:1.1), error, bad anatomy, bad hands, watermark, ugly, distorted, censored, lowres
Similar Models
AI Models for Image, Video & Text Generation
animagine4 xl is a base model for the Stable Diffusion XL 1.0 family listed on ModelTrends.ai, a read-only catalog of open source AI image, video and text models. Compare it with other Stable Diffusion XL 1.0 models, check its heat score to see how it is trending, and open it on PirateDiffusion or BitVector to try it.
More Stable Diffusion XL 1.0 modelsMore Stable Diffusion XL 1.0 Base Modelsillustriousanimeeffectsbasesdxlbase modelanimagine
Browse by Model Family
Text / LLM Models
411
Anima Models
509
Chroma Models
14
Flux Models
1,071
Flux 2 / Klein Models
1,237
MiniMax H3 Models
331
Hunyuan Models
197
Ideogram Models
20
Krea2 Models
674
Qwen Models
17
Qwen2 Models
36
Ltx2 Models
150
Stable Diffusion 1.5 Models
6,465
Stable Diffusion XL 1.0 Models
15,432
Zimage Models
804
Wan Models
919

Model
Trends
.ai
© ModelTrends.ai
|
Made in Japan
|
© 2026