Run Locally
AntiBlur.safetensors
656 MB · SafeTensor
Downloads are served by Civitai. Some creators ask for a Civitai login first.


About This Model
FLUX · LoRAs
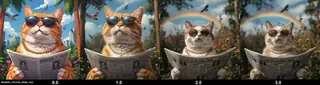
by VadimFedenko - So a weight of 0 will give a shallow DoF, typical for Flux generations. A default weight of 1.0 will reduce DoF to a hopefully more pleasant image, without significant changes in style and composition. The goal was to get DoF at weight 1.0 to be exactly how you'd expect it to be minor good bokeh here and there, without overdoing it as is often the case with Flux more on that later A weight of over 1.0 can be used to make shots with deep DoF. Lora can handle weights up to 3.0 and beyond without significant degradation in quality.
Creator notes
AntiBlur Lora has been significantly improved!
Improvements in new Lora:
-
DoF can be adjusted by Lora's weight.
So a weight of 0 will give a shallow DoF, typical for Flux generations.
A default weight of 1.0 will reduce DoF to a (hopefully) more pleasant image, without significant changes in style and composition. The goal was to get DoF at weight 1.0 to be exactly how you'd expect it to be: minor good bokeh here and there, without overdoing it as is often the case with Flux (more on that later)
A weight of over 1.0 can be used to make shots with deep DoF. Lora can handle weights up to 3.0 and beyond without significant degradation in quality.
-
Stylistically neutral
The dataset was made from hundreds of images created with Flux, so as not to take the style too far from the original model, while small number of real photos were used to keep Flux from degrading in composition (which is what happens when you train AI on it's own pictures)
-
Pairs well with Hires. fix
This Lora works well with hiresfix, allowing you to further increase the details and minimize shallow DoF. This was not the case with basic Flux, because by trying to do hires. fix to a blurred image with shallow DoF, it'd stil remain blurred with the same DoF effect. You just need the details to start appearing in the image, for hires.fix to improve them further.
-
No more Trigger words
Just connect the Lora and it'll do the job
-
Much less artifacts
Using Flux-generated images minimizes artifacts. I also trained a lot of models, and made a merge of the best of them, using (This smoothed out the edges of individual models that led to artifacts. Also, merging turned out to be especially useful for making the model more stylistically diverse.)
Why does Lora weight 655mb
It seemed to me that Lora with basically a "deep DoF" effect should be small, as it doesn't introduce a new style or concept, it just has to remove shallow DoF.
So I tried different Lora ranks, but as it turned out, information about the backgrounds is everywhere in the latent space, and the larger the model, the better results it gives. That's how I settled on the 128-rank Lora.
It's possible to isolate Lora's layers, and only use layers with DoF information in them, but as it turned out, information about DoF is scattered throughout most of the layers. For example, when generating macro shots, DoF is generated from the first layers. Information that appears in the backgrounds is really everywhere in the model, and constant shallow DoF is just the way training data was like for Flux. To make matters worse, Flux has a really poor understanding of DoF and blur conceptually. So not only it is present in much bigger amount than SD1.5/SDXL, it also provides much worse control over it than SD1.5/SDXL.
How was this Lora made
First, I put together a huge dataset with focus stacking techniques and deep DoF, on this I trained a new Lora. Next, using this Lora, I created images for a new dataset.
I've got several hundred variants of the "antiblur" Lora, selected the best ones each with their advantages, and combined them into a one well-balanced model.
What's next?
Since the higher the rank, the better the quality, the obvious way to improve the result would be to train a full finetune (and effectively touch every corner of the latent space, where there is information related to backgrounds), and then extract the Lora.
Another theoretical option is to find the "blur" or "dof" concept/weights in Flux latent space, and make a Lora out of inverted weights. This method wasn't very effective for dof control in SD-based models though.
As of now though I'm happy with the result. The model will remain my best effort for a while
SHA256
328F945688A91B13B5603550CB615CCB218F1400B3456BF409E41D5DBF065655
ModelTrends.ai Model ID
#15971
Flag content
Example renders
Prompts and settings shared by the people who made these renders on Civitai. Pick a render to see how it was made.
Settings
Sampler
Euler
Steps
12
Guidance
1
Seed
620724480
Size
1280x1920
Prompt
a city on the water beautiful landscape, sunset, woman, very intricate, very detailed, sharp, bright, colorful, <lora:Hand v2:0.5> <lora:Anti-Blur:1><lora:Insane Detail Slider:0.25> <lora:flux.1_lora_flyway_Epic-detail_v2:0.3> <lora:fluxenhancer:0.25> <lora:ROWER:0.6> <lora:flux-charmer-v1-1:0.4><lora:Vibrantly_Sharp_style_v.5:0.4> <lora:realanime:0.7> <lora:Chinese_Ink:0.3> chinese ink style
Settings
Sampler
Euler
Steps
12
Guidance
1
Seed
1067198525
Size
1280x1920
Prompt
city, street, beautiful misterious futuristic sci-fi cyberpunk landscape, golden hour, woman, very intricate, very detailed, sharp, colorful, <lora:Hand v2:1> <lora:Anti-Blur:1> <lora:Insane Detail Slider:0.5> <lora:Flux.1_Turbo_Detailer:0.6> <lora:flux.1_lora_flyway_Epic-detail_v2:0.6> <lora:flux-charmer-v1-1:0.4><lora:Vibrantly_Sharp_style_v.5:0.4> <lora:The_Dark_Side_Of_The_Future:0.7> <lora:Neurocore Anime Cyberpunk v2.0:0.6> A digital artwork in the style of cknc
Settings
Sampler
Euler
Steps
12
Guidance
1
Seed
2572308019
Size
1280x1920
Prompt
alien city beautiful cyberpunk landscape, cloudy sky, woman, very intricate, very detailed, sharp, bright, colorful, <lora:Hand v2:0.5> <lora:Anti-Blur:1><lora:Insane Detail Slider:0.25> <lora:flux.1_lora_flyway_Epic-detail_v2:0.3> <lora:fluxenhancer:0.25> <lora:ROWER:0.6> <lora:flux-charmer-v1-1:0.4><lora:Vibrantly_Sharp_style_v.5:0.4> <lora:bv-cybstyenh-v1_rank16_bf16:0.6> <lora:Anime_style:0.8> anime style
Settings
Sampler
Euler
Steps
12
Guidance
1
Seed
2194334330
Size
1280x1920
Prompt
city, street, beautiful misterious futuristic sci-fi cyberpunk landscape, rainy day, woman, very intricate, very detailed, sharp, colorful, <lora:Hand v2:1> <lora:Anti-Blur:1> <lora:Insane Detail Slider:0.5> <lora:Flux.1_Turbo_Detailer:0.6> <lora:flux.1_lora_flyway_Epic-detail_v2:0.6> <lora:flux-charmer-v1-1:0.4><lora:Vibrantly_Sharp_style_v.5:0.4> <lora:The_Dark_Side_Of_The_Future:0.8> <lora:Neurocore Anime Cyberpunk v2.0:0.7> A digital artwork in the style of cknc
Settings
Sampler
Euler
Steps
12
Guidance
1
Seed
983441819
Size
1280x1920
Prompt
an ice city beautiful landscape, bright sunny sky, woman, very intricate, very detailed, sharp, bright, colorful, <lora:Hand v2:0.5> <lora:Anti-Blur:1><lora:Insane Detail Slider:0.25> <lora:flux.1_lora_flyway_Epic-detail_v2:0.3> <lora:fluxenhancer:0.25> <lora:ROWER:0.8> <lora:flux-charmer-v1-1:0.4> <lora:Anime art - Variant 3:0.6> Anime art
Settings
Sampler
Euler
Steps
12
Guidance
1
Seed
2886003608
Size
1280x1920
Prompt
Indonesian beautiful landscape, bright luminous night, woman, very intricate, very detailed, sharp, bright, colorful, <lora:Hand v2:0.5> <lora:Anti-Blur:1><lora:Insane Detail Slider:0.25> <lora:flux.1_lora_flyway_Epic-detail_v2:0.3> <lora:fluxenhancer:0.25> <lora:ROWER:0.6> <lora:flux-charmer-v1-1:0.4>> <lora:Anime_style:0.8> anime style
AI Models for Image, Video & Text Generation
antiblur flux is a LoRA for the Flux family listed on ModelTrends.ai, a read-only catalog of open source AI image, video and text models. Compare it with other Flux models, check its heat score to see how it is trending, and open it on PirateDiffusion or BitVector to try it.
Browse by Model Family
Text / LLM Models
411
Anima Models
509
Chroma Models
14
Flux Models
1,071
Flux 2 / Klein Models
1,237
MiniMax H3 Models
331
Hunyuan Models
197
Ideogram Models
20
Krea2 Models
674
Qwen Models
17
Qwen2 Models
36
Ltx2 Models
150
Stable Diffusion 1.5 Models
6,465
Stable Diffusion XL 1.0 Models
15,432
Zimage Models
804
Wan Models
919

Model
Trends
.ai
© ModelTrends.ai
|
Made in Japan
|
© 2026