Bättre människors rörelse för MiniMax H3: naturliga, konsekventa kroppsrörelser
Ämne: Modeller

Av Captain
Publicerad 2026-10-01
Exempelrenderingar
Prompter och inställningar delade av personerna som gjorde dessa renderingar på Civitai. Välj en rendering för att se hur den gjordes.
Inställningar
Steg
12
Guidance
1
Storlek
1440x832
Prompt
For the target video, at 0.00 seconds into the target video, <Picture 1> (from [Shot 1]) is fully referenced.
integrated_multimodal_description: [Shot 1] The scene opens from <Picture 1>, preserving the three young women standing close together outdoors on a city street in winter, with European-style buildings and bare trees in the background under soft daylight. The camera has a natural handheld smartphone selfie shakiness, as if held by one of the girls at arm's length. The girl on the left with long straight black hair, a thick gray scarf, and a dark coat (S1) shivers slightly, pulling her scarf tighter around her neck with one hand. She looks directly into the camera lens with a bright, slightly complaining expression and says: <d>[Chinese] 今天有点冷啊,快看镜头啊!我们三个谁最好看啊?</d> The girl in the middle with chestnut-brown hair, a gray coat with bow buttons, and a white phone with a bear charm (S2) turns her gaze toward the camera, a playful smile forming on her lips. The girl on the right with a single braid, a gray sweater, and a gold necklace (S3) continues looking down at her dark phone, smiling faintly.
[Shot 2] At 00:05.000, the handheld camera wobbles slightly as the girls adjust their positions. The middle girl (S2) raises her hand in a cute peace-sign gesture beside her face, tilts her head playfully, and laughs with a cheeky, confident expression, saying: <d>[Chinese] 当然是我啦!</d> She winks one eye playfully after the line. The left girl (S1) reacts with a mock-offended expression, opening her mouth in playful protest and lightly nudging the middle girl's shoulder with her elbow. The right girl (S3) finally looks up from her phone toward the camera, an amused smile spreading across her face as she shakes her head at the other two.
[Shot 3] At 00:10.000, the right girl (S3) laughs warmly, her eyes crinkling with genuine amusement, and says in a light, scolding-but-affectionate tone: <d>[Chinese] 两个臭屁精!别拍了,赶快吃火锅去啦!</d> She puts her dark phone away into her coat pocket and starts to turn her body toward the street, gesturing with her hand for the others to follow. The middle girl (S2) giggles and lowers her peace-sign hand, while the left girl (S1) laughs and nods in agreement. The handheld camera begins to lower and tilt as if the person filming is putting the phone down, the three girls starting to move together toward the street, their shoulders brushing as they walk off, still laughing. The frame ends with a slight downward tilt as the selfie video concludes.
overall_soundscape:
Soft outdoor city street ambience continues throughout — distant traffic hum, occasional car passing, faint wind rustling through the bare tree branches, and the low murmur of pedestrians in the background. The girls' voices are clear and close, captured by the phone's microphone with a slight natural reverb from the open street. Subtle fabric rustling is audible as they adjust their coats and scarves, and the soft click of a phone lock button is heard near the end as the right girl puts her phone away. Light, cheerful laughter from all three girls overlaps naturally throughout the conversation.
non_diegetic_music:
N/A
Inställningar
Storlek
416x736
Prompt
the girl from example.png finally meets ryu from streetfighter in a dark ally. the girl proves far more superior in hand to hand combat since she is fighting in her own comfyui environment using a modified workflow.
Inställningar
Sampler
Euler
Steg
8
Seed
1765670026011586
Storlek
512x800
Prompt
[source image: https://civitai.red/images/141930523]
How the reference pictures align with the target video — <Picture 1> (from [Shot 1]) aligns with the end mark of the target video.
integrated_multimodal_description: [Shot 1] mvmt. Live-action, cinematic, a wide shot captures a bustling European city square under bright daylight, featuring richly textured historic buildings surrounding the open plaza, with the camera remaining static, perfectly framing the architectural grandeur. Overall, the scene maintains a pleasant, cheerful atmosphere underscored by upbeat, lively instrumental music. After a period of stillness, at 00:05.000, a distant, drawn-out female shriek of fright drifts faintly through the music. As the sound of the scream grows noticeably louder, overpowering the music's volume, the broom with a woman flying headfirst downwards streaks at high speed across the frame in half of a second from left to right straightly. As the broom carries her out of the frame to the right, her shriek diminishes in volume, gradually being swallowed again by the music. For several seconds, the frame returns to a static depiction of the city square with no significant action.
[Shot 2] At 00:07.500, Medium low-angle shot of the same woman who is now seated upright the broom, seemingly having regained control, the camera placed just in front of her broom handle. With a happy expression on her face, with her hair and scarf blowing in the air and her eyes and mouth widely opened in cry of mixed joy and fear, mingled with laughter, she rapidly flies over the city plaza while the camera tracking her non-stop flight.
overall_soundscape: The primary ambient sound is the distant murmur of the city crowd. The distinct, loud, and then fading shrieks punctuate the general urban noise. The laugh and cries of joy of the woman when she filmed in [Shot 2].
non_diegetic_music: Upbeat, lively instrumental music plays throughout, maintaining a consistent, cheerful tempo, though it is periodically overwhelmed by the screams.
Inställningar
Steg
10
Storlek
768x1216
Prompt
subject_definitions:
<Subject 1> is the veteran archmage, with his facial identity and clothing perfectly matching <Picture 1>, his voice weathered, gravelly, low, ancient and commanding.
<Picture 1> is the opening-frame anchor for [Shot 1], the archmage atop the cliff's edge analyzing the battlefield below.
<Audio 1> is the original background music track for this video, gradually building in intensity over its full duration.
summary:
[keyframe completion + audio reuse] The target video opens from <Picture 1>, the archmage atop the cliff. Over the full 15 seconds, he delivers a lengthy incantation while a storm gathers behind him and the camera arcs from his front to his back, all set to <Audio 1>, which builds gradually in intensity throughout without needing to align to any specific action.
retention_analysis:
<Picture 1> ([Shot 1] first frame): fully_preserved - the archmage, his staff, his aura, and the cliffside setting anchor the opening composition.
<Subject 1> (appears throughout [Shot 1]): fully_preserved - the archmage's identity, staff, and aura from <Picture 1> are retained throughout.
<Audio 1>: fully_copy - the track is reused in full, unmodified, as the complete non-diegetic score for the entire video, its gradual build not tied to any single visual cue.
detailed_description: Live-action, cinematic. [Shot 1] <Subject 1>, the veteran archmage matching <Picture 1>, remains atop the cliff's edge exactly as established, analyzing the battlefield below, his staff still crackling with stored power visualized as a swirling aura of light, the sky overcast but bright behind him. The camera begins directly in front of the mage, matching the vantage of <Picture 1>, and over the full 15 seconds of this shot, arcs slowly and continuously around him with small amplitude at slow speed, tracing a wide arc until it arrives directly behind him by the shot's end, the mage's position remaining fixed in place throughout while the camera alone circles around him. Below on the battlefield, distant armies clash in a chaotic, evenly matched struggle, neither side gaining ground, soldiers and war machines colliding in a constant, disorganized churn visible far below the cliff. From 00:00.000 to 00:05.000, a strong wind begins gusting from behind the mage, his robes snapping and billowing loudly with each fresh surge, the aura around his staff pulsing brighter in time with the wind's intensity. He (S1) begins his incantation, <d>[Japanese] 天をつらぬく黄金のことわり、我が身に降りよ。</d> A white subtitle reading "Golden law that pierces the heavens, descend upon me." appears at the bottom of the frame, slowly raising his staff overhead with both hands as he speaks, lifting it toward the sky in a deliberate, unhurried motion. From 00:05.000 to 00:09.000, the camera continues its slow arc as the overcast sky behind him churns and thickens, towering cumulonimbus clouds building rapidly upward from the wind's disturbance, darkening progressively as they grow, casting a spreading shadow across the chaotic, struggling battlefield below. He continues, his tone sharpening with authority, <d>[Japanese] 閃光のさばき、時よ止まれ。</d> A white subtitle reading "Judgment of the flash, let time stand still." appears at the bottom of the frame, his staff now held fully raised above his head, steady and unmoving. From 00:09.000 to 00:12.500, still arcing steadily around him, the towering clouds above have grown massive enough to plunge the battlefield into a deep, shifting shadow, static electricity visibly building within the cloud mass, faint flickers of inner light sparking intermittently through the dark clouds. He presses on, his voice rising with intensity, <d>[Japanese] いにしえの盟約、今ここに解き放たん。</d> A white subtitle reading "Ancient covenant, I release you here and now." appears at the bottom of the frame, the staff remaining held high overhead, unmoving, in anticipation of the final strike. From 00:12.500 to 00:15.000, the camera completes its arc, arriving directly behind the mage by the shot's end. As he reaches the incantation's final line, his staff's aura flares to its brightest yet, his robes whipping violently in the now-fierce wind, his expression fierce with concentration as he suddenly swings the staff downward in one sharp, decisive motion, bringing it down in front of himself as he delivers the final words, <d>[Japanese] ——きたれ、らいていの顕現!</d> A white subtitle reading "—Come forth, manifestation of thunder!" appears at the bottom of the frame, the shot ending the instant the incantation concludes and the staff completes its downward swing.
overall_soundscape: A low wind begins as a faint murmur and builds steadily into a powerful, sustained gust, the mage's heavy robes snapping and flapping loudly throughout. The distant, chaotic clatter of clashing armies and war machines rumbles faintly from the battlefield far below throughout the entire shot. Beginning around the midpoint, a deep, rolling rumble of distant thunder builds within the gathering clouds, growing steadily louder and closer, punctuated by faint crackling pops of static discharge as the storm intensifies toward the final line, culminating in a sharp whoosh as the staff swings down.
non_diegetic_music: <Audio 1> plays in full for the entire 15-second duration of the video, exactly as the source file, unmodified, its gradual build in intensity underscoring the mage's incantation and the gathering storm without being tied to any specific moment or action.
Inställningar
Steg
30
Storlek
640x1152
Prompt
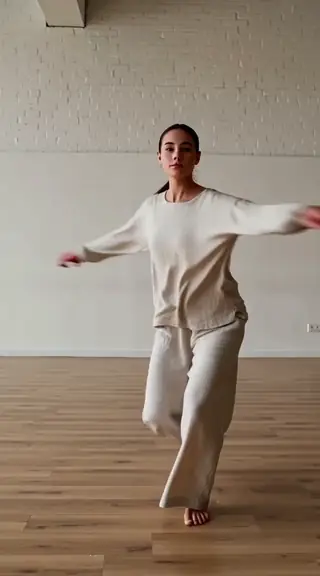
Eye-level continuous shot of a contemporary dancer in loose linen clothing executing a fluid, spinning turn on one foot, transitioning smoothly into a low spiral crouch onto the wooden floor, and rising back up into an extended reach. 360-degree torso rotation, continuous arm trailing, clean limb tracking, no morphing or phantom limbs.
Inställningar
Steg
8
Storlek
768x1216
Prompt
subject_definitions:
<Subject 2> is the spiker, the woman in <Picture 1>, with her facial features, clothing, and back number 3 perfectly referenced. She has a quiet, reserved voice.
<Subject 7> is the male coach in <Picture 2>, with his facial features, clothing, and penis proportions perfectly. He has the voice of an overweight man.
<Subject 8> is the Japanese gymnasium <Picture 3>, with its space, equipment, and lighting perfectly referenced.
Summary:
[Reference generation] This scene shows <Subject 2> entering the room where <Subject 8> is located and conversing with <Subject 7>, who is off-screen.
retention_analysis:
<Subject 2> (appears in [Shot 1]): fully_preserved - the woman's facial features, clothing, and back number 3 are retained.
<Subject 7> (appears in [Shot 1]): fully_preserved - the male coach's facial features and clothing and penis size are retained.
<Subject 8> (appears in [Shot 1]): fully_preserved - the gymnasium's space, equipment, and lighting are retained.
detailed_description:
The target video is set in a dimly lit, dusty Japanese gymnasium storage room from <Subject 8>, evoking a sense of unease and isolation.
[Shot 1] a medium wide shot establishes <Subject 8>, the gymnasium storage room, with a dimly lit interior and a dusty atmosphere. Accompanied by a sound like that of a heavy cart being moved, the metal sliding door slowly side opens. The camera begins a slow, ascending low-angle shot of <Subject 2>, the female volleyball team member, in her volleyball uniform. She appears tense and apprehensive. A quiet, unsettling piano melody begins to play softly in the background. Upon entering the room, she closes the sliding door behind her without turning around; the sound produced is like that of moving a heavy cart. <Subject 2> turns toward the camera and <Subject 2> (S1) says in a quiet, reserved voice, <d>[Japanese] コーチ、何かありましたか?</d> A white subtitle reading "Coach, is there something?" appears at the bottom of the frame. <Subject 7> (S2) voice (off-screen, low and calm) says: <d>[Japanese] 3番ちゃん、頑張ってるし、少し体をほぐしてあげようと思ってね</d> A white subtitle reading "3-chan, you’ve been working hard, so I thought I’d loosen up your body a little." appears at the bottom of the frame. <Subject 2> stands frozen, her back rounded with anxiety. Ventilation fan steady, rhythmic hum fills the silence.
overall_soundscape:
Soft indoor gymnasium room tone and a low ventilation hum.
non_diegetic_music:
Ambient noise and low-pitched drone sounds play faintly, accentuating a claustrophobic and oppressive atmosphere. Low-frequency vibrations create an unpleasant auditory sensation.
AdaptiveVisions Better Motion LoRA får MiniMax H3 (och LTX) karaktärer att röra sig naturligt och konsekvent. Lär dig om vikt, upplösning, antal steg och hur du skriver korta rörelse-promptar.
Översikt
Better Human Motion (v1.0-MH3) är en
LoRA
för
MiniMax H3
och
LTX
videomodeller som förbättrar kroppsrörelser: mjukare gång, gester och vändningar, med färre fel i lemmar och mer konsekvent anatomi mellan bilder. Den tränades på text-till-video men funkar även för bild-till-video.
Författarens rekommendationer: 720x1280, 15-30 steg, vikt 0.4-0.8 och korta meningar för att undvika att prompten flyter ihop.
Referens
Namn | Typ | Vad det är |
|---|---|---|
LoRA weight | 0.4-0.8 | 0.6 standard. |
Resolution | 720x1280 | Porträttvideo; landskap funkar med samma pixelantal. |
Steps | 15-30 | |
Prompt style | short sentences | En handling per mening. |
Mode | T2V / I2V | Båda. |
AD

Inget att installera - kör AI-modeller i molnet
BitVector Prism är det enklaste sättet att komma igång: välj en modell, skriv en prompt och generera i en ren webbapp, utan någon installation alls. BitVector finns också på Discord och på webben (SpyGlass).
Steg för steg
- Skriv H3-prompten med en eller två tydliga handlingar i korta meningar.
- 720x1280, 20 steg.
- Håll ljudbilden enkel så rörelsen får fokus.
- Höj till 0.8 för dans eller sport; sänk till 0.4 för subtila gester.
Exempel
Gång
integrated_multimodal_description: [Shot 1] A woman in a trench coat walks along a rainy pier toward the camera. She adjusts her collar. She stops and looks at the sea.
overall_soundscape: Rain, waves, footsteps on wood.
non_diegetic_music: N/A
Better Motion 0.6
Dans
integrated_multimodal_description: [Shot 1] A dancer in a studio spins once and lands in a low pose. Mirrors behind. Camera static.
overall_soundscape: Soft shoes on wood floor.
Better Motion 0.8
Kreativ idé: anime möter live action
integrated_multimodal_description: [Shot 1] A young woman in a hoodie faces a martial artist in a dark alley. She steps forward and blocks a slow punch. Camera handheld.
Better Motion 0.7
Tips
- Beskriv rörelsens väg (går från vänster till höger) istället för adjektiv.
- Fungerar ihop med Combat LoRA på lägre vikter för actionscener.
- För I2V, se till att startbilden redan visar posen som börjar rörelsen.
- Kortare klipp (5 s) håller sig mer konsekventa.
Felsökning
Prompt flyter ihop (handlingar smälter samman)
Varför det händer
Långa sammansatta meningar.
Så löser du det
Dela upp i korta meningar, en handling per mening.
Stel rörelse
Varför det händer
Vikten är för låg.
Så löser du det
0.7-0.8.
AD

Inget att installera - kör AI-modeller i molnet
PirateDiffusion finns bara på Telegram och är byggt för proffs: tusentals modeller, LoRA och arbetsflöden som styrs med chattkommandon, med obegränsad generering till ett fast pris.

Frågor
LTX också?
Ja, det finns en LTX-variant.
Trigger?
Ingen.
Länkar och källor
Modeller i den här guiden
Skriven av
Captain
Relaterade guider
Modeller
MiniMax H3 Combat BASE V2: stridsrörelse, påverkan och drama
FourBunnys Combat BASE LoRA för MiniMax H3 förbättrar stridskoreografi, träffreaktioner, kontinuitet och fysisk orsak och verkan, och hjälper också till med dialogscener. Lär dig prfight1, prfin1 och prslow1 triggers och hur du iscensätter en scen.
Av Captain
2026-10-01
Modeller
GalaxyAce LoRA för MiniMax H3: lågkvalitativt telefonmaterial från tidigt 2010-tal
aiguilds GalaxyAce LoRA återskapar utseendet från en Samsung Galaxy Ace-telefonkamera: dämpade färger, sensorbrus, rullande slutare och vardaglig inramning. Lär dig styrkor per modell, prompts och idéer för hittat material.
Av Captain
2026-10-02
Modeller
MiniMax H3 Turbo LoRAs: 4-8 stegs video med larryvrh-paketet
MiniMax H3 Turbo LoRA-paketet (larryvrh 4-stegs och vänner) minskar antalet steg för videogenerering från tiotals till några få. Lär dig stegantal, samplers och styrkor för varje variant, plus hur du promptar H3 för snabba, rena klipp.
Av Captain
2026-10-01
Modeller
Passionerad Kyss LoRA för MiniMax H3: övertygande romantiska scener mellan vuxna
kermitfrog1202:s LoRA förbättrar kysscener i MiniMax H3-video. Lär dig trigger-meningen, styrkevärdena för olika par som författaren hittade och hur man iscensätter en smakfull romantisk scen.
Av Captain
2026-10-01
Promptning
Prompting MiniMax H3: text till video, bild till video, referensvideo och ljud
Hur du styr MiniMax H3 från ett chattkommando: receptet WHO + WHERE + ACTION + CAMERA + SOUND för text till video, animera en stillbild med bild till video, ge varje referensbild en uppgift i referensläge och få ren dialog istället för mumlande. Med kopiera-och-försök-promptar och författarens PDF.
Av Mark White
2026-09-20
Fler guider

Modeller
FLUX.1 Dev: hur du promptar det, bästa inställningarna och kreativa idéer
En praktisk guide till FLUX.1 Dev från Black Forest Labs: naturligt språk för prompts, styrning och steginställningar, LoRA-stapling, textrendering och promptidéer som spelar på dess styrkor.
Av Captain
2026-09-30

Modeller
Stable Diffusion XL 1.0: prompts, inställningar och vad den fortfarande är bäst på
Hur du får ut mest av den officiella SDXL 1.0 basmodellen: inbyggda upplösningar, CFG- och sampler-inställningar, refiner, negativa prompts och idéer för stilar där SDXL fortfarande glänser.
Av Captain
2026-10-01

Modeller
Stable Diffusion 1.5: den klassiska modellen, rätt promptad
Stable Diffusion 1.5 är fortfarande värd att känna till: rätt upplösning, CFG och sampler, hur du använder dess stora bibliotek av LoRAs och embeddings, och kreativa promptidéer som passar en 512-pixelmodell.
Av Captain
2026-10-02

Modeller
FLUX.2 Dev: promptning av den senaste modellen från Black Forest Labs
FLUX.2 Dev ger längre prompts, bättre text, starkare realism och redigering med flera referenser. Den här guiden täcker turboarbetsflödet, styrning och upplösningsinställningar, promptstruktur och idéer som använder dess nya styrkor.
Av Captain
2026-10-03

Modeller
Qwen-Image: långa prompts, perfekt text och tvåspråkiga affischer
Qwen-Image är modellen du ska använda när orden i bilden är viktiga. Lär dig hur du skriver långa beskrivande prompts, återger engelska och kinesiska texter korrekt, ställer in CFG och steg, och utforskar kreativa idéer med mycket layout.
Av Captain
2026-09-29

Modeller
SDXL-Lightning: fyrastegs-generering på vilken SDXL-checkpoint som helst
ByteDance:s SDXL-Lightning LoRA förvandlar en 30-stegs SDXL-rendering till en på 4 steg. Lär dig antal steg, vilken CFG du måste använda, samplern och hur du kombinerar den med dina favoritcheckpoints och stil-LoRAs.
Av Captain
2026-09-30

Model
Trends
.ai
© ModelTrends.ai
|
Tillverkad i Japan
|
© 2026