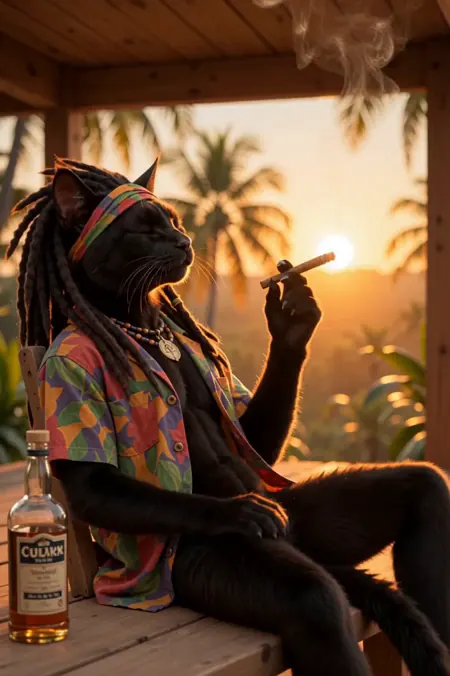
Autouppspelning
Kör lokalt
Furry enhancer Video H3 V2.54.safetensors
887 MB · SafeTensor · bf16
Showcase H3 V2.54.zip
125 MB · Other
Nedladdningar sköts av Civitai. Vissa skapare kräver att du först loggar in på Civitai.


Om denna modell
MINIMAX H3 · LoRA
by freek22 - Furry Enhancer Video
Skaparens anteckningar
This Lora is made to enhance the ability / quality to create anthro and furry
but it works also for all kind of other fantasy creatures and animals too
the range that it can handle for example the Wan 2.2 V2 Lora is from comic and drawing towards real photos .
i made the lora for Hunyuan Video , WAN 2.1 and 2.2 (SFW and NSFW)
Furry Enhancer Hunyuan V1
The Hunyuan Video version is trained for Text to Video (T2V) but i also tested it on Image to Video its also working with it very good but not made for that.
All example images for the Hunyuan Video are made T2V
Its also compatible with
Wan 2.1 I2v and T2V V1
The Wan 2.1 has 2 different models
I2V and T2V
the image to video is in most cases the model of choice for Wan
for the Text to Video Variant please read the description.
Its also compatible and will for sure increase the quality especially in the NSFW Area.
I also tested the I2V Lora with Wan 2.2 it seems to enhance the result too but very experimental
Wan 2.2 I2V and T2V V1
This enhancer version is for its splitted in basically 2 Loras: low and high noise
both loras for I2V are trained on the same dataset. I its my own dataset before i trained with the wan 2.1 Lora but add more pictures and videos
it's completely synthetic so no real persons or art is used for the dataset.
whats the pros of this lora compared to the wan 2.1?
-
more consistent
-
more specimen
better in sfw and nsfw
i recommend using both loras and use the workflow in the training folder Note: your resolution needed to set between 0.4 (480P) and 0.92 (720p) overwise the lora generate backscreens or other failures.
for strength i prefer the full 1.0 strength its tested
its tested with the original wan 2.2 model
also in a short test with my model (use only the high noise version with that model)
for technical data about Wan 2.2 visit there official site
V2 Furry Enhancer High Noise
Changes compared to V1
-
more consistent
-
more specimen
-
better overall movements
-
more stable overall
-
way better with comic and anime than V1
better in sfw and nsfw
i recommend using the V1 Version of the
Note: I used for example the old workflow for this model to compare V1 with V1 if you like the newest workflow download the training folder.
Important for this workflow is to keep the resolution between 0.4 and 0.92 (480p - 720p)
V3 High Noise and Low Noise
This enhancer version is for Wan 2.2
its trained my own dataset
it's completely synthetic so no real persons or art is used for the dataset.
the biggest change in this dataset is its now completely trained on videos
Changes compared to V2
-
trained now on over 650 Videos
-
better overall movements
-
more emotions
-
way better with comic and anime than V1 and V2
better in sfw and nsfw
for this Version there is also an newtrained Low Noise Model
LTX2.3 Version (WIP Preview V0.1)
this is an preview version of the first attempt to train the ltx 2.3 model with a very limited dataset
so it's more like an technical demonstration / trial than a fully trained lora.
So don't expect best results yet it's highly experimental.
for workflow i have also added an experimental workflow.
LTX2.3 Version V1 Lora Pack
This is the First full Release Version of the LTX Version of Furry Enhancer Video.
Better to say it's an model pack because
V1.1 is made based on ltx 2.0 training setup so best for the LTX 2.0 model
V1.215 its the main model trained specifically for the ltx 2.3 Version so start usually with that lora
V1.22 More advanced in training but has sound issues.
V1.3 experimental (wip) model trained in different training modes (heavy sound issues)
you find the used workflows and the different model versions in the "training folder"
the loras are tested on the dev version and the distilled variant.
what has changed to preview?
-
Trained on the full video database (V1.2 and up) at around 700 videos instead of only 40 videos
-
Also trained on my photo database of ratatoskr overall over 10k pictures
-
Trained for i2v and t2v
-
better overall knowledge and movement .
Note: this is still in development because most of the trained videos are based on my wan2.2 database so its planned to train an v2 this year with video output of that model.
also i don't have my own workflow done yet so it depends on other workflow don by afroman4peace and
LTX2.3 Version V2.4
I have decided to retrain the dataset on a far advanced system now its trained on a server with an rtx6000 pro blackwell for more than a week 24/7 (and yes this was expensive)
so what has changed from V1 to V2.4?
-
the trained video resolution is now at 720P constant
-
image training did improved from 1024p to 1536p
-
added 120 new sound videos for training especially for speech and jaw movements.
-
seperated videos with sound and not sound and trained in different databases
-
trained for T2V and I2V in stages so its nearly equally trained for both now
-
added new pictures to database too but more important overworked the captions fitting better for video training
For settings and workflow i have added my example videos in the training folder the images and some videos has the metadata just put them into comfy
on my workflows was the loral at best between 0.8 and 1.0
the lora is trained on the dev model but also tested for the distilled version
for now still don't have my own workflow done yet so it depends on other workflow don by afroman4peace and
please support my work with an like and look on my other loras and models too
the newest workflow download the training folder.
in all videos the metadata is also included just download the video and put it into Comfy
Important for this workflow is to keep the resolution between 0.4 and 0.92 (480p - 720p)
if you like to support me please give a like and Check out my other models.
Making such loras take a huge amount of cost and time please support my work with a like.
and please check out my other models and loras too
SHA256
FC1E06352B7CC8689DAA539CA3064AF57D3265A4ADA995C055F4FE66CDBA3AB0
ModelTrends.ai modell-ID
#26746
Rapportera innehåll
Exempelrenderingar
Prompter och inställningar delade av personerna som gjorde dessa renderingar på Civitai. Välj en rendering för att se hur den gjordes.
Inställningar
Storlek
1152x640
Prompt
Anthropomorphic English bulldog soldier in a World War 1 trench, late 1910s. He has short stocky build, wrinkled grey-brown and white fur, heavy jowls, and a deeply sad, weary expression. He wears a muddy British khaki uniform, puttees, and a dented Brodie helmet resting beside him.
He sits on a wooden crate inside a dim, damp dugout, writing slowly in a small leather-bound diary with a pencil. Soft rain falls outside the trench entrance. The camera slowly pushes in on his face and the open diary pages.
An epic, low, somber male narrator voice says: "War never changes."
Cinematic lighting, muted desaturated colors, detailed wet fur and fabric textures, coherent slow motion over 15–20 seconds, heavy emotional atmosphere, no glory or action — only quiet exhaustion.
Inställningar
Steg
30
Seed
1535164946
Storlek
1280x704
Använd vikt
0.7
Prompt
A 15-second photorealistic cinematic video. An anthropomorphic grey wolf scientist in a cluttered steampunk laboratory filled with brass pipes, glowing gauges, gears, and warm gaslight. He wears a worn leather apron over a white shirt with rolled sleeves and brass goggles pushed up on his forehead. He carefully assembles a detailed mechanical bird made of polished brass, copper, and small clockwork parts on a wooden workbench. While adjusting the wings and gears, he speaks in a thoughtful, serious voice:
“At what point does it stop being just a machine? When the gears move on their own… when it reacts… or only when it wants to keep moving? Where exactly does life begin?”
He turns a small brass component, watches the mechanical bird’s wing twitch slightly, and stares at it with quiet intensity. Soft steam rises in the background. Realistic fur, metal reflections, and warm steampunk lighting. 15 seconds exact
Inställningar
Steg
20
Seed
393546382
Storlek
704x960
Använd vikt
0.7
Prompt
A single continuous cinematic shot in a sunlit courtyard with stone arches and banners. Four women in short black cardigans, white shirts, striped ties, short pleated skirts, and thigh-high black stockings stand in a close group holding thick books. The girl on the far right (long dark wavy hair, hoop earrings) leans in and whispers to the other three with a mischievous smile: “I heard the anatomy professor is EIGHT inches. Some of the other girls saw it."
The blonde woman says "No, he's more like nine. That's why I'm walking so funny today. Man am I sore." The blonde girl stretches and groans.
The other girls all turn and look at her in shock. They are scandalized.
Smooth continuous camera movement, no cuts, natural golden-hour lighting, highly detailed, realistic skin and fabric textures, dynamic expressions and motion.
Inställningar
Storlek
1056x704
Prompt
AA beautiful and highly detailed 30-second anime-style video of an anthropomorphic female red panda sitting in a small wooden boat on a calm lake at night. She has soft reddish-brown fur, cream-colored facial markings, large round ears, and a long fluffy ringed tail. She wears an elegant traditional geisha kimono in deep crimson and gold with delicate floral patterns, her hair styled in an elaborate updo decorated with ornate hairpins and silk flowers. Soft white makeup accents her face while keeping her red panda features clear.
The boat drifts gently near an ancient Japanese temple with glowing paper lanterns and a tall pagoda reflected on the water. Dozens of floating candles and small paper lanterns drift across the dark lake surface, their warm light shimmering on the gentle ripples. Above, an epic night sky stretches wide — a massive full moon, dense fields of stars, and soft purple-blue clouds edged with silver light.
She sings a gentle Japanese-style song in a clear, soft voice, lips moving naturally with the melody:
“Yoru no mizu ni, hikari ga mau
Tsuki ga michite, kokoro yasuragu
Kaze ga sasayaku, furusato no uta
Watashi no koe de, yume o tsunagu…”The camera slowly circles the boat in a smooth, cinematic motion, keeping her fully in frame while revealing the temple, floating lights, and vast sky. Soft moonlight and warm candle glow, highly detailed fur and fabric, serene and atmospheric.
Inställningar
Steg
28
Seed
1357918036
Storlek
1280x704
Använd vikt
0.65
Prompt
A static, locked wide shot of a muddy medieval tournament field, focused on two knights in polished steel plate armor riding massive, scaled T-Rexes instead of horses. The first knight, wearing red plumes, rides his T-Rex forward while the second knight, wearing blue plumes, charges from the right to meet him. They clash lances mid-stride, the wooden shafts snapping on impact, then both T-Rexes lunge backward in recoil before settling into a neutral stance. The camera never moves—no push in, no handheld, no zoom, no dolly. Overcast natural light, muddy ground, distant crowd blurred in the background. Audio: the heavy thud of T-Rex footsteps on mud, the sharp crack of lances breaking, the low guttural growls of the dinosaurs, ambient crowd murmur. No music, no other text.
Inställningar
Storlek
736x1088
Prompt
hree anthropomorphic cat adventurers standing on a stone path at the edge of a massive red-rock canyon, viewed from behind. Left: black-furred cat in a green cloak and leather backpack, holding a wooden staff. Middle: orange tabby cat in a blue hooded cloak with a small satchel. Right: white/grey cat in a red cloak and heavy backpack, sword on his back. They overlook a breathtaking canyon filled with ancient stone ruins carved into the cliffs, a long arched bridge spanning the chasm, a winding river far below, cascading waterfalls, and red banners with golden sun symbols hanging from the walls. Bright blue sky with soft white clouds. Camera starts behind them at eye level. Soft wind moves their cloaks and fur. The black cat slowly raises his staff and points toward the distant bridge. The orange cat turns his head slightly toward the others. The white cat shifts his weight and takes the first step forward. They begin walking down the path together, cloaks billowing. Camera slowly pushes forward and slightly rises, revealing more of the vast canyon and ruins. Distant birds glide between the cliffs. Sunlight glints off the river and stone. Ends as they continue toward the bridge, the full scale of the world opening in front of them. Epic atmosphere, rich colors, cinematic lighting, high detail, smooth motion, no text, no watermark.
Inställningar
Steg
23
Seed
17874010
Storlek
704x960
Använd vikt
0.7
Prompt
a anthro woman is standing in her kitchen holding a red mug.
(0-10s) she waves at the viewer and said in deep mature accent 'hello there! you got here just in time. David just left for work... and now....' she place her red mug down on the countertop behind her and began to grab her button shirt. she said in a seductive tone 'since it's just us you and me... we can get started" she then rips open her own button shirt very hard and fast exposing her breasts and nipples. breast slightly bounces by this.
(10-15s) night club rap music instantly plays here. instant transition cuts to a male pov in bedroom where the anthro woman is completely nude and she is riding the man, her breasts bounce rhythmically as she moves up and down rapidly on his penis. The motion is fast and continuous, with fluid body mechanics and natural weight transfer. Smooth, loopable animation with consistent energy. Static camera framing the couple closely, focusing on the vertical movement. Soft, warm lighting highlights the detailed animation style. High quality, 4k, detailed artwork, smooth motion. anthro tyrannosaurus), (purple scales), (purple skin:1.3), (tan chest:1.3), (tan skin:1.3), mature female, (huge breasts:1.2), (bottom heavy:1.2), (small waist)
romantic music playing in background
Inställningar
Storlek
1056x704
Prompt
Cinematic 15-second sequence. A powerful anthro tiger stands alone on a high mountain peak at sunrise, orange-black fur glowing in the golden light, traditional martial arts robes flowing in the wind. He launches into a fierce kung fu routine — sharp punches, spinning kicks, rapid strikes, and balanced stances — each movement precise and explosive. Dust and small rocks kick up under his feet as he flows from form to form. Wide epic shots of the mountain range, then dynamic circling camera that follows his strikes, ending on a strong final pose silhouetted against the rising sun. Epic orchestral music driving the intensity. High detail, dramatic lighting, powerful atmosphere.
Liknande modeller
AI-modeller för bild-, video- och textgenerering
furry enhancer h3 är en LoRA för familjen MiniMax H3, listad på ModelTrends.ai, en skrivskyddad katalog över AI-modeller med öppen källkod för bild, video och text. Jämför den med andra MiniMax H3-modeller, se dess hettapoäng och prova den på PirateDiffusion eller BitVector.
Fler MiniMax H3-modellerFler MiniMax H3 LoRAvideoanimefurryeffectsartstylesphotorealisticdogcreature
Bläddra efter modellfamilj
Text / LLM-modeller
411
Anima-modeller
509
Chroma-modeller
14
Flux-modeller
1,071
Flux 2 / Klein-modeller
1,237
MiniMax H3-modeller
331
Hunyuan-modeller
197
Ideogram-modeller
20
Krea2-modeller
674
Qwen-modeller
17
Qwen2-modeller
36
Ltx2-modeller
150
Stable Diffusion 1.5-modeller
6,465
Stable Diffusion XL 1.0-modeller
15,432
Zimage-modeller
804
Wan-modeller
919

Model
Trends
.ai
© ModelTrends.ai
|
Tillverkad i Japan
|
© 2026