Ejecutar en local
dreamshaper_631BakedVae_65091.safetensors
1.99 GB · SafeTensor · fp16 · pruned
dreamshaper_631BakedVae_65090.safetensors
5.55 GB · SafeTensor · fp16 · full
Las descargas las sirve Civitai. Algunos creadores piden iniciar sesión en Civitai primero.
AD


Instalar / Ejecutar en Graydient
Requiere membresía
<classic-dreamshaper631>
Sobre este modelo
STABLE DIFFUSION 1.5 · Modelos base
Notas del creador
DreamShaper - V∞!
Please check out my other , including SDXL ones!
Check the version description below (bottom right) for more info and add a ❤️ to receive future updates.
Do you like what I do? Consider supporting me on 🅿️ to get exclusive tips and tutorials, or feel free to ☕
🎟️
Join my
For LCM read the version description.
Available on the following websites with GPU acceleration:
-
-
-
-
-
-
(CPU is slow but free).
New Negative Embedding for this: .
Message from the author
Hello hello, my fellow AI Art lovers. Version 8 just released. Did you like the cover with the ∞ symbol? This version holds a special meaning for me.
DreamShaper started as a model to have an alternative to MidJourney in the open source world. I didn't like how MJ was handled back when I started and how closed it was and still is, as well as the lack of freedom it gives to users compared to SD. Look at all the tools we have now from TIs to LoRA, from ControlNet to Latent Couple. We can do anything. The purpose of DreamShaper has always been to make "a better Stable Diffusion", a model capable of doing everything on its own, to weave dreams.
With SDXL (and, of course, DreamShaper XL 😉) just released, I think the "swiss knife" type of model is closer then ever. That model architecture is big and heavy enough to accomplish that the pretty easily. But what about all the resources built on top of SD1.5? Or all the users that don't have 10GB of vram? It might just be a bit too early to let go of DreamShaper.
Not before one. Last. Push.
And here it is, I hope you enjoy. And thank you for all the support you've given me in the recent months.
PS: the primary goal is still towards art and illustrations. Being good at everything comes second.
Suggested settings:
- I had CLIP skip 2 on some pics, the model works with that too.
- I have ENSD set to 31337, in case you need to reproduce some results, but it doesn't guarantee it.
- All of them had highres.fix or img2img at higher resolution. Some even have ADetailer. Careful with that tho, as it tends to make all faces look the same.
- I don't use "restore faces".
For old versions:
- Versions >4 require no LoRA for anime style. For version 3 I suggest to use one of these LoRA networks at 0.35 weight:
-- (the girls with glasses or if it says wanostyle)
-- (if it says mksk style)
-- (not used for any example but works great).
LCM
Being a distilled model it has lower quality compared to the base one. However it's MUCH faster and perfect for video and real time applications.
Use it with 5-15 steps, ~2 cfg. IT WORKS ONLY WITH LCM SAMPLER (as of December 2023, Auto1111 requires an external plugin for it).
Comparison with V7 LCM
NOTES
-
Version 8 focuses on improving what V7 started. Might be harder to do photorealism compared to realism focused models, as it might be hard to do anime compared to anime focused models, but it can do both pretty well if you're skilled enough. Check the examples!
-
Version 7 improves lora support, NSFW and realism. If you're interested in "absolute" realism, try .
-
Version 6 adds more lora support and more style in general. It should also be better at generating directly at 1024 height (but be careful with it). 6.x are all improvements.
-
Version 5 is the best at photorealism and has noise offset.
-
Version 4 is much better with anime (can do them with no LoRA) and booru tags. IT might be harder to control if you're used to caption style, so you might still want to use version 3.31.
-
V4 is also better with eyes at lower resolutions. Overall is like a "fix" of V3 and shouldn't be too much different.
-
Results of version 3.32 "clip fix" will vary from the examples (produced on 3.31, which I personally prefer).
-
I get no money from any generative service, but you can buy me a coffee.
-
You should use 3.32 for mixing, so the clip error doesn't spread.
-
Inpainting models are only for inpaint and outpaint, not txt2img or mixing.
Original v1 description:
After a lot of tests I'm finally releasing my mix model. This started as a model to make good portraits that do not look like cg or photos with heavy filters, but more like actual paintings. The result is a model capable of doing portraits like I wanted, but also great backgrounds and anime-style characters. Below you can find some suggestions, including LoRA networks to make anime style images.
I hope you'll enjoy it as much as I do.
Official HF repository:
SHA256
853E7E85C46BE9AD4815666CD335545DF32DAB5E0D22AFE5CCC6AD9BDA834B52
ID de modelo de ModelTrends.ai
#2194
Denunciar contenido
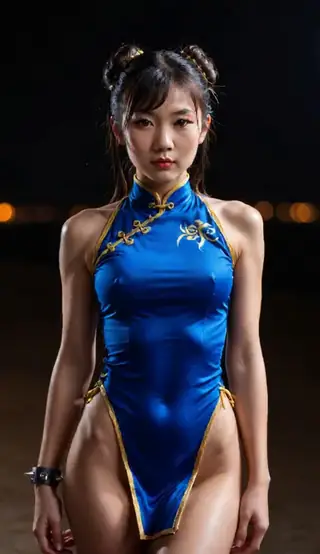
Renders de ejemplo
Prompts y ajustes compartidos por quienes hicieron estos renders en Civitai. Elige un render para ver cómo se hizo.
Ajustes
Sampler
DPM++ SDE Karras
Pasos
28
Guidance
7
Semilla
132340236
Tamaño
512x896
Clip skip
2
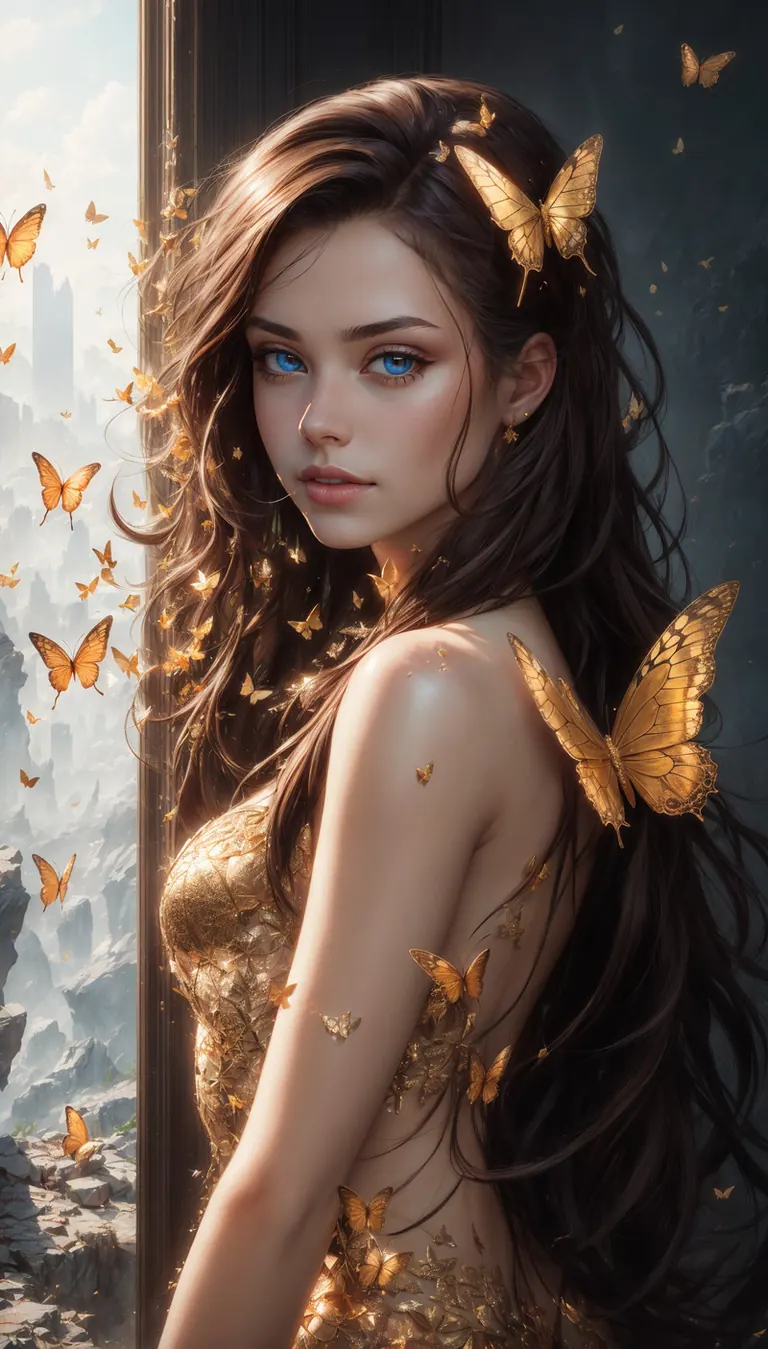
Prompt
8k portrait of beautiful cyborg with brown hair, intricate, elegant, highly detailed, majestic, digital photography, art by artgerm and ruan jia and greg rutkowski surreal painting gold butterfly filigree, broken glass, (masterpiece, sidelighting, finely detailed beautiful eyes: 1.2), hdr, <lora:more_details:0.2>
Prompt negativo
BadDream, FastNegativeV2
Ajustes
Sampler
DPM++ SDE Karras
Pasos
30
Guidance
12
Semilla
605128427
Tamaño
512x768
Clip skip
2
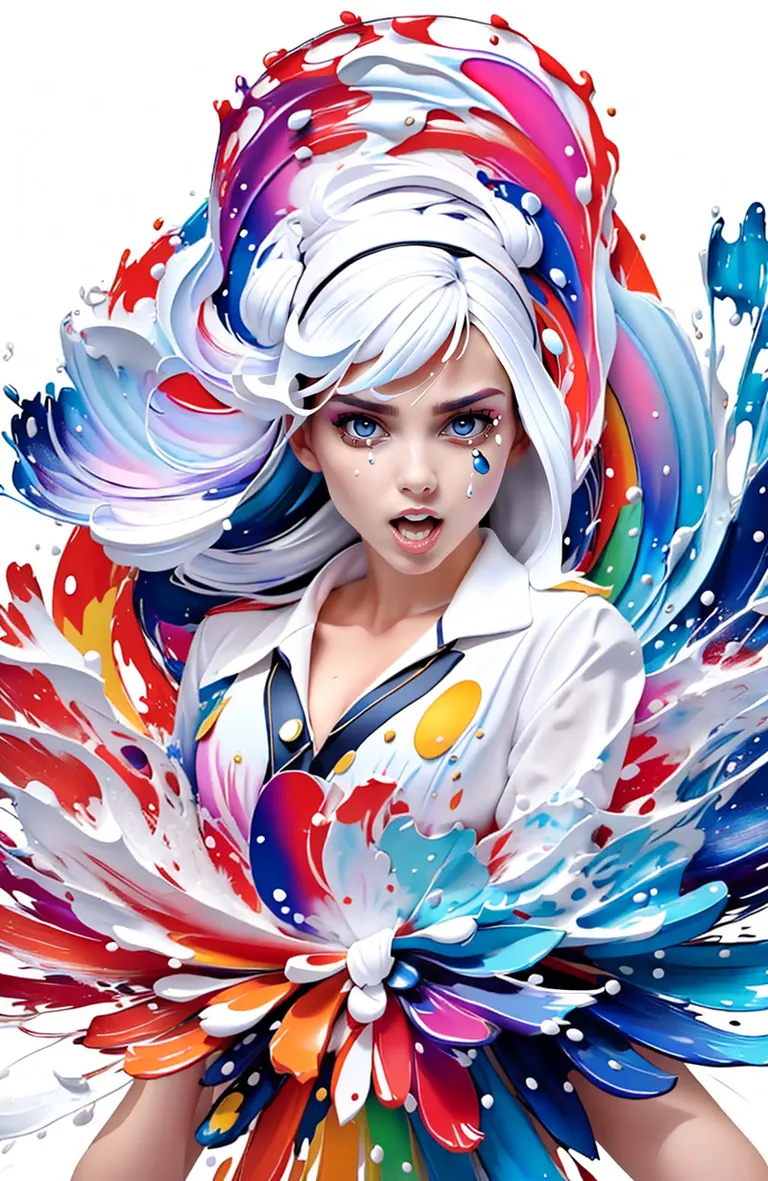
Prompt
girl with a pretty face, white hair, purple eyes,(((sexy school uniform))), wearing a stylish very sexy school uniform, with a funny expression on her face.
Prompt negativo
(worst quality:2), (low quality:2), (normal quality:2), lowres, normal quality, ((monochrome)), ((grayscale)), skin spots, acnes, skin blemishes, bad anatomy, girl, loli, young, large breasts, red eyes, muscular,badquality, badhandv4, bad-artist, bad_prompt_version2, ng_deepnegative _v1_75t ,deformed, logo ,text
Ajustes
Sampler
DPM++ 2M SDE Karras
Pasos
43
Guidance
12
Semilla
380341973
Tamaño
512x768
Clip skip
2
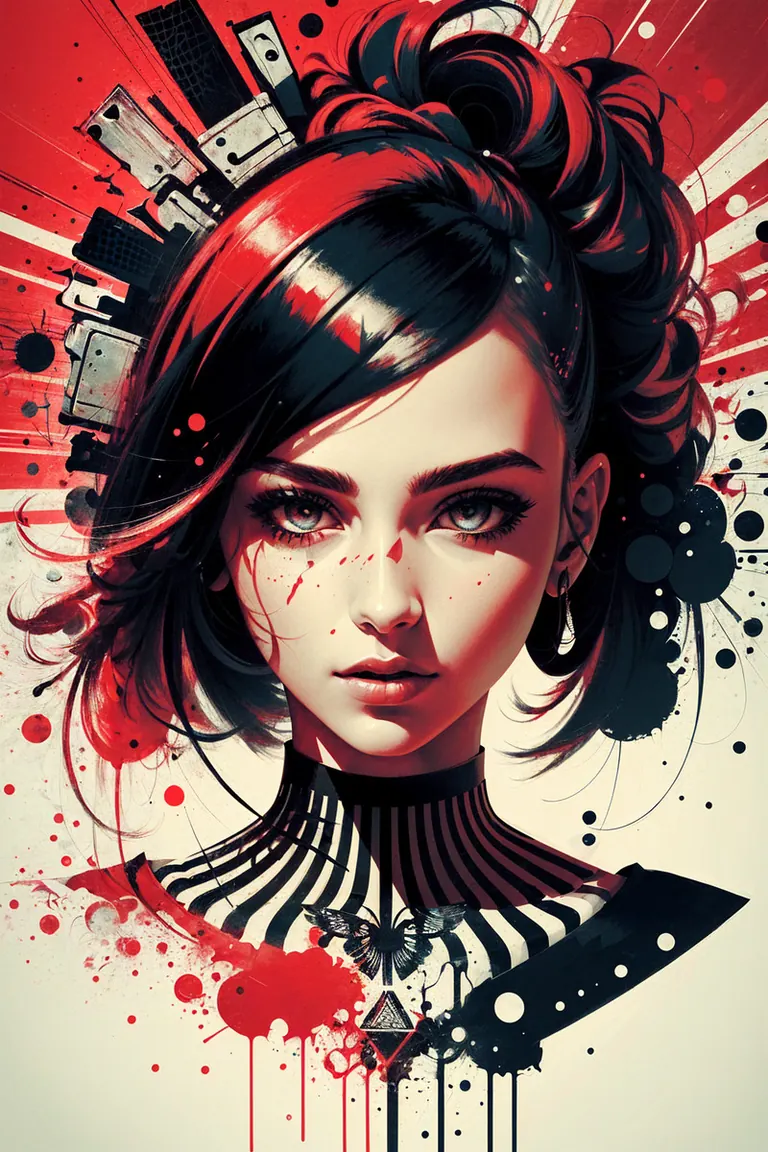
Prompt
a girl, illustration , cover art , (((red))) , portrait , red background , red splash
Prompt negativo
bad-artist bad-artist-anime bad_prompt_version2 badhandv4 ng_deepnegative_v1_75t verybadimagenegative_v1.3 , text , logo , watermark
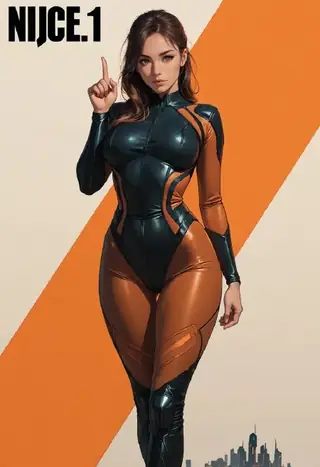
Ajustes
Sampler
DPM++ 2M SDE
Pasos
25
Guidance
13
Semilla
1890108229
Tamaño
1120x1688
Clip skip
2
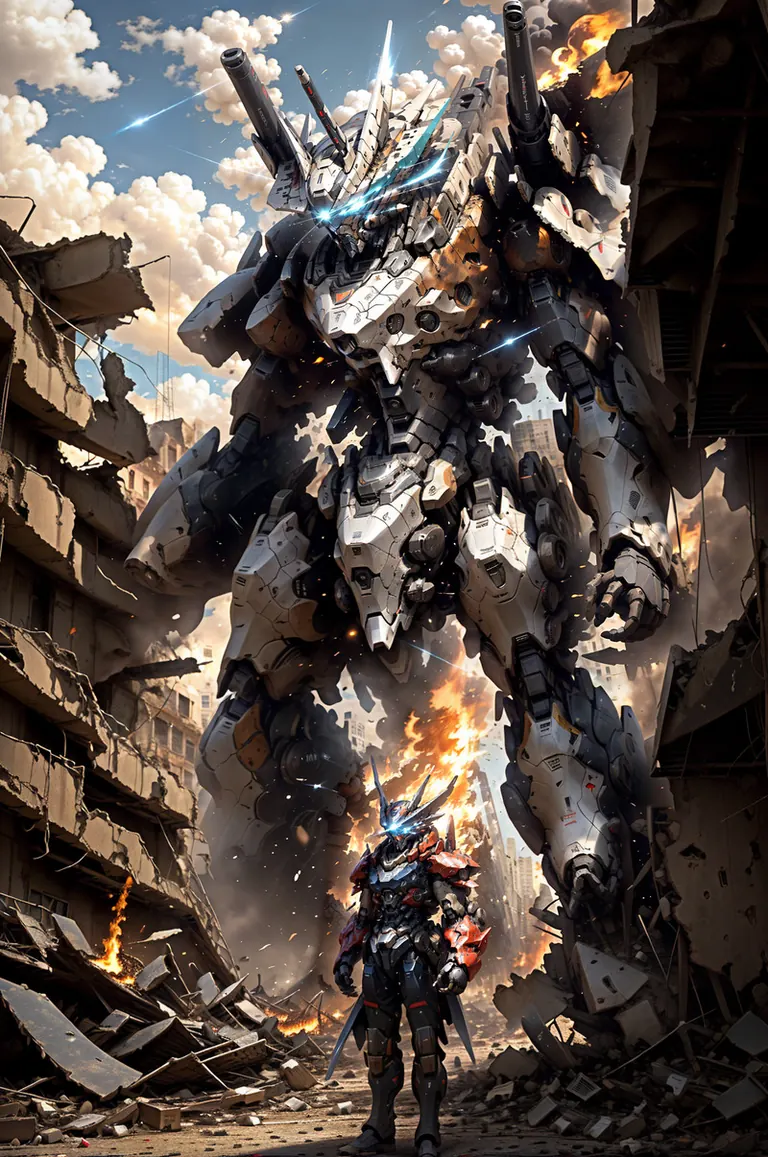
Prompt
masterpiece, best quality, mecha, no humans, black armor, blue eyes, science fiction, fire, laser canon beam, war, conflict, destroyed city background, <lora:Niji:1.2:MIDD>
Prompt negativo
UnrealisticDream, FastNegativeV2,
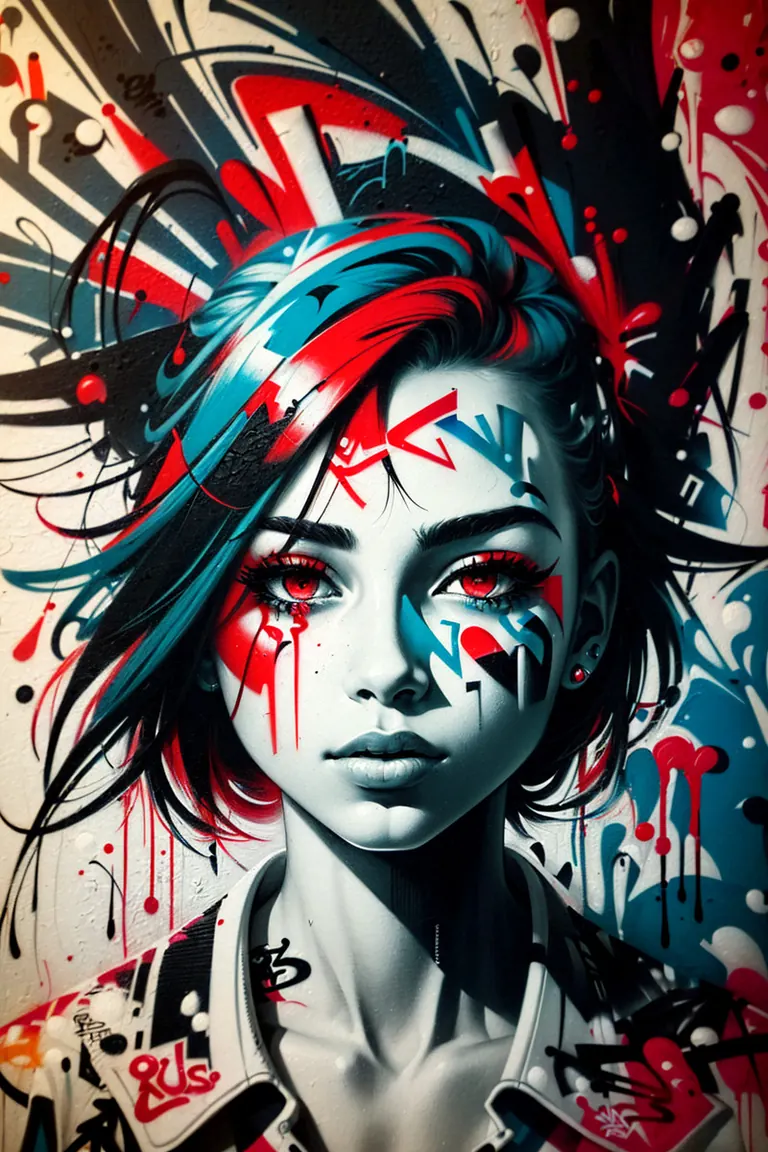
Ajustes
Sampler
DPM++ 2M SDE Karras
Pasos
43
Guidance
12
Semilla
500310396
Tamaño
512x768
Clip skip
2
Prompt
a girl,illustration , cover art , (((red))) , portrait , red background , red splash ,graffiti
Prompt negativo
bad-artist bad-artist-anime bad_prompt_version2 badhandv4 ng_deepnegative_v1_75t verybadimagenegative_v1.3 , text , logo , watermark
Modelos similares
Modelos de IA para generar imagen, vídeo y texto
classic dreamshaper631 es un modelo base para la familia Stable Diffusion 1.5 listado en ModelTrends.ai, un catálogo de solo lectura de modelos de IA de imagen, vídeo y texto de código abierto. Compáralo con otros modelos Stable Diffusion 1.5, consulta su puntuación de calor para ver su tendencia y ábrelo en PirateDiffusion o BitVector para probarlo.
Más modelos Stable Diffusion 1.5Más Modelos base de Stable Diffusion 1.5paintingssemi-realbaseartstylesphotorealistic2dwomanbase model
Explorar por familia de modelos
Modelos Text / LLM
411
Modelos Anima
509
Modelos Chroma
14
Modelos Flux
1,071
Modelos Flux 2 / Klein
1,237
Modelos MiniMax H3
331
Modelos Hunyuan
197
Modelos Ideogram
20
Modelos Krea2
674
Modelos Qwen
17
Modelos Qwen2
36
Modelos Ltx2
150
Modelos Stable Diffusion 1.5
6,465
Modelos Stable Diffusion XL 1.0
15,432
Modelos Zimage
804
Modelos Wan
919

Model
Trends
.ai
© ModelTrends.ai
|
Hecho en Japón
|
© 2026