cartoonishly eaten wan
Bandingkan
7712°
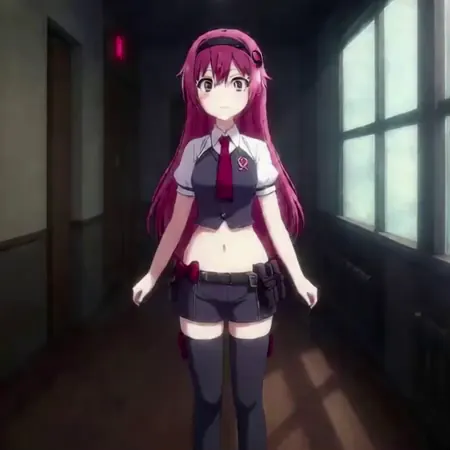
Autoplay
Jalankan secara tempatan
eat-t2v.safetensors
439 MB · SafeTensor
Muat turun disediakan oleh Civitai. Sesetengah pencipta memerlukan log masuk Civitai dahulu.


Tentang model ini
WAN · LoRA
by kabachuha - Cartoonishly Eaten - LTX-2 / Wan2.1 14b T2V
Nota pencipta
LTX-2 Eat
LoRA that gobbles everyone! (Now with sound (really, turn it on on examples))
Basically, you start the video with a subject. Then, suddenly, the camera zooms out revealing that the subject is now miniaturized and then another character steps up and eats them cartoonishly and non-graphically.
This is my fifth LTX-2 LoRA (published globally). Now, this is the start of porting my legacy Civitai loras from Wan to LTX-2.
This LoRA is best working with first-last frame, however start frame may be sufficient if you describe the other subject well. Beware, FLF inherits all LTX-2's flaws and it can do slideshow-like things from time to time (Idk why it spawns the first and the end frame at the end, best way is to simply cut it). Easter egg: characters can devour themselves in a loop if you set the first and the last frames the same pictures.
In contrast to all my previous LTX-2 LoRAs, this one was superhard to train. With CREPA, TREAD, FFN unfreeze, higher rank, Prodigy, the loss didn't lower much and even showed signs of divergence (initially stable loss curve eventually progressing to insanely frequent oscillations without decline). Needless to say, all I could see was pure body horror. With the tongues, the hands themselves being eaten, distorted limbs, etc.
Then I remembered that for sharper results in the case of high oscillations not MSE, but Huber loss is needed. I used scheduled Huber loss (exponential) and it much stabilized the loss curve, producing the much needed downturn at last. Interestingly, this loss choice caused the CREPA regularization loss curve's shape not be just a monotonous sigmoid and even have smooth hills.
Warning: because deep features CREPA or TREAD was used, some of the videos might have slightly washed out feel. If you experience it, try adding vivid colors to the positive prompt, and things like washed out,gray to the negative prompt, and also if the start images are themselves vivid, it will go much better.
The runtime for this experiment totaled 5 hours (and five failed attempts, ranging up to 8 hours). The hardware used for training was 1x5090, with zero blocks swapped, ~4 s/it.
The dataset consists of 6 organic; video fragments (repeated 2 times), which the original LoRA was trained on, plus 47 picked Wan2.2 generations made with that LoRA applied. Overall, the final checkpoint was picked at 4000 optimization steps.
The SimpleTuner training and dataset configs are under config.json and ltx2-multiresolution-eat-t2v-v2.json respectively.
The ComfyUI workflows are inside the .mp4 video files or on the Huggingface repo.
The Huggingface host for the LTX-2 LoRA is at .
Trigger words
You should use eat style to trigger the image generation.
Actually, you shouldn't now, because LTX-2 will add an utterance "eat style" at the beginning of the video. Just describe the action similar to the prompts from the examples and it will do the job!
For Wan2.1 (legacy):
This LoRA introduces the concept of subjects and things eaten in cartoon-like way by being suddenly tossed into a giant mouth and then chewed and consumed non-graphically.
To choose the eater and/or the thing being eaten, use VACE. The examples illustrate each mode, in order: 2 x first-frame2video, first-last2video, last-frame2video, pure text2video (not recommended, as it's slightly retrained in this mode).
The generation resolution is advised to be 512x512 or close in the spatial dimensions, with recommended duration 45 base frames (49 total, 3 seconds).
The t2v training was made using diffusion-pipe for 100 epochs and flow shift of 4.5.
For image2video/flf2video recommended to use with the kijai VACE workflows, standard 1.0 lora weight, 4.0-6.0 cfg, 8.0-16.0 shift + cfg_zero_star. (see videos meta in comfy)
Best works on cartoon-stylized and anime characters, can be weird on realistic. For realistic, supplying an additional existing cartoon-style reference is advised.
Known issues: the object sometimes is bit/chewed like a gum, but not swallowed. (can be slightly countered with adding pushing it inside with the hand.)
The trigger word is 'eat style'. The best prompts are:
"""
eat style. The video begins with [object]. Then a gigantic cartoon hand seizes the [object] from below and tosses it into a gigantic mouth, which appeared on the right side. The camera zooms out, showing the new [eater] chewing and fully swallowing the old tiny [object].
"""
P.S. In case you can't find the metadata, the example workflow for the wolf is here
Kata pencetus
eat style.
SHA256
B2D2C22ED186F39BDF95627E4AD363CF6315156FA8C1F48F173E8AA8A7124754
ID Model ModelTrends.ai
#24477
Laporkan kandungan
Contoh render
Prompt dan tetapan yang dikongsi oleh orang yang membuat render ini di Civitai. Pilih render untuk melihat cara ia dibuat.
Tetapan
Sampler
UniPC
Langkah
25
Guidance
6
Seed
273396971181199
Saiz
512x512
Prompt
eat style. The video begins with an anime girl. Then a gigantic cartoon hand seizes the anime girl from below and tosses it into a gigantic mouth, which appeared on the right side. The camera zooms out, showing the new cartoon candy chewing and fully swallowing the old tiny anime girl.
Prompt negatif
colorful, bad quality, blurry, messy, chaotic
Tetapan
Sampler
UniPC
Langkah
25
Guidance
6
Seed
385946963427102
Saiz
512x512
Prompt
eat style. The video begins with a realistic wolf. Then a gigantic cartoon hand seizes the wolf from above and tosses it up in the air into a gigantic beak, which appeared from above. The camera zooms out, showing the new cartoon bird chewing and fully swallowing the old tiny wolf.
Prompt negatif
colorful, bad quality, blurry, messy, chaotic
Tetapan
Sampler
UniPC
Langkah
25
Guidance
6
Seed
1042695594301049
Saiz
512x512
Prompt
eat style. The video begins with a cartoon bear. Then a gigantic anime hand seizes the cartoon bear from the right and tosses it into a gigantic mouth, which appeared on the right side. The camera zooms out, showing the new anime girl chewing and fully swallowing the old tiny cartoon bear.
Prompt negatif
colorful, bad quality, blurry, messy, chaotic
Tetapan
Sampler
UniPC
Langkah
25
Guidance
6
Seed
276287396674896
Saiz
512x512
Prompt
eat style. The video begins with a crying burger in an intricate restaraunt as background. Then a gigantic cartoon hand seizes the crying burger from below and tosses it into a gigantic mouth, which appeared on the right side. The camera zooms out, showing the new smug cherry chewing and fully swallowing the old tiny burger.
Prompt negatif
colorful, bad quality, blurry, messy, chaotic
Tetapan
Sampler
UniPC
Langkah
25
Guidance
6
Seed
116187357732593
Saiz
512x512
Prompt
eat style. A portrait of an anime girl with modest chest is shown. Then she starts passionately k144ing kissing her finger with her mouth. She blows air inside and infl4t3 inflates her hand, her body expanding uniformly from head to toe. During the whole video she holds her finger in her mouth. Her clothes strain at the seams, and her hair stands on end as she grows larger and larger. The girl continues to blow into herself like a bellows, giggling mischievously. Her clothes fall off. Finally, the girl reaches her maximum size – a gigantic, wobbly anime girl with big breasts. She smiles in satisfaction.
Prompt negatif
balloon, sphere, chewing gum, bubblegum, two girls at the end, static, low resolution, blurry, overexposed, blown out, harsh lighting
Model AI untuk penjanaan imej, video dan teks
cartoonishly eaten wan ialah LoRA untuk keluarga Wan yang disenaraikan di ModelTrends.ai, katalog baca sahaja untuk model AI imej, video dan teks sumber terbuka. Bandingkannya dengan model Wan lain, semak skor habanya untuk melihat trendnya, dan bukanya di PirateDiffusion atau BitVector untuk mencubanya.
Layari mengikut keluarga model
Model Text / LLM
411
Model Anima
509
Model Chroma
14
Model Flux
1,071
Model Flux 2 / Klein
1,237
Model MiniMax H3
331
Model Hunyuan
197
Model Ideogram
20
Model Krea2
674
Model Qwen
17
Model Qwen2
36
Model Ltx2
150
Model Stable Diffusion 1.5
6,465
Model Stable Diffusion XL 1.0
15,432
Model Zimage
804
Model Wan
919

Model
Trends
.ai
© ModelTrends.ai
|
Dibuat di Jepun
|
© 2026