t ponai65 xl
Bandingkan
8479°
Jalankan secara tempatan
tPonynai3_v65.safetensors
6.46 GB · SafeTensor · bf16 · full
Muat turun disediakan oleh Civitai. Sesetengah pencipta memerlukan log masuk Civitai dahulu.


Tentang model ini
STABLE DIFFUSION XL 1.0 · Model asas
Pony fine tune by Tonade. 6.5 fixes some overfitting issues from 6. Usage tips: positive:(score_9,score_8_up,score_7_up,score_6_up,score_5_up,score_4_up) OR (score_9,score_8_up,score_7_up) negative: (score_4,score_3,score_2,score_1), negative: worst quality, bad hands, bad feet hope u like it ᕕ(◠ڼ◠)ᕗ based on nai3
Nota pencipta
Here is the link to discord, there are two channels, Chinese and English
451450868(英灵殿)
929721518(被封的备用群)
这是国内吐司的在线生成平台,可以去白嫖生图
v6使用小技巧:“anime”这个词里面训练了nai3的画风,如果使用过程中出现欧美画风,可以使用这个词稳定nai3画风,这是我尝试的一个减少过拟合的办法。
V6 usage tip: The word "anime" is used to train the art style of nai3. If European and American art styles appear during use, this word can be used to stabilize the nai3 art style. This is a method I tried to reduce overtrain.
模型已经内置vae了,不需要额外添加vae
The model already has included vae, there is no need to add additional vae
最佳的出图策略是适中的分辨率开高清修复,而不是直接使用大分辨率直出
The best generate strategy is to use high-fix at a moderate resolution, rather than directly using high-resolution direct output
v5版本新加了4个style,可以通过style_1到style_4来微调画面细节(理论上是这样的,实际效果比较玄学)
V5 version has added 4 new styles, which can be used to fine tune the details of the image through style_1 to style_4 (theoretically, this is the case, but the actual effect is more mystical or lower)
本模型完美支持由ponyv6为底模训练的模型,ani3,sdxl1.0的lora也能在某种程度上适配
This model perfectly supports lora trained with ponyv6 as the base model, and the Lora of ani3 and sdxl1.0 can also be adapted to some extent.
基于v4.1的图生图测试(这是在之前版本里被忽略的部分)
Image inpaint testing based on v4.1 (this is a previously overlooked part)
pony是神,兼容性满分。本模型支持ani,pony的lora
必备前置效果词和ponydiffusion一样
positive:(score_9,score_8_up,score_7_up,score_6_up,score_5_up,score_4_up)
OR (score_9,score_8_up,score_7_up)
负面可加:
negative: (score_4,score_3,score_2,score_1),
也可以加正常的nai系负面词,例如:
negative: worst quality, bad hands, bad feet
hope u like it ᕕ(◠ڼ◠)ᕗ base on nai3 and ponyv6
训练须知:v1使用了94张,v2用了119张,v3用了348张,v3.5用了474张,nai3生成的图片,训练的lora融进底模进行微调,pony支持的画师tag都支持,使用两个以上的画师tag可能会导致背景崩溃,目前发现能生成原神的角色,其他的不知道了,对于这个模型我测试的也不多,惊叹于其对于nai3的画风复刻中。底模是T-anime-xl和ponyv6以及ani3的融合模型,并未发布。
使用的训练显卡是我自己的3090显卡,v1到v3分别使用了7小时,12小时,35小时,47小时
Training Instructions:Merge Lora used 94 pictures for v1, 119 pics for v2, 348 pics for v3, 474 pics for v3.5,which generated by NAI3 to train into the basemodel for fine-tuning,Pony supports all artist tags which ponyv6 already have, but there is no any addition artist tag from nai3. Using more than two artist tags may cause background crashes,At present, it has been found that characters that can generate Genshin Impact.I don't know the others.I haven't tested much for this model.,Marvel at its reproduction of the painting style of NAI3.The base model is a fusion model of T-anime-xl and ponyv6 and animage3, which has not been released
The training graphics card I used was my own 3090 graphics card, which was used for 7 hours, 12 hours, and 35 hours and 47 hours from v1 to v3.5, respectively.
v1
一次有趣的尝试
An interesting attempt
v2
在v1的基础上略微增加了训练集,并经历了30小时左右的参数试错,但是训练出来的画风仍然具有一些过拟合,例如双重肚脐眼以及杂乱的头发
On the basis of v1, the training set was slightly increased and went through about 30 hours of trial and error, but the trained art style still had some overfitting, such as double navel eyes and messy hair
v3
v3的肢体会比v2的更好,对于footfocus的理解v3可以生成视觉冲击更大的脚,也更高难度的透视视角,v3的头发的ai感也比v2要弱,因为v2的训练集太少了,所以头发部分会有些过拟合,而且v2偶尔会出现的双肚脐眼也没了。总体来说三倍于v2训练集的大小以及更大的dim参数使得画风拟合的更加自然,而且在长prompt下的表现力远远强于v2。
The limbs of v3 are better than those of v2. In terms of understanding footfocus, v3 can generate feet with greater visual impact and higher difficulty perspective. The AI feeling of v3's hair is also weaker than that of v2, because v2 has too little training set, so the hair part may be slightly overfitting, and the occasional double navel eyes that appear in v2 are also gone. Overall, three times the size of the v2 training set and a larger dim parameter make the art style fit more natural, and the performance is much stronger than v2 under long prompts.
v3.5
在这个版本中,对于质量词的要求并不那么严谨,可以完全不用pony的美学评分的质量词去出图,在测试中偶尔会出现图片生成无意义的色块的情况,只需要将美学评分的质量词换成1.5常用的质量词就行,例如score_1,score_2换成worst quality。这个版本我多加入了150张左右的训练集来平衡以及充实画风,并且减少了学习曲线的初始斜率,这让这个模型没有那么过拟合,可以适配更多的lora以及奇思妙想的提示词。总体来说,这个版本是相较v3版本更加自由的一个版本,并且这个版本对于男性的刻画要远强于v3,在某些提示词下的色彩以及画风没有那么过分鲜艳以及油腻。
In this version, the requirements for quality words are not so strict, you can completely not to use the quality words of pony's aesthetic score to plot the picture, and occasionally there will be a situation where the picture generates meaningless color blocks in the test, you only need to replace the quality words of the aesthetic score with 1.5 commonly used quality words, such as score_1, score_2 replace it with worst quality. In this version, I added about 150 more training sets to balance and enrich the art style, and reduced the initial slope of the learning curve, which makes this model less overfitted and can be adapted to more lora and whimsical prompts. Overall, this version is a freer version than the v3 version, and this version is much stronger than the v3 version, and the colors and style of painting under some hints are not so bright and greasy.
v4
这个版本使用了798张图片作为训练素材,并使用3090显卡训练了90个小时。这个版本相较于v3.5在某些prompt下的构图以及对于某些部位的刻画更加正确,比如手指部分的重影以及一些身体部位的重叠。在prompt方面,我还是以中等长度以及稍短长度的prompt作为主要的训练目标,毕竟谁都不喜欢写一长串的prompt才能生成质量好的图是吧?在去掉pony的美学得分的质量prompt后,图像的质量相比v3.5有很高的提升,出图的质量会偏向于更加平面而非立体的画面,更加接近于经典的动漫画风。对于图片数量对于ponyv6的微调效果的测试接近尾声,下一步就是从prompt的训练标签入手,尝试在pony有限的单次训练素材数量里面添加更多可调控的prompt(例如将美学评分加入进去,现在的训练逻辑还是用主流的质量词去覆盖掉pony的美学得分质量词),并且会持续增添合适的新训练素材,例如场景的训练素材以及更多的足部训练素材(v4的足部训练素材似乎有点少了)。
This version used 798 images as training materials and trained for 90 hours using a 3090 graphics card. This version has a more accurate composition and depiction of certain parts in certain prompts compared to v3.5, such as ghosting of fingers and overlapping of some body parts. In terms of prompts, my main training goal is to use medium and slightly shorter prompts, as nobody likes to write a long string of prompts to generate high-quality images, right? After removing the quality prompt of Pony's aesthetic score, the image quality has been significantly improved compared to v3.5, and the resulting quality tends to be more flat rather than three-dimensional, closer to the class
SHA256
A2E734AC29DF9BEDA7CFD8A60AF0168077C67CB26AB4CE292A95B895B43CAF07
ID Model ModelTrends.ai
#4482
Laporkan kandungan
Contoh render
Prompt dan tetapan yang dikongsi oleh orang yang membuat render ini di Civitai. Pilih render untuk melihat cara ia dibuat.
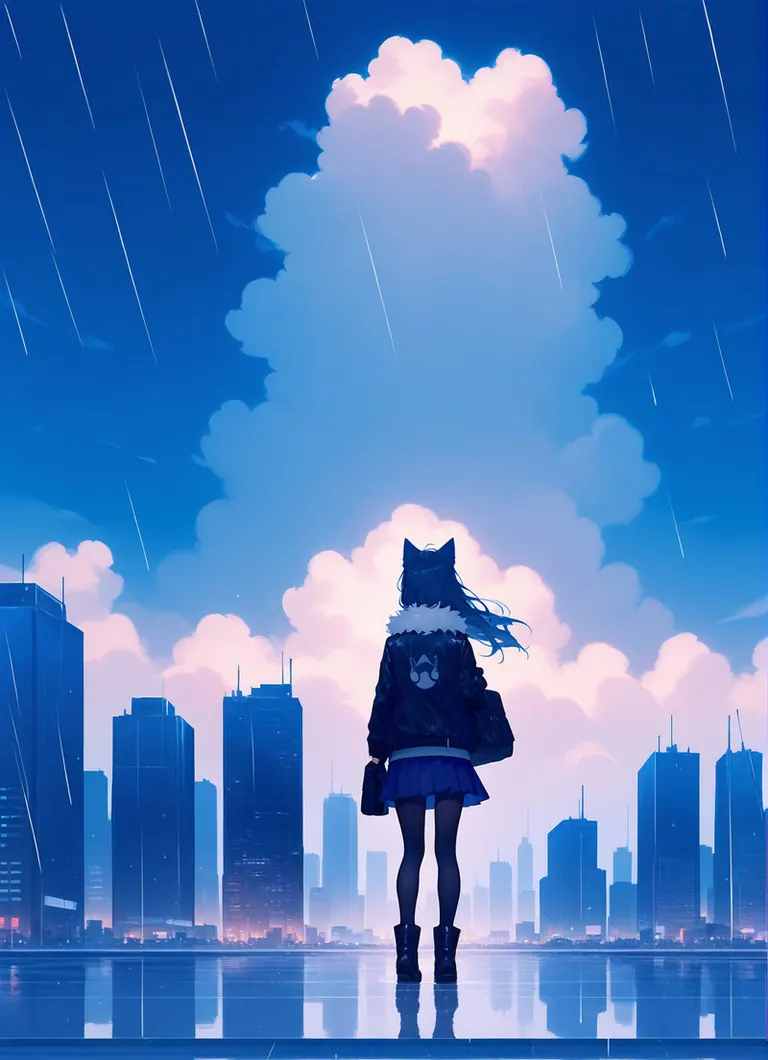
Tetapan
Sampler
Euler a
Langkah
25
Guidance
7
Seed
1190330630
Saiz
776x1072
Clip skip
2
Prompt
score_9,score_8_up,score_7_up,1girl,animal ears,cloud,outdoors,sky,long hair,scenery,cloudy sky,building,rain,skirt,solo,bag,cityscape,boots,reflection,city,standing,from behind,dog,pantyhose,skyline,facing away,tail,long sleeves,blue theme,water,skyscraper,jacket,pleated skirt,fur trim,cat ears,holding,animal,blue skirt,
Prompt negatif
score_4,score_3,score_2,score_1,ugly,bad hands,
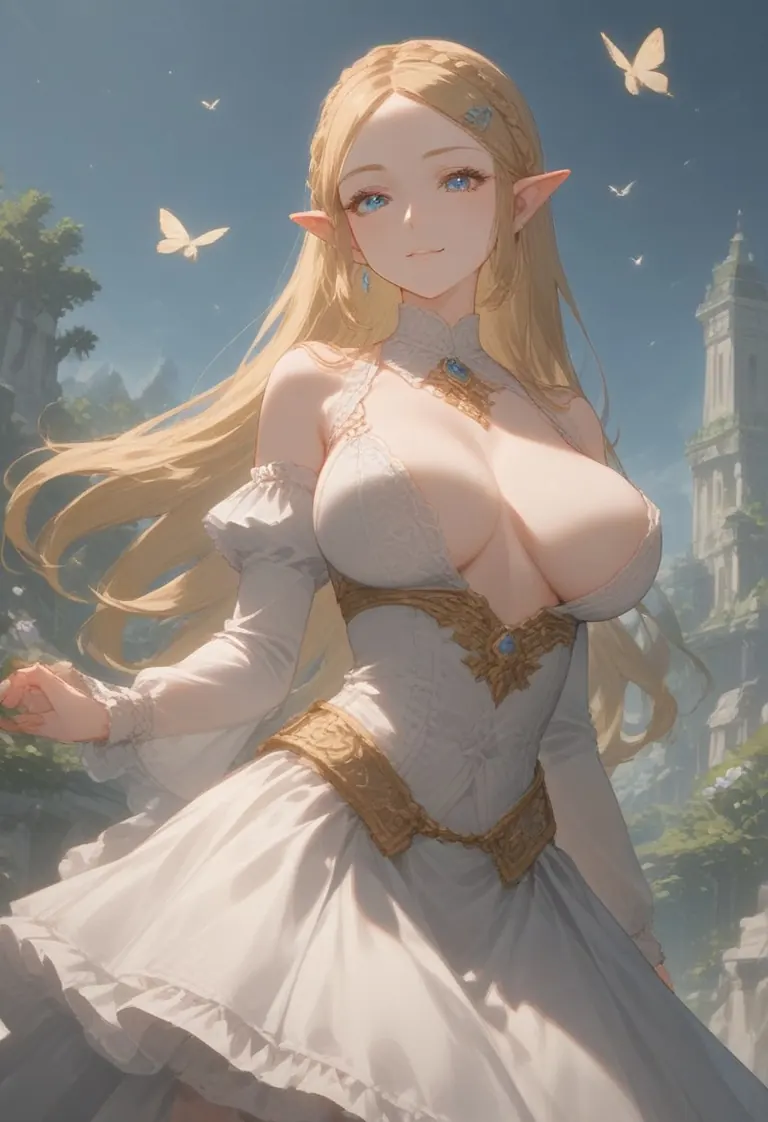
Tetapan
Sampler
Euler
Langkah
8
Guidance
1
Seed
4194436964
Saiz
832x1216
Clip skip
2
Prompt
score_9, score_8_up, score_7_up, masterpiece, ultra detailed, best quality, 1girl, alone, solo, Beautiful eyes, detailed eyes, detailed face, beautiful face, perfect face, perfect body, perfect body, detailled body, large breasts, saggy breasts, breasts apart, wide hips, large ass, velvet skin, curvy body, voluptuous body, zelda, blue eyes, blonde hair, scenery, smug smile, victorian dress, gardenhouse, flower, butterfly, sun
Prompt negatif
verybadimagenegative_v1.3, nipples, small_eyes, bad proportiong, logo, open dress, slit dress, chinese dress, bad anatomy, extra limbs, three legs, three arms, amputee, twisted torso, [:, blurred, low resolution, gaussian, blurry, long fingers, extra_fingers, thick fingers, bad hand, poorly drawn hand, extra_hand, not detailed, simple background, not delicate:0.8]), (worst quality, low quality, ugly face:1.3), multiple girls, 2girls, twins, clone, uneven legs, extra leg, asymmetrical legs, amputee, calf:weird_eyes, empty_eyes, ugly_eyes, uneven_eyes, different_eyes, dull_eyes, strabismus, blank_eyes, asymmetric_eyes, devoid eyes, pale eyes, opaque eyes, extra_arm, extra_hands, extra_hand, 3 hands, extra_arms, weird hands, wrong hands, big hands, deformed hands, malformed hands, ugly hands, malformed fingers, bad fingers, six fingers, extra finger, deformed fingers, distorted fingers, interlocked fingers, muscular, saturated color, patreon mark, logo, creator name
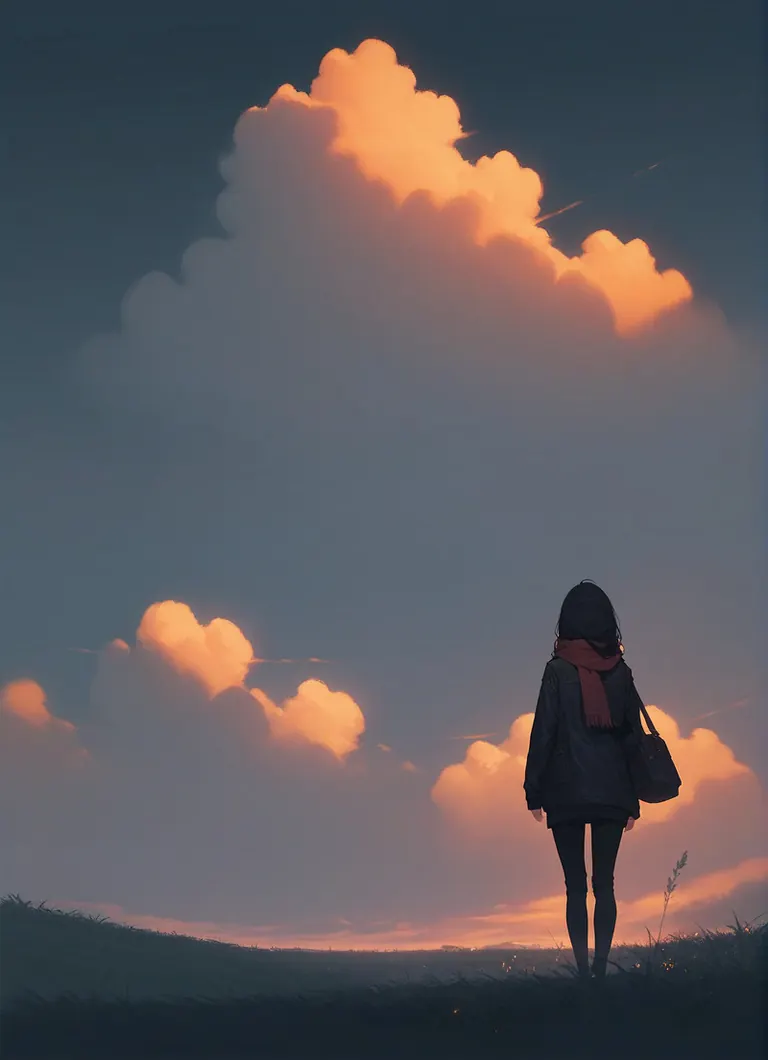
Tetapan
Sampler
Euler a
Langkah
33
Guidance
7
Seed
3758170705
Saiz
776x1072
Clip skip
2
Prompt
score_9,score_8_up,score_7_up,1girl,solo,sky,cloud,outdoors,scenery,black hair,grass,from behind,long hair,standing,cloudy sky,dark,hood,sunset,bag,jacket,night,scarf,long sleeves,facing away,
Prompt negatif
score_4,score_3,score_2,score_1,ugly,bad hands,
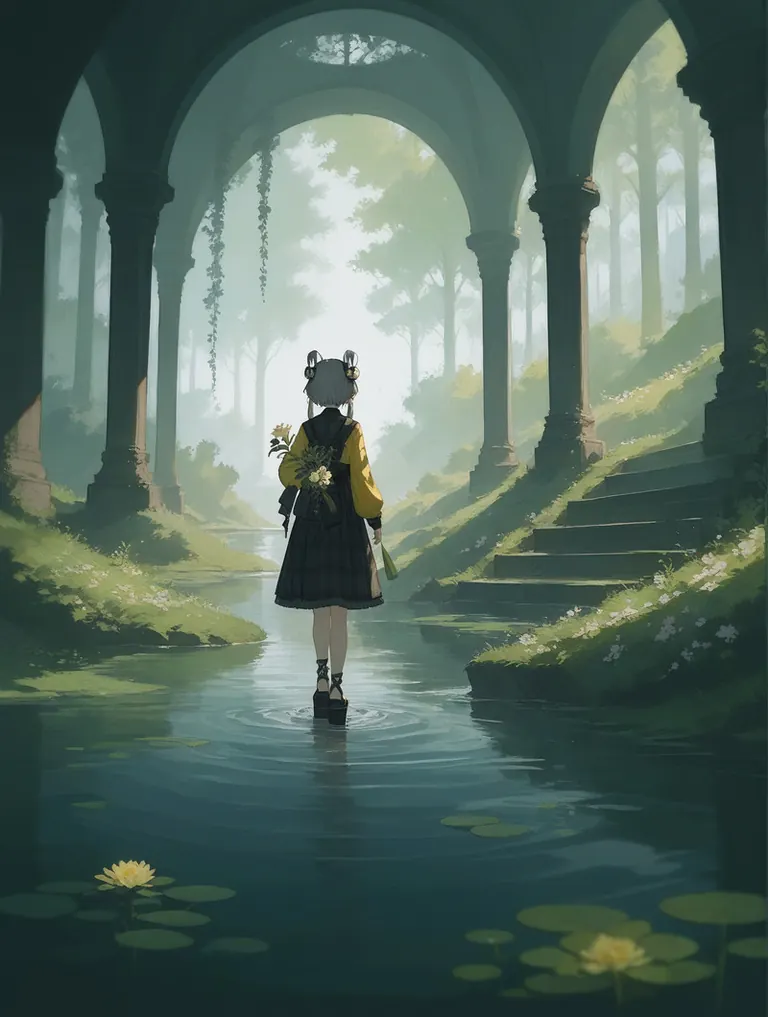
Tetapan
Sampler
Euler a
Langkah
25
Guidance
7
Seed
2974211893
Saiz
848x1120
Clip skip
2
Prompt
(score_9,score_8_up,score_7_up),1girl,green eyes,grey hair,hair ornament,hair rings,short hair with long locks,hair tubes,sandals,black footwear,platform footwear,black gothic dress,leaning_back,leaning_on_object,leaning_forward,watercolor \(medium\),best quality,masterpiece,amazing quality,best aesthetic,absurdres,bust,flower,solo,yellow jacket,black hair,stairs,wading,water,outdoors,holding flower,from behind,holding,plaid,plant,standing,scenery,long sleeves,overgrown,facing away,
Prompt negatif
(score_4,score_5,score_3,score_2,score_1),ugly,bad feet,bad hand,building
Tetapan
Sampler
Euler a
Langkah
25
Guidance
7
Seed
1299577295
Saiz
848x1120
Clip skip
2
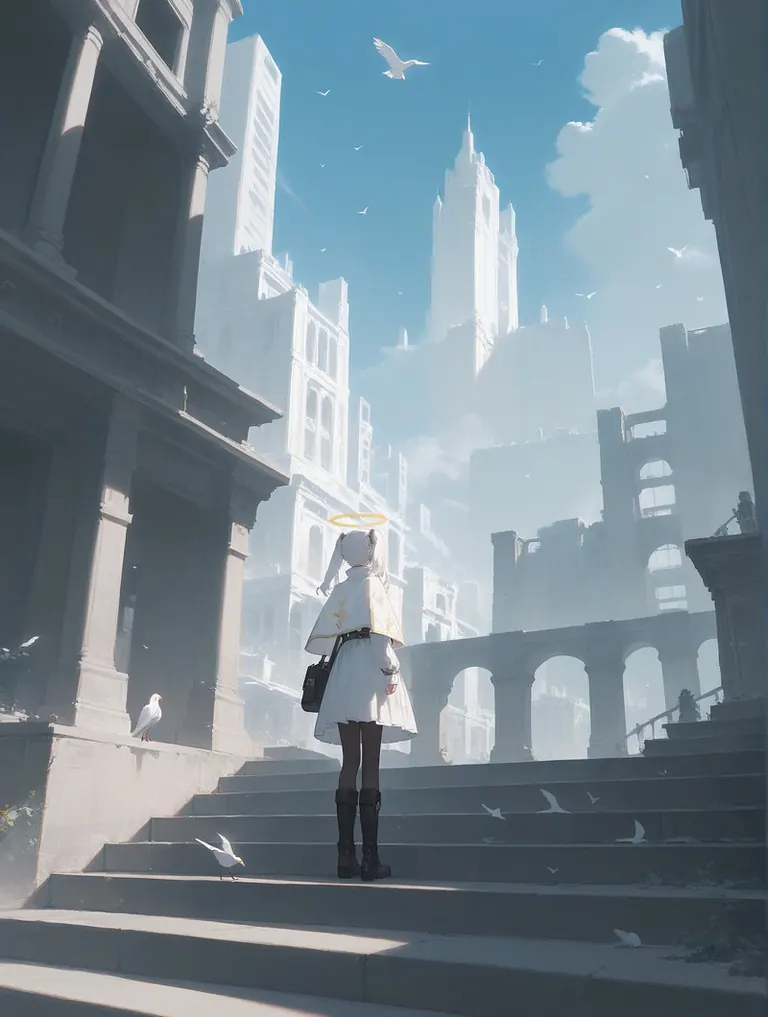
Prompt
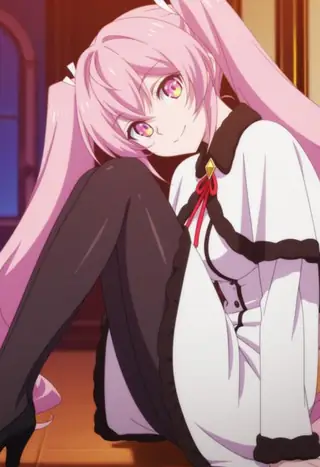
(score_9,score_8_up,score_7_up),1girl,solo,white hair,long hair,white dress,dress,outdoors,standing,halo,holding,scenery,multiple girls,building,bird,ruins,day,capelet,wings,1girl,long sleeves,boots,angel,pantyhose,twintails,white capelet,wide shot,2girls,bangs,bag,stairs,city,
Prompt negatif
(score_4,score_5,score_3,score_2,score_1),ugly,bad feet,bad hand,
Tetapan
Sampler
Euler a
Langkah
33
Guidance
7
Seed
1000538367
Saiz
776x1072
Clip skip
2
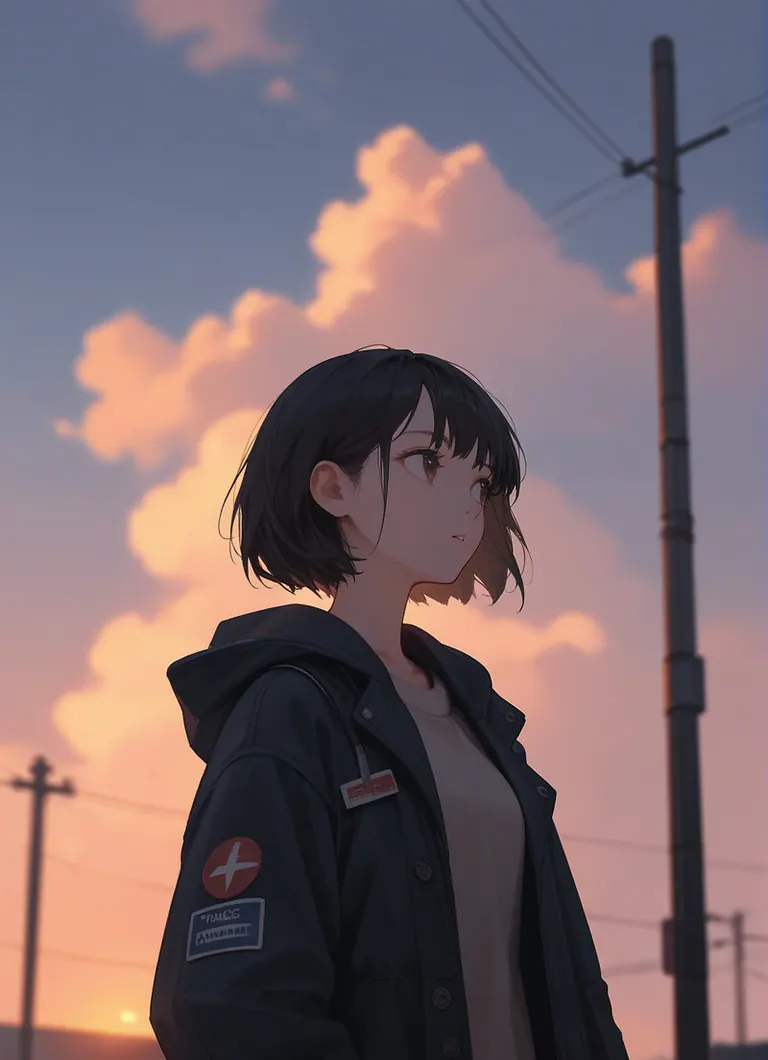
Prompt
score_9,score_8_up,score_7_up,1girl,solo,outdoors,sky,power lines,utility pole,cloud,black hair,short hair,jacket,bangs,bag,blurry,sunset,upper body,blurry foreground,brown eyes,cloudy sky,looking afar,parted lips,closed mouth,evening,depth of field,looking away,sweater,long sleeves,coat,
Prompt negatif
score_4,score_3,score_2,score_1,ugly,bad hands,
Tetapan
Sampler
Euler a
Langkah
33
Guidance
7
Seed
2850010311
Saiz
776x1072
Clip skip
2
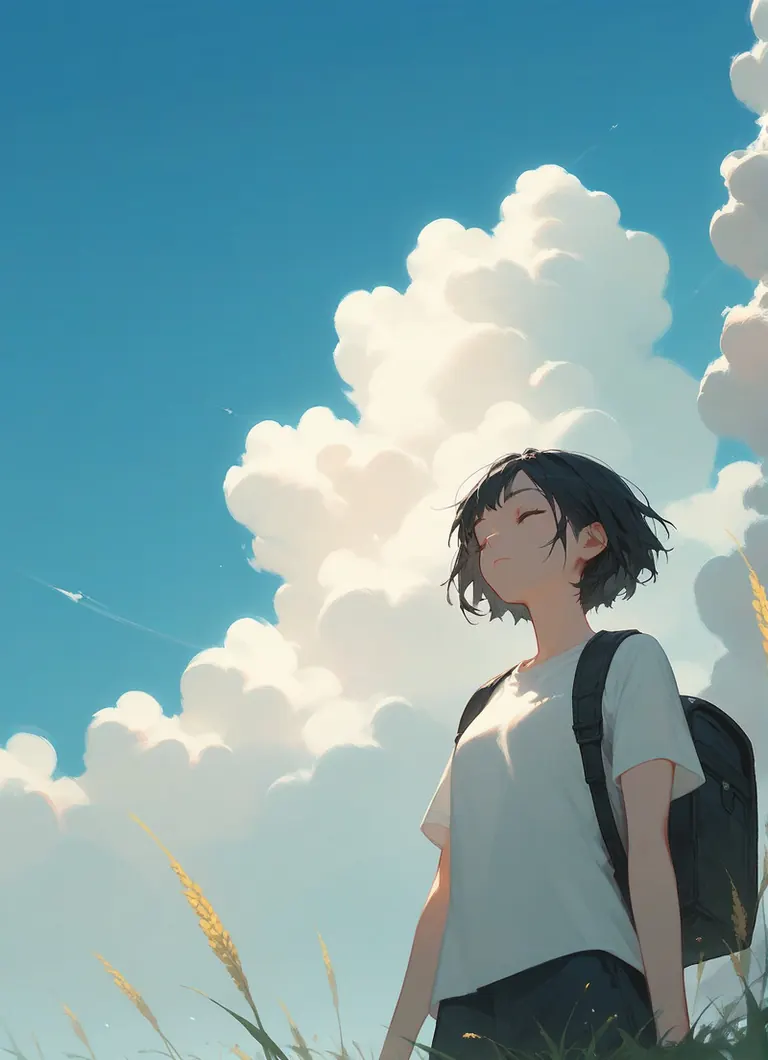
Prompt
score_9,score_8_up,score_7_up,1girl,solo,sky,cloud,1girl,backpack,outdoors,shirt,short hair,bag,from below,white shirt,day,blue sky,short sleeves,black hair,closed eyes,grass,standing,cloudy sky,
Prompt negatif
score_4,score_3,score_2,score_1,ugly,bad hands,
Model serupa
Model AI untuk penjanaan imej, video dan teks
t ponai65 xl ialah model asas untuk keluarga Stable Diffusion XL 1.0 yang disenaraikan di ModelTrends.ai, katalog baca sahaja untuk model AI imej, video dan teks sumber terbuka. Bandingkannya dengan model Stable Diffusion XL 1.0 lain, semak skor habanya untuk melihat trendnya, dan bukanya di PirateDiffusion atau BitVector untuk mencubanya.
Lagi model Stable Diffusion XL 1.0Lagi Model asas Stable Diffusion XL 1.0ponytypeanimeeffectsbaseponybase modelnai3nai
Layari mengikut keluarga model
Model Text / LLM
411
Model Anima
509
Model Chroma
14
Model Flux
1,071
Model Flux 2 / Klein
1,237
Model MiniMax H3
331
Model Hunyuan
197
Model Ideogram
20
Model Krea2
674
Model Qwen
17
Model Qwen2
36
Model Ltx2
150
Model Stable Diffusion 1.5
6,465
Model Stable Diffusion XL 1.0
15,432
Model Zimage
804
Model Wan
919

Model
Trends
.ai
© ModelTrends.ai
|
Dibuat di Jepun
|
© 2026