chenkin beta02 xl
Bandingkan
8315°
Jalankan secara tempatan
chenkinNoobXLCKXL_v02.safetensors
6.62 GB · SafeTensor · fp16 · full
Muat turun disediakan oleh Civitai. Sesetengah pencipta memerlukan log masuk Civitai dahulu.


Tentang model ini
STABLE DIFFUSION XL 1.0 · Model asas
Nota pencipta
Model Introduction
Model Details
-
Developed by:
-
Model Type: Diffusion-based text-to-image generative model
-
Fine-tuned from: Laxhar/noobai-XL-1.1
-
Sponsored by from: 极逸 SOON ()
-
Independence Statement: ChenkinNoob team is an independent team; this project is not an official release of Laxhar Lab, but is built upon their open-source base model.
Participants and Contributors
Participants
-
Chenkin: |
-
waww:
-
leafmoone:
-
heathcliff:
-
tairitus:
-
Ryan Corwin:
-
chinoll:
-
spawner:
ChenkinNoob-XL-V0.5
Long time no see, everyone! It's been a while since our last release, and today we are thrilled to bring you the brand new major version trained on top of V0.2: ChenkinNoob-XL-V0.5. This update focuses on improving overall aesthetics, reducing common AI artifacts, and enhancing practical usability for game art production and illustration workflows.
Key Updates & Features:
-
~12M Dataset Optimization: We removed some style-divergent images (<1M), retained our core 9M open-source anime dataset (Danbooru, with data cutoff up to Jan 2026), and added 2.17M strictly filtered open-source game concept designs and high-quality Western datasets. The total dataset is now around 12 million images.
-
Custom Training Architecture: To efficiently handle this massive dataset, we developed an exclusive training script from scratch. This allows us to better utilize Hierarchical Dropout and Repeat Tag Resampling, significantly improving the model's generalization.
-
Exclusive 8-in-1 ControlNet: Released alongside .
-
Highlight - Fuse Mode: Allows you to mix multiple ControlNet conditions simultaneously (e.g., Lineart + Depth + Pose) in a single pass without weight interference.
-
Requirement: To use this in ComfyUI, you must install our exclusive plugin: .
Recommended Settings:
-
Steps: 25 ~ 30 | CFG Scale: 5 ~ 6 | Sampler: Euler a
-
Positive Prompt: masterpiece, best quality, newest, high resolution, aesthetic, excellent, year 2026,
-
Negative Prompt: nsfw, worst quality, old, early, low quality, lowres, signature, username, logo, bad hands, mutated hands,
Future Roadmap: To better achieve character and style transfer, our exclusive IP-Adapter (IPA) has officially entered the training schedule! Additionally, we are actively researching entirely new model architectures and hope to share these new developments with you later this year. Stay tuned!
V0.5 Acknowledgements:
-
Core Ecosystem: MIAOKA, silvermoong, nian__gao233, yuno779
-
Tech Advisors: , (Laxhar Lab)
-
Art Advisors: MLiang, BLACKDUO, Sdwang
-
Cover & Promo: poi, neko, MMX, and others
-
Discord Beta Testers: Bluvoll, Anzhc, Drac (Special Thanks), talan, Panchovix, itterative, Ryusho, Ly, Silvelter, and others
-
QQ Beta & Visuals: heathcliff, boundless, 2222k, suqingwei114514, 三费武装白色人种, vv--laov, and others
-
Community Support: 孤辰, 昊天, 米豆粒, 乾杯君 (Snke), 砚青, 双月丸‖soutsukimaru, 大尾立人间体, 青空, 喵九,and others. A huge thank you to all the friends who helped us throughout the training process!
--
ChenkinNoob-XL-V0.2
is now live on Civitai. This update builds on the noobai-XL-1.1 backbone while extending the Danbooru training set through 2025-11-23. Compared to V0.1, you can expect:
- Sharper character fidelity: better pose stability, facial consistency, and accessory detail thanks to refreshed captions and alignment tweaks.
- Prompt responsiveness: more reliable control over outfits, lighting, and color palettes, especially in multi-character prompts.
- Open pipeline refinements: updated default prompts/negative prompts, plus cleaner metadata to simplify LoRA or LyCORIS fine-tuning.
Recommended baseline:
CFG 5–6, 25–30 steps, Euler a, 1024×1024-class resolutions
Positive: high resolution, aesthetic, excellent, medium resolution, year 2025, newest
Negative: low resolution, e621, Furry, old
New Tag System
V0.2 introduces additional tags to better surface high-quality generations and recent-era aesthetics.
| Tag Type | Label | Description |
| ----------- | ----------------- | --------------------------------------------- |
| Resolution | **High Resolution** | Image area ≥ 2048 px |
| Resolution | **Medium Resolution** | 1024 px < image area < 2048 px |
| Resolution | **Low Resolution** | Image area ≤ 1024 px |
| Aesthetic | **Esthetic** | Top 100k most liked Danbooru posts |
| Aesthetic | **Excellent** | Top 1M most liked Danbooru posts |
| Era | **Year YYYY** | Explicit year tag (e.g., `year 2025`) |
| Era | **Range: Newest** | Aggregated label for 2022–2025 content |
| Era | **Range: Old** | Aggregated label for 2018 and earlier content |
These labels appear in metadata and recommended prompts so creators can quickly filter for the visual qualities they need.
Stay tuned for V0.3 (ETA January 2026) and the forthcoming anime-focused SDXL all-in-one ControlNet tied to our 1.0 milestone. Join the conversation, share your renders, and let us know how V0.2 performs in your workflows!
V0.2 Contributors
-
Cover Art Providers (V0.2): poi, Sdwang, freewill, 一费白色人种, 十一, wa我我, 屋檐铃兰448, 11.7suki, 曾青 等
-
Discord Closed Beta Reviewers (V0.2) (listed by join order): NukeA.I, 6DammK9, Talan, Ryusho, NAMAME, Anzhc, Ly, HyperClap, itterative, Chat Errꙫr, rred, Bluvoll, Void, Mirai, 𝕮𝖔𝖈𝖔𝕶𝖔𝖐𝖔 (dvxdvxdv). Your skill, passion, and fearless feedback make you the backbone of this open-source community—thank you for every priceless note that keeps the iterations moving forward.
ChenkinNoob-XL-V0.1
New Image Generation Model
model is built upon the Noob XL architecture by continuing its training from the noobai-XL-1.1 checkpoint, utilizing an enhanced dataset that extends Danbooru2024 with additional data from August 2024 to September 2025. It upholds the high-quality performance of the Noob XL series and delivers exceptional image generation capabilities
Contributors
-
Special Thanks (Technical Support): ( | ) for providing long-term technical support and engineering assistance to the ChenkinNoob team.
-
Technical Ad
SHA256
18D4D20789B5105F8B63B538CDEEFFFD695B1E437D3A7D94A94C28D7FE5E6297
ID Model ModelTrends.ai
#20883
Laporkan kandungan
Contoh render
Prompt dan tetapan yang dikongsi oleh orang yang membuat render ini di Civitai. Pilih render untuk melihat cara ia dibuat.
Tetapan
Sampler
Euler a
Langkah
30
Guidance
7
Seed
1398974650
Saiz
832x1216
Clip skip
2
Berat yang digunakan
1
Prompt
(masterpiece), (best quality), (ultra-detailed), amazing quality, very aesthetic, illustration, perfect composition, intricate details, absurdres, incredibly absurdres, A mysterious wandering wizard in a sci-fi post-apocalyptic wasteland, wearing layered desert robes mixed with tactical armor, hood obscuring face, glowing arcane symbols drifting around one hand, the other holding a worn revolver, a ritual dagger at the waist, faintly glowing life-energy constructs forming behind them, lonely horizon, wind-blown dust, cinematic lighting, ultra-detailed, character concept art
Tetapan
Sampler
euler_cfg_pp
Langkah
30
Guidance
1
Seed
1
Saiz
896x1152
Prompt
1girl, lappland \(arknights\), profile, messy hair, holding red apple, licking lips, crazy smile, looking at viewer, black background, sketch, monochrome, pencil drawing lineart, dynamic lighting
Tetapan
Sampler
euler_cfg_pp
Langkah
30
Guidance
1
Seed
1
Saiz
1792x1152
Prompt
1girl, lappland \(arknights\), profile, messy hair, holding red apple, licking lips, crazy smile, looking at viewer, black background, sketch, monochrome, pencil drawing lineart, dynamic lighting
Panduan untuk model ini
Semua panduan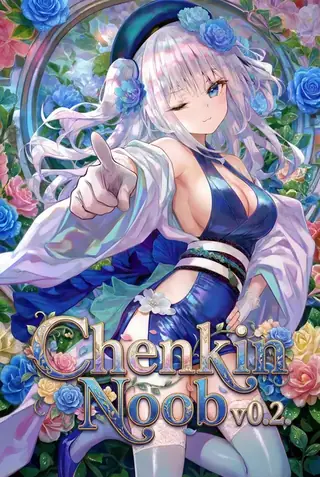

Model serupa
Model AI untuk penjanaan imej, video dan teks
chenkin beta02 xl ialah model asas untuk keluarga Stable Diffusion XL 1.0 yang disenaraikan di ModelTrends.ai, katalog baca sahaja untuk model AI imej, video dan teks sumber terbuka. Bandingkannya dengan model Stable Diffusion XL 1.0 lain, semak skor habanya untuk melihat trendnya, dan bukanya di PirateDiffusion atau BitVector untuk mencubanya.
Lagi model Stable Diffusion XL 1.0Lagi Model asas Stable Diffusion XL 1.0illustriousanimebasesdxlnoobchenkinbase model
Layari mengikut keluarga model
Model Text / LLM
411
Model Anima
509
Model Chroma
14
Model Flux
1,071
Model Flux 2 / Klein
1,237
Model MiniMax H3
331
Model Hunyuan
197
Model Ideogram
20
Model Krea2
674
Model Qwen
17
Model Qwen2
36
Model Ltx2
150
Model Stable Diffusion 1.5
6,465
Model Stable Diffusion XL 1.0
15,432
Model Zimage
804
Model Wan
919

Model
Trends
.ai
© ModelTrends.ai
|
Dibuat di Jepun
|
© 2026