boringreality huny
Bandingkan
8196°
Jalankan secara tempatan
boreal-hl-v1.safetensors
172 MB · SafeTensor
Muat turun disediakan oleh Civitai. Sesetengah pencipta memerlukan log masuk Civitai dahulu.


Tentang model ini
HUNYUAN · LoRA
by Kudzueye - realism effect video lora. makes videos look like ordinary real everyday footage
Nota pencipta
QUICK UPDATE: Please be aware that this LoRA is still very experimental and can be still be very difficult to get good results. I will continue to explore ways to improve on the training and workflow. If you notice anything unusual about the results, or have any suggestions on improving the training or workflow feel free to let me know.
Boreal-HL: Boring Reality Hunyuan LoRA
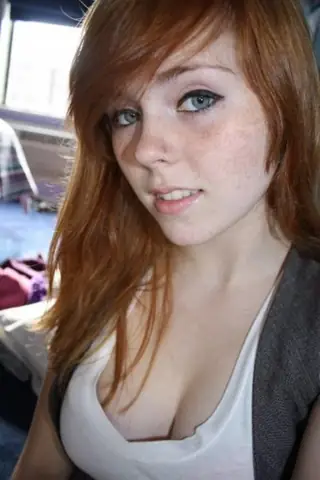
This model is my first attempt at improving the realism details of Hunyuan videos. It focuses on creating more natural backgrounds without shallow depths of field, better skin texture, more realistic lighting, and overall increase in details in a scene.
I followed previous practices in training my other boring reality models where I try to use as diverse of a group of public domain and AI generated photos as possible.
IMPORTANT NOTES FOR USING THIS LORA:
This LoRA is very over-trained. In most scenarios keeping strength at around 0.6 should be good enough. Some prompts and seeds and what not can handle higher strength and give better quality but it is not very consistent.
I have only tested this LoRA so far on the . It is still early in the process of working with Hunyuan workflows and model training so there is still a lot of potential for further improvements down the road here.
Starting out recommended settings:
-
LoRA Strength: 0.6 (0.4-0.9 is the range I mostly worked with if this is the primary lora you are using)
-
Resolution: I would start with something like 512x768 for resolution with a 1.5x upscale. Go higher if not using the upscale. Vertical aspect ratios give more boring realism while wider aspect ratios will make it more cinematic.
-
GUIDANCE: I would start out with a higher guidance like 12.5. It will prevent a lot deformation though you will run into issues such as characters with the same face or same scene. I like to push it down to 3.5 guidance for more interesting images/videos but you have to really work around the seeds/resolution/lora strength to not get a disfigured mess.
-
STEPS: I recommend having a minimum of maybe 30 steps for at least that workflow. You will get better results though if you get up to 55 or so
-
SEED: Be mindful to try swapping out seeds as some will work far better than others.
-
Prompt Recommendations: Try to be descriptive where possible about the actual things and actions in the scene. If you do not provide enough info you may end up with a boring background or a character that always looks the same.
As a general rule of thumb when dealing with distortion try raising the guidance, swapping the seeds, reducing the LoRA strength, increasing the steps, be more descriptive in the prompt, and raise the resolution.
As a general rule to reduce the generic AI look and same characters appearing, try to reduce the guidance, maybe raise the LoRA strength, be more descriptive in the prompt, and swap the seed.
Another note, is that sometimes combing the LoRA with another motion oriented LoRA may lead to more stability in the video output.
Image Generation Capabilities
This LoRA can also generate decent images at times via the first frame. Sometimes they may be more distorted than grabbing a frame from a longer video, so you may need to experiment with the settings mentioned above. I think Hunyuan has a lot of potential to be the next best text2image model. It will take some time though to find a better workflow for utilizing it and maybe improving on the model training.
Additional Info
Video for better demonstrating the different aspects of the LoRA.
SHA256
657972C09D107E6ED41835C23A7E26E005064B2CF071985CE8AC4D8DF2D04465
ID Model ModelTrends.ai
#17372
Laporkan kandungan
Model serupa
Model AI untuk penjanaan imej, video dan teks
boringreality huny ialah LoRA untuk keluarga Hunyuan yang disenaraikan di ModelTrends.ai, katalog baca sahaja untuk model AI imej, video dan teks sumber terbuka. Bandingkannya dengan model Hunyuan lain, semak skor habanya untuk melihat trendnya, dan bukanya di PirateDiffusion atau BitVector untuk mencubanya.
Layari mengikut keluarga model
Model Text / LLM
411
Model Anima
509
Model Chroma
14
Model Flux
1,071
Model Flux 2 / Klein
1,237
Model MiniMax H3
331
Model Hunyuan
197
Model Ideogram
20
Model Krea2
674
Model Qwen
17
Model Qwen2
36
Model Ltx2
150
Model Stable Diffusion 1.5
6,465
Model Stable Diffusion XL 1.0
15,432
Model Zimage
804
Model Wan
919

Model
Trends
.ai
© ModelTrends.ai
|
Dibuat di Jepun
|
© 2026