자동 재생
로컬에서 실행
wan2.2anime to realv2.zip
459 MB · Diffusers
다운로드는 Civitai에서 제공합니다. 일부 제작자는 먼저 Civitai 로그인을 요구합니다.


이 모델에 대하여
WAN · LoRA
by qiaoy123 - anime to real
제작자 노트
To avoid any potential legal risks, please do not buzz me.
请不要给我buzz。
If your initial image has poor results due to disproportionate head-to-body ratios, you can increase the strength of the high-noise LoRA—for example, to 1.2 or even 1.5.
如果你的初始图片头部和身材比例失调而导致效果不好的话,可以增加高噪声部分的lora强度,例如1.2,甚至1.5
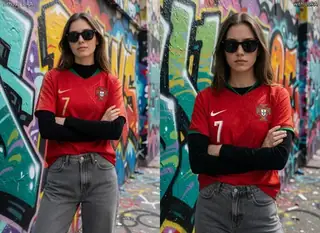
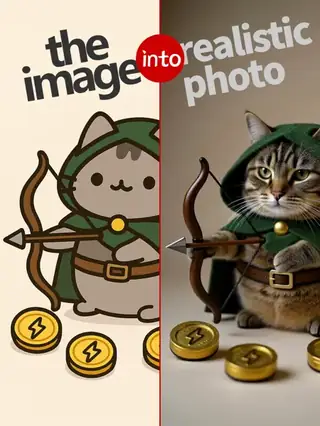
This is an anime-to-real (A2R) LoRA. I haven’t seen this type of LoRA on Civitai, so I decided to create one myself—this way, I don’t have to keep making separate cosplay outfit LoRAs, although I still think the results aren’t quite as good as dedicated outfit LoRAs.
The low-noise part of this LoRA likely needs more training, but I don’t have time for that right now. The high-noise and low-noise components were trained on different datasets. Initially, I used the A2R dataset from XiaoZhi (Jason), which was based on Qwen. I converted real photos into videos using Wan 2.2 i2v, then used Adobe Premiere Pro (PR) to composite the anime images together.
However, since Wan 2.2 isn’t an editing model, when trained on diverse source materials, the resulting model struggled to maintain consistent hair and clothing colors. To address this, I gathered a new, curated dataset and trained a fresh model. Unfortunately, the skin texture turned out quite poor, so I ended up combining the previous low-noise weights with the current high-noise ones—and the result is actually pretty decent.
All training data excludes any uncensored content. When generating images with special poses or actions, you can combine this LoRA with other LoRAs for better results.You can combine this with other i2v or t2v LoRAs available on Civitai to achieve specific poses or actions.
这是一个动漫转真人的lora,我没有在civital看到这种lora,所以我自己做了一个,这样我就不必再去制作cosplay的服装lora了,虽然我认为效果仍然不如服装lora。
这个lora的低噪声部分可能需要更多的训练,不过我暂时没空,高低噪是使用不同的数据集训练的,我最开始是使用小志jason大佬的qwen的a2r的数据集训练的,我将真实图片用wan2.2i2v做成视频,然后用pr将动漫图片拼在一起。但是由于wan2.2不是编辑模型,在素材种类多的情况下,训练出的模型无法控制发色和服装颜色的一致性,所以我自己找了一批素材炼了新的模型,但是皮肤质感很糟糕,所以我用之前的低噪搭配现在的高噪,效果还不错。
训练素材不包含未经审查的内容,有特殊动作时,使用的时候可以搭配其他的lora。
你可以搭配civital上其他的i2v或者t2v lora来完成一些特殊的动作
SHA256
10361B10E7C6C8154F84397BB2608BE2A19364BE6C7BB462375FE8CE4445D916
ModelTrends.ai 모델 ID
#21685
콘텐츠 신고
예시 작품
Civitai에서 이 작품들을 만든 사람들이 공유한 프롬프트와 설정입니다. 작품을 선택하면 어떻게 만들어졌는지 볼 수 있습니다.
설정
샘플러
Euler a
스텝
20
가이던스
1
시드
-1
크기
576x1024
프롬프트
动漫转真人
설정
샘플러
Euler a
스텝
20
가이던스
1
시드
-1
크기
576x1024
프롬프트
动漫转真人
설정
샘플러
Euler a
스텝
20
가이던스
1
시드
-1
크기
576x1024
프롬프트
动漫转真人
설정
샘플러
Euler a
스텝
20
가이던스
1
시드
-1
크기
576x1024
프롬프트
动漫转真人
설정
샘플러
Euler a
스텝
20
가이던스
1
시드
-1
크기
576x1024
프롬프트
动漫转真人
이미지·영상·텍스트 생성을 위한 AI 모델
animetoreal high wan은(는) Wan 패밀리용 LoRA으로, 오픈 소스 AI 이미지·영상·텍스트 모델의 읽기 전용 카탈로그인 ModelTrends.ai에 등록되어 있습니다. 다른 Wan 모델과 비교하고, 열기 점수로 트렌드를 확인하고, PirateDiffusion 또는 BitVector에서 열어 사용해 보세요.
모델 패밀리별로 보기
Text / LLM 모델
411
Anima 모델
509
Chroma 모델
14
Flux 모델
1,071
Flux 2 / Klein 모델
1,237
MiniMax H3 모델
331
Hunyuan 모델
197
Ideogram 모델
20
Krea2 모델
674
Qwen 모델
17
Qwen2 모델
36
Ltx2 모델
150
Stable Diffusion 1.5 모델
6,465
Stable Diffusion XL 1.0 모델
15,432
Zimage 모델
804
Wan 모델
919

Model
Trends
.ai
© ModelTrends.ai
|
일본에서 제작
|
© 2026