- #1
Qwen3.6 35B A3B
Qwen | 262,144 token context | $0.15/M input, $1.00/M output. Qwen3.6-35B-A3B is an open-weight multimodal model from Alibaba Cloud with 35 billion total parameters and 3 billion active parameters per token. It uses a hybrid sparse…Qwen | 262,144 token context | $0.15/M input, $1.00/M output. Qwen3.6-35B-A3B is an open-weight multimodal model from Alibaba Cloud with 35 billion total parameters and 3 billion active parameters per token. It uses a hybrid sparse mixture-of-experts architecture combining Gated DeltaNet linear attention with standard gated attention layers, enabling efficient inference at a fraction of the compute cost. The model supports a 262K token native context window (extensible to 1M via YaRN) and accepts text, image, and video inputs. It includes integrated thinking mode with reasoning traces preserved across multi-turn conversations, function calling, and structured output. Released under the Apache 2.0 license.
- #2
Blowjob cheek bulge 101 H3
By crafted101 - (v1) A detailed, explicit concept for a cheek-bulge oral sex LoRA: Core concept: During a blowjob, the penis is pushed sideways into the inside of the cheek so that the shaft creates a clear, rounded, protruding bulge on…By crafted101 - (v1) A detailed, explicit concept for a cheek-bulge oral sex LoRA: Core concept: During a blowjob, the penis is pushed sideways into the inside of the cheek so that the shaft creates a clear, rounded, protruding bulge on the outside of the face. The cheek stretches tightly around the penis, forming a visible outline of the head and shaft pressing against the skin from within. Key visual elements to capture: Strong, realistic cheek deformation / stretch Clear cylindrical or rounded bulge shape showing the penis outline under the skin Skin tension and slight translucency or vein visibility on the stretched cheek Lips sealed or partially open around the shaft, saliva/wetness Angle usually side-profile or 3/4 view so the bulge is obvious Optional: slight outward push of the cheek, soft tissue displacement, realistic lighting on the stretched skin
- #3
SNOFS (Sex, Nudes, Other Fun Stuff) Krea 2 v1.5
Sex positon enhancer. a weight of 1 is recommended - #4
Step 5 Preview
StepFun | 1,048,576 token context | $1.00/M input, $2.70/M output. Step 5 Preview is StepFun's flagship model for agentic work, built on a sparse Mixture-of-Experts architecture (27B active / 600B total parameters). It performs strongly in…StepFun | 1,048,576 token context | $1.00/M input, $2.70/M output. Step 5 Preview is StepFun's flagship model for agentic work, built on a sparse Mixture-of-Experts architecture (27B active / 600B total parameters). It performs strongly in software engineering and professional knowledge work, with particular strength in finance. It is designed for extended tasks that span large codebases and documents, using tools and refining results over multiple steps.
- #5
Qwen Image 2.1 Restore LoRA
By AusBoss - A LoRA that softens the harsh upscale Qwen Image 2.1 does by itself: the result is a little softer, still detailed, makes up less, and stays true to your picture. Qwen Image 2.1 can upscale a small or worn picture without this…By AusBoss - A LoRA that softens the harsh upscale Qwen Image 2.1 does by itself: the result is a little softer, still detailed, makes up less, and stays true to your picture. Qwen Image 2.1 can upscale a small or worn picture without this LoRA, but it overdoes it. Skin turns gritty, pores and freckles show up that were not there, faces look older, and the picture shifts a few pixels. With this LoRA the result stays on your picture. Blurry photos need a lower strength. If your picture is out of focus, shaky, or a frame from a video, set the LoRA to 0.5. At 1.0 it stays true to the blur and the result comes back soft. A small or compressed picture that is in focus is fine at 1.0. No trigger word. Start at strength 1.0, enlarge your picture to about 2 megapixels, give it as image 1, and ask: Restore the photo: remove blur, noise and compression artifacts and recover sharp, natural detail, keeping the same composition, people and colors. For scratched or faded prints: Restore the old photo: remove scratches, dust, fading and grain and recover sharp, natural detail and color, keeping the same composition and people. On an old print it takes out scratches, dust and grain and brings back most of the color.
- #6
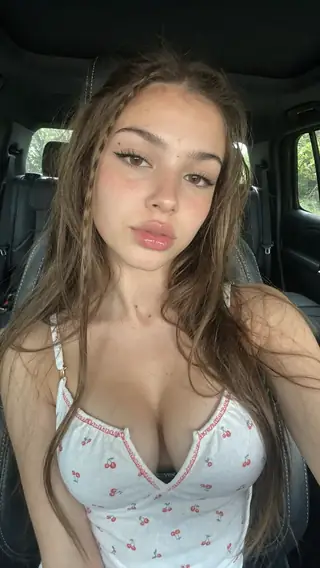
nsfw posture v3
by ynamely - nsfw-posture-v3 - Sexual positions lora, First-person oral sex, Third-person oral sex, Breast sex, Foot sex - #7
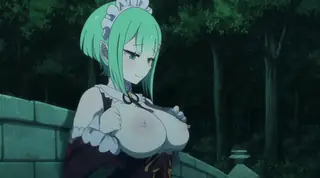
2D Anime Style NSFW LORA H3 v0.5 general NSFW
by tazmannner379 - 2D Anime Style NSFW LORA - H3 V0.5 - For specific words, it was consistently trained on these terms: penis, vagina, vaginal, testicles, penetration, insert, breasts, bouncing, jiggle, anus, anal, buttocks, plopping sound…by tazmannner379 - 2D Anime Style NSFW LORA - H3 V0.5 - For specific words, it was consistently trained on these terms: penis, vagina, vaginal, testicles, penetration, insert, breasts, bouncing, jiggle, anus, anal, buttocks, plopping sound (for both sucking and penetrating), cowgirl, reverse cowgirl, doggy style, missionary, deep throat, thrust (for thrusting hips), blow job, suck, cum, cumming, deep breathing, heavy breathing, moan, grunt, insert, pull out, tentacle, ass ripple (for jiggling ass cheeks). It is trained on sound: moan, grunt, use "plopping" sounds fucking / sucking sounds.
- #8
Nemotron 3 Super
NVIDIA | contesto da 262.144 token | $0.08/M input, $0.45/M output. NVIDIA Nemotron 3 Super è un modello ibrido MoE open da 120B parametri, che attiva solo 12B parametri per la massima efficienza computazionale e accuratezza in…NVIDIA | contesto da 262.144 token | $0.08/M input, $0.45/M output. NVIDIA Nemotron 3 Super è un modello ibrido MoE open da 120B parametri, che attiva solo 12B parametri per la massima efficienza computazionale e accuratezza in applicazioni multi-agente complesse. Basato su un’architettura ibrida Mamba-Transformer Mixture-of-Experts con predizione multi-token (MTP), offre oltre il 50% in più di generazione token rispetto ai principali modelli open. Il modello presenta una finestra di contesto da 1M token per coerenza agentica a lungo termine, ragionamento cross-documento e pianificazione di compiti multi-step. Il MoE latente permette di chiamare 4 esperti al costo inferenziale di uno solo, migliorando intelligenza e generalizzazione. L’addestramento RL multi-ambiente su oltre 10 ambienti garantisce accuratezza leader su benchmark come AIME 2025, TerminalBench e SWE-Bench Verified. Completamente open con pesi, dataset e ricette sotto NVIDIA Open License, Nemotron 3 Super consente facile personalizzazione e deployment sicuro ovunque — dalla workstation al cloud.
- #9
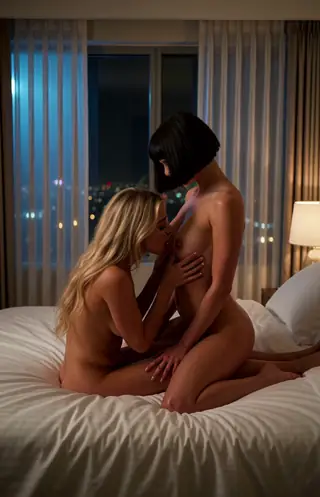
Nipple Sucking
by kermitfrog1202 - Nipple Sucking - #10
GLM 5.3
Z.ai | contesto da 1.048.576 token | $0.08/M input, $4.80/M output. GLM-5.3 è un modello di ragionamento su larga scala di Z.ai, costruito per ingegneria del software complessa e compiti agentici a lungo termine. Supporta input e output…Z.ai | contesto da 1.048.576 token | $0.08/M input, $4.80/M output. GLM-5.3 è un modello di ragionamento su larga scala di Z.ai, costruito per ingegneria del software complessa e compiti agentici a lungo termine. Supporta input e output testuali con una finestra di contesto da 1M token, e migliora GLM-5.2 nel coding e nell'equilibrio tra prestazioni ed efficienza dei token. Il ragionamento è sempre attivo e non può essere disabilitato. Supporta sforzi di ragionamento low, high e max; max è il valore predefinito.
- #11
Nemotron 3.5 Lightning
NVIDIA | contesto da 262.144 token | $0.07/M input, $0.20/M output. NVIDIA Nemotron 3.5 Lightning è un modello open Mixture-of-Experts di NVIDIA, con 3B parametri attivi su 30B totali. È adatto per carichi di lavoro agentici ad alto…NVIDIA | contesto da 262.144 token | $0.07/M input, $0.20/M output. NVIDIA Nemotron 3.5 Lightning è un modello open Mixture-of-Experts di NVIDIA, con 3B parametri attivi su 30B totali. È adatto per carichi di lavoro agentici ad alto throughput e compiti specializzati che beneficiano di personalizzazioni specifiche per dominio.
- #12
Gemma 4 26B A4B
Google | contesto da 262.144 token | $0.09/M input, $0.30/M output. Gemma 4 26B A4B IT è un modello Mixture-of-Experts (MoE) istruito con istruzioni di Google DeepMind. Nonostante 25.2B parametri totali, solo 3.8B si attivano per token…Google | contesto da 262.144 token | $0.09/M input, $0.30/M output. Gemma 4 26B A4B IT è un modello Mixture-of-Experts (MoE) istruito con istruzioni di Google DeepMind. Nonostante 25.2B parametri totali, solo 3.8B si attivano per token durante l’inferenza — offrendo qualità quasi da 31B a una frazione del costo computazionale. Supporta input multimodale inclusi testo, immagini e video (fino a 60s a 1fps). Presenta una finestra di contesto da 256K token, chiamata di funzione nativa, modalità di pensiero/ragionamento configurabile e supporto per output strutturati. Rilasciato sotto Apache 2.0.
- #13
MiMo V2.6 Pro
Xiaomi | contesto da 1.050.000 token | $0.43/M input, $0.87/M output. MiMo-V2.6-Pro è il modello fondazionale di punta sviluppato da Xiaomi. Costruito su una scala di oltre 1T parametri, è progettato per spingere al massimo le capacità per…Xiaomi | contesto da 1.050.000 token | $0.43/M input, $0.87/M output. MiMo-V2.6-Pro è il modello fondazionale di punta sviluppato da Xiaomi. Costruito su una scala di oltre 1T parametri, è progettato per spingere al massimo le capacità per i carichi di lavoro più esigenti. Il modello presenta una finestra di contesto da 1M token e capacità multimodali native. Ottimizzato per flussi di lavoro agentici, offre prestazioni di alto livello in scenari di coding, visivi, generali e di ricerca, eccellendo in compiti complessi e a lungo termine con una robusta generalizzazione su una vasta gamma di agent harness.
- #14
krea2 enf embarrassed nude female
by hamstornado - krea2 enf embarrassed nude female - #15
MiMo V2.6 Flash
Xiaomi | contesto da 1.050.000 token | $0.14/M input, $0.28/M output. MiMo-V2.6-Flash è un modello foundation open-source sviluppato da Xiaomi. Costruito su un'architettura Mixture-of-Experts con 309B parametri totali e 15B attivati per…Xiaomi | contesto da 1.050.000 token | $0.14/M input, $0.28/M output. MiMo-V2.6-Flash è un modello foundation open-source sviluppato da Xiaomi. Costruito su un'architettura Mixture-of-Experts con 309B parametri totali e 15B attivati per token, impiega un meccanismo di attenzione ibrido per una maggiore efficienza computazionale. Il modello presenta una finestra di contesto da 1M token e capacità multimodali native. Ottimizzato per flussi di lavoro agentici, offre prestazioni solide in coding, visione, scenari generali e di ricerca, eccellendo in compiti complessi a lungo termine con robusta generalizzazione su una vasta gamma di harness agentici.
- #16

DeepSeek V4.1 Flash
DeepSeek | 1,048,576 token context | $0.04/M input, $0.68/M output. DeepSeek V4.1 Flash is a sparse mixture-of-experts model from DeepSeek, and the first built on the company's Causal Encoder-Decoder (CED) architecture. It activates 8B…DeepSeek | 1,048,576 token context | $0.04/M input, $0.68/M output. DeepSeek V4.1 Flash is a sparse mixture-of-experts model from DeepSeek, and the first built on the company's Causal Encoder-Decoder (CED) architecture. It activates 8B parameters on input and 16B on output from a 552B-parameter backbone, an asymmetric split that keeps per-token compute low relative to the model's total size. Image understanding is native to the architecture, with visual and text embeddings trained jointly from the start of pre-training rather than added afterward as in the earlier experimental V4 Flash Vision ExpOpens in new tab. It is suited for coding, terminal, and computer-use agents, along with long-horizon tasks that must run to completion across many steps and long-context analysis. Compressed KV caching cuts cache memory to roughly a quarter of the previous Flash generation, significantly reducing costs on agentic workloads. DeepSeek positions it as the cost-efficient tier of the V4.1 family and reports that it exceeds V4 ProOpens in new tab on performance, speed, and task completion time.
- #17
Qwen3.8 Flash
Qwen | contesto da 1.000.000 token | $0.15/M input, $0.47/M output. Qwen3.8 Flash è un modello di ragionamento multimodale di Alibaba. È adatto per assistenza al coding, flussi di lavoro agentici, comprensione visiva, analisi di documenti…Qwen | contesto da 1.000.000 token | $0.15/M input, $0.47/M output. Qwen3.8 Flash è un modello di ragionamento multimodale di Alibaba. È adatto per assistenza al coding, flussi di lavoro agentici, comprensione visiva, analisi di documenti e codebase, interazione desktop, analisi di grafici e analisi di video lunghi.
- #18
[Qwen Image] Asian Mix Lora
by hinablue - [Qwen Image] Asian Mix Lora - v3.0 - Q21 - rank64 Trained using a custom-built trainer with a dataset of 6,000 images, using Rank 64, and merged with v2.0 via SVD to create this LoRA. It is more stable at a weight below 0.8.…by hinablue - [Qwen Image] Asian Mix Lora - v3.0 - Q21 - rank64 Trained using a custom-built trainer with a dataset of 6,000 images, using Rank 64, and merged with v2.0 via SVD to create this LoRA. It is more stable at a weight below 0.8. Limb/anatomy issues may still occasionally occur, so please use at your own discretion.
- #19
Qwen3.8 27B
Qwen | 1,000,000 token context | $0.24/M input, $2.20/M output. Qwen3.8 27B is an open-weight dense vision-language model from Qwen. It is suited for coding, professional workflows, research, multimodal interaction, and long-running agent…Qwen | 1,000,000 token context | $0.24/M input, $2.20/M output. Qwen3.8 27B is an open-weight dense vision-language model from Qwen. It is suited for coding, professional workflows, research, multimodal interaction, and long-running agent tasks, with flexible thinking that can be enabled or disabled.
- #20
Hy3
Tencent | 262,144 token context | $0.13/M input, $0.53/M output. Hy3 is a 295B-parameter Mixture-of-Experts model from Tencent (21B active, 192 experts with top-8 routing) built for reasoning, agentic workflows, and real-world production…Tencent | 262,144 token context | $0.13/M input, $0.53/M output. Hy3 is a 295B-parameter Mixture-of-Experts model from Tencent (21B active, 192 experts with top-8 routing) built for reasoning, agentic workflows, and real-world production use. It supports a configurable reasoning effort: a direct no-think mode by default, plus low and high chain-of-thought modes for complex math, coding, and multi-step problems. With a 256K context window, Hy3 targets long-horizon tasks, including improved coreference resolution, multi-turn constraint tracking, and stable tool-calling that generalizes across agent scaffoldings. Tencent positions it as a reliable, cost-effective option across coding, document processing, financial analysis, game development, and frontend design, with a strong emphasis on grounded, anti-hallucination behavior that answers when grounded and flags when evidence is missing rather than fabricating.
- #21
Gemma 4 31B
Google | 262,144 token context | $0.20/M input, $0.40/M output. Gemma 4 31B Instruct is Google DeepMind's 30.7B dense multimodal model supporting text and image input with text output. Features a 256K token context window, configurable…Google | 262,144 token context | $0.20/M input, $0.40/M output. Gemma 4 31B Instruct is Google DeepMind's 30.7B dense multimodal model supporting text and image input with text output. Features a 256K token context window, configurable thinking/reasoning mode, native function calling, and multilingual support across 140+ languages. Strong on coding, reasoning, and document understanding tasks. Apache 2.0 license.
- #22
gpt oss 120b
OpenAI | contesto da 131.072 token | $0.15/M input, $0.60/M output. gpt-oss-120b è un modello linguistico Mixture-of-Experts (MoE) open-weight da 117B parametri di OpenAI progettato per casi d’uso di produzione ad alto ragionamento,…OpenAI | contesto da 131.072 token | $0.15/M input, $0.60/M output. gpt-oss-120b è un modello linguistico Mixture-of-Experts (MoE) open-weight da 117B parametri di OpenAI progettato per casi d’uso di produzione ad alto ragionamento, agentici e generali. Attiva 5.1B parametri per ogni passaggio forward ed è ottimizzato per funzionare su una singola GPU H100 con quantizzazione MXFP4 nativa. Il modello supporta profondità di ragionamento configurabile, accesso completo alla catena di pensiero e uso nativo di strumenti, inclusi chiamate di funzione, navigazione e generazione di output strutturati.
- #23
- #24
Hy4 preview
Tencent | 1,048,576 token context | $0.83/M input, $2.50/M output. Tencent: Hy4 preview is a mixture-of-experts model from Tencent, with 49B active parameters out of 770B total. It is designed for coding agents, complex tool-use workflows,…Tencent | 1,048,576 token context | $0.83/M input, $2.50/M output. Tencent: Hy4 preview is a mixture-of-experts model from Tencent, with 49B active parameters out of 770B total. It is designed for coding agents, complex tool-use workflows, and productivity tasks that require planning, context continuity, and sustained multi-step execution.
- #25
MiniMax M3
MiniMax | contesto da 1.048.576 token | $0.30/M input, $1.20/M output. MiniMax-M3 è un modello foundation multimodale di MiniMax. Supporta input testuali, immagini e video con output testuale, una finestra di contesto da 1M token, ed è…MiniMax | contesto da 1.048.576 token | $0.30/M input, $1.20/M output. MiniMax-M3 è un modello foundation multimodale di MiniMax. Supporta input testuali, immagini e video con output testuale, una finestra di contesto da 1M token, ed è adatto per lavoro agentico a lungo termine, coding e uso di strumenti. È costruito su MiniMax Sparse Attention (MSA), che sostituisce l'attenzione completa con selezione KV-block per ridurre il calcolo per token su contesti lunghi — circa 1/20 del costo della generazione precedente a 1M token, con prefill e decode sostanzialmente più veloci mantenendo qualità su quasi tutti i compiti. Addestrato come modello multimodale nativo su dati intercalati e ottimizzato per collaborazione multi-turno simile a produzione tramite un framework interattivo con simulatore utente, il modello è orientato a compiti sostenuti e multi-step piuttosto che a esecuzione single-turn.
- #26
DeepSeek V4 Pro 0813
DeepSeek | 1,048,576 token context | $1.32/M input, $3.96/M output. DeepSeek V4 Pro 0813 is a large-scale mixture-of-experts model from DeepSeek. This is the GA release of DeepSeek V4 Pro. - #27
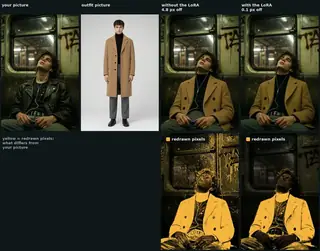
Qwen Image 2.1 Outfit Swap Consistency LoRA
by AusBoss - Qwen Image 2.1 Outfit Swap Consistency LoRA - Qwen Image 2.1 can already dress a person in the outfit from another picture. The result comes back a few pixels off, the face a little softer, the background repainted. With this…by AusBoss - Qwen Image 2.1 Outfit Swap Consistency LoRA - Qwen Image 2.1 can already dress a person in the outfit from another picture. The result comes back a few pixels off, the face a little softer, the background repainted. With this LoRA only the clothes change. No trigger word. Load it at strength 1.0, give the person as image 1 and the outfit as image 2, and ask for the swap
- #28
Cum Shots
By kermitfrog1202 - (v1) Another cumshot helper LoRA for MiniMax H3. Trigger: He ejaculates spurts of semen land on her [insert body part]. Comments indicated this one was very good at having more realistic cumshots rather than the milk…By kermitfrog1202 - (v1) Another cumshot helper LoRA for MiniMax H3. Trigger: He ejaculates spurts of semen land on her [insert body part]. Comments indicated this one was very good at having more realistic cumshots rather than the milk bucket dumps that most other LoRAs cause.
- #29
Cameltoe Qwen 2.1
by kermitfrog1202 - Cameltoe - #30
GLM 5.3 Flash
Z.ai | 1,048,576 token context | $0.02/M input, $0.72/M output. GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture…Z.ai | 1,048,576 token context | $0.02/M input, $0.72/M output. GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture maintains accurate long-context behavior while reducing compute overhead. Yes, the stealth model Ox Alpha was revealed to be ZAI's new model, GLM-5.3 Flash.
- #31
Laguna S 2.1
Poolside | contesto da 1.048.576 token | $0.09/M input, $0.18/M output. Laguna S 2.1 è l'ultimo modello per agenti di coding di PoolsideOpens in new tab. Laguna S 2.1 è un modello da 118B parametri totali con 8B parametri attivi, che…Poolside | contesto da 1.048.576 token | $0.09/M input, $0.18/M output. Laguna S 2.1 è l'ultimo modello per agenti di coding di PoolsideOpens in new tab. Laguna S 2.1 è un modello da 118B parametri totali con 8B parametri attivi, che ottiene il 70.2% su Terminal-Bench 2.1 e il 40.4% su DeepSWE, rendendolo uno dei modelli di coding più forti nella sua categoria. Open-weight sotto licenza OpenMDW-1.1. Laguna S 2.1 è progettato per casi d'uso di ingegneria del software e coding agentico, e sei responsabile di confermare che sia appropriato per la tua applicazione prevista. Laguna S 2.1 è soggetto alla licenza OpenMDW-1.1Opens in new tab, e dovrebbe essere usato in conformità con la Acceptable Use PolicyOpens in new tab di Poolside. Si sconsiglia di aggirare le salvaguardie di sicurezza di Laguna S 2.1 senza implementare mitigazioni sostanzialmente equivalenti appropriate per il tuo caso d'uso. Si prega di segnalare vulnerabilità di sicurezza o preoccupazioni sulla sicurezza a [email protected]. Se usi Laguna S 2.1 gratuitamente, potremmo usare i tuoi input e output per addestrare e migliorare i nostri modelli.
- #32
MoreReal
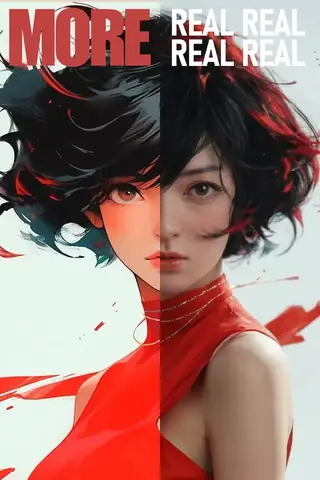
by NO8D - MoreReal - It is a A2R LoRA capable of converting any image into a photorealistic photograph. Weight : 0.6~0.9. Steps : 30/40 - #33
Photo/Detail Slider for SNOFS Krea
By Ashen3 - V2 is a photo/detail slider that was trained directly on SNOFS Krea 1.4. Krea 2 was trained on a ton of artwork, especially for sexual things, and so the model likes to pull in that direction. I've lessened this problem over…By Ashen3 - V2 is a photo/detail slider that was trained directly on SNOFS Krea 1.4. Krea 2 was trained on a ton of artwork, especially for sexual things, and so the model likes to pull in that direction. I've lessened this problem over time and will further 'fix' the issue but fro now, this works wonderfully. The range is about -3 to 3. Negative values will pull toward illustration/anime. Higher values will pull towards photos.
- #34
Qwen Image 2.1 Anime2Real
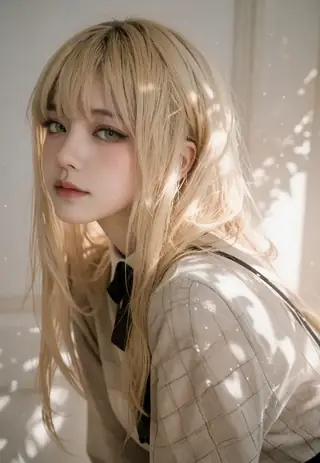
by arpalest - Qwen Image 2.1 Anime2Real - A new Alpha version focused on achieving a truly realistic, photorealistic appearance from anime-style images, including more realistic skin texture. Recommended LoRA weight: 0.8 - #35
Qwen Image 2.1 Consistency LoRA
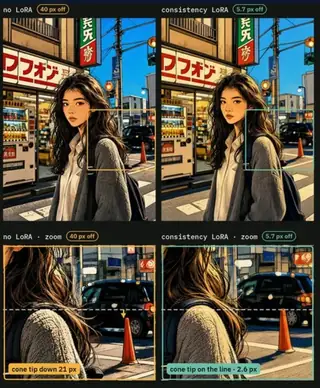
by AusBoss - Qwen Image 2.1 Consistency LoRA - Ask Qwen Image 2.1 for a watercolor, a comic or an anime version of a picture and it comes back a few percent taller, sometimes nudged sideways, different for every seed. A waistband lands 40…by AusBoss - Qwen Image 2.1 Consistency LoRA - Ask Qwen Image 2.1 for a watercolor, a comic or an anime version of a picture and it comes back a few percent taller, sometimes nudged sideways, different for every seed. A waistband lands 40 px lower, a horizon jumps 25 px, a face no longer lines up with the original. On a local edit ("make the cardigan navy") it also repaints things you didn't ask about: hair strands, signs, texture. That breaks anything that stacks the edit on the original: masks, stitching, before/after sliders, video frames. With this LoRA the same prompt makes the same edit, on the original's frame. No trigger word: load it and write your edit instruction as usual
- #36
krea2 sex 淫模 LUF
by EasonnLi - krea2 sex 淫模 (Leg Up Fuck) - #37
DeepSeek V4 Flash 0423
DeepSeek | contesto da 1.048.576 token | $0.09/M input, $0.18/M output. DeepSeek V4 Flash è un modello Mixture-of-Experts ottimizzato per l'efficienza di DeepSeek con 284B parametri totali e 13B parametri attivi, supportando una finestra…DeepSeek | contesto da 1.048.576 token | $0.09/M input, $0.18/M output. DeepSeek V4 Flash è un modello Mixture-of-Experts ottimizzato per l'efficienza di DeepSeek con 284B parametri totali e 13B parametri attivi, supportando una finestra di contesto da 1M token. È progettato per inferenza veloce e carichi di lavoro ad alto throughput, mantenendo forti prestazioni in ragionamento e coding. Il modello include attenzione ibrida per un'elaborazione efficiente di contesti lunghi. Supporta sforzi di ragionamento high e xhigh; xhigh corrisponde al ragionamento massimo. È adatto per applicazioni come assistenti di coding, sistemi di chat e flussi di lavoro agentici dove reattività ed efficienza dei costi sono importanti.
- #38
Kimi K3
MoonshotAI | 1,048,576 token context | $0.30/M input, $11.94/M output. Kimi K3 is a 2.8T parameter open-weight multimodal reasoning model from Moonshot AI. It is suited for complex coding, knowledge work, and long-horizon agentic…MoonshotAI | 1,048,576 token context | $0.30/M input, $11.94/M output. Kimi K3 is a 2.8T parameter open-weight multimodal reasoning model from Moonshot AI. It is suited for complex coding, knowledge work, and long-horizon agentic workflows, and is particularly strong at navigating large repositories, using tools, debugging, and iterating against images, logs, tests, and runtime feedback. Its architecture uses KDA and Attention Residuals for computational efficiency.
- #39
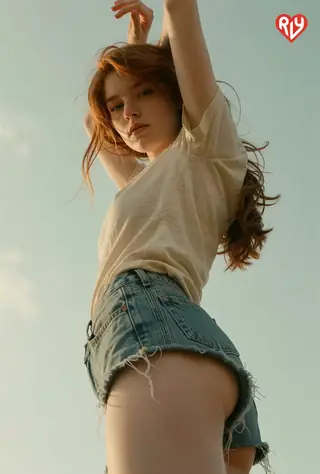
RLY Thot Shot Nell (KREA 2 + ZiT)
By RaymondLuxuryYacht - AI fantasy character for Krea 2. Nell is a 23 year old Scottish professional Ballerina. She has already danced for some of the largest groups in the UK, including the Royal and Scottish Ballets. Her ultimate goal is…By RaymondLuxuryYacht - AI fantasy character for Krea 2. Nell is a 23 year old Scottish professional Ballerina. She has already danced for some of the largest groups in the UK, including the Royal and Scottish Ballets. Her ultimate goal is to be recognized as a Prima ballerina assoluta, an honor reserved for only the best in the world. She has a real shot if she continues on her current path. Privately she is very insular, keeping her socializing to a very small group of close friends. She does not typically go out on weekends and is not on any dating Apps. She has met both of her past partners while on tour, but neither lasted longer than a year. She isn't sure why, but suspects it might be due to her asocial preferences. She'd much rather Netflix and chill than go to a bar or club. She's looking for someone to champion her dancing goals and who fits her more muted social lifestyle.
- #40
Nemotron 3 Ultra
NVIDIA | contesto da 262.144 token | $0.60/M input, $2.40/M output. NVIDIA Nemotron 3 Ultra è un modello open frontier-reasoning e orchestrazione di NVIDIA, con 55B parametri attivi su 550B totali (MoE). Costruito su un'architettura ibrida…NVIDIA | contesto da 262.144 token | $0.60/M input, $2.40/M output. NVIDIA Nemotron 3 Ultra è un modello open frontier-reasoning e orchestrazione di NVIDIA, con 55B parametri attivi su 550B totali (MoE). Costruito su un'architettura ibrida Transformer-Mamba mixture-of-experts, supporta input e output testuali con una finestra di contesto fino a 1M token. È adatto per flussi di lavoro agentici a lunga durata, inclusa orchestrazione agentica, agenti di coding, ricerca approfondita e compiti aziendali complessi. È particolarmente forte nel ragionamento e pianificazione multi-step, con inferenza ad alto throughput progettata per pipeline agentiche ad alto volume. Fa parte della famiglia NVIDIA Nemotron di modelli aperti per AI agentica.
- #41
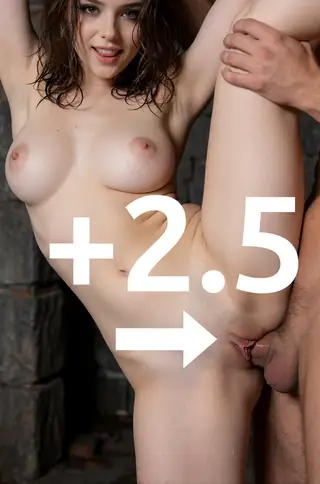
Depth Charge
By arsibalt - (v1) Slider / helper LoRA for controlling penetration depth with Krea 2 Important: Use this slider with a hardcore NSFW checkpoint or LoRA. Start with -1.0 to +2.0 range, but pump it up depending on your checkpoint and LoRA…By arsibalt - (v1) Slider / helper LoRA for controlling penetration depth with Krea 2 Important: Use this slider with a hardcore NSFW checkpoint or LoRA. Start with -1.0 to +2.0 range, but pump it up depending on your checkpoint and LoRA stack and even your composition (it might not know how to move legs around to achieve more depth). Some complex stacks can require a +3.0 or +4.0 to jam it all the way in. Also: not for deepthroat shots; you can find other LoRAs for that.
- #42
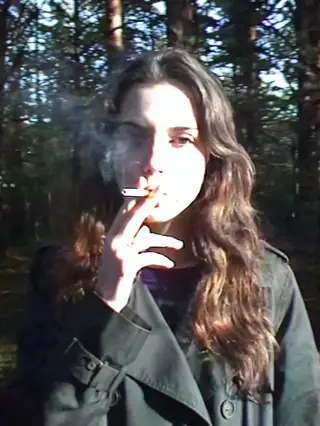
2000s Analog Core v1.0 Qwen2.1
by Danrisi - 2000s Analog Core - 0.7 strength, can be used with other loras - #43
DeepSeek V4 Pro 0423
DeepSeek | 1,048,576 token context | $0.96/M input, $1.91/M output. DeepSeek V4 Pro is a large-scale Mixture-of-Experts model from DeepSeek with 1.6T total parameters and 49B activated parameters, supporting a 1M-token context window. It…DeepSeek | 1,048,576 token context | $0.96/M input, $1.91/M output. DeepSeek V4 Pro is a large-scale Mixture-of-Experts model from DeepSeek with 1.6T total parameters and 49B activated parameters, supporting a 1M-token context window. It is designed for advanced reasoning, coding, and long-horizon agent workflows, with strong performance across knowledge, math, and software engineering benchmarks. Built on the same architecture as DeepSeek V4 Flash, it introduces a hybrid attention system for efficient long-context processing. Reasoning efforts high and xhigh are supported; xhigh maps to max reasoning. It is well suited for complex workloads such as full-codebase analysis, multi-step automation, and large-scale information synthesis, where both capability and efficiency are critical
- #44
krea2 sex 淫模 DFS
By EasonnLi - Doggystyle-from-side sex position helper LoRA for Krea 2 - #45
GLM 5.2
Z.ai | 1,048,576 token context | $0.04/M input, $9.00/M output. GLM 5.2 is a large-scale reasoning model from Z.ai. It supports text input and output with a 1M-token context window, and is suited for long-horizon agent workflows,…Z.ai | 1,048,576 token context | $0.04/M input, $9.00/M output. GLM 5.2 is a large-scale reasoning model from Z.ai. It supports text input and output with a 1M-token context window, and is suited for long-horizon agent workflows, project-level software engineering, and complex multi-step automation. Reasoning efforts high and xhigh are supported; xhigh maps to max reasoning. It is particularly strong at coding and tool use across long-running tasks, able to maintain engineering context and follow standards consistently through a full development workflow, from requirements to multi-platform deployment, in a single task.
- #46
Deblur anything
by Luntrix - Deblur anything - It will remove blur (...like even heavy blur and magically figure out what was in original image, wtf). Can be used also for upscaling but it was trained only on gaussian blur and not resized images (from…by Luntrix - Deblur anything - It will remove blur (...like even heavy blur and magically figure out what was in original image, wtf). Can be used also for upscaling but it was trained only on gaussian blur and not resized images (from lanczos) so will probably make separate lora. It does not remove blurry background/bokeh
- #47
Breast Physics
by kermitfrog1202 - Breast Physics - There is no specific trigger word or phrase... it just adds some jiggle and some natural movement to the titties. - #48
Lotus Sex Position
By kermitfrog1202 - (v1) Lotus sex position helper for MiniMax H3. Author notes that some training samples were in a letterbox position, which could affect some outputs. - #49
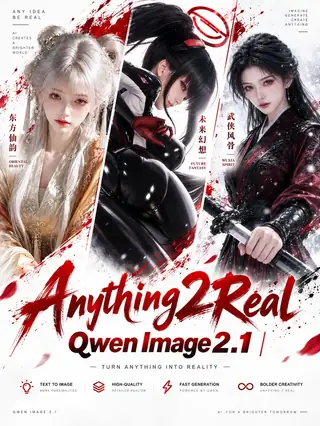
Anything2RealCharacters Qwen2.1
by AIGC_Singularity - Anything2RealCharacters - #50
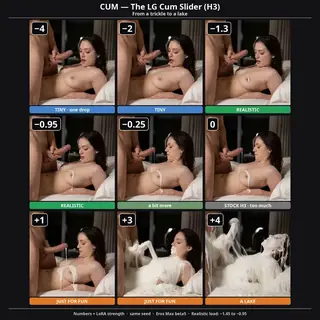
CUM : The LG Cum Slider (H3)
By - LORAGEEK No trigger word. The LoRA strength is the dial. From a TRICKLE to a LAKE Stock MiniMax H3 finishes with far too much cum. Three drops land on her breast, and by the time it runs down there's a full cup. A real man makes about…By - LORAGEEK No trigger word. The LoRA strength is the dial. From a TRICKLE to a LAKE Stock MiniMax H3 finishes with far too much cum. Three drops land on her breast, and by the time it runs down there's a full cup. A real man makes about a teaspoon, a tablespoon at most. The LG Cum Slider puts the amount in your hands. Turn it down for a realistic load, all the way down to a single drop. Turn it up and he fills the bed. As far as I can find, it's the first cum slider for video. The dial Strength What you get −4.0 A single drop of fine, thin cum −2.0 A small amount, thin and semi-white −1.45 to −0.95 Realistic. A normal human load ⭐️ −0.25 A bit more than a real man 0 Stock H3: way too much, covers her whole breast +1.0 Floods both breasts and runs down her stomach +3.0 Sprayed all over her body, filling the bed +4.0 A lake. Over her head and the pillows. He would not survive this. It's very fine. Even a 0.02 change shows, so you can dial in exactly the amount you want. Negative numbers are the point. Most LoRA loaders accept them; just type the minus sign.
Il calore è il nostro punteggio interno di tendenza, da freddo a 9999°. Cambia ogni giorno con i segnali di utilizzo e popolarità delle community e dei servizi attorno a ciascun modello. La classifica copre modelli base, LoRA, embedding e modelli di testo di tutte le famiglie del catalogo.
Sfoglia per famiglia di modelli