- #1
- #2

flux2
FLUX.2 [dev] is Black Forest Labs' second-generation open-weights image model, released in November 2025. It is a much larger flow-matching transformer than FLUX.1 that uses the Mistral Small 3.1 vision-language model as its text encoder,…FLUX.2 [dev] is Black Forest Labs' second-generation open-weights image model, released in November 2025. It is a much larger flow-matching transformer than FLUX.1 that uses the Mistral Small 3.1 vision-language model as its text encoder, which gives it far better understanding of long, descriptive prompts, reliable multi-line typography and real-world knowledge about brands, materials and lighting. It was designed from the start as a unified model: the same weights generate from text, edit an existing picture from instructions, and combine up to ten reference images for character, product or style consistency, with output up to 4 megapixels. The family also includes the smaller FLUX.2 Klein 4B and 9B distillations that most Flux2 LoRAs in this catalog are trained on. This entry is the text-to-image workflow, accelerated with a turbo LoRA so that it finishes in a handful of steps.
- #3
flux
The fastest Flux DEV fp8 workflow, supports up to 5 loras. Built-in upscaler is a factor of 1.4, modify with /slot8 - #4

qwen
Qwen-Image is the image generation foundation model of Alibaba's Qwen team, released as open weights in August 2025. It is a 20-billion-parameter multimodal diffusion transformer that reads prompts through the Qwen2.5-VL vision-language…Qwen-Image is the image generation foundation model of Alibaba's Qwen team, released as open weights in August 2025. It is a 20-billion-parameter multimodal diffusion transformer that reads prompts through the Qwen2.5-VL vision-language model, and its headline strength is text: it renders long paragraphs, multi-line signs, posters and mixed Chinese and English typography with an accuracy no earlier open model reached. The same team's technical report also shows strong results for layout-heavy prompts, infographics and precise image editing, and the companion Qwen-Image-Edit model is the basis of many editing workflows. It generates natively around 1.3 to 1.6 megapixels in the usual aspect ratios and takes natural-language prompts rather than tag lists; the team recommends appending quality phrases such as 'Ultra HD, 4K, cinematic composition'. This entry is the version 2512 text-to-image workflow (the December 2025 refresh of the weights); the original release is kept as qwen-v1.
- #5
sulphur2
by SulphurAI - Sulphur v2 is a custom finetune of LTX 2.3 designed to add in missing NSFW concepts to LTX. This is specifically the LoRA version of the finetune, and should work with both T2V and I2V on workflows that support LTX 2.3…by SulphurAI - Sulphur v2 is a custom finetune of LTX 2.3 designed to add in missing NSFW concepts to LTX. This is specifically the LoRA version of the finetune, and should work with both T2V and I2V on workflows that support LTX 2.3 LoRAs. Be sure to use good quality natural language prompts for the best effects!
- #6
- #7
sdxl
Stable Diffusion XL version 1.0 is here, and the Refiner 1.0 is also installed. This is the official full release, but our software needs adjustment to fully support it. Only the /render command works and SDXL cannot be mixed with old…Stable Diffusion XL version 1.0 is here, and the Refiner 1.0 is also installed. This is the official full release, but our software needs adjustment to fully support it. Only the /render command works and SDXL cannot be mixed with old styles, recipes, loras, inversions, and other commands yet. Keep an eye on the XL news topic in Telegram VIP for more information
- #8
WAI ANI PONYXL
WAI-ANI-NSFW-PONYXL by Wai0731 is a stylish anime pony model. Notes from the creator: Brief description of v7: To better suit a wider range of uses, I adjusted the weights and revised some composition logic. I also incorporated some…WAI-ANI-NSFW-PONYXL by Wai0731 is a stylish anime pony model. Notes from the creator: Brief description of v7: To better suit a wider range of uses, I adjusted the weights and revised some composition logic. I also incorporated some effects-related assets into the training. I made sure to retain the original NSFW content as much as possible. If you encounter any issues or feel there are areas that need improvement, please leave me a message. Version 7 released. v6->v7 Fixed the issue where images appeared entirely covered with snowflakes. Revised the composition logic to be more suitable for general scenarios. Added new assets for backgrounds, mature women, and clothing. Ensured consistency with the previous model and further fixed the issue of blurry eyes in medium and long shots. Fixed some minor issues. V7 Recommended Setting Steps: 30 CFG scale: 7 Sampler: Euler a/DPM++ 2M Karras ADetailer to fix eyes. Positive Prompt score_9, score_8_up, score_7_up,source_anime, Negative Prompt score_6, score_5, score_4, source_cartoon, 3d, (censor),monochrome,blurry, lowres,watermark,
- #9
- #10
FLUX
Flux.1 Krea checkpoint, 4 torrents on CivitasBay (Krea Dev, flux.1_schnell_8x8, Dev, v1.0). The model is also listed on Civitai. - #11
- #12
Aesthetic Quality Modifiers Masterpiece v5.1 [anima base 1]
By - Motimalu Recommended prompt structure: Positive prompt (quality tags at the start of prompt): masterpiece, best quality, very aesthetic, {{tags}}, {{natural language}} - #13
CyberRealistic Pony
by Cyberdelia - CyberRealistic Pony V16 - #14

DeepSeek V4.1 Flash
DeepSeek | 1,048,576 token context | $0.04/M input, $0.68/M output. DeepSeek V4.1 Flash is a sparse mixture-of-experts model from DeepSeek, and the first built on the company's Causal Encoder-Decoder (CED) architecture. It activates 8B…DeepSeek | 1,048,576 token context | $0.04/M input, $0.68/M output. DeepSeek V4.1 Flash is a sparse mixture-of-experts model from DeepSeek, and the first built on the company's Causal Encoder-Decoder (CED) architecture. It activates 8B parameters on input and 16B on output from a 552B-parameter backbone, an asymmetric split that keeps per-token compute low relative to the model's total size. Image understanding is native to the architecture, with visual and text embeddings trained jointly from the start of pre-training rather than added afterward as in the earlier experimental V4 Flash Vision ExpOpens in new tab. It is suited for coding, terminal, and computer-use agents, along with long-horizon tasks that must run to completion across many steps and long-context analysis. Compressed KV caching cuts cache memory to roughly a quarter of the previous Flash generation, significantly reducing costs on agentic workloads. DeepSeek positions it as the cost-efficient tier of the V4.1 family and reports that it exceeds V4 ProOpens in new tab on performance, speed, and task completion time.
- #15

sdv15
Stable Diffusion 1.5 by Stability / RunwayML, the OG model. Someone said it was weird that we didn't have this in the concepts collection, and they were correct, so here you go! Of course, this model is over a year old, but it's still…Stable Diffusion 1.5 by Stability / RunwayML, the OG model. Someone said it was weird that we didn't have this in the concepts collection, and they were correct, so here you go! Of course, this model is over a year old, but it's still fantastic in its own right.
- #16
- #17
- #18
- #19
zimage turbo
Also known as "ZIT" -- Z-Image Turbo from Alibaba is a fast, low-steps general purpose realism text to image model. Doesn't support negative prompts. Works best at around 9 steps and 1 guidance at 1024x1024. - #20
ReV Animated
Rev Animated 2.0 is under new management - the project is now maintained by Zovya This is a remaster of the classic popular Revani series for SD15 - #21
- #22
Counterfeit V3.0
CounterfeitV3.0 by rqdwdw. The 3.0 version of Counterfeit has much brighter colors and more focus on the subject, whereas the previous model was more muted and pastel-like. The backgrounds look totally different in particular, so we're…CounterfeitV3.0 by rqdwdw. The 3.0 version of Counterfeit has much brighter colors and more focus on the subject, whereas the previous model was more muted and pastel-like. The backgrounds look totally different in particular, so we're going to keep both. It should be noted that there are 10 upvotes and 3 comments about green spots from users on Civitai.
- #23
AutismMix SDXL AutismMix_pony
AutismMix SDXL Pony model by Autismix_anon. AutismMix_pony is a merge of ponyv6 with loras, its more compatible with certain styles made for the base Ponydiffusion model. - #24
Hands XL + SD 1.5 + F1D + Pony + Illustrious + zit + ZIB Hand F1D v2.0
by EauDeNoire - Update: Please if you see any of my models somewhere else report or let me know! Thnx Please read version info (about version) Update: Added perfection style model (Hands + Feet + all in one) Update: Added Detailed style…by EauDeNoire - Update: Please if you see any of my models somewhere else report or let me know! Thnx Please read version info (about version) Update: Added perfection style model (Hands + Feet + all in one) Update: Added Detailed style (Hand focus + all in one) Update: Added SD 1.5 Model Trained on base model xl 1.0 + FLUX.1-dev Feel free to check feet model as well. Feedback and ratings are much appreciated. Other models to check: Skin Tone (Cinematic Photography) Style XL (Human skin color) Realistic Skin Texture style XL (Detailed Skin) Facial Expressions (detailed emotions) style XL Perfect Eyes (Variaty of sclera) XL
- #25
DreamShaper
Dreamshaper 8 by Lykon is one of the most popular base models for illustrations and art. This update includes better support for character LoRAs, better photorealism, can still handle anime, and better NSFW - #26
Wan 2.1
Wan 2.1 is the February 2025 generation of Alibaba's open Wan video models: 1.3B and 14B weights for text-to-video and image-to-video. It has been superseded by Wan 2.2 (July 2025), which gives clearly better motion, detail and prompt…Wan 2.1 is the February 2025 generation of Alibaba's open Wan video models: 1.3B and 14B weights for text-to-video and image-to-video. It has been superseded by Wan 2.2 (July 2025), which gives clearly better motion, detail and prompt following with the same kind of workflows, so there is no reason to start with Wan 2.1 in 2026 or later. This page stays as a reference for the older LoRAs and workflows that were made for it.
- #27
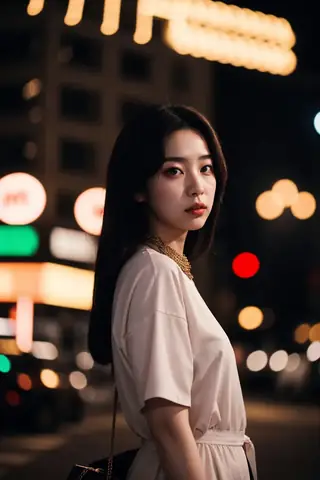
Beautiful Realistic Asians
Beautiful Realistic Asians v7 model by pleasebankai - #28
GLM 5.3 Flash
Z.ai | 1,048,576 token context | $0.02/M input, $0.72/M output. GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture…Z.ai | 1,048,576 token context | $0.02/M input, $0.72/M output. GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture maintains accurate long-context behavior while reducing compute overhead. Yes, the stealth model Ox Alpha was revealed to be ZAI's new model, GLM-5.3 Flash.
- #29
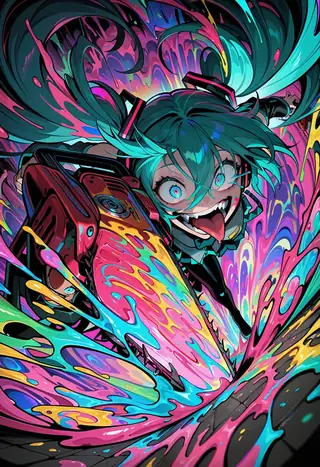
NTR MIX | illustrious XL | Noob XL XIII
by tkio - NTR MIX | illustrious-XL | Noob-XL - #30
Hy4 preview
Tencent | 1,048,576 token context | $0.83/M input, $2.50/M output. Tencent: Hy4 preview is a mixture-of-experts model from Tencent, with 49B active parameters out of 770B total. It is designed for coding agents, complex tool-use workflows,…Tencent | 1,048,576 token context | $0.83/M input, $2.50/M output. Tencent: Hy4 preview is a mixture-of-experts model from Tencent, with 49B active parameters out of 770B total. It is designed for coding agents, complex tool-use workflows, and productivity tasks that require planning, context continuity, and sustained multi-step execution.
- #31
MiMo V2.6 Flash
Xiaomi | konteks 1.050.000 token | $0.14/M input, $0.28/M output. MiMo-V2.6-Flash adalah model fondasi open-source yang dikembangkan oleh Xiaomi. Dibangun di atas arsitektur Mixture-of-Experts dengan total 309B parameter dan 15B diaktifkan…Xiaomi | konteks 1.050.000 token | $0.14/M input, $0.28/M output. MiMo-V2.6-Flash adalah model fondasi open-source yang dikembangkan oleh Xiaomi. Dibangun di atas arsitektur Mixture-of-Experts dengan total 309B parameter dan 15B diaktifkan per token, model ini menggunakan mekanisme hybrid attention untuk efisiensi komputasi yang lebih besar. Model ini memiliki jendela konteks 1M token dan kemampuan multimodal native. Dioptimalkan untuk alur kerja agentik, model ini memberikan performa kuat dalam coding, visual, umum, dan skenario riset, unggul dalam tugas kompleks jangka panjang dengan generalisasi yang kuat di berbagai kerangka agen.
- #32
chilloutmix
Chilloutmix V2 (NI) by Tasuku2023 is best known as an "asian beauty" ai model. It works best with the Pure Eros Face textual inversion embeddings and character loras like Japan Doll and Taiwan Doll - #33
Pony Realism 🌐 v2.2
by ZyloO -- Pony Realism v2.2 Main + VAE tips: use sampler dpm2m, Settings: Steps: >=30 Guidance: 6-9 Clip Skip: 2 Resolution: >1024 Terminology: Recommended the use of "female/male" instead of "woman/man" Additional Information: Use…by ZyloO -- Pony Realism v2.2 Main + VAE tips: use sampler dpm2m, Settings: Steps: >=30 Guidance: 6-9 Clip Skip: 2 Resolution: >1024 Terminology: Recommended the use of "female/male" instead of "woman/man" Additional Information: Use Danbooru tags. Example positive: score_9, score_8_up, score_7_up, asian girl, makeup, goth, emo, portrait, close-up, messy bedroom, supported on bedside table, clutter tattoos, solo, sexy curves, revealing outfit, a latex minidress, depth of field, highly detailed, high contrast, film grain, Rim Lighting — example negative — score_6, score_5, score_4, text, censored, deformed, bad hand — parameters — /guidance:6 /steps:30 /parser:new /clipskip:2 /sampler:dpm2m /karras
- #34
ICBINP "I Can't Believe It's Not Photography" SECO
ICBINP - "I Can't Believe It's Not Photography" SECO by Residentchiefnz - #35
DeepSeek V4 Flash 0731
DeepSeek | 1,048,576 token context | $0.01/M input, $1.28/M output. DeepSeek V4 Flash 0731 is a sparse mixture-of-experts model from DeepSeek, with 13B active parameters out of 284B total. This re-post-trained revision is suited for…DeepSeek | 1,048,576 token context | $0.01/M input, $1.28/M output. DeepSeek V4 Flash 0731 is a sparse mixture-of-experts model from DeepSeek, with 13B active parameters out of 284B total. This re-post-trained revision is suited for coding, reasoning, and agent workflows. This is the GA release of DeepSeek V4 Flash.
- #36
- #37
majicMIX realistic 麦橘写实
majicMIX realistic 麦橘写实 model by Merjic - #38
- #39

- #40
Nemotron 3 Ultra
NVIDIA | konteks 262.144 token | $0.60/M input, $2.40/M output. NVIDIA Nemotron 3 Ultra adalah model frontier-reasoning dan orkestrasi terbuka dari NVIDIA, dengan 55B parameter aktif dari total 550B (MoE). Dibangun di atas arsitektur…NVIDIA | konteks 262.144 token | $0.60/M input, $2.40/M output. NVIDIA Nemotron 3 Ultra adalah model frontier-reasoning dan orkestrasi terbuka dari NVIDIA, dengan 55B parameter aktif dari total 550B (MoE). Dibangun di atas arsitektur hybrid Transformer-Mamba mixture-of-experts, model ini mendukung input dan output teks dengan jendela konteks hingga 1M token. Model ini cocok untuk alur kerja agentik jangka panjang, termasuk orkestrasi agen, agen coding, riset mendalam, dan tugas perusahaan yang kompleks. Model ini sangat kuat dalam penalaran dan perencanaan multi-langkah, dengan inferensi throughput tinggi yang dirancang untuk pipeline agen volume besar. Ini adalah bagian dari keluarga model terbuka NVIDIA Nemotron untuk AI agentik.
- #41
Step 5 Preview
StepFun | 1,048,576 token context | $1.00/M input, $2.70/M output. Step 5 Preview is StepFun's flagship model for agentic work, built on a sparse Mixture-of-Experts architecture (27B active / 600B total parameters). It performs strongly in…StepFun | 1,048,576 token context | $1.00/M input, $2.70/M output. Step 5 Preview is StepFun's flagship model for agentic work, built on a sparse Mixture-of-Experts architecture (27B active / 600B total parameters). It performs strongly in software engineering and professional knowledge work, with particular strength in finance. It is designed for extended tasks that span large codebases and documents, using tools and refining results over multiple steps.
- #42
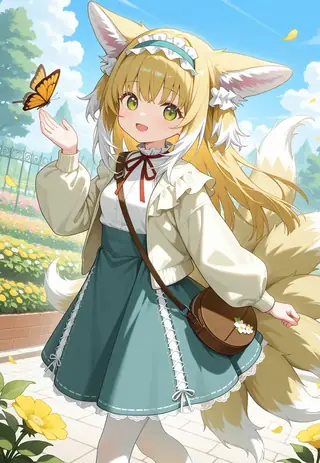
ZUKI anime ILL
by Zu_Ki - Hentai capable illustrious model. Prompt: masterpiece,best quality,amazing quality,very aesthetic,absurdres, Negative prompt: lowres, bad quality, worst quality, bad anatomy, sketch, jpeg artifacts, ugly, poorly drawn,…by Zu_Ki - Hentai capable illustrious model. Prompt: masterpiece,best quality,amazing quality,very aesthetic,absurdres, Negative prompt: lowres, bad quality, worst quality, bad anatomy, sketch, jpeg artifacts, ugly, poorly drawn, censor,blurry, watermark,simple background, transparent background, CFG:3~12 STEPS:30
- #43
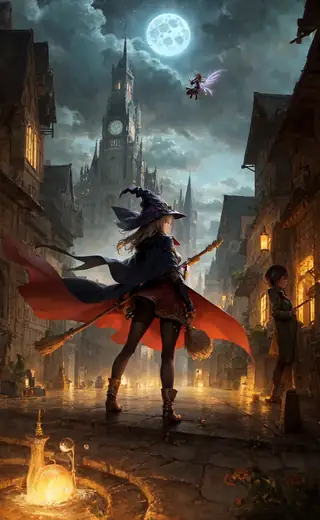
AbyssOrangeMix3 (AOM3)
AbyysOrangeMix3 by liudinglin A midpoint of artistic but bends towards anime - the model has been tuned to combine realistic textures, a artistic style that also feels like an oil colour style, and a cute anime-style face. - #44
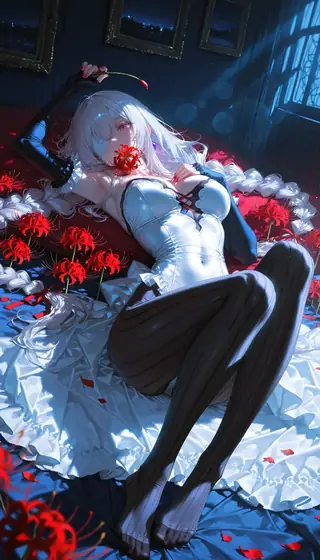
One obsession
by maxfeifei8 - One obsession - #45
- #46

Add More Details Detail Enhancer / Tweaker (细节调整) LoRA
Add More Details - Detail Enhancer / Tweaker (细节调整) LoRA by Lykon writes: his between 0.5 and 1 weight, depending on your preference. You can go lower than 0.5 for a more subtle effect, of course. I also found out that this gives some…Add More Details - Detail Enhancer / Tweaker (细节调整) LoRA by Lykon writes: his between 0.5 and 1 weight, depending on your preference. You can go lower than 0.5 for a more subtle effect, of course. I also found out that this gives some interesting results at negative weight, sometimes
- #47
[MMH3] Mystic XXX v4.0 (FL2VA & REF2VA)
By alcaitiff - (v4) MiniMax H3 general NSFW motion and anatomy helper LoRA, improves on mystic3-h3 and mystic-v2-h3 with higher resolution during the training process. Author notes it has better motion quality, temporal stability, and fine…By alcaitiff - (v4) MiniMax H3 general NSFW motion and anatomy helper LoRA, improves on mystic3-h3 and mystic-v2-h3 with higher resolution during the training process. Author notes it has better motion quality, temporal stability, and fine detail. No specific trigger needed in prompt, just be specific about what you want to see in your prompts.
- #48

waifu
waifu-diffusion by hakurei. A long running base model trained on crisp-looking anime. Compared to your other anime base model options, this one is fairly well-rounded, which unfortunately has been detrimental in making it a clear winner in…waifu-diffusion by hakurei. A long running base model trained on crisp-looking anime. Compared to your other anime base model options, this one is fairly well-rounded, which unfortunately has been detrimental in making it a clear winner in any category.
- #49
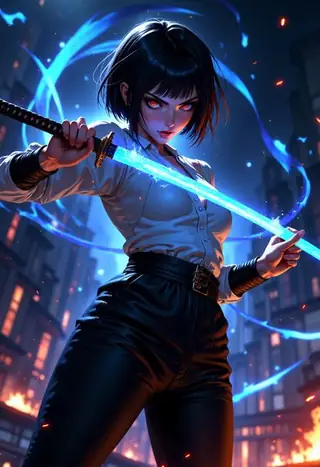
Velvet's Mythic Fantasy Styles | Flux + Pony + illustrious + ZiT + Anima + Krea2 Flux Original
by VelvetS - The new version has been trained to work on Flux models. From my testing Flux is amazing with sentence like prompts, and turns booru prompts to anime pics that don't have a lot of details but this LoRA fixes that - #50
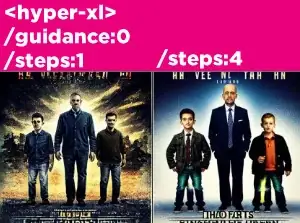
hyper
The "hyper-xl" model is optimized to significantly increase generation speed.
Heat adalah skor tren internal kami dari dingin hingga 9999°. Skor ini berubah setiap hari mengikuti sinyal penggunaan dan popularitas dari komunitas dan layanan di sekitar setiap model. Peringkat mencakup model dasar, LoRA, embedding, dan model teks dari semua keluarga di katalog.
Jelajahi berdasarkan Keluarga Model