vanguardvision25 flux
Bandingkan
7631°
Jalankan secara lokal
VanguardVision25 V1.safetensors
662 MB · SafeTensor
Unduhan disediakan oleh Civitai. Beberapa kreator meminta login Civitai terlebih dahulu.
AD


Pasang / Jalankan di Graydient
Memerlukan keanggotaan
<vanguardvision25-flux>
Tentang Model Ini
FLUX · LoRA
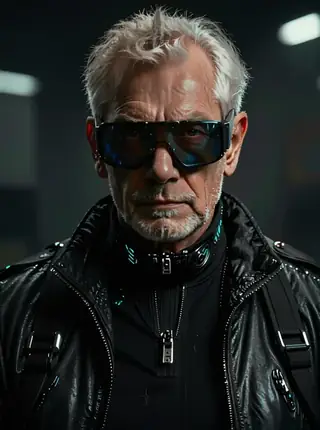
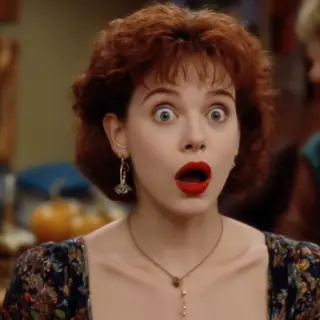
By:thedivergentai Vanguard Vision 25 V1.00 - Elevating Photographic Style to Hyperrealism Vanguard Vision 25 is a FLUX.1 LoRA designed to empower your creations with unparalleled hyperrealism and photographic fidelity. Trained on a meticulously curated dataset of high-resolution images from 2025, this LoRA excels at detailed prompt adherence, enabling you to generate breathtakingly realistic visuals across a vast spectrum of subjects and compositions, all while maintaining creative flexibility.
Catatan pembuat
Vanguard Vision 25 - Elevating Photographic Style to Hyperrealism with Unrivaled Detail
Vanguard Vision 25 is a FLUX.1 LoRA designed to empower your creations with unparalleled hyperrealism and photographic fidelity. This V1.1 update brings significant enhancements, notably improved text legibility and even crisper minute details, thanks to higher resolution training. Dive into generating breathtakingly realistic visuals across a vast spectrum of subjects and compositions, including the ability to seamlessly integrate alternative or mixed media elements while maintaining that signature hyperrealistic style.
Description
This LoRA (Vanguard Vision 25 V1.1) is designed to imbue your generations with a distinct, high-fidelity photographic style. It was meticulously trained on an expanded and refined dataset of approximately 150 full-resolution photographic images, now processed at a higher base resolution of 1024x1024. This enhancement, combined with thorough recaptioning, ensures superior detail rendering and remarkable text generation. The dataset covers a wide array of contemporary subjects, environments, lighting conditions, and compositional techniques.
The goal of this LoRA is to help users easily generate images that exhibit a profound sense of realism, sharp detail, and natural lighting characteristic of high-end photography. Expect results that showcase rich textures, accurate color palettes, dynamic compositions, and excellent adherence to nuanced textual descriptions, including the generation of highly legible text within images. Furthermore, V1.1 is adept at creating creative compositions that subtly blend hyperrealism with alternative or mixed media elements without sacrificing fidelity.
Prominent Subjects, Contents, and Styles Captured in Training Data:
-
People: Diverse ethnicities and ages in various attire (casual, traditional, occupational, and costume), engaged in a multitude of actions and expressions.
-
Animals: A wide range including mammals (elephants, rhinos, lions, wolves, polar bears, monkeys), birds (eagles, hummingbirds, woodpeckers), reptiles (snakes, crocodiles), insects (bees), and marine life.
-
Environments: Expansive natural landscapes (mountains, forests, deserts, savannas, oceans, snowscapes, volcanic regions, caves) and detailed urban/man-made settings (cities, interiors, industrial sites, architectural structures).
-
Objects & Details: Vehicles, tools, everyday objects, artistic elements, and precise text rendering on signs, clothing, and products.
-
Photographic Techniques: Mastery over various lighting conditions (natural, artificial, dramatic, subdued), compositional styles (macro, aerial, wide-angle, portraits, action shots), and effects (long exposure, shallow/deep depth of field, bokeh, silhouettes, high contrast, black & white).
Changelog V1.0 to V1.1
-
Higher Base Resolution Training: The model has been retrained at a higher base resolution of 1024x1024, a significant stride towards our roadmap goals. This fundamentally improves overall image fidelity, particularly enhancing minute details that V1.0 occasionally struggled to render with crispness.
-
Improved Text Legibility: All training images were meticulously recaptioned, focusing on accurately capturing all visible text, even subtle details. This has led to a remarkable improvement in the LoRA's ability to generate clear, precise, and legible text within your images.
-
Enhanced Detail & Crispness: The higher resolution training allows the LoRA to produce images with unparalleled crispness, rendering intricate textures and fine elements with exceptional clarity.
-
Mixed Media Capability: This version is now quite adept at creating alternative or mixed media content, offering the ability to produce creative compositions that still maintain the core hyperrealistic photographic style.
Trigger Word(s)
No Trigger Word Required:
This LoRA was trained without requiring a specific trigger word. It was trained using detailed natural language captions describing the image content and style.
To utilize this LoRA, simply include descriptive terms in your prompt that align with the LoRA's training focus. Describe the desired subject, environment, lighting, composition, and any specific photographic style. The LoRA, when active, will strongly influence the output towards its hyperrealistic photographic effect based on your prompting and the LoRA weight.
Recommended Settings
These are suggested starting points for using this LoRA effectively with FLUX.1.
-
LoRA Weight: 0.8 - 1.0 (Adjust based on desired intensity; typically 1.0 works well)
-
Base Model: Black Forest Labs FLUX.1 Dev (or subsequent compatible versions)
-
Sampler: Euler Beta (or other FLUX.1 compatible samplers)
-
Steps: 25 - 35
-
CFG Scale: 3.0 - 4.0 (Typically ~3.5, depending on FLUX.1 version)
-
Resolution: Trained at up to 1024x1024, highly effective for generating images up to 1 megapixel (e.g., 1024x1024, 768x1280, 1280x768, etc.). Experiment with various aspect ratios.
Strengths
-
Exceptional Realism & Detail: Produces images with unparalleled photographic fidelity, capturing intricate textures and nuanced lighting with enhanced clarity.
-
Enhanced Text Legibility: Significantly improved rendering of legible text within images, making signs, labels, and written elements remarkably crisp.
-
Exceptional Minute Details: Renders tiny, intricate details with remarkable clarity, providing a truly "crisp" output.
-
Detailed Prompt Adherence: Strong ability to interpret and render complex natural language prompts accurately.
-
Versatile Subject Matter: Performs well across a wide range of subjects including people, animals, landscapes, and objects as seen in the training data.
-
Creative Mixed Media: Ability to produce images that seamlessly blend hyperrealism with alternative or mixed media aesthetics, expanding creative compositions.
-
Diverse Photographic Styles: Capable of replicating various photographic te
SHA256
C2DC0E7F4B883DAB69F38E808FF416094EF96F025B8D97E1EF0D8DD1F09BDC87
ID Model ModelTrends.ai
#20164
Laporkan konten
Model AI untuk Pembuatan Gambar, Video & Teks
vanguardvision25 flux adalah LoRA untuk keluarga Flux yang tercantum di ModelTrends.ai, katalog hanya-baca untuk model AI gambar, video, dan teks open source. Bandingkan dengan model Flux lainnya, lihat skor popularitasnya untuk mengetahui trennya, dan buka di PirateDiffusion atau BitVector untuk mencobanya.
Model Flux lainnyaLoRA Flux lainnyaeffectsrealisticphotorealismhyperrealisticportraitphotorealismarchitecture
Jelajahi berdasarkan Keluarga Model
Model Text / LLM
411
Model Anima
509
Model Chroma
14
Model Flux
1,071
Model Flux 2 / Klein
1,237
Model MiniMax H3
331
Model Hunyuan
197
Model Ideogram
20
Model Krea2
674
Model Qwen
17
Model Qwen2
36
Model Ltx2
150
Model Stable Diffusion 1.5
6,465
Model Stable Diffusion XL 1.0
15,432
Model Zimage
804
Model Wan
919

Model
Trends
.ai
© ModelTrends.ai
|
Dibuat di Jepang
|
© 2026