Lokaal uitvoeren
kwFemaleBeta15_SDXL_v1-000008.safetensors
1.70 GB · SafeTensor
Downloads worden geleverd door Civitai. Sommige makers vragen eerst om in te loggen op Civitai.


Over dit model
STABLE DIFFUSION XL 1.0 · LoRA's
Notities van de maker
Beta136: Improved dataset and reduced Learning Rate
==========================================
Beta107: Replace the refined data set from Pony
==========================================
Warning! Beta130, Beta122, and Beta92 v1.0 was created as part of the research on AdamW 32 bits, and not intended for regular usage.
Please add the following arguments in Automatic1111 WebUI webui-user.bat in order to enable 32 bits.
Feel free to create the picture if interested, however, the file is huge.
Thanks to the members from the following groups for generating the pictures and discussing the result, so that this LoRA could be improved greatly before released:
AI乐园:
AI绘图魔法群:
AI练丹交流
奇思妙想会
AI绘画
lora交流
AIGenerateMagic
兔狲的SDXL百老汇
============================================
Thanks for the interest in this LoRA creation. This project has been conducted in Stable Diffusion 1.5 since March 2023.The objective of this project is to create an ideal training data set for LoRA. After the launching of SDXL, the scope of this research was expanded to this new version.
The face of the researcher was taken as reference in order to create the training set. 15 photos were taken purposely for AI training only. These 15 photos contain different angles of face and shoulder to fulfill the AI training requirement.
After trying different combinations of settings, an optimal adjustment was found.
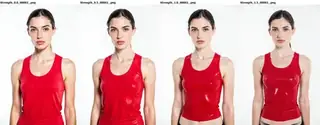
Comparison of Dim256, Dim128, and no LoRA respectively.
*********************************************************
Here is the log for different version.
Beta1: First trying with suggested learning rate 4e-7, resolution 1024x1024, dimension 256, alpha 256, optimizer: Adafactor. Result unsatisfied.
Beta2: Change the learning rate in Beta1 to 0.0004. Result unsatisfied.
Beta3: Reduce the learning rate in Beta2 to 0.0001, increase the steps of each photo to 100. Result unsatisfied.
Beta4: Replace the resolution in Beta3 to 2048x2048, reduce the steps of each photo to 20. Result unsatisfied.
Beta5: Increase the steps of each photo to 100 in Beta4. Result unsatisfied.
Beta6: Applying learning rate 0.0004, resolution 1024x1024, 20 steps of each photo, alpha 1. Result unsatisfied.
Beta7: Reduce learning rate to 0.0001, resolution 960x960, alpha 256. Result unsatisfied.
Beta8: Reduce learning rate to 0.00001, resolution 1024x1024, 20 steps of each photo. Result unsatisfied.
Beta9: Reduce learning rate to 0.000005. Result unsatisfied.
Beta10: Reduce resolution 512x512, 40 steps of each photo. Result unsatisfied
Beta11: Using two subset of resolutions 512x512 and 1024x1024, 40 steps of each photo. Set max resolution to 512x512, dimension 128, alpha 128. Result unsatisfied.
Beta12: Set Max resolution to 1024x1024, dimension 64, alpha 64. Result unsatisfied.
Beta13: Replace optimizer to prodigy, learning rate 1, dimension 128, alpha 128. Result unsatisfied
Beta14: Replace optimizer to adamW8bits, learning rate 0.0001, 20 steps, dimension 256, alpha 256. Result satisfied.
Beta15: Reduce the learning rate to 0.000005. Result satisfied. Uploaded to Civitai as version 1. Marked as miletone.
Beta16: Increase the learning rate to 0.00001, no better results.
Beta17: Reduce the learning rate to 0.000005, dimension 128, alpha 128. Applying Text Encoder learning rate to 0.000005, Unet learning rate to 0.00001. No better results.
Beta18: Removed Text Encoder learning rate and Unet learning rate. No better results.
Beta19: Increased learning rate to 0.0001, resolution 512x512 only, 80 steps, dimension 256, alpha 256, clip skip 2. No better results.
Beta20: Reduced learning rate to 0.00001. No better results.
Beta21: Increased resolution to 960x960. No better results.
Beta22: Reduced learning rate to 0.000001, resolution 1024x1024, 100 steps. No better results.
Beta23: Reduced learning rate to 0.0000004, 400 steps. No better results.
Beta24: Reduced steps to 200, dimension 64, alpha 64, skip clip 1. No better results.
Beta25: Increased learning rate to 0.00001, 30 steps, dimension 256, alpha 256. Result satisfying. Marked as second milestone.
Beta26: Reduced learning rate to 0.000005, 20 steps, No better results.
Beta27: Increased learning rate to 0.00001, 30 steps, dimension 64, alpha 64. Result satisfying.
Beta28: Replace new training data set. Uploaded to Civitai as Dim64 version.
Beta29: Increased dimension to 256, alpha 256. No better results.
Beta30: Increased resolution to 1536x1536. No better results
Beta31: Increased resolution to 2048x2048. No better results
Beta32: Changed resolution to 1536x2048. No better results
Beta33: Reduced resolution to 1280x1280, 40 steps. No better results
Beta34: Changed resolution to 1024x1536, 30 steps, new set of the training data. No better results.
Beta35: Changed resolution to 1024x1280. No better results.
Beta36: Changed resolution to 1024x1024. No better results.
Beta37: Changed resolution to 1024x1024, 50 steps. No better results.
*********************************************************
Since it is ongoing project, your valuable feedback is important, in order to bring this project to the next level.
Triggerwoorden
1girl
kwf
SHA256
0563C4544EFE3C3461A6D676058479B40568F14850A86CAB8A67F91C5DB371BD
ModelTrends.ai model-ID
#7365
Inhoud melden
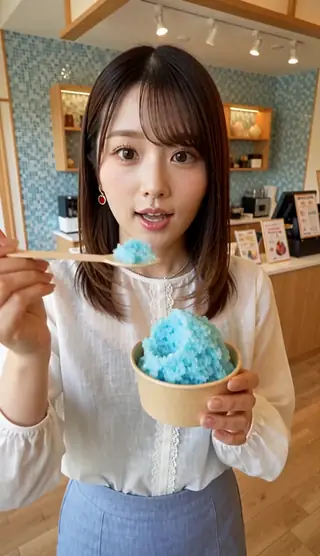
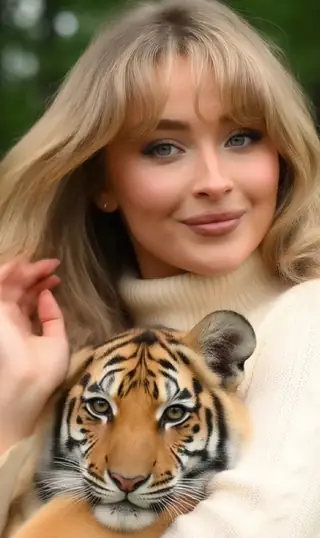
Voorbeeldrenders
Prompts en instellingen gedeeld door de mensen die deze renders op Civitai maakten. Kies een render om te zien hoe hij is gemaakt.
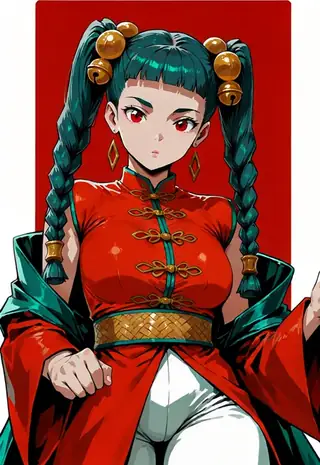
Instellingen
Sampler
DPM++ SDE Karras
Stappen
20
Guidance
7
Seed
838029274
Formaat
1024x1280
Prompt
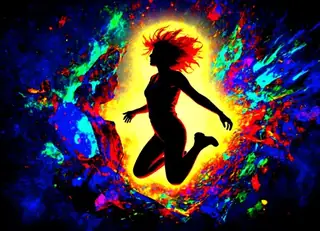
anime,(masterpiece, top quality, best quality, official art, beautiful and aesthetic:1.2), (1girl), upper body,extreme detailed,(fractal art:1.3),colorful,highest detailed, kwf, <lora:kwFemaleBeta15_SDXL_v1-000008:1>
Negatieve prompt
low quality, worst quality, bad anatomy, bad composition, poor, low effort, bad quality, deformed,extra finger,bad hand
Instellingen
Sampler
Euler a
Stappen
48
Guidance
9
Seed
1034193405
Formaat
768x1024
Clip skip
2
Prompt
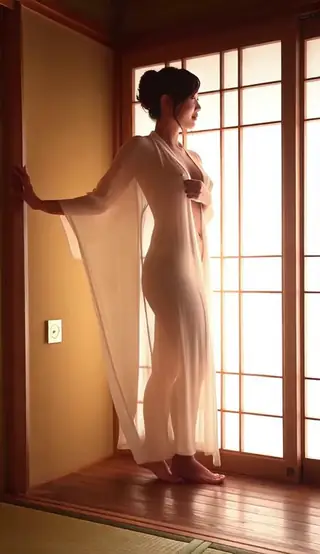
(mysterious:1.3), ultra-realistic mix fantasy, an asian woman holding a Excalibur,void energy diamond sword, mixes realistic and fantastical elements, vibrant manga, uhd image, glassy translucence, vibrant illustrations, ultra realistic, long hair, straight hair, head jewelly, jewelly, shawls,light In eyes, portrait, firefly, bokeh, mysterious, fantasy, cloud, abstract, flame, very detailed, high resolution, sharp, sharp image, 4k, 8k, masterpiece, best quality, magic effect, (high contrast:1.4), dream art, diamond, skin detail, face detail, eyes detail, mysterious colorful background,night sky,
(stochastic angle, stochastic pose,stochastic action),charming, alluring, seductive, erotic, enchanting,Grimoire,
luxury, jewelry, ornate, necklace, bracelet, hairpin,embroidery,(shiny see-through dress:1),
Overhead view,A picture full of stories, GoPro, dynamic blur, long exposure, 1girl,Martial arts, vengeance, cinematic, highly detailed, chinese style, playing the light and shadow, bauhaus photography, fuj, 28mm. hypercolorful dreamscapes, camille claudel, selective focus, cyan - blue light ,3D
(Around floating colorful SwordQi:1)the most beautiful form of chaos,
(glowing colorful geometric:1),
<lora:PAseer-SDXL-GoldenWindAndPalaceV1:0.8>,jinsixiangyun,traditional ,<lora:kwFemaleBeta15_SDXL_v1-000008:0.7>
Negatieve prompt
(worst quality:1.5), (low quality:1.5), (normal quality:1.5), lowres, bad anatomy, bad hands, multiple eyebrow, (cropped), extra limb, missing limbs, deformed hands, long neck, long body, (bad hands), signature, username, artist name, conjoined fingers, deformed fingers, ugly eyes, imperfect eyes, skewed eyes, unnatural face, unnatural body, error, painting by bad-artist layman work, worst quality, ugly, (deformed|distorted|disfigured:1.21), poorly drawn, bad anatomy, wrong anatomy, mutation, mutated, (mutated hands AND fingers:1.21), bad hands, bad fingers, loss of a limb, extra limb, missing limb, floating limbs, amputation, Yaeba, photo, deformed, black and white, realism, disfigured, low contrast,
Instellingen
Sampler
DPM++ 2M SDE Karras
Stappen
30
Guidance
7
Seed
1476878444
Formaat
1024x1024
Prompt
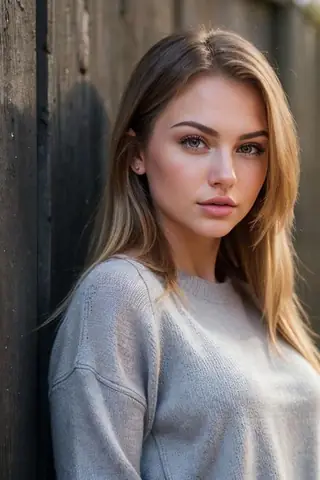
masterpiece, best quality, 1girl, upper body, looking at viewer, simple background, <lora:kwFemaleBeta15_SDXL_v1-000008:1>
Negatieve prompt
easynegative, By bad artist -neg, bad-hands-5, low quality, worst quality, bad anatomy, bad composition, poor, low effort
Vergelijkbare modellen
AI-modellen voor het genereren van afbeeldingen, video en tekst
kwfemale1 xl is een LoRA voor de Stable Diffusion XL 1.0-familie, vermeld op ModelTrends.ai, een alleen-lezen catalogus van open source AI-modellen voor afbeeldingen, video en tekst. Vergelijk het met andere Stable Diffusion XL 1.0-modellen, bekijk de populariteitsscore om de trend te zien en open het op PirateDiffusion of BitVector om het te proberen.
Meer Stable Diffusion XL 1.0-modellenMeer Stable Diffusion XL 1.0 LoRA'scharactersexyrealisticloraanimewomanphotorealisticcharacters
Bladeren op modelfamilie
Text / LLM-modellen
411
Anima-modellen
509
Chroma-modellen
14
Flux-modellen
1,071
Flux 2 / Klein-modellen
1,237
MiniMax H3-modellen
331
Hunyuan-modellen
197
Ideogram-modellen
20
Krea2-modellen
674
Qwen-modellen
17
Qwen2-modellen
36
Ltx2-modellen
150
Stable Diffusion 1.5-modellen
6,465
Stable Diffusion XL 1.0-modellen
15,432
Zimage-modellen
804
Wan-modellen
919

Model
Trends
.ai
© ModelTrends.ai
|
Gemaakt in Japan
|
© 2026